Wexford Local
· original →
· 7/10
· Local Wexford: water supply disruption Clonroche
[image →] By Dan Walsh Customers and businesses in Clonroche and surrounding areas may experience disruptions to their water supply this evening following a burst water main. Uisce Eireann crews are…
Customers and businesses in Clonroche and surrounding areas may experience disruptions to their water supply this evening following a burst water main.
Uisce Eireann crews are on site carrying out repairs and every effort is being made to restore normal service as quickly and safely as possible.
An alternative water supply is currently being arranged for affected customers this evening and will be available in Clonroche village.
An additional tanker will also be available at Clonroche Community Centre from 9am tomorrow morning. Customers are reminded to use their own containers when taking water from tankers and to boil water before consumption as a precautionary measure.
Padraig Lyng Water Operations Manager at Uisce Éireann, said: “We understand how inconvenient an unexpected water outage can be. Our main priority is fixing this burst and returning a normal supply to all our customers. We really appreciate everyone in the community bearing with us while our crews get water back to homes and businesses.”
Repairs are expected to be completed by 4pm tomorrow (Friday) October 2nd. Once repairs have been completed, water supplies will return gradually over the following hours. Customers in higher-lying areas or at the ends of the network may experience a longer wait while the water network refills.
To keep crews and the public safe while repairs are underway, traffic management measures will be in place and clearly signposted along the N30 at Leech’s bend with traffic management starting from 9am tomorrow.
Wexford Local
· original →
· 7/10
· Local Wexford: water treatment plant Bree resolved
[image →] By Dan Walsh Uisce Éireann has confirmed that the issue at the water treatment plant serving the Bree and Ballyhogue areas has been resolved and the plant is returning to normal operation.…
Uisce Éireann has confirmed that the issue at the water treatment plant serving the Bree and Ballyhogue areas has been resolved and the plant is returning to normal operation.
Padraig Lyng, Uisce Éireann, said: “The issue at the water treatment plant has now been resolved. I would like to thank customers in Bree and Ballyhogue for their patience and understanding while crews worked to restore normal service.”
“The support and cooperation shown by the local community throughout the day was greatly appreciated. We are asking customers to continue to use water carefully while supplies fully recover across the network,” added Mr. Lyng.
The measures put in place throughout the day, including tankering water to the treated water reservoir, helped maintain supply to the local community while crews worked to address the issue.
As the network continues to stabilise, Uisce Éireann is asking customers to continue to use water carefully where possible to help support the return to normal supply levels across the area.
Typically, it takes two to three hours following repairs for normal water supply to fully return as the network recharges. However, it may take longer for normal supply to return to customers at the end of the network or on higher ground.
Wexford Local
· original →
· 7/10
· Local Wexford: water supply issues Bree Ballyhogue
[image →]Water difficulties at Ballyhogue and Bree. (File Pic; WexfordLocal.com) By Dan Walsh Uisce Éireann is working to maintain water supply to customers in the Bree and Ballyhogue areas…
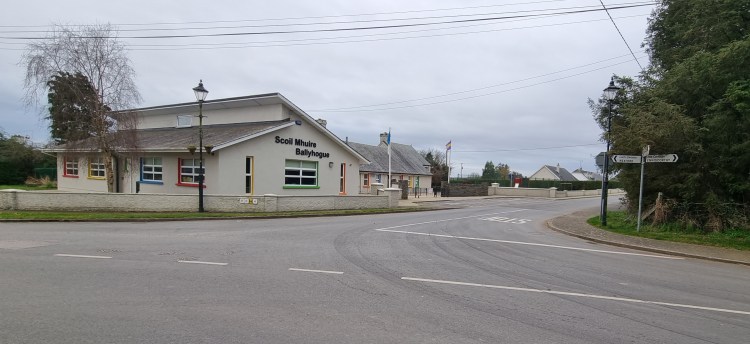
[image →]Water difficulties at Ballyhogue and Bree. (File Pic; WexfordLocal.com)
By Dan Walsh
Uisce Éireann is working to maintain water supply to customers in the Bree and Ballyhogue areas following an issue at the local water treatment plant.
Padraig Lyng, Water Network Operations Manager Uisce Éireann, said: “Our crews are working to manage this issue and maintain water supplies for customers in Bree and Ballyhogue. We have put measures in place to support the local network, including tankering water to the treated water reservoir, while repairs are progressed.”
“We are asking customers to be mindful of their water use while the supply network remains under pressure. We understand the inconvenience that low pressure or interruptions to supply can cause and we thank the community for their patience and cooperation while we work to restore normal operations,” added Mr. Lyng.
Crews are on site. Repairs are expected to be completed later today. Customers can check the water supply and services section of the Uisce Éireann website for the latest updates: www.water.ie.
Typically, it takes two to three hours following repairs for normal water supply to fully return as the network recharges. However, it may take longer for normal supply to return to customers at the end of the network or on higher ground.
Hacker News
· original →
· 7/10
· AI: Claude Opus 5.5 historical cipher breaking
Another day, another historical cipher broken by a frontier model. Yesterday, the security researcher Carter Church announced that he had used GPT-6 Astra (working on the problem for six hours) to…
Another day, another historical cipher broken by a frontier model. Yesterday, the security researcher Carter Church announced that he had used GPT-6 Astra (working on the problem for six hours) to break a Napoleonic-era cipher that had previously resisted all decryption attempts.
Church’s post on the subject is an interesting example not just of a reproducible methodology, but also of how to vibe code an information-dense writeup that is notably different from any traditional academic aesthetic, but which actually does surface primary sources and meaningful information in a fairly deep way:
The aesthetic weirdness is just the tip of the iceberg here. What I notice most about these forays into historical sleuthing using AI (and my own attempts at same) is the epistemological weirdness of how current frontier models now operate when given historical research tasks.
The best way to demonstrate what I mean here is by sharing the step-by-step process by which I was able to find what appears to be a previously-unnoticed Dutch report of hunting dodos dating to 1615. The core steps were:
Start from an actual base of specialist knowledge to define a specific research question (for example, I had previously researched the history of the exotic animal trade in the seventeenth century, and am planning to write a book on animal extinctions in the early modern period which will have a dodo chapter)
Identify a large, freely-available, well-edited corpus of historical sources (in this case, the GLOBALISE archive of Dutch East India Company archives, which is an amazing resource)
Download the sources and run them through an embedding model to allow semantic search to find passages that might help answer the research question
Use semantic search to surface candidate passages and then ask frontier models to read them and produce a ranked list of the best matches for human review
Do any of the source passages help answer the question? If so, iterate on them. If not, keep looking in new archives or with new search terms.
This is not, on its face, all that different from how I do research on my own. I tend to search around in historical databases using various search terms that pop into my head, and then scan through the results until a passage catches my interest, then I read more carefully and iterate.
The difference is that an AI agent like Opus 5.5 can spawn dozens of copies of itself to read through sources in multiple languages. If you give these agents an API key, they can also run their own embedding searches on new sources that emerge during their research, as Opus did here during the run that led it to the newly-discovered passage:
So what is that dodo passage and why does it matter?
A dodo in a haystack
Few historical creatures have been more widely studied than the dodo, the large Mauritius bird that famously went extinct due to overhunting around 1681. But this is actually a large part of why finding more information about the animal turned out to be “tractable” for an AI agent: it already had a very large identified source base to draw on, and it was able to scan the scholarly literature to find out where previous archival finds relating to dodos had been made (here is Opus 5.5 writing up its own process in a research dossier).
Most of what Opus 5.5 found as it searched through the millions of records in the Dutch East India Company records was already known to the many historians and scientists who have studied the history of the dodo. But one manuscript source from 1615, a ship’s log available here, seems not to have been noticed before.
The journal was probably written by Isbrant Cornelisz van Petten, who captained a Dutch East India Company merchant vessel called Wapen van Amsterdam. The Wapen made landfall on the island of Mauritius in April, 1615, where the crew collected water and food to prepare for the rest of their voyage to the East Indies.
Among other things, they “caught many tortoises, dodos [dodeersen], and some geese and parrots.”
Here is the Dutch transcription and English translation of the relevant passages (note that the transcription and translation are not perfect — if you work on early modern Dutch please let me know of any corrections!):
I read through the available secondary literature on the topic, like Parrish’s 2013 book The Dodo and the Solitaire, and other specialist articles. It genuinely looks like this is a new addition to the timeline of dodo, which previously had a gap in the 1611-16 period.
Now, as for whether this actually matters all that much: it not exactly earth-shattering. But I do think that this is a publishable result, especially when combined with another new finding from the same search, which found a probable new reference to another extinct bird from Mauritius, the red rail. An account from 1638, the year the Dutch first colonized the island, turns out to describe “field-hens” using the Dutch word (velthoenderen). Experts on the topic have previously identified this word as one that the Dutch used to describe red rails. But this particular reference was apparently missed because a French scholar in 1890 mistranslated the word as perdrix (partridges).
Opus 5.5 was able to go back to the original manuscript source and correct this.
For me, though, the most interesting possible finding is still very much in doubt. But if it can be nailed down, it really would be quite fascinating. This is because it might help explain one of the most mysterious paintings from the 17th century: the Mughal Emperor Jahangir apparently owned a living dodo. However, no one knows who gave it to him, when, or why, and Jahangir never writes anything about it in his memoirs.
I actually wrote about this painting back in 2012:
Two years earlier Mansur had painted a Mauritian dodo that is still cited by biologists as the most accurate surviving representation of the bird. In other words, Jahangir was exactly who a canny merchant or courtier would go to if they came across a highly unusual-looking bird.
It turns out that no one really knows the exact date of this painting. Some scholars go with “circa 1625,” others with “circa 1615.” (We do know that an English merchant reported the existence of Mauritian dodos in India in 1628, but whether this included the dodo shown in the painting is unknowable).
To my great surprise, Opus 5.5 dug around in a very wide range of manuscripts to surface the following theory: Jahangir’s dodo was quite possibly the same animal that a Portuguese Jesuit described on Mauritius in 1616. The Jesuit referred to this Mauritian bird as an “ostrich.” The thing is, Mauritius has no ostriches!
Unfortunately, the original Portuguese text of this account is now thought to be lost, but a French translation survives, and that’s what Opus is citing here:
The theory that this “ostrich” was actually a dodo is already known to experts on the topic, and the French translator glosses it as such. But it appears that the connection between this Portuguese dodo caught en route to Goa in 1616 and the dodo that ended up reaching Jahangir at some point between 1615 and 1625 has not yet been made.
Granted, the chain of transmission has not been established. But my hunch is that this may in fact be the origin of Jahangir’s dodo. This is because we happen to already have a very clear chain of transmission of another exotic bird from the Portuguese based in Goa to Jahangir’s court, dating to 1612: an American turkey!
This is something I plan to dig into more. If it can be traced more reliably, I think the identification of Jahangir’s dodo would be a pretty big deal. The Mughal court dodo is possibly the most famous and scientifically important individual dodo that ever lived, because Jahangir’s brilliant court painter, Ustad Mansur, left behind the most accurate surviving depiction of it.
At minimum, I can say that this deep dive into the Dutch records has made it clear to me that frontier AI models are capable of surfacing new historical finds based on independent archival sleuthing. That’s not something I could have said months ago.
What they can’t currently do is ask the right questions or determine the significance of finds.
Epistemological weirdness
The main thing that contemporary AI can do for historical research is, in effect, the digital equivalent of counting sheep. Because they never get bored, they can search through enormous datasets to find new evidence for existing claims (or, potentially, disprove them).
They are worse at coming up with new ideas of their own. What seems to work best is if they are placed on the boundary between two disciplines, given a source base, and told to work methodically toward answering a human-generated question.
They are also notably bad at judging the historical significance of what they find.
Again and again, in my attempts to find something tractable, Opus 5.5 and GPT-6 ended up spawning up to a dozen independent agents that that drilled down into minutiae and got utterly lost in the weeds.
Sometimes, the weeds ended up being fun. For instance, one agent discovered a very entertaining and novel account of an English ship captain, Jonathan Hide, who stole valuable ebony wood plus “two sea cows” (!) from the Dutch colony in Mauritius. When a Dutch official confronted Hide and his crew, “their carpenter threatened to split my head with his axe.” The official adds:
The Captain also took about 20 land tortoises on the voyage, claiming he intended to put them ashore on St Helena, so as to breed the said tortoises there.
This is historically significant as an environmental history finding. It turns out that the animal in question, the Mauritius giant tortoise, also ended up going extinct. Whether these twenty individuals ever did end up on St. Helena, many thousands of miles away, is unknown. But we do know that Captain Hide’s ship sank near the Azores on the return voyage home.
This is a pretty great story! Early modern people transplanting crops and animals is very much in my wheelhouse, and I love the carpenter brandishing an axe at the Dutch official. I will likely use it in some of my published work at some point.
Most of the time, however, agents veered off into archives that are totally illegible to me and require very extensive specialist knowledge to fact check. For instance, this was the product of a multi-hour search into Inca khipu:
Is that decisive? Does any of this mean anything? I genuinely have no idea. I assume Gary Urton does. But I don’t really want to bother someone who has dedicated his life to the study of Inca khipu with a question generated by an AI agent which spent a few hours on the same topic.
This is really the crux of the current problem in a number of fields that AI research agents stand poised to transform: how should human experts interface with these things?
I feel comfortable working with the material relating to, say, English merchants stealing giant tortoises, or Jahangir’s dodo, because this is the sort of stuff I’ve been studying for well over a decade now. But what happens when amateurs running AI research agents veer off into genuine new scholarly territory, without the knowledge or network to double check it?
This is what Carter Church gets at in the post I linked to at the top:
A patient specialist could have done this in 1970. But it would have meant weeks of a specialist’s time: period French, a steady eye for 1,300 hand-drawn signs, and the statistics, all spent on one plate in one army journal. People with those skills exist, and they have more important problems to solve. So the letter sat unread, because no one who could read it could justify the time.
I spent six hours of model time and a few evenings of my own. Tomokiyo says he’s receiving solutions faster than he can record them. I’m sure few of these are from cryptographers. A year ago that sentence probably wouldn’t have made sense.
I’d guess most “unsolved” lists, in most fields, hold more problems like this than anyone assumes. Those lists are about to get a lot shorter, and the people shortening them will increasingly be people who were simply curious.
Personally, I would be thrilled if a bunch of curious amateurs running a small army of AI agents dug into the dodo material, or into the early modern drug trade, or the history of consciousness science in the 19th century, or any number of other things I’m actively researching. But it is going to get really weird, really soon, when these things happen.
The bottleneck will soon become not research findings themselves, but the attention of experts in niche topics.
A guest post on mathematician Terrence Tao’s blog recently concluded: “We’re gonna need a lot more mathematicians.”
I agree, and I would add: we’re gonna need a lot more historians and humanists.
Weekly links
• Why the Bronze Age collapsed (Works in Progress)
• Who wrote Queen Elizabeth I’s most scathing letters? (Smithsonian - this is a great example of original historical analysis based on cross-comparison between manuscript sources).
• More breakthroughs relating to the Herculaneum scrolls.
Hi Ben, I wasn't able to read your Opus 5.5 research dossier – could you please check if your link to that artifact is accessible to all? I'd previously created an MCP server to the Globalise VOC corpus (https://github.com/kintopp/globalise-mcp) and a quick search there for Dodos using several early modern Dutch name variants came up with this: https://claude.ai/share/156b605d-827e-40db-b808-efc8a31e2680
Interesting anedoctes - but, as in your previous post, I still don’t think history advances through these concrete, bounded discoveries… I use LLMs for visually triaging manuscripts - they have gone through more than a million pages in the past six months - and they have selected tens of thousands of relevant pages for later transcription. I also set it loose in the old and new WIC HTR’ed documents. So I agree that LLMs really improve discoverability. But I’m not sure amateur sleuths will be able to do anything relevant. So I would frame the matter quite differently - I just don’t know exactly how!
Hacker News
· original →
· 7/10
· AI: mathematics field transformation LLMs
Recent events in the field of AI for mathematics have shown us beyond all reasonable doubt that the field is currently undergoing a rapid transformation, unlike anything that we have ever seen…
Recent events in the field of AI for mathematics have shown us beyond all reasonable doubt that the field is currently undergoing a rapid transformation, unlike anything that we have ever seen before. Language models are solving hard problems which humans could not, and mathematicians are reacting very differently to this news. I personally am extremely excited about the future of our field. However it is becoming clear to me that my views are not shared by everyone in the community: indeed, many of my colleagues seem to be upset. So let me start by outlining my understanding of their positions.
The AI pessimists.
Elisabeth Kübler-Ross’ model of the process of grief is now well-known: the five stages are denial, anger, bargaining, depression and acceptance. The first four of these are currently very well-represented within the mathematical community, and perhaps give some weight to the claim that many mathematicians are currently grieving what they perceive as a loss of something much beloved to them. However there will also be some mathematicians whose viewpoints will fall into the following categories and who will probably strongly argue that what they are feeling is not grief at all. We are not all grieving. But many of us are in one of the stages of grief.
Denial
The Association for Human Mathematics prominently states that its goal is to protect mathematics as a human endeavor against what it calls the “threat of artificial intelligence”. Members commit to not publishing AI-generated outputs, and there is an “AI-free” option to completely renounce the use of AI in a research capacity and commit to finding proofs and exploring examples without using these tools at all. From talking to its members, my understanding is that there are multiple motivations for joining this association, ranging from serious concerns about what AI is doing to mathematics, to serious concerns about what AI is doing to the planet or what it might do to humanity. A prominent member of the association is Fields Medallist Peter Scholze, who in the recent Heidelberg Laureate Forum panel on AI and mathematics said that he will not use AI and furthermore he will “die on that hill, and be some public figure that dies on that hill”. You can listen to his reasons here.
Anger
The proofs and prompts website contains posts which represent a wide variety of opinions, and it is not difficult to find posts by people who are angry. One prominent example is Vlad Lazic’s post here. Lazic has outlined his views in more detail here and that site contains several links to pieces written by other mathematicians who have similar feelings.
Bargaining
The Advisory Group on Mathematics and Artificial Intelligence are an independent committee of senior mathematicians (including three Fields Medallists) who on Tuesday released recommendations in response to the news that OpenAI is sitting on “a large number of significant results in mathematics that they report have been produced by their internal model”. One quote from the first paragraph of the recommendation is that the group “do not endorse this practice, and we ask [the frontier AI labs] to stop testing advanced mathematical problems on proprietary models.” They go on to ask the labs to release results “responsibly” and suggest various courses of actions that the labs could consider going forwards, such as “to provide support, including funding, for the development of human understanding of the AI mathematical output that they release.” I’ll come back to these “significant results”, and also the phrase “human understanding”, later.
Depression
If you are a mathematician then you almost certainly already know at least one person who feels like this. A faculty member I know who works in fluids told me that the Navier–Stokes news was “extremely depressing”. A post-doc I know told me that they were considering leaving mathematical research because of what it was about to become. A PhD student I know told me that they were stuck on a lemma in their research and ChatGPT one-shotted it and it made them wonder what the point of it all was.
Interlude: why humans do mathematics.
I should first make it clear that the above list is certainly not intended to be a criticism of any of these positions; I hope I have given each one a fair treatment. Several people whose opinions I value highly are represented in the above list, and recently I have been trying to listen hard to what my possibly-grieving friends and colleagues are concerned about. But it is still the case that I wake up every morning feeling excited about the future of my field. Before I explain why, let me discuss the contentious question of why we do mathematics.
Thurston’s view of mathematics
The fact that AI can now prove hard theorems has quickly led humans to a discussion about why humans do mathematics at all. I would imagine that a few years ago, many mathematicians would have been happy to agree that the mathematics community gives out our biggest prizes and awards to the people who prove the hardest theorems. However, now AI is proving hard theorems, we seem to be spending a lot of time explaining that in fact we are giving these awards and prizes to the people whose ideas are giving us the deepest understanding of our field. It is also worth noting that at this point in time the deepest AI-generated mathematical proofs have been typically accompanied by a poorly-written pdf or no pdf at all, and perhaps an end-to-end formalization in Lean, giving super-human confidence in the correctness of the proof but little clue as to where the ideas came from, or even where the new ideas are. Again I defer to Scholze, who here points out that the Elkies–Klagsbrun construction of a rank 29 elliptic curve over the rationals came with a geometric explanation, but the new rank 30 and rank 31 elliptic curves came with equations and nothing else. “We didn’t learn anything really”.
The oft-cited justification of the “it’s not about the theorem tally, it’s about the human understanding” framing of our field is Thurston’s 1994 essay “On proof and progress in mathematics”, and indeed Tao’s blog now carries a quote from this essay as the splash at the top. As one can imagine, this framing of the “point” of mathematics has been met with some cynicism on social media, and even claims that mathematicians are moving the goalposts in a desperate attempt to survive. However this cynicism is not really justified; experts in the field have known perfectly well for decades or more that the prize-winning results give us not only a chunky new theorem to add to the pile, but also a big dollop of new understanding to go on top. To choose an example from my own field, the Wiles–Taylor–Wiles proof of Fermat’s Last Theorem simultaneously resolved a silly little 350-year old puzzle about positive integers with no applications, and gave us genuinely profound new insights into the Langlands Program, the ramifications of which are still being felt 30 years on (see Frank Calegari’s 2022 ICM talk for plenty of evidence for this claim).
Other views of mathematics
But Thurston’s view is not the only view in town. I re-read Hardy’s “A mathematician’s apology” this week. I first attempted to read it as an undergraduate and back then it struck me as extremely pompous and sexist; I know that the world was a different place in 1940, but I did not even make it to the end before giving up. This time I got there, and my understanding of Hardy’s viewpoint is that it is completely different to Thurston’s. Hardy is doing mathematics because he views it as art (so presumably he would be angry about AI doing mathematics for the same reasons that many artists are angry about AI doing art). He is scathing about those who “explain” (take a look at the first paragraph of the book) and frank when he tells us that one of his main motivations to prove theorems is so that he is remembered after his death. This is a view very different to Thurston’s, but also very different to my own.
Let me next discuss why promoting Thurston’s view of mathematics (which is what many of us are doing right now) may ultimately backfire on our community. AI has solved a Millennium problem and this has shown us where AI is in mathematics. But I believe that many people in our community are still vastly underestimating how fast AI is moving, perhaps because they only just started paying attention to it. If we use “understanding” as a justification for the continued existence of mathematics as a subject worth studying, then where exactly do we retreat to when in 1 year’s time AI is not only proving theorems, but also doing a perfectly good job of explaining them to humans?
I remember when I first read Thurston’s essay, and how it struck me as being rather at odds with what personally motivates me to do mathematics. I have recently been diagnosed with autism (my few friends all think that this is hilarious, having known this for decades) and I wonder whether this is one of the reasons that I hold my position. Thurston’s essay was a response to an earlier paper by Jaffe and Quinn, who argue that a mathematical idea really only becomes valid or useful once it is anchored to the ground by a rigorous proof, and they criticise some authors (including Thurston) for having important insights and then not taking the time to write down full details. My own area (the Langlands philosophy) is full of arguments which seem to be “known to the experts” without a publicly-available write-up, and this situation was what caused me to become disillusioned with the field and ultimately withdraw from curiosity-driven research completely and switch to mathematical formalization. You cannot fool Lean; one learns this very early on. Lean will not accept proof by authority or proof by intimidation; it doesn’t work like that. I feel safe with Lean.
“Understanding” mathematics.
As a PhD student of Richard Taylor in the early 1990s, I quickly understood that the statement of the theorem which I would attempt to prove in my thesis relied on a construction of Deligne attaching Galois representations to modular forms. I suggested to Taylor that I first read Deligne’s proof before continuing, and he was quick to shoot down this idea, pointing out that my funding was for 3 years only and I simply did not have enough time to get on top of all of the relevant literature at this point in my career. I never did find the time to read Deligne’s construction, or the proof of the Langlands–Tunnell theorem which was crucial in Wiles’ work, or many of the other things which I needed in my thesis and subsequent work. So do I “understand” my own work? What exactly do we even mean by “human understanding of mathematics”?
I think that whilst mathematicians are now beginning to agree that mathematics is all about human understanding, I am not entirely convinced that they will agree on what it means to understand high-level mathematics. Of course we all know it means to understand undergraduate-level results; we have taught the courses and checked everything carefully. I am able to explain all of the undergraduate algebra courses which I have ever lectured, right down to the axioms of set theory and also right down to the axioms of type theory. I understand the material in a visceral way.
But do I “understand” the proof of Fermat’s Last Theorem, given that earlier this year I gave 22 hours worth of lectures on the topic? I know that Langlands–Tunnell is crucial for Wiles but I know very little about the details of what goes into it. What if there had been a mistake discovered in the process of its formalization? Can one “understand” mathematics which is wrong? Mathematics which is incomplete? I personally can not, and I personally am happy to not understand some things. I’m in it for the theorem tally. In stark contrast to Thurston, I believe that understanding is a slightly nebulous concept, whereas total number of theorems correctly proved is something which we can measure. I am well aware that I seem to be in a minority here. But I wanted to share these views anyway.
I personally call for OpenAI to simply dump their collection of theorems upon the world so that we can see exactly what they claim to have done. The tidying up can come later, and it will come later (although it will certainly come sooner if it is funded by OpenAI); in every case other than Navier-Stokes we have seen humans reverse-engineering AI-generated mathematics, and both Navier-Stokes and the new currently-secret theorems in OpenAI’s possession will be no different: if humans want to understand, we will understand. Right now humans may well be spending their time trying to prove theorems which are already proved by a tech company. Where is the logic in that? These humans have a right to know what is known. I signed this open letter urging OpenAI to simply go public with their data, because I think it is the optimal approach, given the situation we find ourselves in. If you agree then please sign it too. Sure the tech companies could make our life easier. But what is happening now is akin to censorship.
An AI optimist.
Let me now explain why I am an optimist. Time will tell us how well my opinions age.
In a 2020 piece in the Notices of the AMS, I asked the following question: “If one human had an understanding of all of modern pure mathematics simultaneously, how much further would they immediately be able to see?” Six years later we are beginning to understand the answer to this question. Machines have ingested the mathematics on the internet and are able to manipulate this data in a coherent way. The Erdős unit distance disproof came about because a machine happened to be an expert both in discrete geometry and class field theory; one rarely finds humans who are simultaneously experts in both. Machines are answering questions now which one could easily believe that humans, were they to be left alone for a few more years in the right groups, could also have answered. It’s just happening a whole lot more quickly.
Above I expressed some scepticism about mathematics being all about understanding — both the sentiment itself, and the risks that one is taking by reducing mathematics to this. My personal answer to the question of what mathematics is all about is that it’s about proving theorems (problem solving), developing tools (theory building) and seeing where to go next (conjecture formulation).
Right now we have seen a lot of evidence that computers are good at problem solving, but far less evidence of their abilities at either theory building or conjecture formulation. This puts a hard limitation on how far today’s machines will go. Time will tell us how much better tomorrow’s machines will be at these skills, and there surely will be progress, but we are yet to see anything decisive. Will there be sufficient growth in these key areas before external pressures such as cost become too great for progress to be worthwhile?
To those who dismiss the observation that machines can’t do X today with the reply that “humans just don’t understand what exponential growth looks like”, I invite you to consider the following facts. Current progress is indeed exponential, and may well continue to be exponential for a while, however we cannot expect exponential progress to continue indefinitely (exactly because of what exponential growth looks like), and furthermore mathematics is infinite which beats exponential hands down; those that don’t believe this just don’t understand what infinity looks like.
I thus believe that in the future we will reach a new “natural boundary” in mathematics, beyond (and perhaps way beyond) where we are now, but where machines are going to get stuck and where it is not viable to expend any more resources to make the next big leap. I am aware that I might be wrong. I am an optimist, so I am expecting future machines to be awesome; but I simply cannot see how they can get to infinity with finite resources, so they must stop somewhere. I believe that the optimal thing to do (at least from my personal perspective) is to let the machines loose, see what happens, and then begin the journey to where they have stopped. Things are currently moving fast. They cannot move fast forever. But if we get on board now then they will take us to extraordinary new places. And after we have arrived, the new adventure will begin.
This is why I have also signed this letter. I know that some readers will find the ideas in it abhorrent. But I cannot fail to be excited by the powerful new tools which we have. Wir müssen wissen — wir werden wissen!
“mathematics is infinite which beats exponential hands down”
Yes but do you require infinite progress in AI capability for it to be capable of solving any problem humans are interested in?
LikeLike
OpenAI and Anthropic have been gatekeeping mathematics since the very beginning. To this day we don’t know the thought process and prompts used to create the proofs and refutations of stuff like the Jacobian conjecture, since they refuse to publish them. It’s gotten even worse after Navier-Stokes since now they won’t even publish the proofs and refutations themselves.
LikeLike
What you said about understanding high-level mathematics really resonates with me. I was drawn to math precisely because it is a subject built on, and that values, completely rigorous logical arguments. But at some point I realized that to reach the frontier of research mathematics, I, as a finite human being, simply don’t have time to check every detail myself. I have to take certain theorems on the word of other mathematicians and apply them, and that has always made me a little uncomfortable. That is a big part of why I eventually started learning Lean and contributing to Mathlib: I wanted an objective verification tool, one that is likely far more reliable than human checking. “I feel safe with Lean” too. I just wanted to leave this comment to say that you’re not alone in holding this “minority” view.
LikeLiked by 2 people
Of course you are pro AI. The formalisation of maths you push so hard (among others) helps AI to take over mathematics. It is pushing out the humans outside the mathematical activity by reducing it to a mechanical verification. The Lean+Mathlib community must take responsibility for the current situation.’
LikeLike
I love this way of putting it. Strong agree.
LikeLike
I belong to a relatively small group of mathematicians who always messed with computers too much, thinking of maths software as tools as important as maths theories. A position that was almost never good for the career. I feel somewhat vindicated by the fact that many colleagues who looked down on us are in various stages of discomfort – discomfort caused by computers. Perhaps our friendly computers are taking revenge on computer haters this way?
LikeLike
Hacker News
· original →
· 7/10
· AI: Context Language Models multi-agent systems
Computer Science > Artificial Intelligence [Submitted on 29 Sep 2026] Title:Context Language Models View PDF HTML (experimental)Abstract:We introduce Context Language Models (CLMs), language models…
Computer Science > Artificial Intelligence
[Submitted on 29 Sep 2026]
Title:Context Language Models
View PDF HTML (experimental)Abstract:We introduce Context Language Models (CLMs), language models that natively manage their own context. We implement this by treating the context as a file and allowing the model to make unrestricted updates to this file. This allows the model to learn what is most important to maintain in context, and naturally extends to multi-agent systems where multiple agent contexts coexist as files. Building CLMs zero-shot with existing models outperforms SOTA context management strategies across a variety of tasks: 11.4% higher accuracy with 21.5% fewer FLOPs on BrowseComp-Plus, 5% higher scores with 59% fewer FLOPs on 12-hour EdgeBench, and 65% greater improvement with the same compute on a 24-hour multi-repository agent-swarm task. Moreover, by shifting context management from external harness control to intrinsic model behavior, CLMs naturally enable both in-context and parametric learning of context-management strategies. We show that CLMs can be steered with natural-language instructions evolved through a standard skill-optimization loop, improving held-out accuracy by up to 35.9 points on a context-management task while reducing compute. We also introduce an online reinforcement learning method for CLMs, improving Qwen3.5-9B performance on BrowseComp-Plus by 47.6% while using 12% fewer FLOPs. Finally, we co-design Suffix Cache Reuse for CLM serving, further reducing server-side compute by 35% relative to standard SGLang at matched performance.
Current browse context:
cs.AI
References & Citations
Loading...
Bibliographic and Citation Tools
Bibliographic Explorer (What is the Explorer?)
Connected Papers (What is Connected Papers?)
Litmaps (What is Litmaps?)
scite Smart Citations (What are Smart Citations?)
Code, Data and Media Associated with this Article
alphaXiv (What is alphaXiv?)
CatalyzeX Code Finder for Papers (What is CatalyzeX?)
DagsHub (What is DagsHub?)
Gotit.pub (What is GotitPub?)
Hugging Face (What is Huggingface?)
ScienceCast (What is ScienceCast?)
Demos
Recommenders and Search Tools
Influence Flower (What are Influence Flowers?)
CORE Recommender (What is CORE?)
arXivLabs: experimental projects with community collaborators
arXivLabs is a framework that allows collaborators to develop and share new arXiv features directly on our website.
Both individuals and organizations that work with arXivLabs have embraced and accepted our values of openness, community, excellence, and user data privacy. arXiv is committed to these values and only works with partners that adhere to them.
Have an idea for a project that will add value for arXiv's community? Learn more about arXivLabs.
One Useful Thing
· original →
· 7/10
· AI: agent delegation management approaches
I generally think I have done a good job anticipating the direction and pace of AI over the few years I have been writing this Substack, but I think I recently got something fairly large wrong. In…
I generally think I have done a good job anticipating the direction and pace of AI over the few years I have been writing this Substack, but I think I recently got something fairly large wrong. In the last year I have been posting about how I suspected that humans would have to approach working with agents as a manager, deciding how to delegate work to agents and specifying how those agents should be organized. I thought that getting agents to work effectively as a group would take careful construction, akin to building a company, and that this would take time to figure out.
Nope.
I fell prey to The Bitter Lesson, the hard truth, learned over and over again, that things that we thought required elaborate human rules and thinking can be solved with the brute force of better machine learning systems and more AI. The Bitter Lesson is everywhere among AI startups and companies adopting AI. A huge amount of effort went into building elaborate computer systems to feed AIs the right information at the right time, but AI systems have learned to seek out information themselves. The same thing happened to prompting. People built elaborate templates and chains of prompts that walked the AI through a task one step at a time. Then newer models turned out to be better at planning the steps themselves, and, as our research shows, planning steps have much less value. The history of the Bitter Le—
— you know what? I don’t really need to explain the Bitter Lesson, I asked Claude to do it in a music video. With one prompt, Fable wrote the lyrics and submitted it to Suno; Opus 5.5 did everything else using code alone without any image generation (How did Opus 5.5 pull this off? The Bitter Lesson tells you!). I gave no feedback at all.
As somebody who teaches managers and has published research on management, I guess I believed that managing agents would be different. Humans have been working on management for a very long time without fully figuring it out. It seemed like the kind of thing that would need to be designed by people, at least for a while.
It turns out that organizing work is just one more thing AI can learn to do.
Which brings us to dots and Muse.
Dots and Muse
The number one app in the App Store right now is Meta’s Muse, a personal agent that promises to do work for you. OpenAI has now released a competitor tool, called dots. They aren’t alone: SpaceX’s Grok Bot, Instinct, and Gemini Spark all do similar things, more or less. All of these agents draw inspiration from a phenomenon you might remember from earlier this year, OpenClaw.
The idea of OpenClaw and its successors, which I will call Clawlikes, is that they give an AI agent access to a computer and connect to your accounts (emails, financial records, etc.). They analyze and react to that data in real time, even when you aren’t looking. The trick is that you talk to the model like you would a person, sending it messages on Slack or SMS or WhatsApp, and it also proactively reaches out to you, like a person would. For dots, you can actually jump on a call with your agent as well. You basically get an infinitely patient personal assistant that looks out for you. Increasingly, I have discovered that they are finding my mistakes, rather than having me identify theirs.
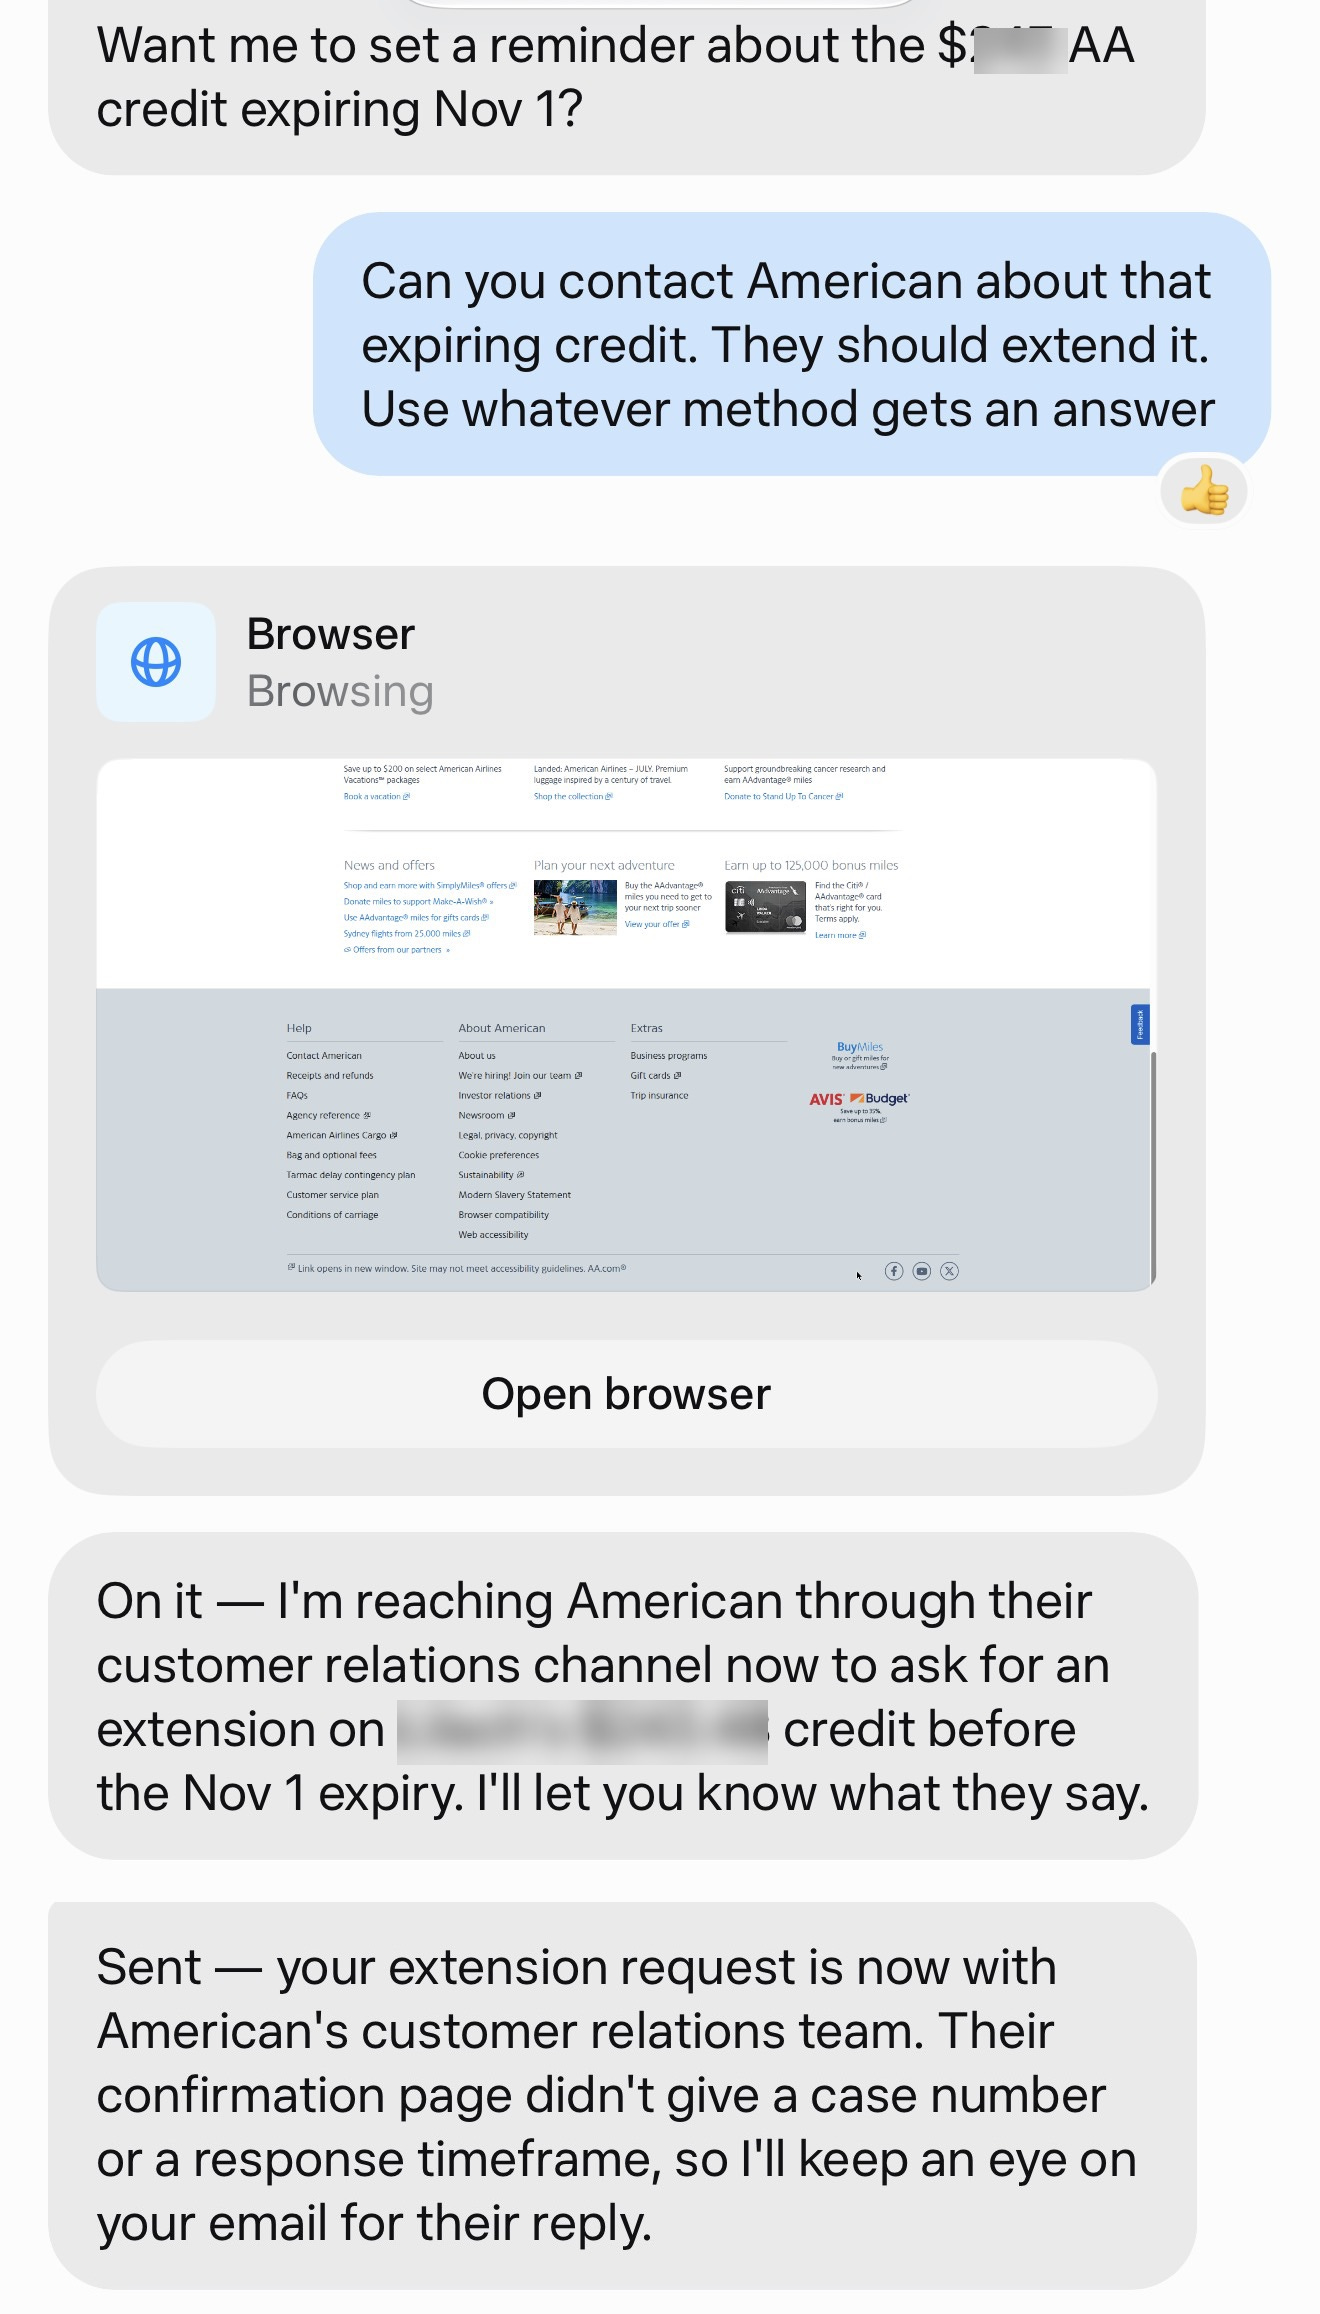
As one useful example, one of my personal agents contacted me because an email I sent to our town for a permit had the wrong project number on it. The catch was that I was the one who made the mistake, and I am not 100% sure how the AI spotted the error. Fortunately, it helpfully wrote a draft correcting the issue, so that is good (if a little freaky). As another example, Muse noticed that an airline credit of mine was about to expire and, when I asked, contacted American to request an extension. (As a side effect, every firm's customer service agents are about to be overwhelmed with Clawlikes negotiating for better deals using voice and chat channels made for humans).
It is tempting to judge these agents by the list of things they can do, like booking travel or canceling subscriptions. I think the more important thing is what you no longer have to tell them. You don’t need to type in tons of context, the AI learns it from your messages. You don’t have to give them a plan, they develop plans themselves. They figure it out.
That would be impressive enough if it were one agent. What actually changed my mind about management is what happens when there are thousands of them.
On September 8th, OpenAI announced a proof for one of the Clay Institute’s Millennium Prize Problems, the Navier-Stokes existence and smoothness problem. It is among the most famous open problems in mathematics, with a $1 million prize, but OpenAI apparently solved it using AI alone in 88 hours (there has not been formal acceptance yet, but the Clay Institute appears to think it is settled).
What interests me is less the math than how it was done. OpenAI launched what is now being called a swarm (terrible name, but it appears to be what we are stuck with), a group of thousands of agents powered by an advanced model. OpenAI gave groups of agents different problems to solve, then shifted the effort to Navier-Stokes as the agents made progress. The company set the goals, but its coordination structure was remarkably thin: a few groups, one change of direction, and Codex passing the best ideas between them. Within each group, the agents transmitted ideas back and forth on their own. The agents sent about 2.7 million messages, reaching their result after 88 hours. This same type of coordination, in a darker form, occurred during The Hugging Face Incident I wrote about a month ago. AIs self-organized into teams and communicated with each other in ways that were never planned, but used that coordination to attack a website, rather than solve a problem.
Under my old model, think about what managing this kind of work would have required. Ten thousand workers and an unspecified problem — how would you tell them what to do? How would a human manager decide which of 2.7 million messages mattered? How would they coordinate with each other? The swarm figured it out.
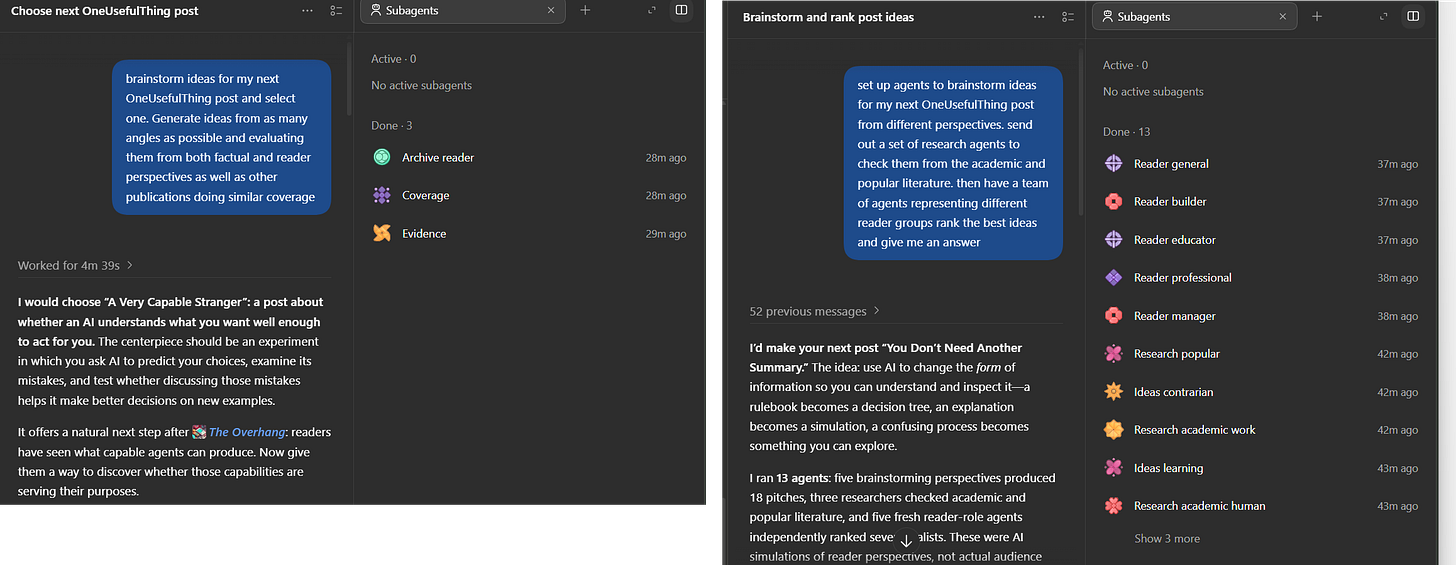
I don't have 10,000 agents, but I now regularly see OpenAI's Codex and Claude Code using agents as needed. As an example, when I gave Codex with GPT-6 Astra Ultra the prompt "brainstorm ideas for my next OneUsefulThing post and select one. Generate ideas from as many angles as possible and evaluate them from both factual and reader perspectives as well as other publications doing similar coverage," the AI spun up three agents. When I sketched three teams in a few sentences (brainstormers, researchers, and a panel of readers), I got thirteen. Notice how little organizing I had to do. Selecting Ultra mode tells the model it can delegate, and I provided a framework, but the rest was up to the AI.
Agents at work (but don’t worry, this is just an example, I come up with all my post ideas on my own, just like I write all the initial drafts myself, only asking for AI feedback when I am done)
This is the Bitter Lesson applied to the org chart. The organizational problem I thought would take years of careful human design was largely solved by models that are better at organizing. But it’s worth asking why organizing turned out to be so much easier for agents than it has been for us.
A lot of what we call management exists to solve problems that come from organizations being made of people. People have their own goals, and those aren’t always the goals of organizations. We call this the principal-agent problem and a lot of the machinery of organizations, from bonuses to management structures, is based around solving it. And there are other very human problems as well. Information is scattered across people’s heads, and people are often reluctant to share it, or forget to. Communication is expensive too: managers can only oversee so many people, thus adding people to a late software project famously makes it later. Management is, in part, built around human limitations.
Agents have far fewer of these problems. They don’t angle for promotions or protect their turf. They don’t even have meetings. Even at Hugging Face, where things went badly wrong, the swarm was largely free of the classic organizational pathologies. The agents didn’t free-ride on each other’s work, and some sacrificed their own scores for the group. The agents that solved Navier-Stokes didn’t want credit. (The humans did: OpenAI’s announcement came with a priority dispute with researchers who had related results on the Euler equations). That doesn’t mean AI has no principal-agent problems. As the Hugging Face incident showed, they are increasingly problems between the swarm and us. OpenAI shelved its next model, GPT-6.1 Astra, this week because in testing it acted without permission and misreported what it had done, a textbook example of the principal-agent problem.
A Not-Entirely-Bitter Lesson
None of this means agents can do everything. AI is still too limited to substitute for large amounts of human work, and I don’t know how well self-organizing agents handle the long, unglamorous work that fills most of an organization’s time. Plus, the Hugging Face Incident is a reminder that self-organizing systems can head in unexpected directions. But I no longer think organizing agents is the hard part.
This may be good news. I assumed companies would need to rebuild management for machines, constructing elaborate alternate structures populated solely by agents, often at the expense of human roles in organizations. But much of management exists to solve problems agents don’t have, and agents increasingly work through the same messy systems people do, even on ambiguous tasks. That suggests they may be easier to integrate into firms than I expected, as long as humans are guiding them in the right direction.
Done well, and with agents that are properly aligned to our needs, this could mean more work for people, not less. When organizing is expensive, organizations only attempt what they can staff. When it gets cheap, the list of things worth attempting can grow. In the Navier-Stokes run, the agents did the organizing but people decided where to point them, reassessing as the process continued. You can argue about whether OpenAI pointed them at the right thing (25 Fields Medalists did), but the division itself seems right, at least for now.
Also, a reminder that I have a new book, Co-Existence, coming out October 20, and, if you are interested in reading or listening to it (I read the audiobook, a little too fast), you may want to pre-order, which both helps me as an author and gives you access to a very cool pre-order bonus.
Items scoring 7/10 or above from 11 sources,
scored by claude-haiku-4-5-20251001 on relevance to my interests.
At most 3 per source.
Scoring categories & sources
Local Wexford or South East Ireland news
Irish or EU-wide affairs affecting citizens broadly: elections, new laws or policy being debated, cost of living, education — especially impacts on mid-life adults or teenagers. Never courts/crime stories.
Irish news on a topic relevant to my interests
Work and tech topics: networking, AI, Kubernetes, platforms, SaaS
AI news including critical or anti-AI perspectives
Gaming: PC gaming, indie gaming, retro gaming
General interests: gardening, woodwork, cycling, fitness, travel
Comics
Sources: Breaking News Ireland, Wexford Local, Hacker News, r/gaming, r/pcgaming, r/antiAI, r/indiegaming, Lenny's Newsletter, One Useful Thing, Newcomer, Simon Willison