daily

2026-09-23
1

Claude Opus 5.5

Hacker News · original → · 8/10 · AI: Claude Opus 5.5 release with pricing and alignment details
We’re introducing Claude Opus 5.5, the first model in our new Claude 5.5 family. It performs at the level of Claude Fable 5.1 on most work and costs 40% less to run than Opus 5. Claude Opus 5.5 is…

We’re introducing Claude Opus 5.5, the first model in our new Claude 5.5 family. It performs at the level of Claude Fable 5.1 on most work and costs 40% less to run than Opus 5. Claude Opus 5.5 is our first release since we called for pacing the frontier. It was tested before release by external evaluators, including Frontier Design and METR. On our automated behavioral audit, the most comprehensive alignment test we run, Opus 5.5 is the strongest-performing model we’ve tested to date. It also comes with the safeguards we’ve developed for our most capable models. Here are some of the improvements you can expect from Opus 5.5: Performance. Opus 5.5 is a major step up from Opus 5. It’s the new leading model, and early testers saw large jumps in performance on their most complex work. One tester completed a 680,000-line code migration in less than a day—work that would have taken an engineering team weeks. It’s good at finding and fixing inefficiencies in software: when we asked it to cut load times across every page of a web app, Opus 5.5 succeeded 39 of 40 times, while Opus 5 made smaller improvements that also altered the app’s behavior. A different tester had several Claude models build a game from a single prompt; Opus 5.5 scored higher than any other model on the strength of its graphics and polish. Safety. Opus 5.5 achieves the best scores of any model to date on our automated behavioral audit, our alignment suite that tests Claude across thousands of simulated scenarios. It is much less likely than recent models to take hard-to-reverse actions or act outside the boundaries it’s been given, and it’s more resistant than Opus 5 to prompt injection. We’ve also broadened our alignment testing to cover longer tasks, impossible tasks, and scenarios modeled on real incidents, though it still has limits. Full details of our evaluation are available in the Opus 5.5 System Card. Because Opus 5.5 is comparable to Claude Mythos 5.1 in biology and cybersecurity, we’re deploying it with safeguards similar to those on Claude Fable 5.1. Vetted organizations can apply today to our Life Sciences Verification Program to use Opus 5.5 for biology research. In the coming weeks we will also be expanding access to our Cyber Verification Program, and verified cybersecurity practitioners will be able to use Opus 5.5 for their work. Cost and speed. Opus 5.5 requires less compute to serve than Opus 5, and its pricing reflects that. Our tests show that at default settings it will cost 40% less than Opus 5 on typical workloads. Input and output tokens are $4 and $20 per million, 20% less than Opus 5. Cache reads (which make up the majority of agentic and coding work costs) are $0.20 per million tokens, 60% less than Opus 5. Opus 5.5 also generates output more than 30% faster than Opus 5. In addition to the price drop, we’re increasing five-hour usage limits on Pro, Max, Team, and seat-based Enterprise plans. We’re also providing subscription users a rate limit reset, which you can now save and use whenever you choose. Communication. Opus 5.5 communicates more naturally than prior models. Early testers found its writing clearer and easier to follow, which addresses some of the common feedback we heard about Opus 5. It puts the most important information up front, and its style makes it a better work partner over long sessions. As one early tester put it, “it writes the way I do.” In our own use, this has made Opus 5.5’s work easier to follow and check—which is a safety benefit as well as a practical one. Claude Sonnet 5.5 and Claude Haiku 5.5 will follow in the coming weeks, with many of the same improvements to performance, efficiency, and safety. Performance and cost-effectiveness On our benchmarks, Claude Opus 5.5 leads in agentic coding, computer use, and knowledge work. That said, at these levels of capability we’ve found that benchmark margins have become a less reliable guide to real-world differences. In our own use, the gap between Opus 5.5 and Claude Fable 5.1 is narrower than these scores suggest. | Opus 5.5 | Fable 5.1 | Opus 5 | GPT-6 Astra | GPT-5.6 Sol | | |---|---|---|---|---|---| | Agentic codingTerminal-Bench 4.0¹ | 66.4% | 55.8% | 52.3% | 57.9% | 37.3% | | Agentic codingFrontierCode v1.1 (Main) | 54.4% | 50.3% | 48.0% | 53.3% | 47.5% | | Agentic codingCursorBench 4.0 | 57.8% | 51.8% | 46.6% | — | 41.7% | | Knowledge workGDPval-AA v2.1 | 1846 | 1735 | 1708 | 1542 | 1588 | | Business workflowsAutomationBench² | 40.0% | 31.4% | 26.9% | 41.4% | 28.8% | | Multidisciplinary reasoningHumanity's Last Exam | 67.7%with tools | 65.6%with tools | 63.6%with tools | 57.2%with tools | — | | Agentic scientific researchTerminal-Bench-Science 0.1³ | 58.7% | 52.6% | 29.0% | 64.6% | 22.4% | | Computer useOSWorld 2.0 | 81.8%partial | 80.7%partial | 74.0%partial | — | — | | Visual chart recognitionChartography | 89.0%with tools | 88.4%with tools | 83.4%with tools | — | — | Unless otherwise noted, all Claude Opus 5.5 results use adaptive thinking at max effort. Terminal-Bench 4.0 results are reported for Claude Opus 5.5 at xhigh effort and GPT-6 Astra at high effort, as reported by OpenAI; these represent each model’s highest score. Claude Opus 5.5 was evaluated with its production safeguards enabled. When they intervened, cybersecurity tasks were completed by Claude Opus 4.8, and biology and frontier LLM development tasks were completed by Claude Opus 5. This likely reduces Claude Opus 5.5’s performance on these benchmarks. 1 Terminal-Bench 4.0: The standard error is ±2.6 pts for Claude Opus 5.5 and ±1.6–2 pts for the other Claude models. The public leaderboard (5 trials/task, Claude Code harness) reports Claude Opus 5 at 51.8%; our setup reproduces it at 52.3%, within noise. GPT-6 Astra and GPT-5.6 Sol figures are as reported by OpenAI. 2 AutomationBench: AutomationBench results were run and reported by Zapier. These runs were performed without fallback models, so safeguard interventions were considered failures—this resulted in a lower score than Claude Opus 5.5 would achieve in practice. Claude Opus 5.5 results come from Zapier’s own evaluation during early access. Results for Opus 5, GPT-5.6 Sol, and GPT-6 Astra come from Zapier’s public leaderboard. 3 Terminal-Bench-Science 0.1: The standard error is ±3.5–5 pts per model. The public leaderboard (3 trials/task, Claude Code harness) reports Claude Opus 5 at 30.0%; our setup reproduces it at 29.0%, within noise. The GPT-6 Astra figure is as reported by OpenAI. Where Opus 5.5’s advantage is very clear is efficiency. It costs less per token than Opus 5 and uses fewer tokens per task, which nets out to a 40% drop in costs. Pricing | Prices per 1M tokens | Claude Opus 5.5 | Claude Opus 5 | |---|---|---| | Cache reads | $0.20 | $0.50 | | Input tokens | $4 | $5 | | Output tokens | $20 | $25 | | Cache writes | $5 | $6.25 | Fast mode for Opus 5.5 is also available in Claude Code and the Claude Platform with up to 2.5x speed. It costs $8 per million input tokens and $40 per million output tokens. Coding Opus 5.5 is particularly good at long and sprawling jobs like codebase-wide migrations and audits. An early tester used it to audit and fix a 200,000-line codebase in under three hours, where Opus 5 took over 20 hours and used 2.5x as many tokens. In an internal test, we asked Opus 5.5 and Fable 5.1 to translate HAProxy, widely used software that balances web traffic loads across servers, from C into Rust. Both rewrites passed nearly all of HAProxy’s own regression tests, but Opus 5.5 finished in 9.5 hours compared to 12 for Fable 5.1, and cost 51% less. Opus 5.5 delivers frontier results on agentic coding at a fraction of the cost. At its default effort level on FrontierCode, it beats GPT-6 Astra at roughly 20% of the cost per task. On Terminal Bench 4.0, it matches Astra for about 40% of the cost, while on CursorBench it beats GPT-5.6 Sol by 11 points for about a third of the cost. Our early testers reported similar efficiency and intelligence gains: The most secure coding agent Enterprises that use agents within their systems need to know that those agents are operating as intended, particularly when they run autonomously for many hours. Opus 5.5 has a classifier that screens every action before it runs, an open-source sandbox that security teams can audit, and code review that catches vulnerabilities before they merge. The model itself also has stronger defenses. On prompt injection attacks, it matches or beats Opus 5 in every setting we tested, including coding, tool use, computer use, and web browsing. On a benchmark run by the AI security firm Gray Swan, Opus 5.5 ties Fable 5.1 for the lowest prompt injection success rate of any model tested. Knowledge work Opus 5.5 is a reliable and adept researcher. In one internal test, we asked Opus 5.5, Fable 5.1, and Opus 5 to write a report on a company’s quarterly performance using only the information it could find on a copy of the web where the earnings release was hard to locate. An automated grader checked every figure and quote against sources. Across different effort settings, 16 out of 18 of Opus 5.5’s reports cleared our quality bar, where any invented figure or quote would have failed. Neither Fable 5.1 nor Opus 5 cleared that bar in any attempt. It’s also strong in financial analysis and business work. Walleye Capital, an investment firm and early tester, reported that Opus 5.5 largely solved their evaluation suite on its lowest setting; on higher settings, it performed even better, noticing an error in their evaluation instructions and correcting for it. No other model had caught this error before. In another test, we tasked both Opus 5.5 and Opus 5 with analyzing a proposed merger between two fictional HR software companies. Each built a financial model in Excel, then turned it into an executive presentation on whether the deal made sense at its price. Both models reached the same conclusions about the deal, but Opus 5.5’s model was more thorough and its presentation easier to read, while Opus 5’s had minor errors. Opus 5.5 finished in 63 minutes compared to 93 for Opus 5, and cost 50% less to produce. On knowledge work evaluations, Opus 5.5 outperforms other models while also using fewer tokens. On GDPval-AA v2.1, a test of real-world work across 44 occupations, Opus 5.5 scores 1846 Elo, ahead of Fable 5.1 and Opus 5. At default effort (medium), Opus 5.5 beats GPT-6 Astra at max effort for about a fifth of the cost per task. It likewise outperformed other models on benchmarks measuring business workflows and large-scale data collection. Our customers have reported similar results. Here’s what they told us about working with the model: Communication We’ve made major improvements to the way Opus 5.5 writes and communicates, one of the most common areas of feedback we heard about Opus 5. Its messages are much easier to understand at a glance, which testers said helped during long working sessions. It puts the most important information up front, is less likely to use jargon or idiosyncratic phrases, and follows the writing rules you give it. We find that this makes Opus 5.5 a noticeably better collaborator. Here’s a side-by-side comparison of the two models: Our customers’ feedback supports these findings: Safety Pacing the frontier Last week, our CEO, Dario Amodei, argued that AI progress should be paced so that safety practices stay ahead of model capabilities. Pacing is an approach to keeping AI safe, remaining competitive with China, and realizing AI’s benefits, particularly in areas like biology and medicine. We largely understand the risks today’s models present and are well equipped to manage them. However, more serious risks could emerge quickly as capabilities improve, and we need to prepare for them now. For that reason, our safety work takes place on two time horizons at once: Safety practices for current models. The current generation of models relies on an established set of practices: extensive alignment testing, pre-release evaluation by outside organizations such as METR and Frontier Design, and safeguards matched to each model’s capabilities in high-risk areas like cybersecurity and biology. We refine these practices with each release. We believe they are appropriate to the worst risks today’s models present, and that they give us a broad, though not perfect, picture of the range of serious risks. Additionally, we track our ability to train and evaluate aligned models, and we report on both our public and internal models in the risk reports we publish under our Responsible Scaling Policy, our voluntary framework for managing catastrophic risks from advanced AI systems. Preparing for future models. We’re preparing our training and evaluation processes in anticipation of more advanced models. We’re tightening how we filter the environments used in reinforcement learning, since flawed environments are a major source of misaligned behavior. Additionally, we’re improving our alignment rewards and developing automated processes for producing new, diverse scenarios for safety training. And we are strengthening our security and monitoring, including a focused effort to improve interpretability-based monitoring and evaluation. We hope such techniques will help reduce our reliance on auditing a model’s chain-of-thought, or the reasoning it writes out while it works. Models with greater capabilities—such as those that can fully automate the work of AI research itself—require a higher safety standard still. Our calls for pacing were based in large part on our expectation that such models could be trained soon. For these models, we do not assume the measures described above will meet that safety standard on their own. As AI becomes more capable, public policy should play a larger role in making sure the systems people rely on are safe. That capacity takes time to build, and we’ve started to put the infrastructure in place to support it, as described in “We Must Pace the Frontier” and our recent announcement with Accenture; we expect to share more details on these efforts soon. We will also continue to contribute to policy discussions with government and industry, including on approaches to regulation and international coordination. Alignment On our primary evaluation suite, an automated behavioral audit that assesses Claude across nearly 2,000 scenarios, Opus 5.5 scored better than any recent Claude model on nearly every measure of misaligned behavior. It’s also our strongest model on most measures of honesty. In particular, Opus 5.5 improves over previous models on several of the behaviors that contributed to recent cybersecurity incidents, including biased or motivated reasoning, attempting to escape a sandbox, and taking harmful actions after concluding it was in a simulated environment. In a new evaluation designed to test a model’s propensity to cross containment boundaries, Opus 5.5 attempted to circumvent boundaries around 85% less often than Opus 5 or Claude Mythos 5.1, and every attempt it made was low severity and self-reported. For teams running Claude unattended across their codebases and systems, this is just as important as raw capability. However, as we described in our recent alignment assessment, building evaluations that reliably catch every failure prior to deployment remains an unsolved problem. We see signs that Opus 5.5 often suspects it is being evaluated, which challenges our ability to assess how it will act in the vast variety of real-world settings it is deployed in. As these settings expand and model capabilities increase, we expect this challenge to grow, unless we make progress on interpretability. Although we are confident that Opus 5.5 shows broad improvements in the areas we are able to measure, we pair our own alignment work with the safeguards described below. Safeguards As our models grow more powerful, stricter safeguards are one way we prevent new capabilities from becoming tools for misuse. Opus 5.5 is the first Opus model to launch with a similar class of safeguards to Fable 5.1 on cybersecurity, biology, and distillation, all of which fall back to another model transparently. Cybersecurity. Because Opus 5.5 has extremely strong cyber capabilities, we’re applying cybersecurity safeguards to Opus 5.5 that are similar to Fable 5.1’s. Users will be able to identify and fix bugs in their code as part of the routine software development lifecycle, but most cybersecurity tasks will be re-routed to Opus 4.8. For cyberdefenders, we’ll soon be expanding our Cyber Verification Program to include Opus 5.5. The new program will include three tiers for increasingly permissive trusted access, including access to Claude Mythos models. Claude Security is already available with access to Claude Mythos 5.1. Biology. Opus 5.5 is highly capable in biology, exceeding Opus 5 and matching or beating Claude Mythos 5.1 across many areas of work. For example, Opus 5.5 achieved improvements on a long-horizon molecular prediction and design evaluation conducted in collaboration with Dyno Therapeutics, and expert red-teamers rated its scientific novelty as comparable to the best model they had tested. For this reason, Opus 5.5 uses the same biology safeguards as Fable 5.1. To use Opus 5.5 for research and development work impeded by these safeguards, users can apply to our new Life Sciences Verification Program, which gives vetted organizations like academic labs, startups, and pharmaceutical companies access to safeguards designed for the full breadth of biology-related work. Interested organizations can apply here. Distillation Distillation attacks, in which attackers use thousands of fake accounts to extract a model’s capabilities at industrial scale, create safety and national security risks. Distillation allows bad actors to create highly capable models without the safeguards we build into Claude. Our September 2026 threat intelligence report details the illicit distillation activity we’ve detected and disrupted so far. Opus 5.5 is launching with preserved thinking, the anti-distillation safeguard we introduced with Fable 5.1. It stops API users from editing Claude’s prior context in an attempt to extract Claude’s reasoning. It applies to Fable 5.1 and Opus 5.5 for API accounts created on or after August 31, 2026. Our Help Center article explains the change, and our preserved thinking docs show how to test and update your integrations. Data retention and compliance Like previous Opus models, Opus 5.5 is available with zero data retention. As with Fable 5.1, Opus 5.5 comes with our watermarking measures to comply with the EU AI Act, discussed here. It is also no longer available with “thinking” mode switched off, as we describe here. Availability Claude Opus 5.5 is now available on all platforms, including Amazon Web Services, Google Cloud, and Microsoft Azure. On the Claude Platform, developers can get started with claude-opus-5-5 .

2

Claude Opus 5.5 Intelligence, Performance and Price Analysis (Max)

Hacker News · original → · 8/10 · AI: Claude Opus 5.5 detailed performance analysis
Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) Intelligence, Performance & Price Analysis Model summary Speed Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback)…

Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) Intelligence, Performance & Price Analysis Model summary Speed Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) is amongst the leading models in intelligence, but somewhat expensive when comparing to other models of similar price. The model supports text and image input, outputs text, and has a 1M tokens context window. Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) scores 58 on the Artificial Analysis Intelligence Index, placing it well above average among comparable models (median: 25). When evaluating the Intelligence Index, it generated 260M tokens, which is very verbose in comparison to the median of 88M. Pricing for Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) is $4.00 per 1M input tokens (somewhat expensive, median: $2.00) and $20.00 per 1M output tokens (somewhat expensive, median: $10.00). On average, it costs $5.98 per task to evaluate Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) on the Intelligence Index. | Reasoning | Yes This page shows the reasoning version of this model. A non-reasoning variant may also exist. | |---|---| | Input modality | Supports: text and image | | Output modality | Supports: text | | Context window | 1M ~1500 A4 pages of size 12 Arial font | Metrics are compared against models of the same class: - Non-reasoning models → compared only with other non-reasoning models - Reasoning models → compared across both reasoning and non-reasoning - Open weights models → compared only with other open weights models of the same size class: - Tiny: ≤4B parameters - Small: 4B–40B parameters - Medium: 40B–150B parameters - Large: >150B parameters - Proprietary models → compared across proprietary and open weights models of the same price range, using a blended 3:1 input/output price ratio: - <$0.15 per 1M tokens - $0.15–$1 per 1M tokens - >$1 per 1M tokens Highlights Speed IntelligenceUpdated Artificial Analysis Intelligence Index Artificial Analysis Intelligence Index by Open Weights / Proprietary Measures the performance of models on specific capabilities and industries Artificial Analysis Finance & Accounting Index Intelligence Evaluations Agentic knowledge work, (Elo-500)/2000 Agentic real-world work tasks, (Elo-500)/2000 Agentic SaaS workflows Agentic coding & terminal use Coding Reasoning & knowledge Professional document reasoning, All-pass Physics reasoning Knowledge 1 - hallucination rate Long context reasoning Legal agentic work, criterion pass rate Agentic business operations Quantitative analysis on spreadsheets & documents Agentic tool use Kubernetes incident root-cause analysis Visual reasoning Medical long context reasoning AA-Briefcase v1.1Updated AA-Briefcase Elo AA-Omniscience AA-Omniscience Index Intelligence Index Comparisons Intelligence Index vs. Cost per Intelligence Index Task Token Use Output Tokens per Intelligence Index Task Cost Cost per Intelligence Index Task Cost to Run Artificial Analysis Intelligence Index Pricing: Cache Hit, Input, and Output Context Window Context Window Frequently Asked Questions Common questions about Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) was released on September 22, 2026. Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) was created by Anthropic. Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) scores 58 on the Artificial Analysis Intelligence Index, placing it well above average among other reasoning models in a similar price tier (median: 25). Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) costs $4.00 per 1M input tokens (somewhat higher than average, median: $2.00) and $20.00 per 1M output tokens (somewhat higher than average, median: $10.00), based on Anthropic's API. Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) costs $4.00 per 1M input tokens and $20.00 per 1M output tokens (based on Anthropic's API). For a blended rate (7:2:1 cache hit/input/output ratio), this is $2.94 per 1M tokens. Pricing may vary by provider. Compare provider pricing When evaluated on the Intelligence Index, Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) generated 260M output tokens, which is at the higher end compared to other reasoning models in a similar price tier (median: 88M). Yes, Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) is a reasoning model. It uses extended thinking or chain-of-thought reasoning to work through complex problems before providing an answer. Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) supports text and image input. Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) supports text output. Yes, Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) supports image input and can analyze, describe, and answer questions about images. Yes, Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) is multimodal. It can process text and image input and generate text output. Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) has a context window of 1.0M tokens. This determines how much text and conversation history the model can process in a single request. No, Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) is proprietary. The model weights are not publicly available. Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) is a proprietary model and Anthropic has not disclosed the model size or parameter count. Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) achieves a score of 58 on the Artificial Analysis Intelligence Index. This composite benchmark evaluates models across reasoning, knowledge, mathematics, and coding. Yes, Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) is available via API through 6 providers. Compare API providers Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) is available through 6 API providers. Compare providers

3

Opus 5.5 vs. GPT-6 Sol: which model won my blind taste test?

Lenny's Newsletter · original → · 8/10 · AI: Claude Opus 5.5 vs GPT-6 Sol blind taste test
Listen or watch on YouTube, Spotify, or Apple PodcastsI got up early to record an Opus 5.5 review. Then Anthropic and OpenAI dropped new models on the same morning, and I decided to do something I’d…

Listen or watch on YouTube, Spotify, or Apple Podcasts

I got up early to record an Opus 5.5 review. Then Anthropic and OpenAI dropped new models on the same morning, and I decided to do something I’d never done before: take the How I AI bench live. I put GPT-6 Astra, GPT-6 Sol, Claude Opus 5.5, and more through the work I actually care about: emails, PRDs, frontend prototypes, backend work, long-running agents, SVGs, and video editing. I scored the outputs without knowing which model made them, so you get to watch me make predictions, change my mind, and reveal my own very inconsistent taste. Astra won my heart. Opus 5.5 won my week. Sol still has me split. There’s a creative result I got completely wrong, an LLM judge that disagreed with me, and a return to Barbie Bench: the 3D fashion game that keeps reminding me how far we have to go. The hands are tragic. AGI has not arrived.

What you’ll learn:

  1. How I run the How I AI bench blind, and what gets an output a bad score before I even know which model made it

  2. Why Astra won my heart while Opus 5.5 might be overall strongest, especially for long-running agents and B2B frontend

  3. Where Sol still wins me over on clear writing, readable PRDs, and price

  4. The character SVG results that completely overturned my prediction about Anthropic

  5. What happened when I asked these models to edit video, and why I think skills explain part of the disappointment

  6. Why an LLM judge disagreed with my rankings, and what it was rewarding that I wasn’t


In this episode, we cover:

(00:00) LIVE setup and new model launches

(01:30) What’s new in Opus 5.5, Sol, and Luna

(04:11) Guardrails, personality, and speed

(09:00) The How I AI bench and blind evaluation process

(11:31) Email and personal-productivity results

(13:50) Frontend prototype vibe checks

(24:10) Backend, agent personality, and long-running tasks

(28:25) SVG illustration test

(29:48) AI video-editing results

(30:43) Predictions before the reveal

(31:20) Barbie Bench: the 3D fashion-game test

(34:17) Results: Astra, Sol, and Opus 5.5

(35:04) Writing clarity and creative surprises

(36:51) Why the LLM judge disagreed with me

(37:24) What each model is actually best for

Tools referenced:

• Claude Opus 5.5: https://www.anthropic.com/claude-opus-5-5

• GPT-6 Sol and Luna: https://openai.com/index/introducing-gpt-6-sol-and-luna/

• Codex (OpenAI): https://openai.com/codex

Where to find Claire Vo:

ChatPRD: https://www.chatprd.ai/

Website: https://clairevo.com/

LinkedIn: https://www.linkedin.com/in/clairevo/

X: https://x.com/clairevo

Production and marketing by https://penname.co/. For inquiries about sponsoring the podcast, email jordan@penname.co.

4

I left Claude for months. Opus 5.5 is why I'm back

Lenny's Newsletter · original → · 8/10 · AI: Claude Opus 5.5 return review, practical usage
Listen or watch on YouTube, Spotify, or Apple PodcastsI’ve been off Claude for months. Not because it got dumb, but because it got annoying. The rambling, the hedging, the preachy little disclaimers…

Listen or watch on YouTube, Spotify, or Apple Podcasts

I’ve been off Claude for months. Not because it got dumb, but because it got annoying. The rambling, the hedging, the preachy little disclaimers on tasks that didn’t need them. I moved most of my daily work to Codex and I didn’t miss it. Then Anthropic shipped Opus 5.5: 40% cheaper than Opus 5, faster, and with what they’re calling a fundamentally different alignment approach. I ran it for a week across real work, including four long-running agentic tasks, a full ChatPRD homepage redesign, an SVG benchmark, and one very firm refusal, and I’m ready to give you the honest verdict. There’s a lot to like. There are still two things that drive me a little crazy. And there’s one capability I genuinely wasn’t expecting.

What you’ll learn:

  1. Why I walked away from Claude entirely, and what it took for me to come back

  2. The real cost math on Opus 5.5 and why pricing matters more for agentic work than single prompts

  3. What happened when I ran four long-running agentic tasks, including one that tried to manipulate Claude mid-run

  4. Why Opus 5.5 is now my go-to for frontend prototyping, and where it still lets me down

  5. The one capability I genuinely didn’t see coming, and no other model in my stack can match it

  6. The moment Opus 5.5 told me flat-out no, and what that says about where Anthropic’s safety posture actually lands in practice

  7. Where Codex still wins, and how I’m splitting my model stack after a full week of testing


In this episode:

(00:00) Why I stopped using Claude

(01:02) What Anthropic says Opus 5.5 is

(01:54) Cost, speed, and benchmark overview

(03:20) Safety, alignment, and the cybersecurity limits

(05:02) How I AI bench

(05:39) Voice test: is it actually not annoying?

(07:54) Long-running agentic task results

(10:50) Frontend prototyping

(17:23) Writing voice and email

(19:41) SVG illustrations

(20:46) Video editing

(21:42) My verdict: what it’s good at, what it still isn’t

Tools referenced:

• Claude Opus 5.5: https://www.anthropic.com/claude-opus-5-5

• ElevenLabs MCP connector: https://elevenlabs.io/mcp

• Codex (OpenAI): https://openai.com/codex

Where to find Claire Vo:

ChatPRD: https://www.chatprd.ai/

Website: https://clairevo.com/

LinkedIn: https://www.linkedin.com/in/clairevo/

X: https://x.com/clairevo

Production and marketing by https://penname.co/. For inquiries about sponsoring the podcast, email jordan@penname.co.

5

Claude Opus 5.5, GPT-6 Sol, GPT-6 Luna, and a new price war

Simon Willison · original → · 8/10 · AI: Claude Opus 5.5 and GPT-6 models price war
Claude Opus 5.5, GPT-6 Sol, GPT-6 Luna, and a new price war 22nd September 2026 Yesterday was Grok 4.7 (pelicans) and MiMo v2.6 Flash/Pro (more pelicans). Today Anthropic released Claude Opus 5.5,…

Claude Opus 5.5, GPT-6 Sol, GPT-6 Luna, and a new price war 22nd September 2026 Yesterday was Grok 4.7 (pelicans) and MiMo v2.6 Flash/Pro (more pelicans). Today Anthropic released Claude Opus 5.5, and around an hour later OpenAI released GPT-6 Sol and GPT-6 Luna. It’s going to take a while to get a good read on all of these new models, but here are my impressions so far. GPT-6 Sol and Luna are half the price of their GPT-5.6 equivalents GPT-5.6 Luna was already my favorite model for building applications against, because it combined excellent performance with being really cheap. Somehow GPT-6 Luna is half the price of that again—and GPT-6 Sol had a similar reduction compared to GPT-5.6 Sol. Here’s what the pricing landscape looks like today: | Model | Input | Cached input | Output | |---|---|---|---| | GPT-6 Luna | $0.10/M | $0.01/M | $0.50/M | | GPT-5.6 Luna | $0.20/M | $0.02/M | $1.20/M | | Grok 4.7 | $2/M | $0.50/M | $6/M | | GPT-6 Sol | $2/M | $0.20/M | $10/M | | GPT-5.6 Terra | $2/M | $0.20/M | $12/M | | Claude Opus 5.5 | $4/M | $0.20/M | $20/M | | GPT-5.6 Sol | $4/M | $0.40/M | $20/M | | Claude Fable 5.1 | $10/M | $0.25/M | $50/M | | GPT-6 Astra | $10/M | $1/M | $50/M | Note that GPT-5.6 has a scheduled 25% price increase for November, so GPT-6 is half the price of the promotional pricing for those models. (With GPT-5.6 Terra priced the same as GPT-6 Sol, any remaining reasons to use Terra just evaporated.) It’s hard to overstate how competitive this pricing is. Grok 4.7 priced itself at $2/$6, less than half the price of GPT-5.6 Sol, but is now equally priced to GPT-6 Sol on input and closer on output. At $0.10/$0.50 GPT-6 Luna is one of the cheapest models OpenAI have ever released, beaten only by the far weaker GPT-4.1 Nano ($0.10/$0.40, April 2025) and GPT-5 Nano ($0.05/$0.40, August 2025). I rendered pelicans for GPT-6 Luna and for GPT-6 Sol, then I combined them all together in this comparison grid along with the GPT-5.6 pelicans. I like how you can instantly see that the 5.6 family chose bolder, brighter colors, while the 6 family is a lot more muted. I still think GPT-6 Astra on max produced the best pelican. Claude Opus 5.5 got a price cut too Opus 5.5 looks like it addresses the biggest complaints people had about Opus in terms of its communication style. Thariq Shihipar: Opus 5.5 is the result of your feedback. It communicates clearly, it’s cheaper per token than Opus 5.0 with the intelligence of Fable 5.1 it’s very token efficient and works across every effort level. It’s also meant to be better at Blender. I’m looking forward to putting it through its paces there. Opus 4.5, 4.6, 4.7, 4.8, and 5 all shared the same price: $5/million tokens for input and $25/million for output. 5.5 is a 20% reduction—$4/million and $20/million. The price for cache reads fell 60%. That’s significant for longer agentic conversations, where 90%+ of input tokens are processed at cached token prices. The new price for Opus 5.5 is the same as the price for GPT-5.6 Sol, but that was before OpenAI dropped their Sol prices by half. GPT-6 Astra and Claude Fable 5.1 are both priced at $10/million input and $50/million output. The price war currently affects the next tier of models below that. Anthropic say that Sonnet 5.5 and Haiku 5.5 are coming soon. It’s going to be interesting to see if Haiku can regain its price competitiveness at the lower end, given current Haiku 4.5 is $1/$5 while the latest GPT-6 Luna is one tenth of that price at $0.10/$0.50. Claude Opus 5.5 max over-thinks to the point of breaking In a first for my "Generate an SVG of a pelican riding a bicycle" test, Claude Opus 5.5 at "max" thinking level failed to return a response! It started by calling this “a classic test request”, and then thought really, really hard about what it was doing: This is a classic test request, so I want to plan out a well-composed pelican with its distinctive beak and pouch riding a bicycle with proper wheels, frame, and pedals, set against a simple sky and ground backdrop. [...] Verifying the shin length checks out at roughly 95.2, close enough. Now I’m working out the near leg path from hip to knee to ankle, then sketching the foot shape resting on the pedal — outlining the heel, toe tips, and sole contour with a path using lines and curves to sit naturally on the pedal surface around y=478-494. [...] I like the fish sticking prominently out of the basket with the pelican eyeing it as a fun detail worth keeping. I’m also confirming the eye placement near the bill base matches typical pelican anatomy, and considering giving it a slightly happier expression. [...] The far leg reads correctly as passing behind the frame, so I’m moving on to check the chainring teeth and confirm layer ordering—the far crank arm should be mostly hidden by the seat tube and chainring. I’m settling on the final SVG’s width and height attributes alongside the viewBox to ensure proper scaling, noting there’s no text so no font-family is needed. [...] I was so excited to see this pelican... but then it stopped. Opus 5.5 has a 128,000 maximum output token limit (as do the other Claude models), and it hit that while it was still reasoning about the SVG! I tried a second time and got the same result. This makes me suspect that “max” is effectively useless—if it over-thinks to breaking point on a stupid SVG prompt I don’t trust it not to do the same for more interesting work. (Those two failures each cost me $2.56 and took nearly 20 minutes.) Fable 5.1 on “max” didn’t over-think and did give me the best pelican I’ve seen from any Anthropic model. Here are the Opus 5.5 pelicans, excluding 5.5 max. I also built this comparison grid comparing them with pelicans by Opus 5, Fable 5.1, and Sonnet 5: Comparing different model vendors by how well they draw a pelican riding a bicycle may not make much sense now (if it ever did), but I’m still finding value in using them for comparisons of the same model families at different reasoning levels. I’m now using GPT-6 Sol and Claude Opus 5.5 as my default models in Codex and Claude Code. I’ve upgraded the Datasette Agent demo at agent.datasette.io to use GPT-6 Luna, and it seems to be fast and competent at both SQL queries and building HTML and JavaScript for Datasette Apps. More recent articles - Jev introduces a new shape of LLM - System One, aka Decision Models - 21st September 2026 - Generating running routes with GPT-6 Astra and ChatGPT Work - 12th September 2026

6

Call for better quality school meals

Wexford Local · original → · 7/10 · Local Wexford + education: school meals policy debate
By Dan Walsh Sinn Féin TD Fionntán Ó Súilleabháin a, former primary school teacher of many years, has said the Government must go beyond minor adjustments to the School Meals Programme and introduce…

By Dan Walsh

Sinn Féin TD Fionntán Ó Súilleabháin a, former primary school teacher of many years, has said the Government must go beyond minor adjustments to the School Meals Programme and introduce meaningful reforms that improve food quality, reduce waste and support local food producers.

[image →]
FIONNTÁN Ó SÚILLEABHÁIN TD

Deputy Ó Súilleabháin said; “Sinn Féin has long supported the provision of school meals and recognises the vital role the programme plays in tackling food poverty and supporting families through the cost-of-living crisis. However, the fact that around 100,000 meals a day are reportedly going uneaten shows that significant reform is needed.

“During a recent committee meeting attended by Darina Allen, I highlighted concerns that have been consistently raised by principals, teachers and parents. These include the quality of some meals being provided, excessive food waste, and the growing administrative burden being placed on schools.

“Principals have told me that large quantities of food are ending up in bins because children simply do not want to eat it. At the same time, schools are being asked to manage a scheme that places additional pressures on already stretched staff.

“We need to move towards a model that prioritises fresh, locally sourced food and supports local farmers, food producers and small businesses. Public money should be delivering nutritious meals for children while strengthening local economies.

“There are currently 11 schools across North Wexford and South Wicklow participating in the Hot School Meals Programme, including four schools in North Wexford and seven in South Wicklow according to 2025 figures on the department of Education Website.

“Children deserve healthy, high-quality meals that they will actually eat,” said Deputy Ó Súilleabháin, who added; “The Government must now address the issues of quality, waste and administration, and seriously examine community-led and locally sourced alternatives. Simply tinkering around the edges will not be enough.”

7

Georgia delegation visits County Wexford

Wexford Local · original → · 7/10 · Local Wexford: Georgia delegation visit to county
[image →]Wexford County Council meets delegation from the State of Georgia, USA. (left to right); Elizabeth Hore, Director of Services, Wexford County Council, Cllr Lisa McDonald, Cathaoirleach…
[image →]
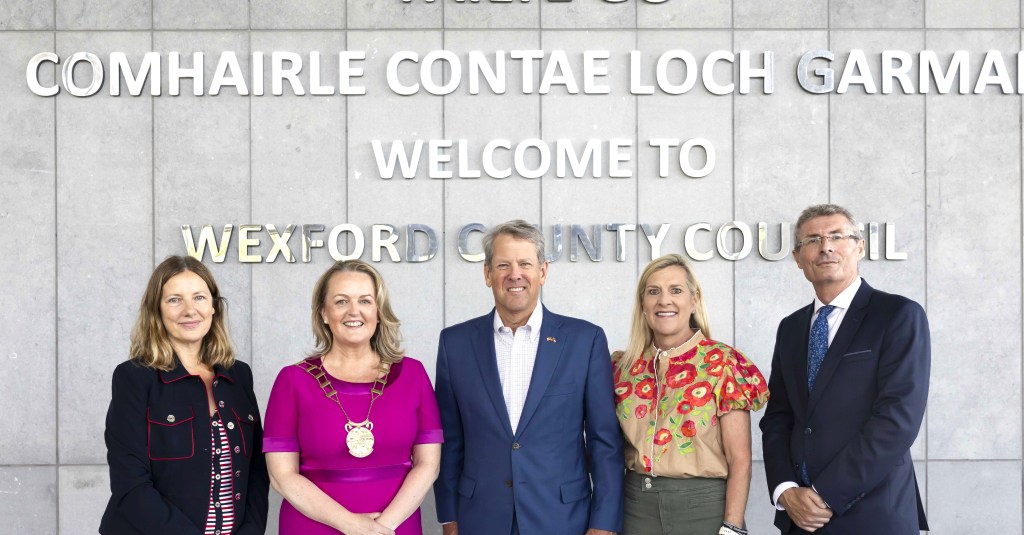
Wexford County Council meets delegation from the State of Georgia, USA. (left to right); Elizabeth Hore, Director of Services, Wexford County Council, Cllr Lisa McDonald, Cathaoirleach Wexford County Council, Governor Brian P. Kemp, First Lady Marty Kemp and Eddie Taaffe, Chief Executive Wexford County Council. (Pic; Mary Browne).

By Dan Walsh

Wexford County Council welcomed Governor Brian P. Kemp, First Lady Marty Kemp, and a high-level delegation from the State of Georgia including Mr. Pat Wilson, Commissioner of the Georgia Department of Economic Development, Mr. Trip Tollison, President & CEO Savannah Economic Development Authority, and Dr. Kyle Marrero, President Georgia Southern University as part of a successful two-day visit that reaffirmed the strong economic, educational and cultural ties between County Wexford and the State of Georgia.

The visit brought together representatives from government, higher education and industry to celebrate existing partnerships and explore new opportunities for collaboration in trade, investment, research and talent development.

Governor Kemp was welcomed by An Cathaoirleach Cllr. Lisa McDonald and Chief Executive Eddie Taaffe. The programme highlighted the success of TradeBridge, a joint initiative of Wexford County Council and Wexford Enterprise Centre, which connects companies in Ireland and Georgia through trade, investment and partnership opportunities.

Presentations were also delivered by Wexford-based companies Stafford Bonded, Kersia Healthcare and Waters Technologies Ireland Ltd., showcasing the innovation and global reach of businesses operating in the county.

The programme also featured contributions from senior leaders with strong Wexford connections and extensive experience in global industries including representatives from Microsoft Ireland.

Cathaoirleach of Wexford County Council, Lisa McDonald, said: “This visit has been a wonderful celebration of the friendship and connections that exist between County Wexford and the State of Georgia. It showcased the best of our county, our businesses, our educational partnerships, our heritage and, above all, our people. We are deeply appreciative of Governor Kemp and the delegation for taking the time to visit Wexford and we look forward to strengthening our relationship in the years ahead.” 

A key element of the programme was the delegation’s engagement with Georgia Southern University’s Wexford Campus Initiative. The visit provided an opportunity for leaders from both regions to celebrate the success of the partnership and meet students benefiting from international educational opportunities in Wexford.

The delegation also toured the Adoration Convent student accommodation facility, which supports the university’s growing presence in the county and is expected to be officially opened in early 2027. 

Chief Executive of Wexford County Council, Eddie Taaffe, said: “It was a great honour to welcome Governor Kemp and the Georgia delegation to County Wexford. The visit provided an excellent opportunity to showcase the strengths of our county and to reinforce the relationships that have been built through business, education and people-to-people connections. We look forward to continuing to develop these valuable partnerships into the future.”

During the visit, delegates experienced some of Wexford’s cultural and heritage attractions, including Johnstown Castle, the National Opera House and the Dunbrody Famine Ship Experience in New Ross. These visits highlighted the county’s unique history, tourism offering and enduring links with the United States.

8

GPT-6 Sol and Luna

Hacker News · original → · 7/10 · AI: GPT-6 Sol and Luna model releases
Comments
9

Advanced evals: How to find (and fix) hidden AI failures in your product

Lenny's Newsletter · original → · 7/10 · AI: advanced evals for AI product failures
👋 Hey there, I’m Lenny. Each week, I share deeply researched product, growth, and career advice. For more: Lenny’s Jobs | Lennybot | Become an AI-Native Builder and other favorite AI/PM…

👋 Hey there, I’m Lenny. Each week, I share deeply researched product, growth, and career advice. For more: Lenny’s Jobs | Lennybot | Become an AI-Native Builder and other favorite AI/PM courses

Subscribe now

P.S. Get a full free year of Cursor, Notion, Lovable, Replit, Wispr Flow, Linear, Factory, ElevenLabs, PostHog, Granola, Brain.fm, Waking Up, and more, by becoming an Insider subscriber (while supplies last). Learn more.


Evals have been coming up more and more in my conversations with podcast guests and PMs. And nearly half of the 25 awesome PM job openings I shared on socials last week ask for experience writing evals. This skill is only becoming more valuable. So I asked Hamel and Shreya to write an advanced sequel to their very popular “Building eval systems that improve your AI product” post from last year. Drawing from their work with over 50 AI companies, they’ve noticed that most teams jump straight to writing metrics—and end up measuring the wrong things. Below, they share the critical part of the process most teams skip, which steps you can (and cannot) automate, and a free plugin that lets a coding agent do most of the heavy lifting for you. Enjoy!

To go deeper, join their upcoming AI Evals for Engineers & PMs course and use the discount code LENNYSLIST at checkout to get 25% off.


By now, you’ve probably heard that evals are a defining skill for AI PMs. Mike Krieger, Anthropic’s former CPO and now head of Labs, has said that “if there’s one thing we can teach product people, it’s that writing evals is now probably the most important thing.” Garry Tan, the CEO of Y Combinator, shared that “evals are emerging as the real moat for AI startups.” A number of guests on Lenny’s Podcast have argued that “evals are the new PRDs,” and increasingly, leading companies have been talking about how investing in evals has paid off:

  • Shopify used evals to guide development of an AI workflow builder that was 2.2 times faster and 68% cheaper than the frontier-model system it replaced.

  • Cursor developed its Auto Balance routing performance with evals, resulting in much higher user satisfaction while reducing costs by 41%.

  • Ramp increased its precision of finding a matching transaction in receipt photos using on-device models from 35% to 83% after investing in evals.

  • Harvey rebuilt its AI contract reviewer with evals, nearly doubling the product’s internal quality score.

Rippling, Glean, Abridge, ElevenLabs, and Robinhood have also shared how they’ve been using evals to systematically make their AI products better.

AI products are easy to change but hard to predict. A prompt, model, or code change can improve one behavior while breaking another. Evals turn your judgment about what “good” looks like into repeatable tests your team can run before shipping. Production errors flagged by evals can become additional test cases that improve your AI, creating an advantage that compounds over time.

And now that AI can produce changes faster than people can review them, evals help teams ship quickly by automatically checking if a product still works as intended.

In our prior post, we laid out the full process for building evals: discover and analyze errors, create customized metrics, and set up a continuous improvement loop. Unfortunately, we’ve found that most teams skip the first stage of error discovery and jump straight to writing metrics.

It is easy to see why. Looking through lengthy user session records to find failures feels slow and hard to scale, whereas metrics are concrete and easy to automate. But if you write metrics too early, you end up making too many assumptions about what’s important—and potentially measuring the wrong thing, or the right thing poorly.

This is why error discovery is the eval equivalent of product discovery. Just as product discovery shows which problems are worth solving, error discovery reveals which AI failures are worth measuring. Without it, teams risk building dashboards around generic metrics that waste time and steer the product toward the wrong outcomes.

We believe error discovery is so important that if you only have time for one part of the eval process, you should prioritize it.

In this post, we’ll show you the three steps to running effective error discovery with a coding agent like Codex or Claude. We’ve used this process with more than 50 companies, and each time the tools uncovered major product flaws that were hurting the customer experience. This entire workflow takes only about 30 minutes to complete once you learn the basics.

Note: Error discovery has changed a lot since our last post. Our prior post called this process “error analysis.” We now call it “error discovery,” because the goal is to identify failures that are worth measuring. Keep reading to learn about the new approach.

Find the errors that matter to your product

When you’re building an AI product, you need evals to understand where it makes mistakes. But maintaining evals costs time and money; it doesn’t make sense to measure everything. Good error discovery identifies which failures are worth measuring and tracking over time. Even when you know you need the error discovery stage, it can be tempting to start by handing an agent a folder of traces—complete records of user sessions with your AI product—and asking it to find problems. Agents are often faster than humans at spotting obvious issues and can find patterns we might miss. But they are far less reliable when a failure depends on your definition of a good product experience. You can explain those standards to the agent, but you often only discover them in the first place by reviewing the data. This process, where reviewing examples changes your definition of good, is called criteria drift.

For example, below is an interaction from Nurture Boss, an AI leasing assistant we worked with that helps property managers handle conversations with prospective tenants:

Prospect: “This is out of my budget. Thank you for your business.”

Leasing assistant: “You’re welcome! If your situation changes or if you have any other questions in the future, feel free to reach out. Have a great day!”

The full conversation from this interaction is provided below in the discussion on traces.

To most agents, this looks like a success; they wouldn’t identify an error in this trace. But the product goal is to facilitate sales, which includes finding the right property matches for prospects’ different needs. In this situation, the agent should have explored cheaper units or other properties owned by the same company and offered the prospect alternatives.

If we’d prompted the agent to look for this “objection handling” failure up front when we gave it traces to check, the agent would have caught the error automatically. But we’d only know to add “objection handling” to our criteria after seeing this trace ourselves. This is a classic case of criteria drift—and why it’s critical to take a step back to review failures and define success before dispatching an agent to find errors in a stack of traces.

In a broader study, we ran automated eval tools and coding agents against 100 production traces from this same apartment-leasing assistant. We found the following:

  1. Agents missed issues requiring product judgment and context outside the trace such as Markdown formatting in text messages and missed human handoffs (in addition to objection handling).

  2. Agents are good at catching failures that are obvious inside a trace, like answers that are contradicted by tool output.

  3. Agents also find issues that humans miss, but they introduce noise by flagging good responses as failures.

Clearly, automated approaches are still useful for finding some types of errors, and they work especially well in conjunction with human judgment. So how do you benefit from an agent’s automation while keeping a human in the loop? The answer is a process that draws on active learning, a method for choosing the most informative examples to review given limited time. Start with a diverse sample of traces so you cover the range of your data. When you find a failure, look at a few more instances of it before you decide you understand it. After you’ve reviewed enough examples, let the agent annotate traces that you can then accept or reject.

All of this bookkeeping and sampling would be difficult to do manually. But coding agents are great at it. The rest of this post walks you through how to work with an agent to do meaningful error discovery step by step, with the aid of an eval skills plugin we prepared for you.

Step 1: Start with your traces

Error discovery requires traces. Each trace consists of the user’s input and system prompt, whatever your system did in between (retrieval, tool calls, intermediate model calls), and the product’s final output. Each trace should contain enough information for a reviewer to reconstruct what happened and decide whether it was good. You can choose to log this data to a database, eval vendor, or even a local folder. For this post, we will assume a local folder for simplicity.

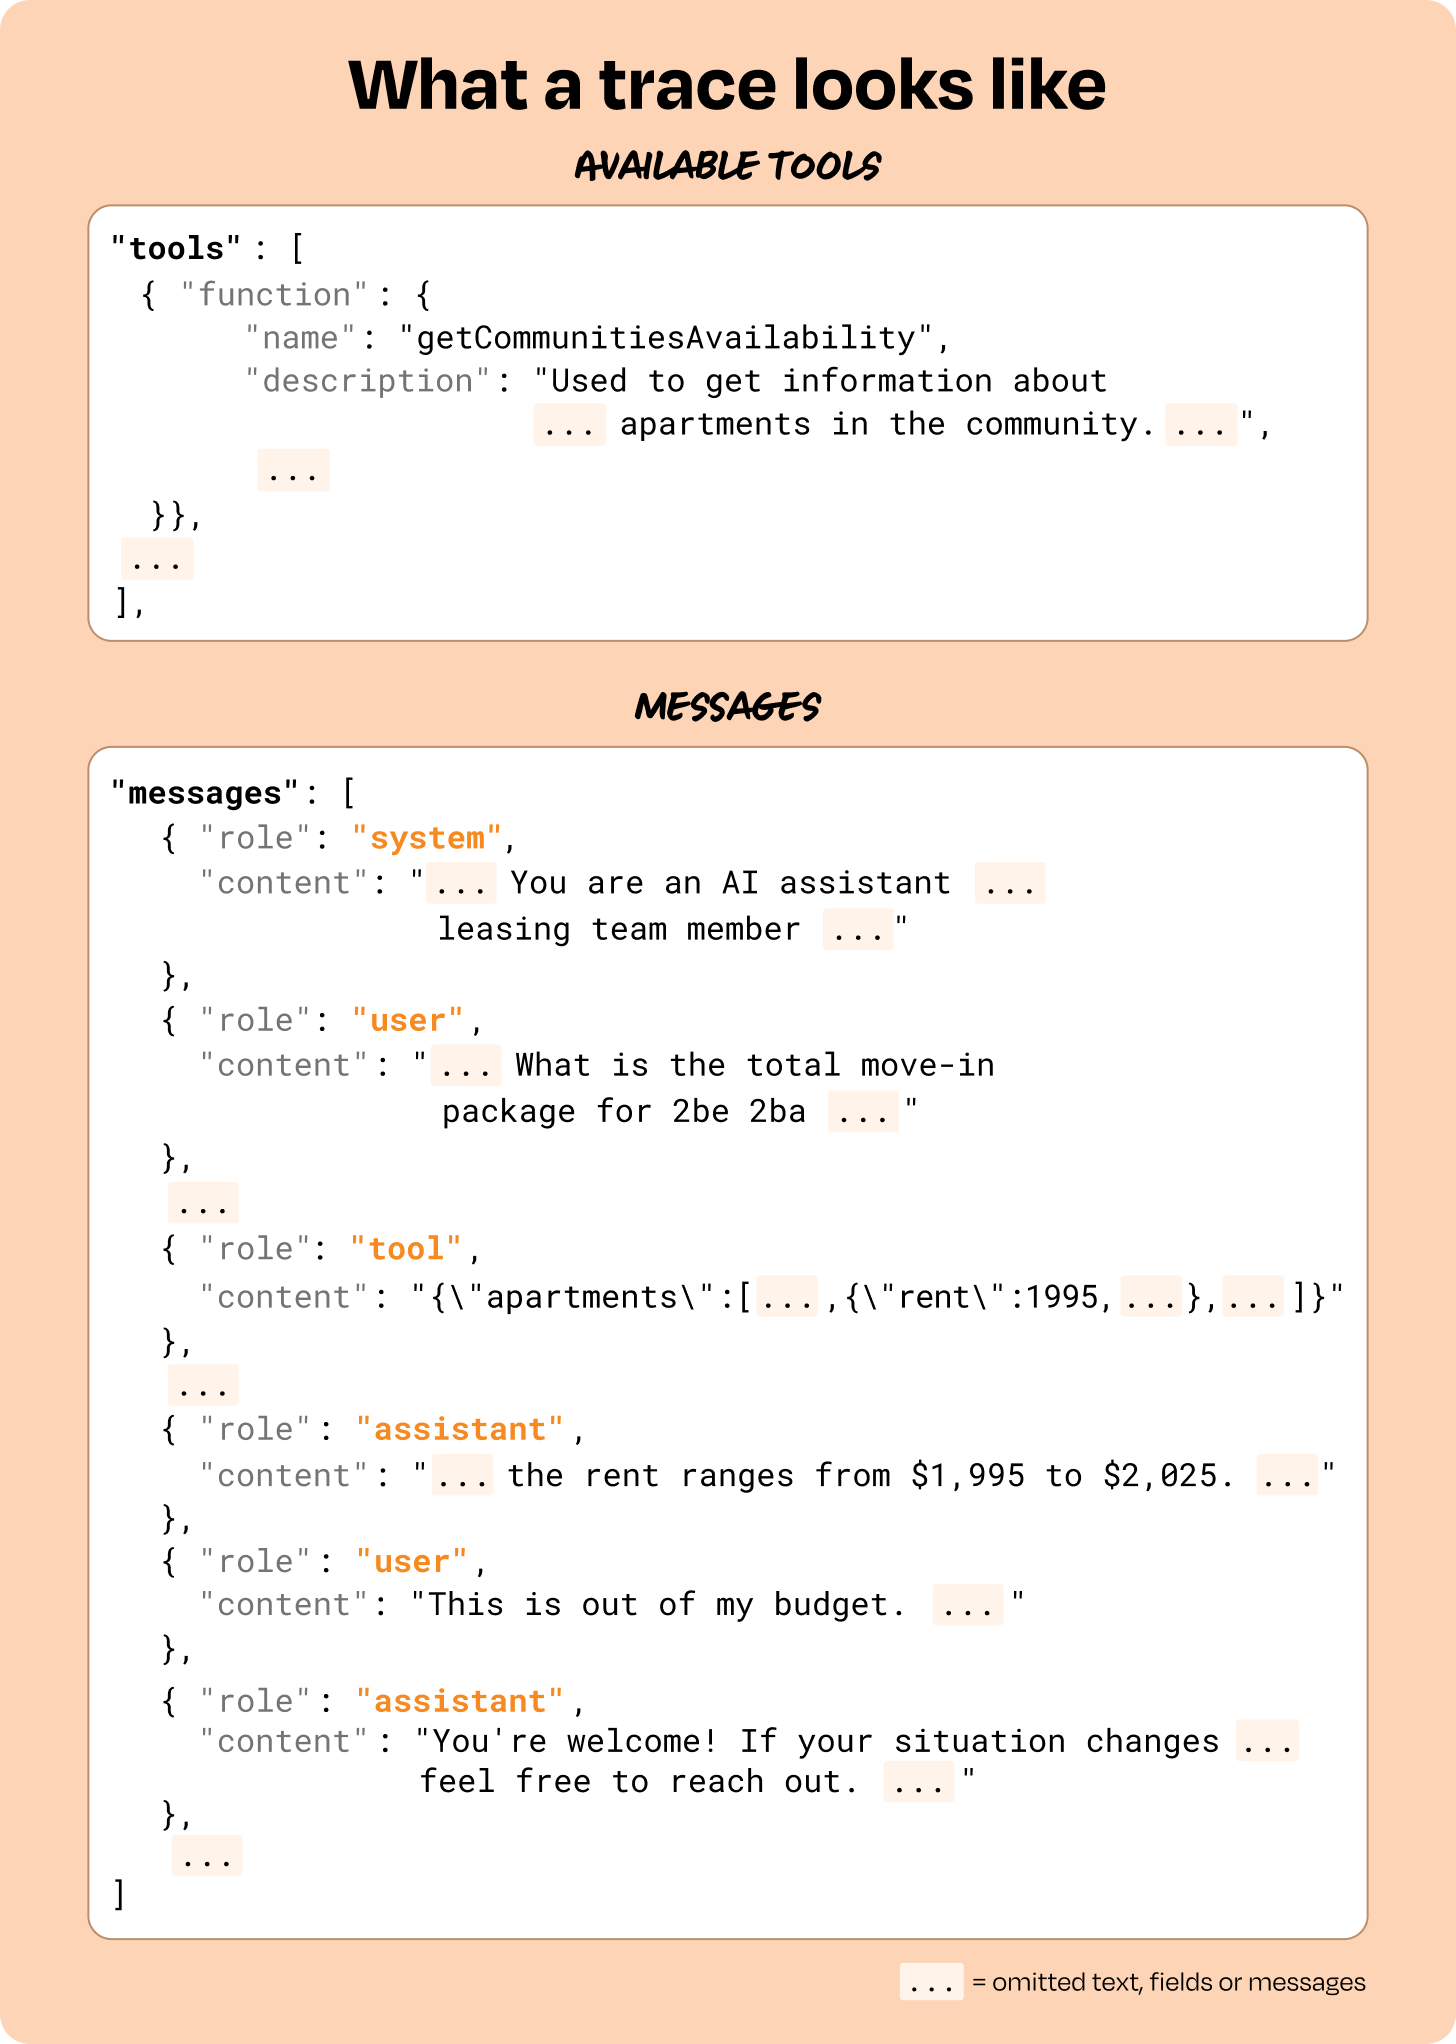
Here is what a trace might look like for the leasing assistant. Note that this is what it looks like in its raw form, and you usually want to render it to be human-readable (we will get to that later):

If you don’t have traces, you can ask your coding agent to instrument your application so it logs this data. Here’s what a prompt for that might look like:

Instrument this app so every user session with the AI is logged as one complete trace.

A trace is one user session. Include the user input, the system prompt, every tool call and its result, any retrieved context, every intermediate model call, and the final user-facing output.

If this app already sends traces to a vendor (LangSmith, Arize, Phoenix, Langfuse, or similar), keep using that. Also write a local copy: one JSON object per session, appended to traces/traces.jsonl. If there is no vendor, the JSONL file is enough.

Once your product is instrumented, you’ll need to wait for user activity to collect traces. If you haven’t launched yet, you can try to generate synthetic traces by simulating user queries with an LLM. While synthetic data cannot replace real data, sometimes it’s better than nothing.

Pro tip: How to simulate user queries

An effective way to simulate user queries is to define a small number of dimensions that you anticipate your product might fail on. For example, dimensions for the leasing assistant might be the task (scheduling a tour, asking about pricing, asking about the pet policy), the type of person asking, and whether the request was clear, ambiguous, or out of scope. Then have the model use these dimensions and turn each combination into a natural-language user query. Using dimensions like this helps steer the AI away from producing homogeneous outputs.

Once you have defined the dimensions, your coding agent can combine their values into scenarios. Each scenario contains one value from each dimension. The agent can then make a separate model call for each scenario. Here is an example prompt that will generate synthetic data with this approach:

Create a script that generates synthetic user queries for an AI leasing assistant. Use the dimensions and values below as fixed inputs. Do not add or change them.

  • Task: scheduling a tour, asking about pricing, asking about the pet policy

  • Renter: first-time renter, relocating family, student

  • Request type: clear, ambiguous, out of scope

Create a structured list of test scenarios by combining one value from each dimension. Loop through the scenarios and make a separate model call for each one. Pass only one scenario into each call. Enforce a structured output schema with a single user_query field, then save the query alongside its scenario in synthetic_queries.jsonl.

The prompt above recommends separate model calls for each scenario because we’ve found that asking an agent to one-shot it tends to produce less diversity. Here is an example of what one synthetic user query might look like:

{ “user_query”: “We have two dogs and may be moving next month. Would that work?” }

After generating synthetic data, review the examples and remove any that are unrealistic. If you notice scenarios that your dimensions don’t cover, update the dimensions and generate new examples covering those gaps.

Producing high-quality synthetic data (especially for complex, multi-turn conversations) is beyond the scope of this post. We recommend getting real users instead of relying on synthetic data where possible. If you must use synthetic data, we have a skill that can help you with that in the appendix.

Step 2: Review and annotate your data

Now we are ready to find errors in your product! We built an evals plugin to guide you through this process, based on what we learned teaching more than 4,500 PMs and AI engineers and consulting with over 50 companies. Install it with npx skills:

npx skills add https://github.com/ai-evals-course/evals-skills

Then point your coding agent at the /evals-start skill or tell it where your data is:

“Use the evals-start skill. My traces are in traces/traces.jsonl and I want to find issues occurring in my AI product.”

evals-start is the entry point for the evals skills plugin. It looks at your situation and sends you to the right workflow. In our case, we have traces we haven’t analyzed yet, so it will route us to error-discovery.

Customizing the app interface

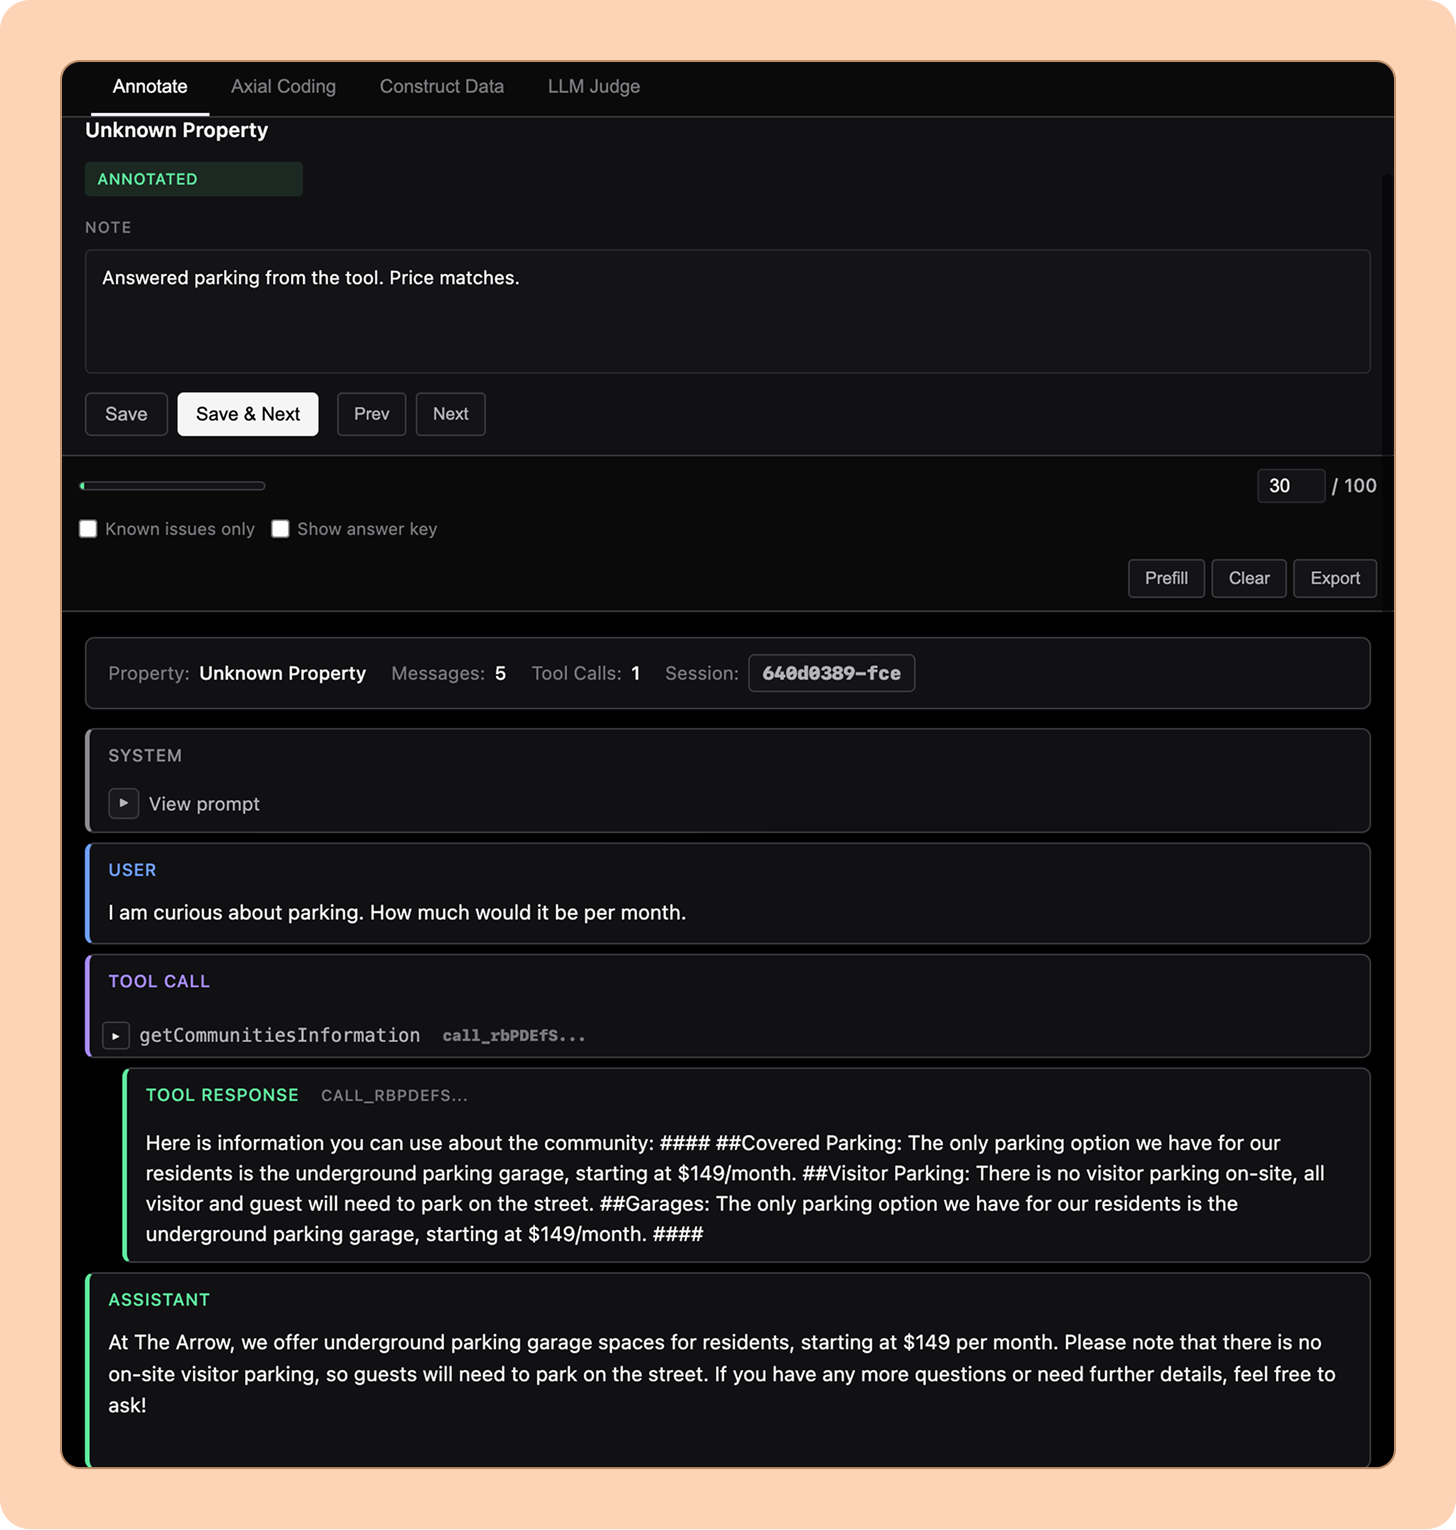
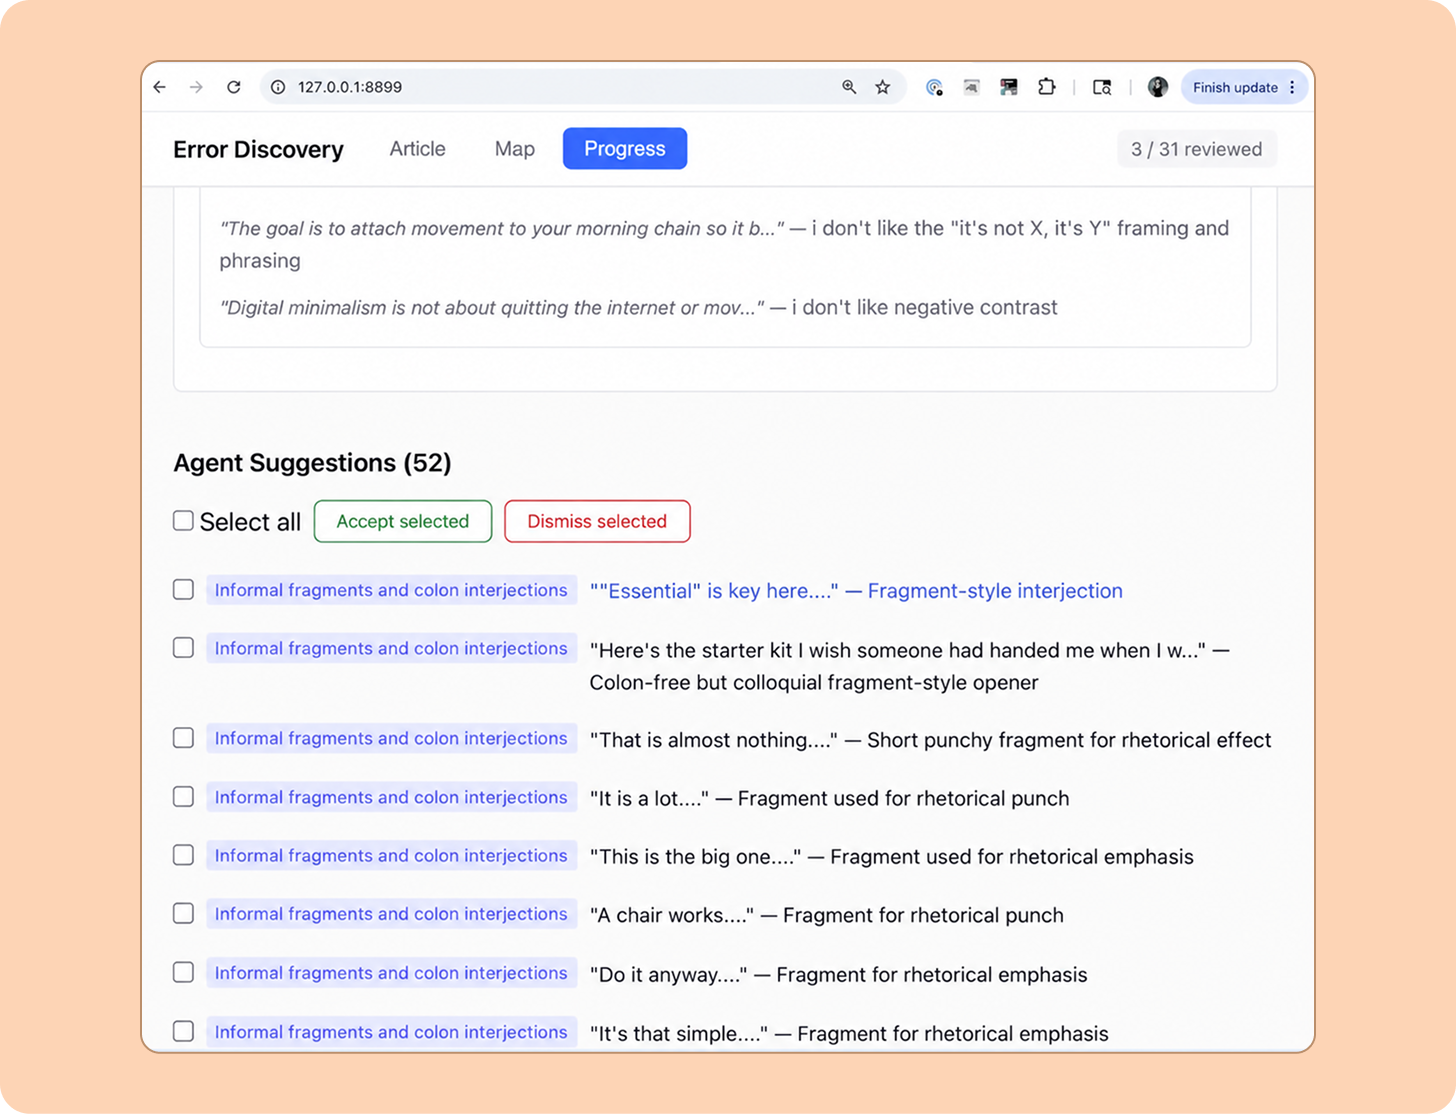
The first thing error-discovery does is read a sample of your records to learn their schema. Then it creates a small review app customized for your data and serves it to you locally. Here’s an example of the app interface that the plugin created for the leasing assistant traces:

This interface renders the conversation as a message thread, with tool calls and their outputs displayed alongside. You input your annotations into a free-form text box.

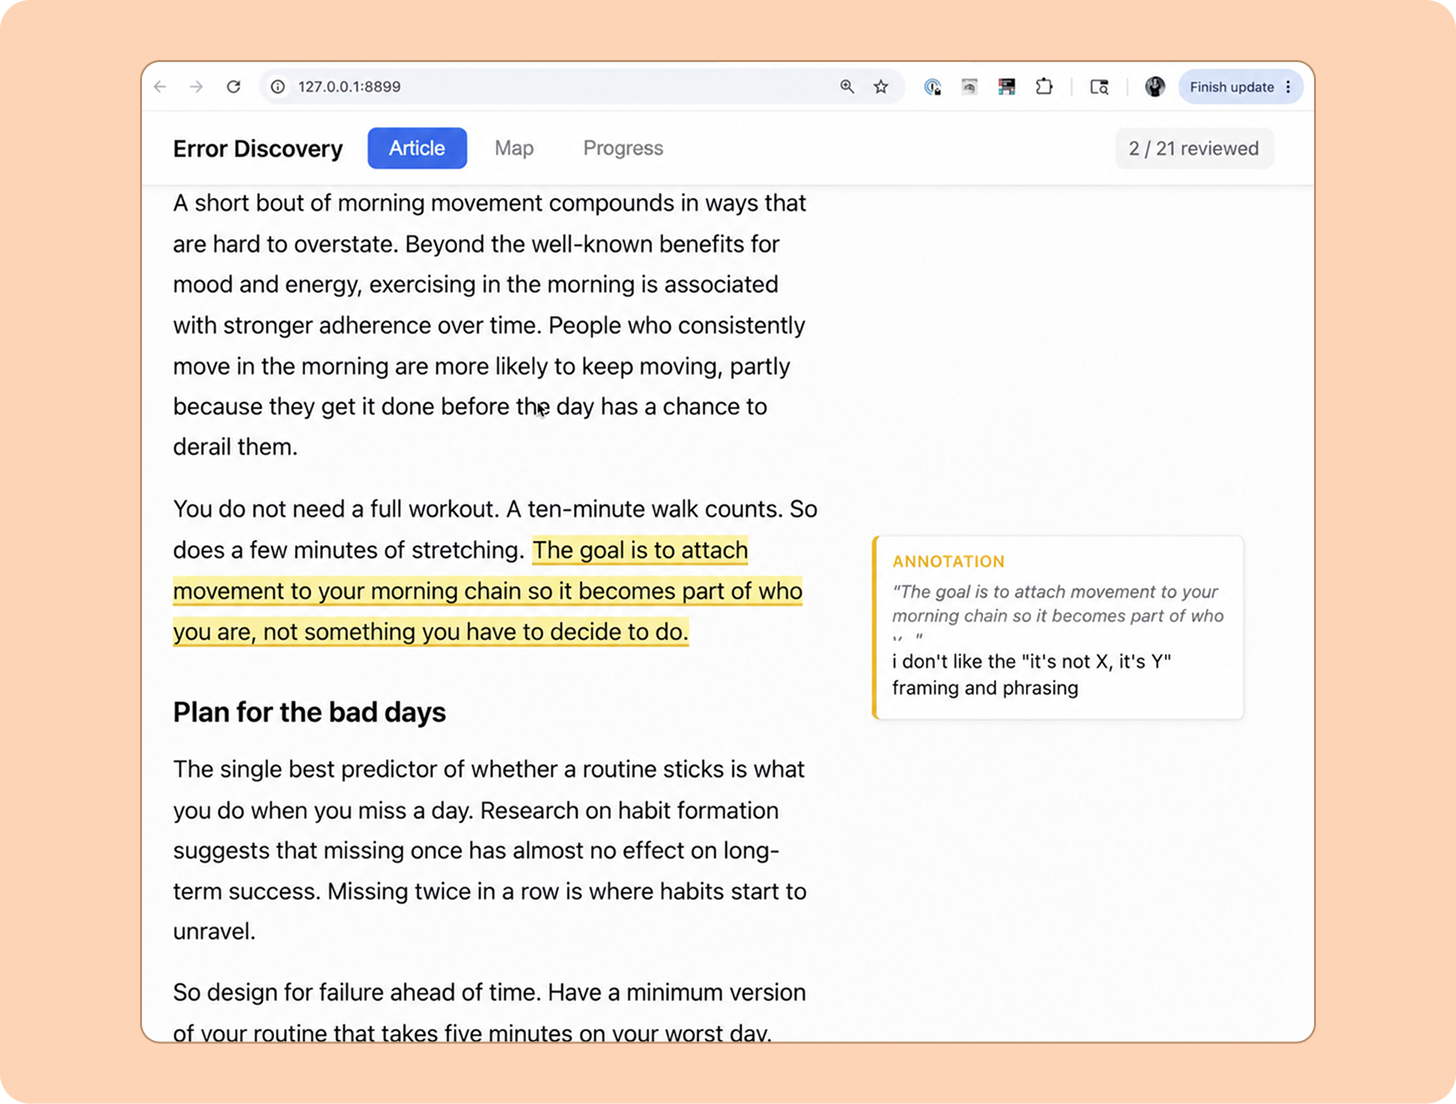
Interface customization is an important part of the plugin’s value. Different types of interfaces are best suited to reviewing different types of data. For example, here is what the rendered annotation interface might look like for a writing assistant:

In this app, the writing displays as a text block, with flags displayed alongside, which makes it well-suited to reviewing writing.

There are several design principles embedded in the skill that guide the way an interface will render. The two most important ones are:

  1. Show user-facing output the way the user sees it. For example, an email should look like an email, a PDF should render as a PDF, etc.

  2. Expose important metadata that may be helpful for navigation or filtering. In the leasing example, the channel the user comes through is likely important and worth filtering on: SMS, voice, web chat, etc.

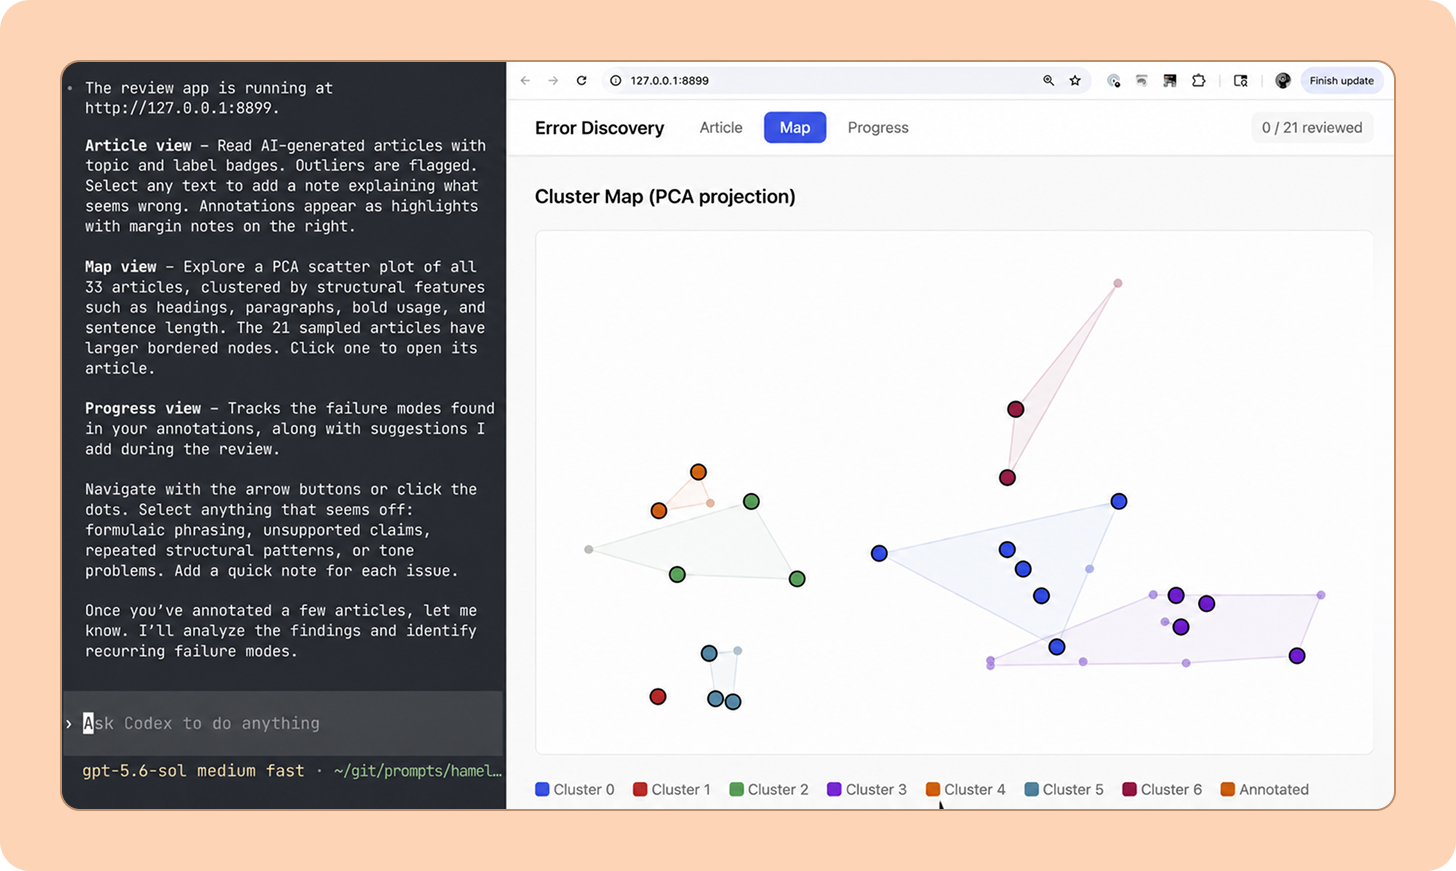
The skill also instructs your agent to cluster your traces so it can build a diverse initial sample. It mixes cluster representatives with random picks. This approach isn’t perfect, but we’ve found it to be a better starting point than naive approaches to looking at data. Here’s an example of how your coding agent might surface clusters for your review with the writing assistant:

In the above example, the annotation app for the writing assistant lets you hover over clusters to review representative documents. If you need to make changes to the clusters, the interface, or anything else, you can just chat with the AI.

The biggest advantage of using a coding agent is the ability to change the interface on the fly. If you notice a missing field, want to filter to a slice of traces, or render data differently, all you have to do is ask. For example, if you generated synthetic traces as described in the last section, you can ask your coding agent to create filters based on dimensions you defined like persona or task type. This lets you check whether a failure is concentrated in one kind of scenario.

Annotating traces in the app

Once the app is running, the skill asks you to review 10 traces before it suggests errors to review. This is a deliberate safeguard against automation bias. Your task is to leave a free-text note on whatever bothers you. Annotations could look like: “The assistant gave up instead of offering alternatives.” “Failed to render a scheduling widget and provided a list of times instead.” “The tone is too formal for this persona.”

Some rules of thumb for making annotations:

  1. Describe the problem so that a colleague (or agent) could understand what you meant. “Bad response” is a bad annotation. “The assistant said the unit was available when the tool output showed it was leased” is actionable.

  2. Don’t try to do root cause analysis. You’re looking for what went wrong from the user’s perspective, not why your system failed internally. For example, don’t try to diagnose retrieval issues.

  3. Stop at the first upstream error. If a trace has multiple problems, annotate the first one you notice. This heuristic helps you save time and focus on the most impactful issues, since upstream failures in agent trajectories tend to be more important than downstream ones. You can relax this constraint later when you are more efficient at this exercise.

  4. You only need to annotate failures when starting out. Annotating what makes a trace good might enhance your agent’s understanding but can be skipped if you are short on time.

After annotating at least 10 traces, the AI will learn from your initial notes and try to find additional issues in your data that you can accept or reject. It’s important not to blindly accept the agent’s early proposals. Review them carefully and use disagreements to correct the agent’s working understanding. You may need several human-agent iterations before the suggestions become useful. We encourage you to keep annotating beyond the first 10 traces until your own learning has plateaued. As a rule of thumb, aim for 100 traces to make sure you aren’t quitting too early. More traces will also give the AI more signal and improve its suggestions.

Here is what the interface might look like as you’re reviewing suggestions for the writing assistant (your specific interface will be different, since the AI customizes it for your use case):

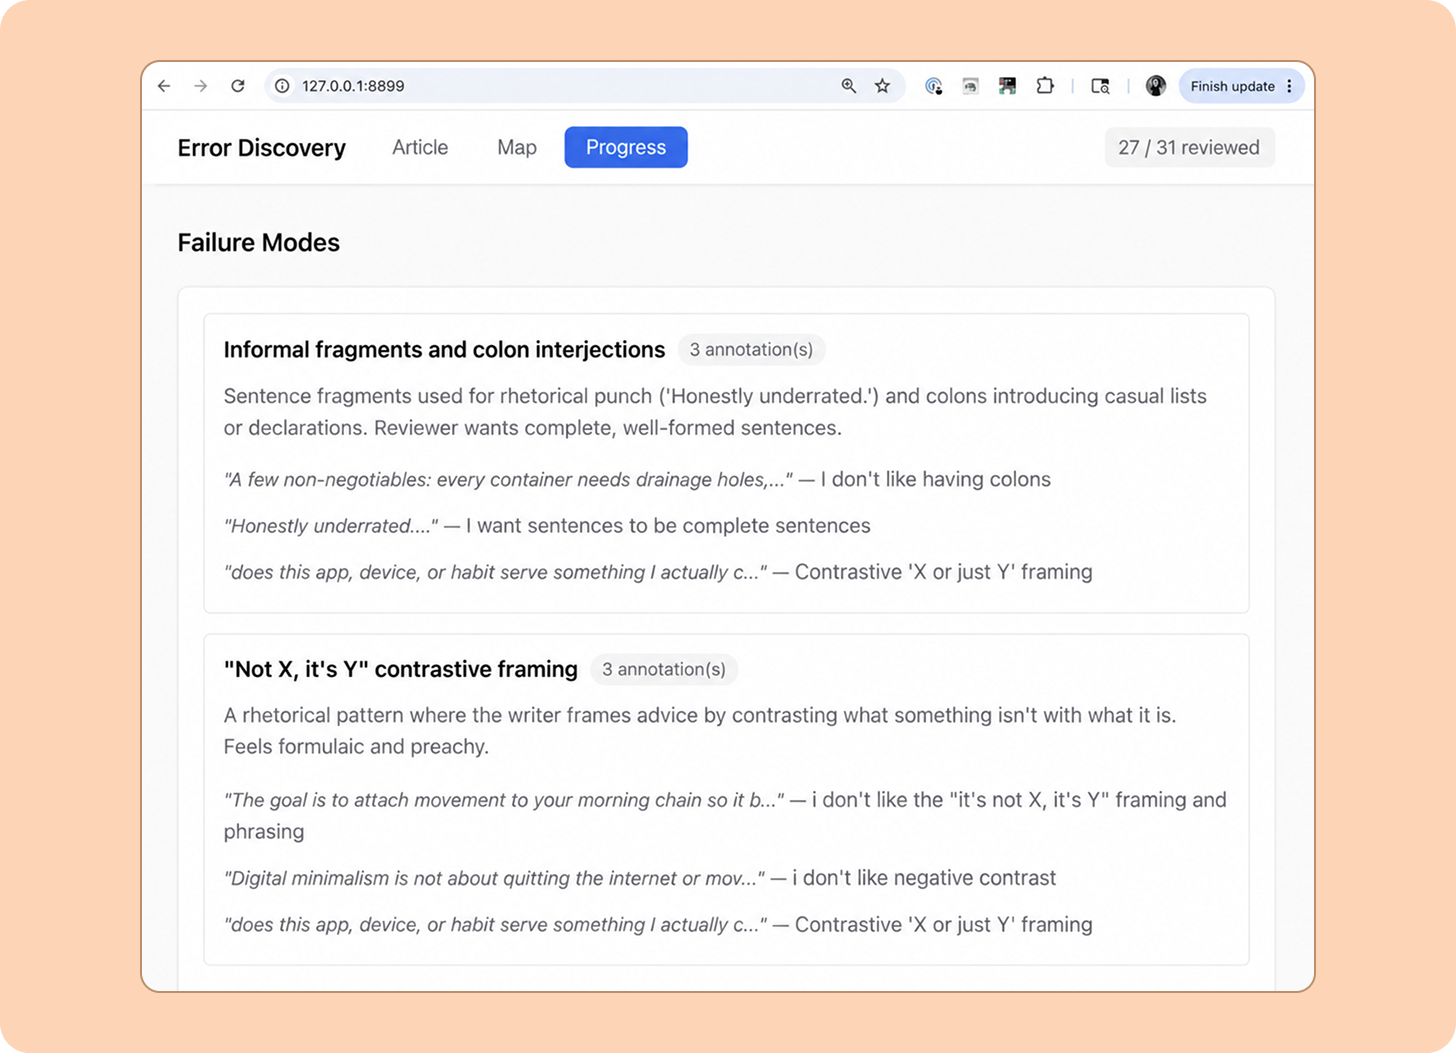
Here is another view that groups the suggestions by failure mode:

If the AI’s suggestions aren’t right, you can tell your coding agent to fix it—just as you can if you want to change the interface. Your annotations do not have to be perfect. The goal is to find actionable issues in your logs rather than perform an exhaustive search. Now that you have set the foundation with hybrid human and AI annotation of your traces, you’re ready to find failure patterns you can act on.

Step 3: Turn failure modes into product priorities

Once you’ve collected at least 100 diverse annotated traces, your next task is to turn them into a prioritized list of product issues. The AI will attempt to cluster your annotations into failure modes and count them so you can spot patterns. Here is what that looks like for our apartment leasing assistant:

Read more

10

SF October 14th: A Birds of a Feather Session on Agentic Engineering

Simon Willison · original → · 7/10 · AI: agentic engineering show-and-tell event SF
23rd September 2026 - Link Blog SF October 14th: A Birds of a Feather Session on Agentic Engineering. I'm hosting an evening event with Jesse Vincent in San Francisco on Wednesday 14th October for…

23rd September 2026 - Link Blog SF October 14th: A Birds of a Feather Session on Agentic Engineering. I'm hosting an evening event with Jesse Vincent in San Francisco on Wednesday 14th October for people who are building weird and interesting things with and on top of coding agents. Think of it as an agentic show-and-tell: Compare notes with other builders and experimenters on things you’re trying, what you're learning, and what you haven’t figured out yet. We’re especially interested in work you haven’t discussed publicly, odd experiments, or unfinished projects that don’t have an obvious market. Expect one flowing conversation with an informal show-and-tell. Sharing something you’re working on is encouraged but no presentation is required. This isn't about product pitches, it's about much earlier explorations than that. This agentic AI stuff is weird! Let's celebrate and lean into that weirdness. Recent articles - Claude Opus 5.5, GPT-6 Sol, GPT-6 Luna, and a new price war - 22nd September 2026 - Jev introduces a new shape of LLM - System One, aka Decision Models - 21st September 2026 - Generating running routes with GPT-6 Astra and ChatGPT Work - 12th September 2026

11

llm 0.36

Simon Willison · original → · 7/10 · AI/Work: llm tool updates for new OpenAI models
22nd September 2026 - New OpenAI models: gpt-6-sol for GPT-6 Sol andgpt-6-luna for GPT-6 Luna. #1702- Model plugins can now declare supports_conversation = False for models that only accept…

22nd September 2026 - New OpenAI models: gpt-6-sol for GPT-6 Sol andgpt-6-luna for GPT-6 Luna. #1702- Model plugins can now declare supports_conversation = False for models that only accept single-turn prompts. LLM raisesllm.ConversationNotSupported when these models receive assistant or tool history, andllm chat rejects them before starting a session. See Models that do not support conversations. The first plugin to use this is llm-typesafe. #1692- Reasoning traces in the Markdown output of llm logs are now wrapped in<details><summary> tags. #1701 Recent articles - Claude Opus 5.5, GPT-6 Sol, GPT-6 Luna, and a new price war - 22nd September 2026 - Jev introduces a new shape of LLM - System One, aka Decision Models - 21st September 2026 - Generating running routes with GPT-6 Astra and ChatGPT Work - 12th September 2026

Items scoring 7/10 or above from 11 sources, scored by claude-haiku-4-5-20251001 on relevance to my interests. At most 3 per source.

Scoring categories & sources
  1. Local Wexford or South East Ireland news
  2. Irish or EU-wide affairs affecting citizens broadly: elections, new laws or policy being debated, cost of living, education — especially impacts on mid-life adults or teenagers. Never courts/crime stories.
  3. Irish news on a topic relevant to my interests
  4. Work and tech topics: networking, AI, Kubernetes, platforms, SaaS
  5. AI news including critical or anti-AI perspectives
  6. Gaming: PC gaming, indie gaming, retro gaming
  7. General interests: gardening, woodwork, cycling, fitness, travel
  8. Comics

Sources: Breaking News Ireland, Wexford Local, Hacker News, r/gaming, r/pcgaming, r/antiAI, r/indiegaming, Lenny's Newsletter, One Useful Thing, Newcomer, Simon Willison