daily

2026-09-22
1

48 new social homes allocated in New Ross

Wexford Local · original → · 9/10 · Local Wexford: housing policy affecting citizens
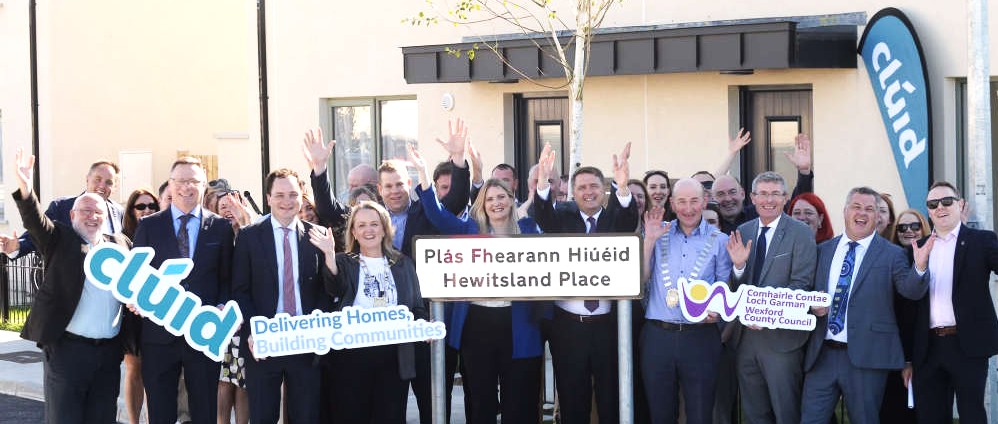
[image →]Celebration time at Hewitsland, New Ross, where Minister James Browne opened 48 new social homes. By Dan Walsh Minister for Housing, Local Government and Heritage, James Browne TD has…
[image →]
Celebration time at Hewitsland, New Ross, where Minister James Browne opened 48 new social homes.

By Dan Walsh

Minister for Housing, Local Government and Heritage, James Browne TD has officially opened 48 new social homes in Plás Fhearann Hiúéid, Hewitsland, New Ross, delivered by Clúid, Ireland’s leading Approved Housing Body (AHB). 

Minister Browne said: “It is a pleasure to be in New Ross today to officially open these 48 new social homes, including 10 age-friendly bungalows. These homes will make a real and lasting difference to the lives of the individuals and families who will now call them home.

“Supported by €4.3 million in funding from my Department, this development is an excellent example of the strong partnership between local authorities and Approved Housing Bodies in housing delivery. 

“Wexford County Council has established itself as a national leader in social housing delivery, consistently exceeding its targets and demonstrating what can be achieved through ambition, commitment and effective partnership,” concluded Minister Browne.

Cllr Lisa McDonald remarked; “As Cathaoirleach for Wexford County Council, I am delighted to launch these much-needed homes in Hewittsland, New Ross. I wish to thank the Minister and his officials in the Department for the support on this scheme and to compliment Clúid on what is a fabulous project.

“I want to especially wish the families here today every success and happiness with their new homes. Wexford County Council has delivered and will continue to deliver an ambitious housing construction programme for the county.”

Averil Power, Chief Executive Officer, Clúid, commented: “Plás Fhearann Hiúéid is a strong example of the high-quality, well-designed homes Clúid is delivering across the country. Through our growing construction programme, we are providing more people with secure, affordable homes and the foundation for a better quality of life.

“Spending time with residents here today is a powerful reminder of what that means in practice. A secure home brings stability, dignity and opportunity.

“We are proud to support people to put down roots here in New Ross, and to play our part in building a strong, inclusive and thriving community. We wish all of our new residents every happiness in their new homes,” added Ms. Power.

Eddie Taafe, Chief Executive, Wexford County Council, said; “We are delighted to work with our partners Clúid in the delivery of 48 new social homes in New Ross. The delivery of all forms of housing, social, affordable and private, along with associated community and servicing infrastructure remains the number one priority for Wexford County council. We wish the new tenants well in their new homes and look forward to further housing delivery under the Government’s Delivering Homes, Building Communities 2025-2030 housing plan.”

The 48 homes will provide secure, long-term, affordable homes for individuals and families on the Wexford County Council housing list. The new homes are a mix of 2- and 3-bedroom houses, and one-bedroom age-friendly bungalows for residents aged 55 and over.

All the homes have now been allocated, and the new residents are beginning to settle in and build their new community.

The new homes in Hewitsland bring to 408 the number of Clúid homes in Wexford. Clúid currently has 136 homes in the pipeline in Gorey and Clonard that are due to be delivered in the next six months.

The homes have been developed as part of Clúid’s own construction programme on a site provided by the Housing Agency. The main contractor was local firm Mythen Construction Limited, from Foulksmills.

The homes were delivered in partnership with Wexford County Council, and with the support of the Department of Housing, Local Government and Heritage, The Housing Agency and the Housing Finance Agency. 

2

Transformers Explained Visually

Hacker News · original → · 8/10 · AI: foundational transformer architecture explained
What is a Transformer? Transformer is a neural network architecture that has fundamentally changed the approach to Artificial Intelligence. Transformer was first introduced in the seminal paper…

What is a Transformer? Transformer is a neural network architecture that has fundamentally changed the approach to Artificial Intelligence. Transformer was first introduced in the seminal paper "Attention is All You Need" in 2017 and has since become the go-to architecture for deep learning models, powering text-generative models like OpenAI's GPT, Meta's Llama, and Google's Gemini. Beyond text, Transformer is also applied in audio generation, image recognition, protein structure prediction, and even game playing, demonstrating its versatility across numerous domains. Fundamentally, text-generative Transformer models operate on the principle of next-token prediction: given a text prompt from the user, what is the most probable next token (a word or part of a word) that will follow this input? The core innovation and power of Transformers lie in their use of self-attention mechanism, which allows them to process entire sequences and capture long-range dependencies more effectively than previous architectures. GPT-2 family of models are prominent examples of text-generative Transformers. Transformer Explainer is powered by the GPT-2 (small) model which has 124 million parameters. While it is not the latest or most powerful Transformer model, it shares many of the same architectural components and principles found in the current state-of-the-art models making it an ideal starting point for understanding the basics. Transformer Architecture Every text-generative Transformer consists of these three key components: - Embedding: Text input is divided into smaller units called tokens, which can be words or subwords. These tokens are converted into numerical vectors called embeddings, which capture the semantic meaning of words. - Transformer Block is the fundamental building block of the model that processes and transforms the input data. Each block includes: - Attention Mechanism, the core component of the Transformer block. It allows tokens to communicate with other tokens, capturing contextual information and relationships between words. - MLP (Multilayer Perceptron) Layer, a feed-forward network that operates on each token independently. While the goal of the attention layer is to route information between tokens, the goal of the MLP is to refine each token's representation. - Output Probabilities: The final linear and softmax layers transform the processed embeddings into probabilities, enabling the model to make predictions about the next token in a sequence. Embedding Let's say you want to generate text using a Transformer model. You add the prompt like this one: “Data visualization empowers users to” . This input needs to be converted into a format that the model can understand and process. That is where embedding comes in: it transforms the text into a numerical representation that the model can work with. To convert a prompt into embedding, we need to 1) tokenize the input, 2) obtain token embeddings, 3) add positional information, and finally 4) add up token and position encodings to get the final embedding. Let’s see how each of these steps is done. Step 1: Tokenization Tokenization is the process of breaking down the input text into smaller, more manageable pieces called tokens. These tokens can be a word or a subword. The words "Data" and "visualization" correspond to unique tokens, while the word "empowers" is split into two tokens. The full vocabulary of tokens is decided before training the model: GPT-2's vocabulary has 50,257 unique tokens. Now that we split our input text into tokens with distinct IDs, we can obtain their vector representation from embeddings. Step 2. Token Embedding GPT-2 (small) represents each token in the vocabulary as a 768-dimensional vector; the dimension of the vector depends on the model. These embedding vectors are stored in a matrix of shape (50,257, 768) , containing approximately 39 million parameters! This extensive matrix allows the model to assign semantic meaning to each token, in the sense that tokens with similar usage or meaning in language are placed close together in this high-dimensional space, while dissimilar tokens are farther apart. Step 3. Positional Encoding The Embedding layer also encodes information about each token's position in the input prompt. Different models use various methods for positional encoding. GPT-2 trains its own positional encoding matrix from scratch, integrating it directly into the training process. Step 4. Final Embedding Finally, we sum the token and positional encodings to get the final embedding representation. This combined representation captures both the semantic meaning of the tokens and their position in the input sequence. Transformer Block The core of the Transformer's processing lies in the Transformer block, which comprises multi-head self-attention and a Multi-Layer Perceptron layer. Most models consist of multiple such blocks that are stacked sequentially one after the other. The token representations evolve through layers, from the first block to the last one, allowing the model to build up an intricate understanding of each token. This layered approach leads to higher-order representations of the input. The GPT-2 (small) model we are examining consists of 12 such blocks. Multi-Head Self-Attention The self-attention mechanism enables the model to capture relationships among tokens in a sequence, so that each token’s representation is influenced by the others. Multiple attention heads allow the model to consider these relationships from different perspectives; for example, one head may capture short-range syntactic links while another tracks broader semantic context. In the following section, we will walk through how multi-head self-attention is computed step by step. Step 1: Query, Key, and Value Matrices Each token's embedding vector is transformed into three vectors: Query (Q), Key (K), and Value (V). These vectors are derived by multiplying the input embedding matrix with learned weight matrices for Q, K, and V. Here's a web search analogy to help us build some intuition behind these matrices: - Query (Q) is the search text you type in the search engine bar. This is the token you want to "find more information about". - Key (K) is the title of each web page in the search result window. It represents the possible tokens the query can attend to. - Value (V) is the actual content of web pages shown. Once we matched the appropriate search term (Query) with the relevant results (Key), we want to get the content (Value) of the most relevant pages. By using these QKV values, the model can calculate attention scores, which determine how much focus each token should receive when generating predictions. Step 2: Multi-Head Splitting Query, key, and Value vectors are split into multiple heads—in GPT-2 (small)'s case, into 12 heads. Each head processes a segment of the embeddings independently, capturing different syntactic and semantic relationships. This design facilitates parallel learning of diverse linguistic features, enhancing the model's representational power. Step 3: Masked Self-Attention In each head, we perform masked self-attention calculations. This mechanism allows the model to generate sequences by focusing on relevant parts of the input while preventing access to future tokens. - Dot Product: The dot product of Query and Key matrices determines the attention score, producing a square matrix that reflects the relationship between all input tokens. - Scaling · Mask: The attention scores are scaled and a mask is applied to the upper triangle of the attention matrix to prevent the model from accessing future tokens, setting these values to negative infinity. The model needs to learn how to predict the next token without “peeking” into the future. - Softmax · Dropout: After masking and scaling, the attention scores are converted into probabilities by the softmax operation, then optionally regularized with dropout. Each row of the matrix sums to one and indicates the relevance of every other token to the left of it. Step 4: Output and Concatenation The model uses the masked self-attention scores and multiplies them with the Value matrix to get the final output of the self-attention mechanism. GPT-2 has 12 self-attention heads, each capturing different relationships between tokens. The outputs of these heads are concatenated and passed through a linear projection. MLP: Multi-Layer Perceptron After the multiple heads of self-attention capture the diverse relationships between the input tokens, the concatenated outputs are passed through the Multilayer Perceptron (MLP) layer to enhance the model's representational capacity. The MLP block consists of two linear transformations with a GELU activation function in between. The first linear transformation expands the dimensionality of the input four-fold from 768 to 3072 . This expansion step allows the model to project the token representations into a higher-dimensional space, where it can capture richer and more complex patterns that may not be visible in the original dimension. The second linear transformation then reduces the dimensionality back to the original size of 768 .This compression step brings the representations back to a manageable size while retaining the useful nonlinear transformations introduced in the expansion step. Unlike the self-attention mechanism, which integrates information across tokens, the MLP processes tokens independently and simply maps each token representation from one space to another, enriching the overall model capacity. Output Probabilities After the input has been processed through all Transformer blocks, the output is passed through the final linear layer to prepare it for token prediction. This layer projects the final representations into a 50,257 dimensional space, where every token in the vocabulary has a corresponding value called logit . Any token can be the next word, so this process allows us to simply rank these tokens by their likelihood of being that next word. We then apply the softmax function to convert the logits into a probability distribution that sums to one. This will allow us to sample the next token based on its likelihood. The final step is to generate the next token by sampling from this distribution The temperature hyperparameter plays a critical role in this process. Mathematically speaking, it is a very simple operation: model output logits are simply divided by the temperature : temperature = 1 : Dividing logits by one has no effect on the softmax outputs.temperature < 1 : Lower temperature makes the model more confident and deterministic by sharpening the probability distribution, leading to more predictable outputs.temperature > 1 : Higher temperature creates a softer probability distribution, allowing for more randomness in the generated text – what some refer to as model “creativity”. In addition, the sampling process can be further refined using top-k and top-p parameters: top-k sampling : Limits the candidate tokens to the top k tokens with the highest probabilities, filtering out less likely options.top-p sampling : Considers the smallest set of tokens whose cumulative probability exceeds a threshold p, ensuring that only the most likely tokens contribute while still allowing for diversity. By tuning temperature , top-k , and top-p , you can balance between deterministic and diverse outputs, tailoring the model's behavior to your specific needs. Auxiliary Architectural Features There are several auxiliary architectural features that enhance the performance of Transformer models. While important for the model's overall performance, they are not as important for understanding the core concepts of the architecture. Layer Normalization, Dropout, and Residual Connections are crucial components in Transformer models, particularly during the training phase. Layer Normalization stabilizes training and helps the model converge faster. Dropout prevents overfitting by randomly deactivating neurons. Residual Connections allows gradients to flow directly through the network and helps to prevent the vanishing gradient problem. Layer Normalization Layer Normalization helps to stabilize the training process and improves convergence. It works by normalizing the inputs across the features, ensuring that the mean and variance of the activations are consistent. This normalization helps mitigate issues related to internal covariate shift, allowing the model to learn more effectively and reducing the sensitivity to the initial weights. Layer Normalization is applied twice in each Transformer block, once before the self-attention mechanism and once before the MLP layer. Dropout Dropout is a regularization technique used to prevent overfitting in neural networks by randomly setting a fraction of model weights to zero during training. This encourages the model to learn more robust features and reduces dependency on specific neurons, helping the network generalize better to new, unseen data. During model inference, dropout is deactivated. This essentially means that we are using an ensemble of the trained subnetworks, which leads to a better model performance. Residual Connections Residual connections were first introduced in the ResNet model in 2015. This architectural innovation revolutionized deep learning by enabling the training of very deep neural networks. Essentially, residual connections are shortcuts that bypass one or more layers, adding the input of a layer to its output. This helps mitigate the vanishing gradient problem, making it easier to train deep networks with multiple Transformer blocks stacked on top of each other. In GPT-2, residual connections are used twice within each Transformer block: once before the MLP and once after, ensuring that gradients flow more easily, and earlier layers receive sufficient updates during backpropagation. Interactive Features Transformer Explainer is built to be interactive and allows you to explore the inner workings of the Transformer. Here are some of the interactive features you can play with: - Input your own text sequence to see how the model processes it and predicts the next word. Explore attention weights, intermediate computations, and see how the final output probabilities are calculated. - Use temperature slider to control the randomness of the model’s predictions. Explore how you can make the model output more deterministic or more creative by changing the temperature value. - Select top-k and top-p sampling methods to adjust sampling behavior during inference. Experiment with different values and see how the probability distribution changes and influences the model's predictions. - Interact with attention maps to see how the model focuses on different tokens in the input sequence. Hover over tokens to highlight their attention weights and explore how the model captures context and relationships between words. Video Tutorial How is Transformer Explainer Implemented? Transformer Explainer features a live GPT-2 (small) model running directly in the browser. This model is derived from the PyTorch implementation of GPT by Andrej Karpathy's nanoGPT project and has been converted to ONNX Runtime for seamless in-browser execution. The interface is built using JavaScript, with Svelte as a front-end framework and D3.js for creating dynamic visualizations. Numerical values are updated live following the user input. Who developed the Transformer Explainer? Transformer Explainer was created by Aeree Cho, Grace C. Kim, Alexander Karpekov, Alec Helbling, Jay Wang, Seongmin Lee, Benjamin Hoover, and Polo Chau at the Georgia Institute of Technology.

3

I don't want to read what you didn't write

Hacker News · original → · 8/10 · AI: critical perspective on AI-generated writing
I Don’t Want to Read What You Didn’t Write People who rarely produced original writing are suddenly producing extensive design proposals, business plans, documentation, presentations, tickets, pull…

I Don’t Want to Read What You Didn’t Write People who rarely produced original writing are suddenly producing extensive design proposals, business plans, documentation, presentations, tickets, pull requests, blog articles, and meeting summaries, all generated by AI. It is all unreadable. AI is helping me write better and faster, but I’m fed up with reading almost anything written by AI. In this essay, I want to express my frustration, and describe how I’m finding value in AI for writing. AI Is Terrible for Writing A pattern I see is that people use AI to build something new, then they use AI to retrospectively summarize what they have already built into a design document. Reading a document like this isn’t just difficult—it is punishing. The design document is no longer a proposal to build consensus, bring people along with you, and refine ideas through slow, deliberate thinking—it is a summary made by a machine, in exhausting detail, without context or perspective. It is unreadable. Inhumane. The authors of these documents become impatient when people aren’t engaged, and it is hard not to be, because the thing they built is already working.[1] I also see more and more pull request summaries clearly written by machines for machines. They are rich in detail: this was changed to that, these things were split, those things were merged, this was left untouched, tests were added for this, and so on. But I’m left asking: Why are we doing this? What is the value? How risky or urgent is this work? Where do you want my input? What should I pay attention to? The same goes for tickets or meeting summaries made by AI. The writing, like more and more of the world, consists of statements outside of context. I had someone write me a personal message about a sensitive topic that was clearly workshopped with AI in an effort to nuance the conversation and not offend me. But the message became impersonal, dispassionate, and disjointed. It had all of the parts, but it didn’t make sense as a whole. I wasn’t interested in reading it, or responding. I would much rather someone be themselves and write with their own voice, or with some passion, even if they can’t quite find the words, or risk offending me. In relationships with others, there is vulnerability and risk. In communicating with your AI, there is none, and attempts to eliminate vulnerability and risk will eliminate the process of relationship itself. As Simon Sarris writes in Resist Summary, an essay I keep returning to: I think one should write as much as they can with their own empiricism, their own senses, giving the reader their own characterization of life or events. —Simon Sarris, Resist Summary Perhaps the laziest and most offensive use of AI writing I have seen: I had someone use AI to summarize my comments on their proposal as their response to me! Thanks! I couldn’t have said it better myself![2] I Don’t Have the Context You Do Cynthia Dunlop recently shared survey results on reading AI-written articles entitled Report: How developers react to AI-scented blog posts. For the majority of readers, if they think an article is AI-assisted or AI-authored, they will stop reading (78%) and avoid the author in the future (71%). As Bryan Cantrill wrote about this research in his essay The revolt of the reader: “our brains pull an LLM-triggered ejection handle, bailing us out mid-sentence in an act of self-preservation.” The strongest result in the survey was people overwhelmingly preferred the author’s own writing (98%), with all its flaws and idiosyncrasies, as compared to a soulless rewrite by an AI. Writing authentically is one of the best ways to connect with people. It reminds me of a comment Bjarne Stroustrup, the creator of C++, made during a panel discussion I attended over a decade ago on writing books: When I read a book, I really feel that if I can hear the author’s voice ringing in my head—complete with weird accents and peculiarities of their speaking patterns—then I feel like something has succeeded. If it feels like dry, academic text, somebody has written yet another dry, academic text. And so, giving talks about the subject really helps. And, for many people, ... I can hear them when I read it, and that is good. —Bjarne Stroustrup[3] When you are the one who prompted the AI, the written output is often quite useful. But do not mistake this for effective writing. When you read the output, you already have lots of context—you formulated the prompts, established the constraints, and provided artefacts like documentation, source code, logs, statistics, pictures, etc., that led to the output. You can skim the output and quickly decide what is relevant and valuable versus what is irrelevant or wrong. You are also part of the process—prompting the AI and seeing the results—a call and an answer. You bring a human perspective to the machine. When you send the same text to someone else, they have little to no context. They are not part of the process—there is no unfolding—so it is much harder to decide what is relevant versus what is not. They are forced to read exhaustively and consider every line, peering into the internals of a machine with the hope of establishing context. It is only natural to stop reading. AI Can Be Great for Writing I recently wrote an academic paper.[4] I used AI extensively and it made the writing process faster and more enjoyable. But AI did not write a single line of the paper. I wrote the paper in LaTeX. The context I provided to the AI included the journal style guide and LaTeX template, all papers previously published in the journal, the source code for the software systems I was writing about, and the configuration, logs, and metrics for production deployments of the software. After writing a paragraph, many times I would ask the AI to ensure what I had written was correct by referencing the source code or configuration, or examining production logs or metrics. For example, ensuring I had correctly described which columns in the database were indexed, or how the rows in the Parquet files were sorted. This allowed me to stay in the context of writing, often moving on to the next paragraph while the AI verified the previous one. It helped me spot important omissions and inaccuracies. Remarkably, reversing this process—asking the AI to write the paragraph from the context I provided, like describing how something works from the source code—was never valuable. Not once. It was consistently unpleasant to read, and often inaccurate. Another thing that helped me stay in context was using AI to complete the citations. It is tedious to look up the details of a paper, website, or book, fill in the BibTeX format, and then reference it in the text. Instead, I would leave parenthetic instructions for the AI to reference what I wanted, and then keep on writing without breaking stride.[5] The AI was incredibly good—indeed ruthless—at finding spelling and grammar mistakes. It was great at suggesting simplifications to sentences that are too long or unclear.[6] It was skilled at drawing technical diagrams in TikZ, again speeding up the work, and saving me from learning this syntax. The AI even found a very subtle mistake where I had used the incorrect notation in one paragraph, something four human reviewers who were experts in the system all missed.[7] What was the one thing the AI was incredibly good at writing? It wrote the abstract—the most terse, mechanical, inhuman part of the whole paper—indeed, the most abstracted part. I included it entirely unchanged. Perhaps this shouldn’t be a surprise, as AI is great at summary, abstraction, and re-presentation of original work. Can AI Become Good at Writing? It would be a mistake to underestimate the writing that can one day be achieved by AI. We are still in the very early days of model development, and the models most of us are using are trained to be factual, direct, and correct, rather than creative. However, Murat Demirbas’s excellent essay The Safest Job from AI may be Writing notes that the quality of writing from LLMs has plateaued and it may be difficult to improve since unlike programming, mathematics, and accounting, it is difficult to provide a clear formulation and verifiable output.[8] Since LLMs lack an active mental model of a specific human reader, they are just optimizing for the statistical probability of the next word over a vast dataset. They cannot empathize with the human reader, as they don’t have the human lived experience. And they have zero skin in the game. —Murat Demirbas, The Safest Job from AI may be Writing I am interested in two efforts to improve AI writing that I’ve recently come across. The first is ASD-STE100 Simplified Technical English, a standard for writing technical documentation that grew out of an aerospace working group in the 1980s. It has two parts: a controlled dictionary and writing rules about grammar and style. A version of ASD-STE100 has been created for use with AI models.[9] ASD-STE100 isn’t appropriate for all AI-generated writing—it is specifically targeted at clear and easy-to-follow instruction manuals. I’m going to give it a try for installation instructions, runbooks, and similar documentation. The second is Pangram, a model fine-tuned to detect AI writing. Bryan Cantrill in the essay The revolt of the reader notes: To use an LLM to write is to void the social contract between writer and reader: we readers shouldn’t be expected to labor to understand a sentence that the writer themselves didn’t work to create. —Bryan Cantrill, The revolt of the reader I could not agree more. Bryan has started experimenting with Pangram to detect AI-generated writing that violates this contract and has gone so far as to mandate that all public writing at Oxide be reported by Pangram as human-authored. A tool like this could save us from the laziest and worst AI writing.[10] When There Are No Words When we write, the meaning of our words is not always direct, factual, or concise. Examples include poetry, literature, song, mythology, humour, and theatre. Iain McGilchrist, who I believe is one of the most important writers of our generation, writes in the book The Matter with Things: “The more important something is, the more we have to struggle in the attempt to reduce it to language.” Ask an LLM what the reliable formula is for falling in love. In AI-generated writing, detailed information gives the illusion of meaning. But in mimicking human knowledge, intelligence, and understanding, an AI writing about the facts is very different from the quality of writing from a lived experience. The whole cannot be decomposed into parts without a substantial loss of meaning. The direct approach destroys its object. Similarly, there are things that can be conveyed only indirectly. To recapture the depth of what is said, or in order to say anything truly new, we are always engaged in going beyond everyday language, which means being alert to what is being said implicitly. —Iain McGilchrist, The Matter with Things It might seem silly to say that writing in business, engineering, or science should involve uncertainty, not just facts and conclusions. But operations, incident response, product development, performance engineering, hunting for security vulnerabilities, performance reviews, mission statements, and many other endeavours, are all creative and involve uncertainty. The narrative is regularly as important as the facts and conclusions. It is also easy to anthropomorphize LLMs as good systems thinkers because they can synthesize such a wide range of information. However, returning to Simon Sarris: “narrative resists compression” and “the opposite of summary is attention to detail”. Despite an emphasis on linear, first-principles thinking, the work of a good systems engineer, just like the work of a good anthropologist or psychologist, is difficult to put into words, and especially into summary. You can’t necessarily observe and write things down using a formula. Even writing things down loses some of the context. The observer is also part of that context. Systems work always has some sense of discovery, holding open the unknown, an unfolding of relationship with the system itself, and a willingness to be surprised. Normal language doesn’t always have the words.[11] The nature of the output, of summary, is speed things along. But the consequence is to avoid you having to build your own complex mental model of anything. I worry that without a complex model in one’s own mind, one may never notice complex relationships that are otherwise missed. A loss of attention to detail. —Simon Sarris, Resist Summary Conclusion I don’t want to live in a world where you use AI to summarize something important into unreadable text, and then I use AI in an attempt to decipher it. I want to hear you, imperfections and all. I want your interpretation of aesthetics, beauty, quality, relationship, time. I want to know how you feel. I want you to cut through and tell me what really matters. I don’t want to read a summary of facts and connections separate from experience and relationship. As Iain McGilchrist describes, the way we attend to the world changes the nature of what comes into being, the only world we can know.[12] If you ask a machine to do something for you, you are at risk of not asking for what you want, but what it can do well. If what it can do well is summarize, and you rely upon the tool, you may tune your questions so that you get better answers. This looks like training a machine to do what you want, but its also training yourself to ask questions about the world in a certain way. What are the questions you are omitting? —Simon Sarris, Resist Summary Intentional writing will likely become more valuable. People who write, and write to think, to think deeply and carefully, or to create, to share, or to capture something important without explicitly expressing it will continue to write and produce original work. The people who never were writers will use AI to produce lots of text. As we read more and more text generated by AI, we might not notice what AI has disrupted and changed, because we’ve become more shallow anyway. The search for certainty limits our humanity. Sometimes it is more important to not find the words. I don’t want to read what you didn’t write. In some instances, design documents are not the right fit, and using AI to rapidly collaborate around working software is perhaps a better approach to refine ideas and build consensus. ↩︎ In another example, a group of people had been working on a proposal, building consensus through a number of wiki pages. Someone new wanted to modify the proposal. Rather than going through the messy, relational process of working with this group to update the existing wiki pages, they used AI to proliferate a new wiki page, copying the existing work and adding their own twist. ↩︎ I’ve used this quote previously in Techniques for Improving Your Technical Writing. ↩︎ The paper describes a database I created and my hope is it will be accepted to The Conference on Innovative Data Systems Research (CIDR). ↩︎ For example, I would write: {TODO: reference the Amazon Aurora paper} and the AI would take care of the rest. ↩︎I also use AI as an editor for my blog. It gives me more confidence posting an essay without having someone else proofread it. But I only let AI identify errors or make suggestions. I don’t let it rewrite and change my voice or perspective. ↩︎ I was describing a log-structured merge (LSM). We had originally called the levels Generation 1, Generation 2, Generation 3, or Gen1, Gen2, Gen3 for short. In the paper, I described the LSM more generically using L0, L1, L2 for Level 0, Level 1, Level 2, respectively. This meant my colleagues reading this paper had to map L1 to Gen2 in their heads, which made my error in one paragraph of incorrectly using L1 when I meant L2 extra hard to spot. The LLM found it, no problem. ↩︎ Another interesting essay on the limitations of AI for writing, especially the individuality in understanding, is The Human Skill That Eludes AI: Why can’t language models write well? by Jasmine Sun in The Atlantic. ↩︎ Thanks to Chris Riccomini for making me aware of this. ↩︎ For more on Pangram, listen to the Oxide and Friends podcast with the founder Max Spero. One thing they note is there is some evidence that people who use LLMs regularly are good at detecting LLM writing, but people who do not are less adept. There is also an interesting discussion about trying to reverse the prompt and the input context in an effort to describe how much of the output came from the input and how much came from the model. ↩︎ The best systems thinkers I know tend to be excellent writers. I expect this skill to remain important and perhaps become even more important. Returning to Murat Demirbas’s essay on writing that I referenced earlier, it concludes: “And maybe programming itself is turning into a form of creative writing, getting more opinionated and more architectural.” ↩︎ Iain also draws the distinction between comprehension—taking the world as a whole—and apprehension—taking hold of the world. The quality of attention is different. I find it interesting that while apprehension is the act of seizing or capturing, it is also a fearful or uneasy anticipation of the future. I highly recommend watching Iain’s lecture AI and the Battle for the Soul: Information is Not Understanding at Ralston College. ↩︎
4

AI coding has made CI a bottleneck, so we reworked ours to keep up

Hacker News · original → · 8/10 · AI/platforms: CI/CD optimization with AI agents
AI coding has made CI a bottleneck, so we reworked ours to keep up Earlier this year, I opened Linear to find that Tuomas, our CTO, had assigned an issue to me, titled “CI costs are high.” While I…

AI coding has made CI a bottleneck, so we reworked ours to keep up Earlier this year, I opened Linear to find that Tuomas, our CTO, had assigned an issue to me, titled “CI costs are high.” While I was at it, he also wanted me to make CI faster. Agents have made it exponentially faster to ship code, but validating those changes hasn’t quite kept up at the same rate. Every PR still has to pass through CI, so as development accelerates, CI becomes a bottleneck, driving up infrastructure costs and leaving developers and agents waiting longer for feedback. In our pursuit to make CI more performant at Linear, we optimized for how long a PR waits on CI and how much runner time it consumes. Despite our test suites almost quadrupling since the start of the year, we brought pull request wait time down from more than 6 minutes to just over 5, while cutting runner time per test roughly in half. Broadly, we improved CI in four ways: - Upgraded infrastructure and tooling - Optimized the jobs that gate other work - Reduced repeated setup - Made test execution more efficient Linear’s codebase is primarily TypeScript, but many of these optimizations apply across languages and toolchains. Upgraded infrastructure and tooling Some of our earliest gains required almost no optimization of CI itself. Moving our workloads off GitHub Actions to third-party runners with faster CPUs, higher-performance storage, and better cache infrastructure gave us faster machines to run the same pipeline on. In a like-for-like comparison of the two days either side of the switch, jobs ran 34% faster on average, with some workloads like tsc dropping 52%. Separately, modernizing our toolchain also paid off. Switching to tsgo , the native TypeScript compiler, cut the weekly median of the tsc check by 73%, large enough to move the bottleneck off of typechecking entirely. Lint without the type checker Linting was another early target. A handful of our custom lint rules depended on TypeScript type information, either to enforce a restriction or apply an autofix. That meant every lint run had to build the full type graph before evaluating those rules, making linting one of our most memory-intensive CI jobs. We rewrote the rules to use static analysis over the abstract syntax tree, identifying function-like constructs and guard patterns without type information. That let ESLint drop TypeScript entirely, reducing API lint time by 68%, and full-repository lint time by 55%. Memory usage dropped substantially as well. Removing the dependency on type information also made our later move to Oxlint much easier because rules that operate purely on syntax are straightforward to port. Oxlint itself reduced the CI runner-minutes spent on linting. Optimize the jobs that gate other work With the underlying infrastructure and individual checks running faster, we zoomed out to look at CI as a system. That drew our attention to the small jobs that sat in front of everything else. Every run starts by checking which paths a PR touched and whether these tests have already passed for the same inputs. We gate on those checks at the job level so skipped work never reserves a runner, but that also puts them directly on the critical path. None of the eight API test shards can start until they finish, making even small delays disproportionately important. Fetch only what each job needs Several of our workflows start with a change-detection job that decides what runs next; for instance, it checks whether a diff contains a database migration and outputs a signal used to schedule the relevant database CI checks. These jobs were checking out the full working tree even though they needed only a small subset of it. We capped the fetch depth, which took the slowest of these gates from 94 seconds to 20, and removed checkout entirely from the jobs that never needed a working tree, reducing time spent on those from 27 seconds to 7. For commit push and merge-queue events, where we do have to diff paths, we found that a sparse, blobless checkout with limited history was enough, saving another 11 odd seconds. Make checkout more resilient After we swapped the underlying runner infrastructure, we noticed that our checkout times (with actions/checkout ) in our jobs had gotten longer and would sometimes hang. Because the third-party runners sit outside GitHub’s network, they rely on a direct IP link to reach GitHub. The provider traced the hangs to intermittent degradation on that link. Several of our workflows begin with a checkout, so a stalled fetch could delay the entire CI run. To be resilient to the network instability, we replaced actions/checkout with a composite action of our own that retried with backoff, and sets GIT_HTTP_LOW_SPEED_LIMIT and GIT_HTTP_LOW_SPEED_TIME so a stalled connection aborts after about 30 seconds instead of hanging and also uses the checkout cache, which keeps a persistent git mirror on a sticky disk. The result was far fewer runs where a critical-path job sat idle waiting for checkout to finish. Minimize what’s on the critical path Not every job on the critical path needed to be there. We were writing cache markers as part of the final check before merging, which meant a pull request could sit in the merge queue even after its tests had passed. We moved that write into a job that runs once the test shards finish but gates nothing, shaving 42 seconds from the merge path for every API pull request and merge-queue entry. Together, these changes took roughly a minute off the required check for API pull requests on cache misses, while also reducing runner starts. Reduce repeated setup From there, we turned to the setup cost repeated across every job, like booting a runner, installing packages, and provisioning build dependencies. That overhead means a job that does only seconds of useful work can end up consuming whole minutes of infrastructure time. Here are a few steps we took to work around that issue: Our API test shards each spent 7 to 8 seconds installing the same Postgres client with apt on every run. We moved it into a small CI base image containing Node and the client, so each shard could start from an environment that was ready to run. We later added the required native build headers to the image after discovering that downloading them during setup could occasionally hang, shortening the tail. Install only the dependencies each job needs Linear’s codebase is a monorepo managed as a pnpm workspace. Our API test workflow was installing the entire workspace even though it only needed the API package and its dependencies. Restricting the install to our API package cut pnpm install from 44-73 seconds to 16-18 seconds. We applied the same pattern to API-adjacent jobs, which were each installing the full repository and uploading a dependency cache that later runs almost never hit. Don’t cache when it’s faster to rebuild We also tested caching node_modules and found it was faster to rebuild. The cache key depended on a frequently changing lockfile, and even a cache hit took about 28 seconds to restore, compared with roughly 7.5 seconds for a filtered install. The cache was adding save time and variability without giving us any discernible advantage. Together, these three changes reduced per-shard setup time by roughly 44%, from 110-140 seconds to 67-73 seconds. Beyond this, there were other forms of repeated setup we could avoid altogether. Avoid replaying unchanged setup Some setup work only needs to be repeated when its inputs change. Our API containers, for example, were replaying the full database migration history on every run, even when a PR hadn’t changed the schema. For those cases, we switched to loading a generated schema snapshot and bootstrap file instead, cutting database setup from roughly 12 seconds to 1-2 seconds per container. Batch short checks into fewer jobs Seven independent checks were each starting a runner, checking out the repository, and installing dependencies before doing only seconds of useful work. We consolidated them into two jobs, and then ran the seven tasks concurrently inside them. That reduced the number of times we paid the same setup overhead from seven to two. Based on June usage, the change saved roughly 87,000 runner-minutes per month, equivalent to 11.8% of our total CI usage. Make test execution more efficient With the fixed cost of each test shard down, we could afford to parallelize the API suite more aggressively. It was the largest and one of the most frequently executed parts of our workflow, so improvements there had an outsized effect on merge time. Balance work the way the test runner sees it Vitest, the test runner we use for our TypeScript test suites, distributes work by file rather than by the duration of individual tests. That meant a few unusually large test files could dominate a shard and effectively hold up completion of the entire suite, even when the other shards finished much earlier. We split those large files into smaller, more focused files while preserving the structure of the tests, then evaluated different shard and runner configurations. We had already gone from three to four shards earlier in the year; moving to eight made the critical job roughly 19% faster and 19% cheaper in our initial benchmark. A week after the change, the slowest shard dropped from 5.25 minutes to 4.33 minutes. Vitest normally isolates every test file, which for us meant rebuilding the entity, GraphQL, and decorator graph in each test shard. We introduced an opt-in vitest project with isolate: false , allowing safe files to share a module registry within each worker. This was our largest single performance improvement, worth roughly 17% in monthly savings at our volume. The slowest shard fell from roughly 300-379 seconds to about 195 seconds, while total API-shard runner time dropped from about 32.8 to 22 minutes per run. It was also the optimization with the highest correctness risk. We made eligibility explicit with an opt-in comment on every file, and added the necessary teardown for shared state. A handful of files used fake timers or shared state in ways we couldn’t untangle safely, so we left them in the isolated project. And because agents now write the majority of our tests, we updated our respective agent skills to account for this performance opt-in as well, so generated tests follow the same constraints by default. Further sharding only pays off when the fixed cost per shard is low, since doubling the shard count also doubles the workflow time spent on setup. The setup optimizations we referred to earlier are what made eight shards practical. At 110-140 seconds per shard, eight shards would have spent 15-19 minutes of runner time on setup alone, more than the tests themselves. Setup is now around 40 seconds, so eight shards spend less total setup time than four did before, while parallelizing the tests twice as far. Improvements that compound across a system Had we not made a deliberate effort to improve CI earlier this year, today’s test suite would take roughly 11 minutes, close to double what developers wait now. And the work doesn’t end here. It’s clear that our codebase will continue to grow; we’re currently adding roughly 2,000 tests a week. Keeping CI fast as that happens will be a continued effort, much of it using what we learned through this process to new bottlenecks.

5

How Warp ships 2,000 PRs a month with AI factories | Zach Lloyd (CEO, Warp)

Lenny's Newsletter · original → · 8/10 · Platforms/SaaS: Warp AI software factories
Zach Lloyd is the co-founder and CEO of Warp, an AI-powered terminal and software factory platform used by tens of thousands of engineers. Before Warp, he spent nearly a decade at Google, including…

Zach Lloyd is the co-founder and CEO of Warp, an AI-powered terminal and software factory platform used by tens of thousands of engineers. Before Warp, he spent nearly a decade at Google, including time as a principal engineer on Google Sheets. He built Warp from the ground up as a modern, AI-native alternative to legacy terminals, and the team has since expanded into software factories: a full cloud-based system that takes an idea in Slack all the way through to a merged PR.

Listen or watch on YouTube, Spotify, or Apple Podcasts

In this episode:

  1. Why a software factory is more than a coding agent

  2. The public Slack → Linear → GitHub → QA workflow

  3. Human interactions per PR as a signal of automation and throughput

  4. Why human review is still the bottleneck

  5. Scoring agent runs, finding failure modes, and self-improving agent workflows

  6. Replaying real tasks to choose model cost and quality tradeoffs

  7. CEO workflows with Figma MCP, Granola, and research agents


Brought to you by:

DX—Engineering intelligence for the AI era

OpenArt—An all-in-one AI creation platform for images, videos, music, audio, and more

In this episode, we cover:

(00:00) Intro

(02:35) Warp’s AI software factory, Wilson

(09:23) Automatic factory triggers

(11:12) The engineering leader dashboard Zach wishes he’d had

(15:18) How code review is changing in an AI factory

(17:08) Tracking cost per PR across model configs

(18:47) Using LLM-as-a-judge to score every agent run

(20:02) Catching redundant tests

(22:19) How the factory self-improves from failed runs

(26:03) Quick recap

(28:33) Building a cost-quality Pareto chart for model selection

(31:35) How Zach uses AI for non-technical CEO work

(32:10) Figma MCP demo

(35:43) Granola MCP demo

(36:41) GOG CLI demo

(38:20) Thinking in parallel tasks instead of sequential ones

(40:42) Zach’s prompting strategy for factory tasks

(44:48) Where to find Zach

Tools referenced:

• Warp (AI terminal and software factories): https://warp.dev

• Warp Factories: https://warp.dev/factories

• Linear (project and issue tracking): https://linear.app

• GitHub (version control and PR management): https://github.com

• Slack (team communication and factory input layer): https://slack.com

• Sentry (crash reporting and automated issue triggers): https://sentry.io

• Figma (design, used via Figma MCP): https://figma.com

• Granola (AI meeting notes and MCP integration): https://granola.so

• Grok Bot (fast inference, cost/quality trade-off): https://x.ai/bot/guides/grok-bot-101

Where to find Zach:

X: https://x.com/ZachLloydTweets

Where to find Claire:

ChatPRD: https://www.chatprd.ai/

Website: https://clairevo.com/

LinkedIn: https://www.linkedin.com/in/clairevo/

X: https://x.com/clairevo

Production and marketing by https://penname.co/. For inquiries about sponsoring the podcast, email jordan@penname.co.

6

Jev introduces a new shape of LLM - System One, aka Decision Models

Simon Willison · original → · 8/10 · AI: new LLM architecture category (decision models)
Jev introduces a new shape of LLM—System One, aka Decision Models 21st September 2026 Last week TypeSafe AI unveiled Jev, their first example of a new category of model that they are calling “System…

Jev introduces a new shape of LLM—System One, aka Decision Models 21st September 2026 Last week TypeSafe AI unveiled Jev, their first example of a new category of model that they are calling “System One models” (I’m with Maggie Appleton, I think “decision models” is a better name for these). Jev is an interesting variant on the usual LLM format: it still accepts text inputs, but instead of text output it returns floating point numbers corresponding to categories, yes/no questions, ratings, and associated confidence scores. TypeSafe describe Jev like this: Think of Jev as a frontier-intelligence function call: unstructured state in, typed probabilistic decisions out. It’s also very fast, and really cheap. Regular LLMs are priced in terms of input and output tokens, with output generally charged at significantly higher rates. Jev charges only for input—output is free—and the input price of their first model is $0.042 per million tokens—cheaper even than OpenAI’s GPT-5 Nano ($0.05/million). Jev lets you ask questions about text or semi-structured data. You compose a “state” object containing a string, array of strings, or set of name-value pairs—this might describe an article, or a customer, or any other kind of record. You then send that to their API with one or more questions, and get a reply back for each. You can ask three kinds of questions: - Yes/No questions, which Jev calls “Noul” questions—their CEO confirmed on Hacker News that this is short for Bernoulli, from the Bernoulli distribution. You pose a statement and get back a floating point number between 0 and 1 for how confident the model is that the statement is true. - Choice questions, where the model picks one from a set of provided options—actually a confidence score plus a probability distribution across all of the options. - Score questions, where you provide sequence of numeric levels with descriptions and it provides a floating point score somewhere along that range. The Jev API can accept a single document (“state”) and as many questions as you can cram into the context window. Questions are evaluated in parallel, so sending many questions should take a similar time to sending just one. I think the decision model framing is useful for understanding where to use Jev. It’s great for anything that can be expressed as a classification task—think spam detection, suggesting labels, prioritization and ranking. I’ve also been experimenting with it for search reranking, where you fetch 100 likely matches using an inexpensive algorithm like BM25, then have Jev score those 100 candidates for relevance against the original query. Black boxes are back in fashion Something I’ve found a little uncomfortable about Jev is how it very much represents a regression even further towards black box machine learning systems. LLMs are black boxes already—you can ask them to justify their decisions, but you can’t guarantee that what they say is useful or accurate. Jev doesn’t even give you that: put in all the text you want, the only thing you’re going to get back is a floating point number. If Jev marks something as spam, which content signals tipped it off? This also means that concerns about bias should be front and center. I really hope nobody uses Jev to rank job applicants—that floating point number could conceal all manner of unseen bias baked into the models, and experimentally picking that bias apart is going to be a tricky business. (I tried one experiment where I had Jev score every city in the San Francisco Bay Area on a yes/no answer to whether they were a “Good city?”—it rated Cupertino top and East Palo Alto bottom. Huh.) In practice, this all means that evals and structured experiments are even more important than they are for regular LLM projects. Thankfully, Jev is so cheap that running hundreds or even thousands of experimental prompts through it costs just a few cents. Unconventional uses for Jev It’s been really fun watching the wider community come up with potential use-cases for Jev over the past few days. Here are some creative ones that caught my eye: - jevchat by Kyle Pena turns Jev into a (terrible) chat model. “At every step it asks Jev one question: Given the user’s question and the reply written so far, which symbol comes next?”. ericpruitt on Hacker News: “It’s the digital equivalent of Morty speaking with the death crystal”. - jev-leftpad by Fatih Kadir Akın implements left-pad with the prompt “How many spaces are needed before value to reach targetLength?” and a choice query allowing options from “0 spaces are needed” to “10 spaces are needed”. - jev-2048 by Andy Gayton uses Jev to play the 2048 sliding puzzle game. Open weight recreations There’s also been a flurry of projects attempting to create a model like Jev using on top of open weight models. Kev is one interesting example, using Qwen 3.5 to produce 0.8B, 4B, and 9B models. Here’s the accompanying Hacker News thread, where someone linked to a JevBench benchmark that has already cropped up to compare “Jev-class decision models”. Given Jev was released just under a week ago, the amount of activity around it is extremely impressive. More recent articles - Generating running routes with GPT-6 Astra and ChatGPT Work - 12th September 2026 - OpenAI agents attacked RubyGems back in May - 12th September 2026

7

Cloudflare Python Workers are now generally available

Simon Willison · original → · 8/10 · Platforms: Cloudflare Python Workers GA
21st September 2026 - Link Blog Cloudflare Python Workers are now generally available (via) After a two year preview, Cloudflare's support for running Python code in their server-side Workers…

21st September 2026 - Link Blog Cloudflare Python Workers are now generally available (via) After a two year preview, Cloudflare's support for running Python code in their server-side Workers platform is now stable: "Python is now a first-class, fully supported language on the Cloudflare Developer Platform". A neat thing about this is how it works. Cloudflare are running Python compiled to WebAssembly via Pyodide in their V8-based workerd runtime. This comes with some limitations, documented here - most notably both multiprocessing and threading are non-functional in the WebAssembly VM. One particularly interesting detail of this is the local development environment story - their pywrangler development tool (confusingly packaged as workers-py on PyPI) runs a full local simulation of their stack, including executing code with Pyodide in WebAssembly in V8 in a 123MB workerd binary, which for me ended up in node_modules/@cloudflare/workerd-darwin-arm64/bin/workerd . Python Workers represent a significant investment in the wider Python ecosystem by Cloudflare. The release announcement is credited to Gyeongjae Choi, Dominik Picheta, and Hood Chatham - Gyeongjae and Hood are both Pyodide core maintainers. Recent articles - Jev introduces a new shape of LLM - System One, aka Decision Models - 21st September 2026 - Generating running routes with GPT-6 Astra and ChatGPT Work - 12th September 2026 - OpenAI agents attacked RubyGems back in May - 12th September 2026

8

🎙️ How I AI: Meta’s Muse review + How Warp ships 2,000 PRs a month with AI factories

Lenny's Newsletter · original → · 7/10 · AI/platforms: Meta Muse agent and Warp CI
[image →]Muse review: The personal AI agent that gets consumer UX rightListen now on YouTube • Spotify • Apple Podcasts[image →]Brought to you by:Optimizely—Your AI agent orchestration platform for…

Muse review: The personal AI agent that gets consumer UX right

Listen now on YouTube • Spotify • Apple Podcasts

Brought to you by:

Optimizely—Your AI agent orchestration platform for marketing and digital teams

OpenArt—An all-in-one AI creation platform for images, videos, music, audio, and more

In this solo episode, Claire tests Meta’s Muse, a personal AI agent designed for everyday users. She walks through how it manages her family calendar, creates a polished morning newsletter, tracks personal goals, and asks for permission before acting on sensitive information. She also explores the thoughtful details that make Muse feel trustworthy, where its browser use still falls short, and what its approach could mean for the future of consumer AI.

Biggest takeaways:

  1. Meta’s consumer design expertise makes Muse feel different from other agents on the market. The teams behind Facebook and Instagram understand how to build trust with nontechnical users, and that experience shows up throughout Muse. It never exposed Claire to a terminal, surfaced a confusing error, or requested permission at an awkward moment. She tested onboarding, calendar management, email ingestion, goal setting, and browser-based purchasing in one session without encountering a single moment of friction that broke the experience.

  2. Muse created the best version of Claire’s family morning brief on its first attempt. Claire has tested generating family newsletters with OpenClaw and Codex, but Muse produced a more beautiful and thoughtfully structured PDF without requiring any follow-up prompting. It even added a “Talk at the Table” section with kid-friendly questions about the news and proactively identified scheduling conflicts. That is the standard personal agents should aim for: not simply completing the request but noticing useful things the user did not think to ask about.

  3. How an agent requests permission matters as much as what it can do once permission is granted. Muse does not default to unlimited access or interrupt the user with constant approval requests. It asks at the moment access becomes relevant, confirms what it found, and checks again before taking action. After reading Claire’s email to build a family profile, for example, Muse summarized what it had learned and asked whether it could use that information. Anyone building an agent that handles personal data should pay attention to that interaction pattern.

  4. Muse’s activity feed provides the kind of agent transparency Claire wants everywhere. Every task includes a detailed record of the tool calls, scripts, searches, and individual steps Muse completed. Most consumers will probably ignore it, but developers and power users will find it invaluable. Claire immediately wanted the same interface in Codex and Claude Code. Seeing exactly how an agent arrived at an outcome builds a different level of trust than receiving a polished result with no visibility into the process.

  5. Personal goals require a different product model than tasks or chat. Helping someone gently sleep-train an eight-and-a-half-month-old while room-sharing in a small house is not a request that can be completed in one sitting. Muse gathered context across multiple turns, established a reminder, and treated the situation as an ongoing goal whose progress should be tracked. Its tone was warm and specific without becoming overly agreeable. Claire said she felt “zero percent annoyed” with it, which she described as a miracle.

  6. Browser use remains the weak link for consumer agents. Muse struggled to shop for New Balance 9060s in a specific colorway, returning incorrect results and failing to complete the purchase. It performed better while buying tickets for The Odyssey, but initially opened the wrong movie. These failures are not unique to Muse. They are a reminder that browser-based shopping remains unreliable across the entire agent category.

  7. Muse’s animated avatar shows what it means to design specifically for AI. Instead of displaying a generic spinner while it works, Muse generates an animation in which its avatar picks up a tiny laptop when completing tasks and an orb when creating media. Nobody asked for this feature, but it makes the agent’s state immediately understandable. For Claire, this is what operating at the top of the craft looks like. It is not just polished corners and clean icons. It is using capabilities like image generation and animation to solve experience problems that could not have been solved before.

  8. Muse is introducing a new vocabulary for consumer AI. It avoids technical terms such as crons, tools, artifacts, plugins, and connectors. Instead, it organizes the product around a feed, ideas, goals, and a library. That language is a deliberate design decision. The words a product uses determine who feels comfortable using it, and Muse is clearly designed for a much broader audience than today’s coding and productivity agents are.

Blog and detailed workflow walkthroughs from this episode:

Meta Muse Review: A Personal AI Agent for Family Life: https://www.chatprd.ai/how-i-ai/meta-muse-review-personal-ai-agent
↳ How to Create a Printable Family Newsletter with Meta Muse: https://www.chatprd.ai/how-i-ai/workflows/meta-muse-printable-family-newsletter
↳ How to Set Personal Goals and Reminders with Meta Muse: https://www.chatprd.ai/how-i-ai/workflows/meta-muse-personal-goals-reminders
↳ How to Find and Buy Movie Tickets with Meta Muse: https://www.chatprd.ai/how-i-ai/workflows/meta-muse-movie-tickets

How Warp ships 2,000 PRs a month with AI factories | Zach Lloyd (CEO, Warp)

Listen now on YouTube • Spotify • Apple Podcasts

Brought to you by:

DX—Engineering intelligence for the AI era

OpenArt—An all-in-one AI creation platform for images, videos, music, audio, and more

Zach Lloyd is the co-founder and CEO of Warp, an agentic development platform for software teams. In this episode, he demonstrates how Warp Factories turns a request in Slack into a tracked, tested, and merged pull request, with the first PR ready in as little as 35 minutes. He also explains how the team measures human involvement, scores every agent run, replays real tasks to compare models, and uses failed runs to continuously improve the factory itself.

Biggest takeaways:

  1. A software factory is not just a faster coding agent. It is the entire development lifecycle running in the cloud. Warp’s factory, Wilson, can take a request from Slack through triage, Linear ticket creation, implementation, pull-request creation, computer-use QA, and merge without a human touching the keyboard. The difference between a factory and a coding agent is the difference between an assembly line and a single machinist. One completes a task. The other coordinates the entire production process.

  2. “Human interactions per pull request” may be the clearest measure of factory efficiency. Every follow-up prompt in Slack, clarification on a Linear ticket, and correction during code review represents additional human effort. Zach believes that the more steering an agent requires, the lower the factory’s true throughput becomes. It does not matter how quickly the agent writes code if a human remains the rate limiter, yet most teams are not measuring this.

  3. Humans in code review are now the biggest bottleneck in Warp’s engineering process. Wilson takes an average of 35 minutes to move from kickoff to pull request. The first human review arrives 3.5 hours later. Warp has already removed one source of delay by allowing the person who prompted the agent to review its work instead of requiring a separate reviewer. The company has not eliminated human review entirely, but Zach expects that accumulated trust will eventually make it possible for selected changes to merge without human review.

  4. A company’s own past work provides a better model benchmark than a public leaderboard. Benchmarks such as SWE-bench and Terminal-Bench measure performance on generic tasks. Warp instead replays real factory jobs using different model configurations, evaluates them with the same judging system used in production, and maps the cost-quality tradeoff on a Pareto chart. For Warp’s workload, model selection is the largest cost lever by far, with context management a distant second.

  5. Software factories can improve themselves when their configuration lives in code. Warp’s improvement loop collects failed runs until there is enough evidence to identify a pattern, typically around 20 to 25 examples. An observer agent analyzes what went wrong and proposes changes to the factory’s agent definitions. Because those definitions are stored as code, the same agents that complete the work can also update the instructions governing how they operate.

  6. The scoring layer is what separates a reliable factory from a vibe-coded pipeline. Warp uses an AI judge to score every agent run across multiple dimensions, including whether it created redundant tests. Agents often write tests that merely confirm current behavior instead of protecting against future regressions. The judging model is intentionally mid-tier so evaluation costs do not erase the factory’s savings, and Warp can adjust the sampling rate depending on how much oversight a workflow needs.

  7. AI becomes far more valuable outside engineering when it connects to real business data. During the conversation, Zach ran three tasks in parallel: redesigning a slide through Figma, extracting the 10 most common sales questions from four weeks of Granola transcripts, and creating a cold-lead re-engagement list in Google Sheets. The redesigned slide was useful, but the Granola analysis was more consequential. It identified “buy versus build” as the top customer question and backed that conclusion with evidence, giving Warp a clear signal about what its website and sales deck should address next.

  8. Working with agents in public can spread expertise without a formal training program. Every Wilson task runs in a shared Slack channel, allowing junior employees to watch experienced users prompt, steer, and correct the system in real time. Zach sees a power-law effect in agent usage: a small number of people become dramatically better than everyone else. Making their workflows visible allows those skills to spread quietly across the organization.

  9. Building faster does not help if the team builds the wrong thing. Warp still relies on user interviews, design sessions, and direct observation of how people use the product. The factory dramatically accelerates implementation, but it does not decide what deserves to be built or why. Those decisions still depend on human taste, customer understanding, and product judgment. The build phase may be changing quickly, but the work that comes before it remains remarkably traditional.

Blog and detailed workflow walkthroughs from this episode:

Inside Warp’s Software Factory: https://www.chatprd.ai/how-i-ai/inside-warps-software-factory
↳ How to Build an Automated Software Factory: https://www.chatprd.ai/how-i-ai/workflows/how-to-build-an-automated-software-factory
↳ How to Build an AI-Powered CEO Toolkit: https://www.chatprd.ai/how-i-ai/workflows/how-to-build-an-ai-powered-ceo-toolkit
↳ How to Measure and Self-Improve Your AI Software Development Factory: https://www.chatprd.ai/how-i-ai/workflows/how-to-measure-and-self-improve-your-ai-software-development-factory


If you’re enjoying these episodes, reply and let me know what you’d love to learn more about: AI workflows, hiring, growth, product strategy—anything.

Catch you next week,
Lenny

P.S. Want every new episode delivered the moment it drops? Hit “Follow” on your favorite podcast app.

9

MCP was always a bad idea?

Simon Willison · original → · 7/10 · AI: Model Context Protocol design critique
20th September 2026 This article entirely misses the value that MCP brings today. Sure, there's almost no reason to use MCPs if you are running a full-blown terminal agent (Claude Code, Codex, Meta…

20th September 2026 This article entirely misses the value that MCP brings today. Sure, there's almost no reason to use MCPs if you are running a full-blown terminal agent (Claude Code, Codex, Meta Muse, OpenClaw etc) with unfettered internet access - just let it call APIs directly. If you want to operate something that's less YOLO than that, you'll find yourself wanting: - Control over exactly which external services it can access - A way to handle authentication that doesn't allow the agent to directly access API keys - A sensible UI to allow users to connect and authenticate further services - Strong audit logging for what's going on MCP makes all of that so much easier to provide. Thinking MCP is obsolete because full coding agents don't need it misses out on all of the other things we might want to build. Recent articles - Jev introduces a new shape of LLM - System One, aka Decision Models - 21st September 2026 - Generating running routes with GPT-6 Astra and ChatGPT Work - 12th September 2026 - OpenAI agents attacked RubyGems back in May - 12th September 2026

Items scoring 7/10 or above from 11 sources, scored by claude-haiku-4-5-20251001 on relevance to my interests. At most 3 per source.

Scoring categories & sources
  1. Local Wexford or South East Ireland news
  2. Irish or EU-wide affairs affecting citizens broadly: elections, new laws or policy being debated, cost of living, education — especially impacts on mid-life adults or teenagers. Never courts/crime stories.
  3. Irish news on a topic relevant to my interests
  4. Work and tech topics: networking, AI, Kubernetes, platforms, SaaS
  5. AI news including critical or anti-AI perspectives
  6. Gaming: PC gaming, indie gaming, retro gaming
  7. General interests: gardening, woodwork, cycling, fitness, travel
  8. Comics

Sources: Breaking News Ireland, Wexford Local, Hacker News, r/gaming, r/pcgaming, r/antiAI, r/indiegaming, Lenny's Newsletter, One Useful Thing, Newcomer, Simon Willison

Comics

Stargazing 5

XKCD · view →
The sun and the moon appear the same size in the sky, even though in real life the sun is more than twice as big. Some call this lucky alignment coincidence; others say it

The sun and the moon appear the same size in the sky, even though in real life the sun is more than twice as big. Some call this lucky alignment coincidence; others say it