daily

2026-09-16
1

Vinegar Hill visitor experience

Wexford Local · original → · 8/10 · Local Wexford: Vinegar Hill visitor experience improvements
[image →]VINEGAR HILL to get new signage and QR codes to enhance the visitor experience. (File Pic; WexfordLocal.com) By Dan Walsh at Enniscorthy Municipal District meeting Cllr Jackser Owens has…
[image →]
VINEGAR HILL to get new signage and QR codes to enhance the visitor experience. (File Pic; WexfordLocal.com)

By Dan Walsh at Enniscorthy Municipal District meeting

Cllr Jackser Owens has long championed the Vinegar Hill visitor experience. At today’s monthly meeting of Enniscorthy Municipal District Council in the Council Chamber at the Presentation Centre, he called for a visitor centre, coach access to the hill, a tea and coffee outlet, fresh water and toilet facilities.

Cathaoirleach Cllr Pat Kehoe was in the chair and there was some good news for Cllr Owens and the team when Barbara Nolan, Staff Officer deputising for District Manager Claire Lawless presented the Enniscorthy Municipal District Report.

It read; “Enniscorthy Municipal District recognises the significant historical, cultural, and tourism value of Vinegar Hill. District staff are currently progressing a number of initiatives aimed at enhancing the visitor experience and improving public understanding of the site’s historical significance.

“Work is underway on the development of new signage similar to signage installed at Oulart Hill. The signage will identify and highlight key landmarks, locations, and areas visible from the hilltop.

In addition, staff will work with The National 1798 Historical Centre Board to develop a series of QR codes that will be installed at appropriate locations throughout the site.

“These QR codes will allow visitors to access digital content through their mobile devices, providing a more interactive and engaging experience. The content will tell the story of the Battle of Vinegar Hill from a range of perspectives.

“Enniscorthy Municipal District looks forward to advancing these projects and delivering an improved visitor experience that celebrates the rich history and unique significance of Vinegar Hill.”

2

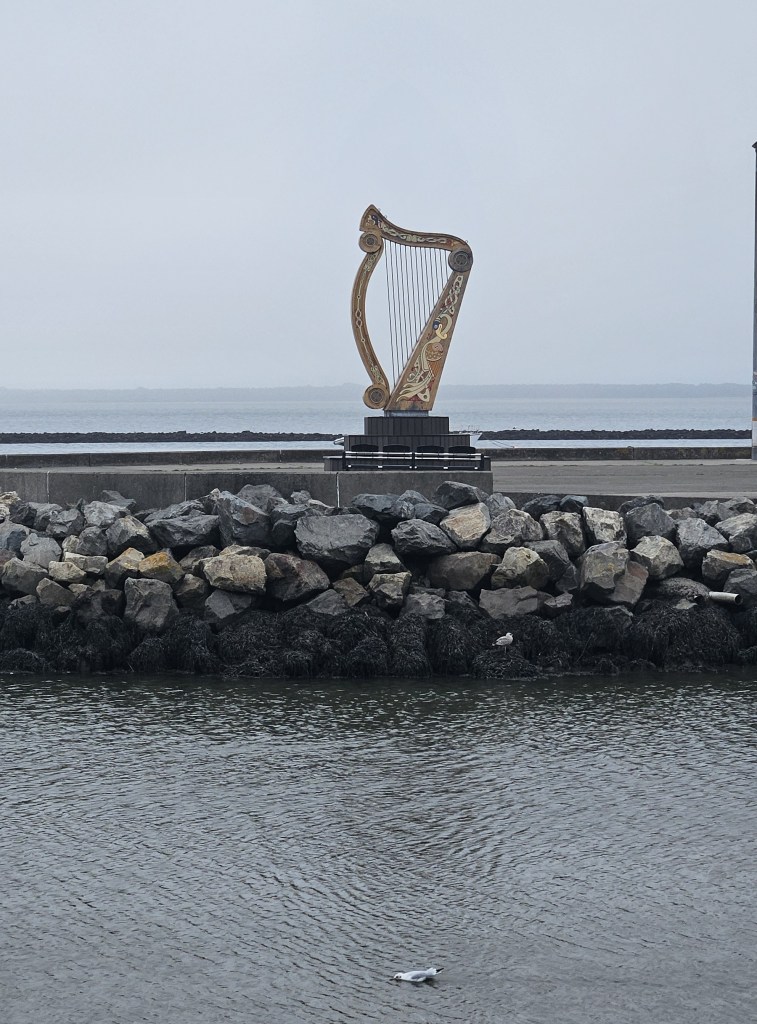
Harp is “the Eiffel Tower of Wexford”

Wexford Local · original → · 8/10 · Local Wexford: iconic Harp monument maintenance concerns
[image →]The HARP or ‘the Eiffel Tower of Wexford’. (Pic; WexfordLocal.com) By Dan Walsh at Wexford County Council meeting Cllr Catherine ‘Biddy’ Walsh raised concerns about the poor condition of…
[image →]
The HARP or ‘the Eiffel Tower of Wexford’. (Pic; WexfordLocal.com)

By Dan Walsh at Wexford County Council meeting

Cllr Catherine ‘Biddy’ Walsh raised concerns about the poor condition of the iconic Fleadh Cheoil Harp on Wexford Harbour’s breakwater at yesterday’s (Monday) monthly meeting of Wexford County Council, chaired by Cllr Lisa McDonald.

Cllr Walsh described the Harp as “the Eiffel Tower of Wexford” and said its plinth was in poor repair, calling the situation “dangerous”.

Describing the memorial as “exposed to the elements and exposed to the sea” Cllr Walsh believes it needs a permanent base, some varnish, repairs and maintenance going forward.

Chief Executive Eddie Taaffe admitted that the Harp on the breakwater was temporarily constructed, however, the Council has consulted with the people who carried out the installation and proposed a more permanent structure base.

“It is a wooden structure and will need regular maintenance,” stated Mr. Taaffe.

The giant Harp is a legacy from Fleadhanna 2024 and 2025 constructed by locals under guidance from Buí Bolg and is located on the boardwalk at Wexford Harbour.  

3

Show HN: An e-ink frame that hears birds and draws them as 1800s illustrations

Hacker News · original → · 7/10 · AI + gardening: bird detection with local AI and e-ink display
E-ink bird frame for Raspberry Pi - real-time bird detection by audio, fully local AI, rendered as real, hand-cut 1800s bird illustrations. Sorry about the dirty window - squirrels have been…

E-ink bird frame for Raspberry Pi - real-time bird detection by audio, fully local AI, rendered as real, hand-cut 1800s bird illustrations. Sorry about the dirty window - squirrels have been stealing the bird food. Note Still in early development: expect the odd bug and a few unpolished edges, with plenty more features to come. Live on fugleramme.arnegiacomo.dev running from my kitchen window and displaying the actual birds currently heard in my garden (Bergen, Norway). Hardware, install and operations docs: arnegiacomo.dev/fugleramme BirdNET-Go listens on a mic and handles the classifier. Fugleramme polls its api, matches each species to an illustration, then packs them onto a page, and redraws only when the birds change - on an Inky Impression e-ink panel, and as a web kiosk serving the same view. There's an admin page that lets you configure what to show, and automatic updates and such. If you already run BirdNET-Go, point the frame at it instead - on the same machine or anywhere else reachable from your network. Tip The e-ink panel is not required, although it's recommended for the intended experience. Without one, Fugleramme runs web-only - show the kiosk on a display over HDMI, or open it from any device on the network. A Raspberry Pi 5, an Inky Impression 13.3" (Spectra 6), a mic and an A4 frame. Full parts list, recommendations and alternatives: Hardware. Half the point of this project is showing off some amazing public-domain natural-history illustrations. Over 800 cut-outs covering more than 400 species, every one taken from a real plate and hand-curated for this project (no art is AI-generated, though some has been retouched with AI). Each detected species is matched to its illustration, background-removed, and packed onto a textured paper page with the larger birds toward the centre, sized by body mass. An empty window shows a bare perch. The plates are Scandinavian, British and central European, so the Nordics, the British Isles and Germany are best covered. Elsewhere not so much (yet). Broader European and North American coverage is in the works! See Adding artwork for manual cutout steps. | No detections | A few visitors | A full garden | |---|---|---| The look came from a WWF Verdens naturfond poster by Axel Thorenfeldt hanging on my wall, the live-frame idea from AvianVisitors that I saw on Instagram, and the detection from BirdNET-Go - I wanted a version of that poster showing the actual birds in my garden. Similar projects: - AvianVisitors - BirdNET-Pi, AI-generated illustrations and photo cutouts - inky-bird-frame - BirdNET, field-journal illustrations on an Inky panel - HABirdDashboard - BirdNET-Go, a collage card for Home Assistant - belkins-birdnet - BirdNET-Pi, AI-generated kachō-e style illustrations Fugleramme shares no code or art with them. uv sync # set up venv uv run fugleramme-fake-detector # stand-in BirdNET-Go on :8090 uv run fugleramme-dev # start service on :8080 with hot-reload The fake detector's flags, and working against a real station instead: Running it without a Pi. From the pi (assuming you have the hardware up and running): curl -fsSL https://raw.githubusercontent.com/arnegiacomo/fugleramme/main/install.sh | bash Asks where BirdNET-Go should live and which ports to use, clones the repo, installs the required deps, and starts the frame as a systemd service. NB! Will probably require a reboot on a fresh system. From a blank SD card, see the full install guide. docker run -d -p 8080:8080 -v fugleramme:/data \ -e FUGLERAMME_DETECTOR_URL=http://birdnet.local:8080 \ ghcr.io/arnegiacomo/fugleramme Or build the image from a checkout: docker build -t fugleramme . docker run --rm -p 8080:8080 -v fugleramme:/data \ -e FUGLERAMME_DETECTOR_URL=http://birdnet.local:8080 fugleramme Kiosk on :8080 , admin on :8080/admin , everything it persists in /data . On a Linux box with a USB mic, this brings up BirdNET-Go alongside it: curl -fsSL https://raw.githubusercontent.com/arnegiacomo/fugleramme/main/examples/docker-compose.yml -o docker-compose.yml docker compose up -d See Container for more info. Contributions are very welcome and encouraged - fixes, docs and artwork most of all. Thanks to everyone who has contributed so far ❤️ - Something is broken - a bug report - A question, an idea, or a frame you have built - the FAQ first, then Discussions - A fix, a doc change, or a bird you have cut - open a PR, no issue needed See Contributing for more info. - Code: MIT - see LICENSE . - Detection (BirdNET-Go, installed separately as a container): CC BY-NC-SA 4.0, non-commercial only. BirdNET model by the Cornell Lab of Ornithology and Chemnitz University of Technology, taxonomy data powered by eBird.org. - Bird images: each style folder carries its own terms and sources, and its manifest links the plate every file was cut from. classic is CC BY-SA 4.0 - seeassets/artwork/classic/ATTRIBUTION.md . - Label fonts ( assets/fonts/ ): SIL OFL 1.1 - seeassets/fonts/ATTRIBUTION.md . - Bird sizes ( assets/bird_sizes.csv ): body mass from AVONET (Tobias et al. 2022, Ecology Letters, doi:10.1111/ele.13898), CC BY 4.0. - BirdNET scientific-name aliases ( assets/birdnet_aliases.json ): OpenFauna's compiled taxonomic alias map, CC BY-SA 4.0 - seeassets/ATTRIBUTION.md . Questions and ideas about the project belong in Discussions. For anything else, you can reach me through arnegiacomo.dev. I've built a few of these frames, but I currently don't have the capacity to build them for others.

4

Recreating Voodoo Graphics and a Late-1990s Gaming PC on an FPGA

Hacker News · original → · 7/10 · Retro gaming: Voodoo Graphics FPGA emulation and 1990s gaming
Recreating Voodoo Graphics and a Late-1990s Gaming PC on an FPGA I've spent the last month adding features and improving performance in z486_MiSTer, mostly working through games from the first half…

Recreating Voodoo Graphics and a Late-1990s Gaming PC on an FPGA I've spent the last month adding features and improving performance in z486_MiSTer, mostly working through games from the first half of the 1990s. Looking a few years ahead brought me to another change I wanted to explore: the arrival of 3D graphics cards. The first one that left a strong impression on me was the Voodoo. The game was Need for Speed II SE. Smooth textures, fog, and the speed of the whole thing made it feel like a new generation of PC gaming. Could I recreate that on an FPGA now that the z486 CPU exists? The result of this detour is zSST, a SystemVerilog implementation of the 3dfx Voodoo Graphics, or SST-1. Combined with my z486 CPU and the surrounding PC hardware, it forms z486 XL: a DOS PC with Voodoo graphics running in the programmable logic of a Xilinx KV260 board. Tomb Raider now runs with its original 3dfx renderer. zSST implements most of the central Voodoo features: prepared triangles, texture filtering and mipmapping, depth and alpha tests, fog, blending, dithering, framebuffer access, and buffer swaps. It supports both the fixed-point and floating-point setup interfaces. Hardware game testing is still concentrated on Tomb Raider; broader compatibility and later Voodoo generations are work for another day. The CPU and renderer run at 100 MHz on the KV260. That board has enough logic, DSP blocks, on-chip memory, and DDR bandwidth for the combined design. The DE10-Nano does not have room for this graphics addition. The KV260 uses its onboard DDR; there is no external SDRAM module to add. Starting from the programming model Fortunately, there is plenty of material to work from. 3dfx released the Glide source in 1999, before NVIDIA acquired its core graphics assets in December 2000. The surviving Glide source and SST-1 specification explain how software prepares triangles, configures the pixel pipeline, and manages textures and framebuffers. The specification is a behavioral target, rather than a circuit diagram. It tells what should happen when software writes a register, but leaves many implementation choices open. 86Box provides useful references for complicated rendering behavior. The earlier MAME Voodoo work is another part of this preservation history. SpinalVoodoo supplied particularly useful Glide traces and reference screenshots for testing. From triangles to 3D, one pixel per clock Voodoo Graphics turns triangles into pixels, leaving much of the 3D work to the host CPU. Its command interface is surprisingly compact: five main command registers drive the accelerator. | Register | Action | |---|---| triangleCMD | Start rendering a prepared triangle. | ftriangleCMD | Start a triangle through the floating-point setup interface. | nopCMD | Flush the pipeline; optionally reset the statistics counters. | fastfillCMD | Clear a clipped rectangle of color and/or depth data. | swapbufferCMD | Switch the displayed buffer, immediately or synchronized to vertical retrace. | Both triangle commands launch the same rendering pipeline. Other registers hold coordinates, gradients, and render state, while memory-mapped regions provide texture uploads and direct framebuffer access. The main drawing primitive is simply a prepared triangle. For game developers, Glide presents a friendlier interface: void grDrawTriangle(const GrVertex *a, const GrVertex *b, const GrVertex *c); Before this call, the host CPU transforms the 3D geometry, computes vertex lighting, clips it, and projects it onto the screen. Glide then prepares the screen-space triangle and its parameter gradients—the increments used to interpolate values across its surface—and writes the triangle command to start rendering. Unlike later GPUs such as the GeForce 256, SST-1 has no hardware transform-and-lighting engine. That still leaves plenty of work for the accelerator. The rasterizer finds which pixel centers lie inside the triangle and interpolates their color, depth, and texture coordinates. The texture unit fetches and filters texels; the framebuffer unit combines colors, applies visibility tests and fog, blends with the existing image, and writes the result. The original card divides this work between two ASICs: the FBI, or Frame Buffer Interface, and TREX, the texture mapping unit, usually called the TMU. At a 50 MHz graphics clock, the advertised peak is one textured, depth-tested output pixel per clock: 50 million pixels per second. One pixel per clock does not mean that a pixel finishes in one clock. It means that different stages can work on different pixels simultaneously: while one pixel is being textured, an earlier one can be blended and another written out. Once the pipeline is full, it can ideally accept and finish a pixel every clock, provided memory keeps up. That is the appeal of a fixed-function pipeline. A software renderer executes many instructions for each pixel; dedicated hardware overlaps that work across a steady stream of pixels. Voodoo brought richly textured 3D games to life at a fluid 30 FPS or more—a big part of what made it so popular. Building the pixel pipeline Compared with an x86 CPU, the arithmetic path is pleasantly regular. Let's follow a pixel from its interpolated parameters through texturing and color operations to the framebuffer, starting with how the numbers are represented. Fixed point behind a floating-point interface Floating-point arithmetic is central to modern GPU programming. SST-1 sits at an interesting transition: software can submit floating-point values, but the rendering machinery largely operates in fixed point—integers with an implicit scale factor. | Setup value | Fixed-point register format | |---|---| | Screen X and Y | 12.4 | | Red, green, blue, alpha | 12.12 | | Depth Z | 20.12 | | Texture S/W and T/W | 14.18 | | Reciprocal W | 2.30 | Here 12.4 means twelve bits before the binary point, including the sign, and four fractional bits. A screen coordinate of 10.5 is therefore stored as the integer 168: multiply by 16 to encode it, divide by 16 to recover the value. Those fractional bits let the rasterizer handle vertices between pixel centers. The fvertex , fstart , and floating-point gradient registers accept IEEE single-precision values. SST-1 converts them into its internal fixed-point representation, and zSST follows that contract. Once the triangle is prepared, advancing along a scanline mostly means adding a precomputed increment to each interpolated parameter. Much of the pixel-by-pixel work becomes simple integer addition. Four texels for one pixel For perspective-correct texturing, the TMU interpolates S/W, T/W, and 1/W, then divides the first two by the third to recover texture coordinates. This keeps a floor or wall texture in perspective as the surface recedes. The TMU also selects a mip level: a smaller version of the texture for pixels that cover a larger area of its surface. This reduces aliasing and shimmering in the distance. Bilinear filtering then combines four neighboring texels—the pixels of the texture—around the sample position. First blend the top pair horizontally, then the bottom pair, and finally blend vertically between those two results. The fractional position determines the weights, producing a smooth transition between texel colors instead of an abrupt jump from one to the next. In zSST, a four-stage front end pipelines the perspective and level-of-detail calculations. Address generation and cache lookup supply the texels, and two registered decode stages turn their stored formats into colors for filtering and texture combining. Palette-based and NCC-encoded textures need different decoding rules, but ultimately feed the same pixel stream. Color, tests, fog, and blending Once texture and framebuffer data are available, zSST's FBI pixel path uses six registered stages: | Stage | Main work | |---|---| | F0 | Select sources, check chroma key, prepare Z/W depth values. | | F1 | Apply the color and alpha combine functions. | | F2a | Test alpha/depth and look up the fog factor. | | F2b | Apply fog. | | F3 | Reconstruct destination color and perform alpha blending. | | F4 | Convert to framebuffer precision, dither, and apply write masks. | These stage boundaries are chosen to meet the FPGA's clock target. The SST-1 specification describes the operations but does not reveal the original ASIC's exact pipeline registers. Splitting fog lookup from fog application, for example, keeps a long arithmetic path out of a single clock while retaining the ability to accept one pixel per clock. The result is written to the back buffer. A retrace-synchronized buffer swap then displays the finished image without switching buffers halfway through scanout. The original Voodoo was a 3D-only add-on, passing the ordinary VGA card's output through when inactive. z486 XL makes the analogous selection between the PC's VGA output and zSST's display output inside the FPGA system. The hard part: feeding it from memory The zSST pixel pipeline proved relatively straightforward to implement, at least compared with z486's CPU pipelines. Keeping it fed turned out to be much harder. A bilinear sample needs four texels from separate addresses. A depth-tested, blended pixel also needs the existing depth and color, followed by writes of the new values. Performing those accesses one at a time quickly destroys throughput. I ended up spending more time designing, tuning, and debugging the memory system than the arithmetic pipeline. How the original card supplied the pixels The division of labor is visible on this Diamond Monster 3D. The upper 3dfx chip is the TMU, the lower one the FBI, each with four EDO RAM chips to its right. The upper group holds textures; the lower group holds color and depth/alpha buffers. FBI and TMU each have a dedicated 64-bit memory path. On the texture side, four-way interleaving lets the banks read independent addresses, supplying the four neighbors for bilinear filtering in parallel. The specification (p. 13) promises the same throughput as point sampling, without storing duplicate texels. But what if two neighboring texels land in the same chip? The trick is to distribute texels in a repeating two-dimensional pattern, rather than split the image into four large regions. Assign a bank to each combination of even or odd column and row, and the reason becomes clear: Every 2×2 window contains A, B, C, and D—even the orange window crossing both horizontal and vertical block boundaries. Two consecutive columns have opposite parity, as do two consecutive rows. All four combinations occur exactly once, so each bank supplies one texel with no conflict. Texture edges and small mip levels need a little more care. SST-1 uses power-of-two texture dimensions, so wrapping preserves the alternating pattern for dimensions of two or more. At clamped edges, or in mip levels only one texel wide or high, some samples reuse the same texel. The central insight remains: fast bilinear filtering depends on arranging memory so that the arithmetic receives all its inputs together. The FBI applies a similar idea to color and depth/alpha memory. Its interleaved path supports a peak of one rendered pixel per clock, or two pixels per clock for clears. Working on adjacent pixels together spreads the read/write cost across a scanline. Fabien Sanglard's two-pixel explanation offers a useful reconstruction of this behavior, though the exact ASIC bank schedule is not documented in the programming guide. At 50 MHz, each 64-bit path has a theoretical bandwidth of 400 MB/s: 800 MB/s in total, but reserved for different jobs. The TMU cannot borrow idle FBI bandwidth, or vice versa. These dedicated buses and carefully arranged banks remind me of the NES- and SNES-era designs I explored in projects such as SNESTang: getting the most out of memory means designing around exactly when and where each value is needed. What changes on an FPGA SoC Voodoo's memory layout explains how it kept the pipeline busy, but I cannot simply transplant that design to the KV260. The board has much more memory bandwidth, yet no dedicated EDO memory attached to either rendering unit. Instead, the FPGA accesses shared DDR through the Zynq processing system's AXI ports. Linux, the FPGA PC, and display scanout all compete for that memory. The goal is the same—keep the pixel pipeline fed—but the way to achieve it has to change. Our KV260 measurements show why bandwidth alone is not enough. A 128-bit port at 100 MHz has a theoretical bandwidth of 1.6 GB/s. With one request outstanding, a 4 KiB read reaches 1,370 MiB/s, but a 64-byte read reaches only 189 MiB/s. The first data typically takes about 280 ns to arrive—roughly 28 clocks at 100 MHz—with occasional much longer waits. A renderer that waits for each small read before issuing the next will spend most of its time idle. zSST needs enough independent work in flight to cover those waits. Caches, replay, and a reorder buffer Keeping the pipeline fed requires both fewer DDR accesses and less time spent waiting for them. The first step is caching. Nearby screen pixels often sample overlapping parts of a texture, so recently fetched texels can be reused from on-chip RAM. zSST's texture cache holds 8 KiB in 64-byte lines; each fetch also brings in neighboring texels that subsequent pixels are likely to need. A cache miss still takes many clocks, but independent texture samples need not wait for it. zSST keeps up to eight cache-line fetches outstanding, using a replay queue to park samples with missing data and retry them when it arrives. Meanwhile, samples whose texels are already cached can proceed. Prefetching gets a head start on future reads. Now a later cache hit can finish before an earlier miss. A 64-entry reorder buffer, or ROB, collects those results and releases them in their original order. The principle is familiar from CPUs: do useful work during a long wait, then restore order before passing the results downstream. The framebuffer side uses separate 4 KiB color and depth/alpha read caches, while write combiners pack neighboring 16-bit updates into 128-bit requests. Here, ordering matters: blending or depth testing may need a value that an earlier pixel has changed but not yet written to DDR. Forwarding supplies the pending value directly. Framebuffer updates take effect in order, and state changes that require completed work wait for it to drain. Memory requests can overlap, but later pixels must still see the effects of earlier ones. FBI and TMU share the renderer's 128-bit AXI port, HP2. The PC uses HP0 and display scanout uses HP3, keeping their request queues separate even though all three ultimately share DDR. Evaluation results I measure the renderer separately from the complete PC. The simulation benchmark sends commands through zSST's front end and exercises the TMU, FBI, shared arbiter, and a DDR timing model. Read data arrives after at least 26 clocks, with deterministic variation and occasional longer delays; writes are also rate-limited. The full-renderer tests allow 32 outstanding reads. At 100 MHz, zSST reaches 78.5 million pixels per second (MPix/s) for textured triangles, and 72.8 MPix/s with depth testing and blending. Voodoo 1's published estimates at its native 50 MHz are 43 and 37 MPix/s for comparable feature sets. This is not an apples-to-apples benchmark: the triangle workloads differ, and the original estimates also include fog, mipmapping, and Gouraud shading. I do not have a Voodoo 1 to run the same test on both. The comparison shows the approximate fill-rate range, not a measured speedup over the original card. High fill rates do not automatically translate into high game FPS. On the board, Tomb Raider Level 2 produced 237 displayed buffer swaps in about 20 seconds—roughly 12 per second, measured from swaps rather than an engine FPS counter. Preliminary measurements point to a CPU bottleneck: it still has to run the game, prepare geometry, and submit commands. Shared DDR contention may also contribute. There is plenty left to optimize in the complete machine. For non-Voodoo games, the current 100 MHz z486 XL runs maximum-detail Doom at 38.5 FPS and Quake 1.06 at 8.1 FPS. That is roughly 20% faster than the 85 MHz DE10-Nano build—about 23% for Doom and 19% for Quake. A 512 KiB write-back L2 cache in UltraRAM helps the CPU make better use of DDR. In the integrated XCK26 build, zSST accounts for about 29,500 LUTs, 28,100 flip-flops, 14 RAMB36 blocks, 8 RAMB18 blocks, and 97 DSP slices. The combined PC and graphics design meets timing at 100 MHz. Closing The rewarding part is seeing original Glide software drive hardware I built in RTL. I expected the rendering arithmetic to be the hard part; getting data to it efficiently took more work. Voodoo's carefully interleaved EDO and zSST's caches and queues solve the same problem under very different constraints: a fast pixel pipeline is only useful when it has something to do. Both zSST and z486 XL are available open source. If you already have a KV260, the z486 XL SD image provides the Linux support and application needed to launch your own DOS disk images. Credits: Thanks to SpinalVoodoo for the Glide traces and reference screenshots, and to 86Box for its implementation references. Fabien Sanglard's The story of the 3dfx Voodoo1 is an excellent introduction to the original card's memory system. Comments

5

Why I'm still bearish on LLMs after Navier-Stokes

Hacker News · original → · 7/10 · AI: critical perspective on LLM limitations and automation
why i'm still bearish on LLMs after navier-stokes [thank you to claude fable 5.1, holden saberhagen, gabriel kammer, andres erbsen, alice mckean, and tristan wylde-larue for comments on this post]…

why i'm still bearish on LLMs after navier-stokes [thank you to claude fable 5.1, holden saberhagen, gabriel kammer, andres erbsen, alice mckean, and tristan wylde-larue for comments on this post] i'll begin with a few theses for the reader to chew on: - the frontier labs are priced according to the narrative that they have produced or will in the very near future produce a fully automated drop-in replacement for most knowledge workers, but current frontier models need laborious oversight and guardrails on even the simplest tasks. one misled by the headline shows of force (navier-stokes, freebsd RCEs, the huggingface incident) and frontier lab rhetoric into believing meaningful autonomy has been achieved need only look at the software firms continuing to employ and hire bottom quartile software engineers who would score far below the models they supervise on the benchmarks du jour. - the models generalize well only on tasks within a small neighborhood of the specific tasks they've been trained on, and even then with severe caveats. the frontier labs have developed a general recipe to teach models almost any specific task enjoying clearly defined levels of task performance; many tasks are covered in the training data; but even small perturbations within a covered class of task result in outright failure or reward hacking. - the present problem of reward hacking can be solved only by rigorous specification by domain experts. the time of domain experts is expensive. rigorous specification is itself a skill, demanding its own expertise outside of a given problem domain. even many skilled software engineers are bad at it. for the vast majority of domains, the intersection of domain experts and specification experts is ludicrously small. - the labor costs of rigorous specification can greatly exceed that of direct implementation of an informal specification. the hardware engineering world presents a great case study on this, where a typical CPU project anecdotally has about three times as many specification and validation engineers as design engineers and a 5:1 ratio is not unheard of. even worse, many tasks don't admit a convenient spec-and-forget regime where you write a specification once and continuously implement against it: rigorous formal specifications frequently evolve in conversation with insights derived from discoveries made while implementing according to the informal specification. for tasks that enjoy high level one-and-done specifications (say an executable ISA specification for a family of CPU architectures) the costs of verification against such high level specifications are insurmountable with current technology, necessitating the use of lower level specifications that are both more expensive to construct and far more fragile to design flux. - navier-stokes and statements in pure mathematics like it are the absolute best case scenario for agentic work against rigorous specification. the theorem statement itself is already a rigorous specification. it has undergone decades of auditing by the mathematical community and its rendering in lean is a straightforward translation defined in terms of battle-tested mathematical objects from mathlib. the verifier, the lean theorem prover, has been extensively audited and specifically designed to avoid the types of unsoundness that would make it vulnerable to reward hacks. even lean and theorem provers like it are not invulnerable: soundness bugs have allowed LLMs to launder bogus proofs through the proof kernel before and it is not improbable that more such bugs exist. this is the rosiest setup; the vast majority of human knowledge work does not look like this. i'll comment below on the few areas of knowledge work that do resemble pure mathematics in this respect. - the best alternative to rigorous specification is human review. human review doesn't scale well to the volumes of output produced by language models. to make matters worse, even expert human review is extremely vulnerable to reward hacking: consider the xz backdoor and the infamous UMN hypocrite commits that landed in linux. if human review remains a critical part of the agentic production loop, the pace of production is necessarily bottlenecked by factors like the limits of human time and attention; it is a total non-starter for the country full of geniuses in a datacenter frontier lab CEOs would have you believe is perpetually just a few more months out. taken together, it appears that for most domains LLMs will continue to look like a cracked intern: quick and effective in the hands of an adult but not given run of the place. most firms will not be able to adopt fully autonomous AI, not for problems of skill issue or lagging technology diffusion but rather for structural reasons seemingly endemic to current architectures. the classes of firms that can accept the use of fully autonomous LLMs are few, by my count just three: - those who can accept failure cheaply: firms that would otherwise hire interns, firms involved in rapid prototyping work, etc. - those who need done a small set of narrowly defined tasks with existing clear guardrails: repetitive physical labor in a controlled environment, call center and customer service chat work, etc. - those that can accept or already do by nature the costs of rigorous specification and validation: chip design, drug discovery, and other domains where failure on deployment is an existential concern. the first two classes are price sensitive and arguably don't need the jump in reasoning quality you see going from cheap to frontier models. most of these firms will be best served by open models running on cheap hardware, perhaps even locally at the site of use. for the first and third classes, the type of fuzzy combinatorial search that has produced headline results in mathematics and security research seems more sensitive to agentic swarm width than reasoning capacity: see small open models reproducing the mythos CVEs that drove the spring 2026 hype cycle. if that is indeed true, there is even greater reason to use cheap open models that enable you to run the same workload with wider swarms. the third class of firms might still use frontier models, though it's not totally clear that their work couldn't be done with cheap models like deepseek v4.1 flash, and the swarm width advantage i hypothesized above gives them all the more reason to push for cheaper models. another interesting property of firms of this class is that they are generally very secretive about their IP and probably aren't overjoyed about shipping it all to anthropic and openai even with supposed agreements to not train on user data. now, you might propose that even if the frontier labs are cooked, the data center full of brainlets scenario drives just as much AI compute as an artificial superintelligence scenario. the difference is that the data center full of geniuses is self-driving and limited only by how much compute it can consume while the brainlet swarms will be heavily bottlenecked by their human orchestrators. my personal bet is that the blast radius will go far beyond the frontier labs.

6

Appreciation post for everyone who has made emulation possible

r/gaming · original → · 7/10 · Retro gaming: appreciation for emulation community efforts
[image →] A genuine thank you to everyone who has contributed in any way to making emulation of consoles possible across different platforms be it Android, iOS, macOS, Windows, Linux or something…
[image →]

A genuine thank you to everyone who has contributed in any way to making emulation of consoles possible across different platforms be it Android, iOS, macOS, Windows, Linux or something esle.

Thank you to everyone who had to take apart machines, read thousands of pages of architecture documentation, understand hardware that wasn't fully documented, figure out the countless architectures of different SoCs, CPUs, and GPUs, write emulators for them, test them, break them, fix them, and then keep doing it for years driven purely by enthusiasm. Thank you to everyone who, despite lawsuits and legal obstacles, kept going and fighting for your rights until the very end.

And it isn't just the people whose names appear on a project's page. It's everyone who contributed code, research, testing, documentation, bug reports, reverse engineering, tools, discussions, or even some obscure piece of information that helped make an emulator better.

So everyone who has played even a small part in the world of emulation:

Thank you.

submitted by /u/sxydoctor
[link] [comments]
7

Gemini Live audio

Simon Willison · original → · 7/10 · AI: Gemini Live speech models and voice interaction UI
15th September 2026 Google released Gemini 3.8 Live and 3.8 Live Extended Thinking today - two new speech-to-speech models that are a similar shape to OpenAI's GPT-Live family. I pointed GPT-6 Astra…

15th September 2026 Google released Gemini 3.8 Live and 3.8 Live Extended Thinking today - two new speech-to-speech models that are a similar shape to OpenAI's GPT-Live family. I pointed GPT-6 Astra Extra High at the documentation and had it build me this web UI for trying out the new models. You can select a model and voice preset, enter an optional system prompt and then start a voice conversation through your browser, including the ability to interrupt the model while it is talking. The implementation uses no libraries. It connects to the wss://generativelanguage.googleapis.com/ws/google.ai.generativelanguage.v1alpha.GenerativeService.BidiGenerateContent?key=... WebSocket endpoint and uses a Web Audio API AudioContext for both capture and playback. Here's the Gemini Live tutorial for getting started with that WebSockets API. Recent articles - Generating running routes with GPT-6 Astra and ChatGPT Work - 12th September 2026 - OpenAI agents attacked RubyGems back in May - 12th September 2026 - Some thoughts on the Navier–Stokes Millennium Prize Problem - 8th September 2026

Items scoring 7/10 or above from 11 sources, scored by claude-haiku-4-5-20251001 on relevance to my interests. At most 3 per source.

Scoring categories & sources
  1. Local Wexford or South East Ireland news
  2. Irish or EU-wide affairs affecting citizens broadly: elections, new laws or policy being debated, cost of living, education — especially impacts on mid-life adults or teenagers. Never courts/crime stories.
  3. Irish news on a topic relevant to my interests
  4. Work and tech topics: networking, AI, Kubernetes, platforms, SaaS
  5. AI news including critical or anti-AI perspectives
  6. Gaming: PC gaming, indie gaming, retro gaming
  7. General interests: gardening, woodwork, cycling, fitness, travel
  8. Comics

Sources: Breaking News Ireland, Wexford Local, Hacker News, r/gaming, r/pcgaming, r/antiAI, r/indiegaming, Lenny's Newsletter, One Useful Thing, Newcomer, Simon Willison