daily

2026-09-03
1

Cllr Sheehan joins Independent Ireland

Wexford Local · original → · 8/10 · Local Wexford: councillor party change, local government representation
[image →]CLLR MICHAEL SHEEHAN joins Independent Ireland Party. (File Pic; WexfordLocal.com) By Dan Walsh A former Fianna Fáil Cathaoirleach of Wexford County Council has joined the Independent…
[image →]
CLLR MICHAEL SHEEHAN joins Independent Ireland Party. (File Pic; WexfordLocal.com)

By Dan Walsh

A former Fianna Fáil Cathaoirleach of Wexford County Council has joined the Independent Ireland Party, increasing the fledgling party’s nationwide local government representation to 26 councillors.

Michael Sheehan served as a Fianna Fáil Councillor for New Ross from 1999 to 2024, before leaving the party prior to the 2024 General Election.

The New Ross man is to be appointed as Independent Ireland’s spokesperson on Finance and Enterprise.

Cllr Sheehan was one of four candidates for Fianna Fáil in Wexford in the 2020 General Election when he accrued 5.8% of first preferences, 4,366 votes.

In the most recent General Election, he received 1,623 first-preference votes, or 3.1% of the total, as an Independent candidate.

He criticised Fianna Fáil for fielding retired international soccer referee Michelle O’Neill alongside Housing Minister James Browne. Mr Browne was elected, while Ms O’Neill received 296 votes.

“My decision has not been taken lightly, but I believe now is the right time to join Independent Ireland. People are increasingly frustrated with politics and want representatives who will listen and, importantly, deliver,” said Cllr Sheehan.

Fianna Fáil has struggled in Wexford. A few months ago outgoing Cathaoirleach of Wexford County Council Cllr Joe Sullivan from Gorey Kilmuckridge District resigned from the party.

2

Fable 5.1 World Modeling

Hacker News · original → · 8/10 · AI: Claude Fable 5.1 world modeling with autonomous agents, work-relevant
Worlds via code. Explorable, browser-native reconstructions of real places — researched, modelled, and quality-checked end to end by autonomous Claude Fable 5.1 agent swarms, then shipped as plain…

Worlds via code. Explorable, browser-native reconstructions of real places — researched, modelled, and quality-checked end to end by autonomous Claude Fable 5.1 agent swarms, then shipped as plain Three.js apps you can run with npm run dev . No game engine. No proprietary 3D tiles. Every building, storefront, sign, tree and traffic light is generated from open data and public reference imagery by code that lives in this repo. ▶ Watch the full 59-second walkthrough · 1920×1080 · aerial, plaza, Nintendo, lower level, Apple The square and its surrounding blocks — Powell, Geary, Post and Stockton — on real terrain and a real street grid, with 129 identified storefronts, working traffic lights and cable cars, day/sunset/night, and two explorable interiors: Apple Union Square (300 Post St) and Nintendo SAN FRANCISCO (331 Powell St). | Run it | cd union-square-sf && npm install && npm run dev | | Buildings | 453 OSM footprints · 75 hand-authored façades · 129 named storefronts | | Life | 220 pedestrians on a 1,398-node nav graph · 109 vehicles incl. Powell St cable cars | | Interiors | Apple + Nintendo, 23 interactive objects | | Validation | 34 camera-matched viewpoints vs. real photographs · 147 comparison sheets · 9 independent reviewer reports | ▶ Watch the full 54-second walkthrough · 1920×1080 · seven scenes — over the roofs, the Shirakawa, Yasaka Shrine, the weeping cherry, the Yasaka Pagoda, Sannenzaka, and Kiyomizu-dera at sunset Kyoto's Southern Higashiyama walking route — Gion → Hanamikoji → Yasaka Shrine → Nene-no-michi → the Yasaka Pagoda → Ninenzaka → Sannenzaka → Kiyomizu-zaka → Kiyomizu-dera — 2.3 km of it, continuously walkable, climbing 76 m from the ochaya on Hanamikoji to the temple stage. Rendered 3D-to-2D as a hand-painted anime background: cel materials with hue-shifted shadow bands, screen-space ink taken from a second difference of depth, and a split-tone grade. No binary assets at all — every sign, noren, lantern, roof tile and paving stone is drawn with Canvas2D at start-up. | Run it | cd kyoto-higashiyama && npm install && npm run dev | | Or, with nothing installed | npm run viewer && open viewer/higashiyama.html — one self-contained HTML file | | Buildings | 266 buildings · 471 shopfronts · 19 hero landmarks across 15 districts | | Detail | 1,938 trees (11 species) · 3,076 props (60 kinds) · 142 interactions | | Survey | Every elevation an independent GSI 1 m LiDAR query; street widths ray-cast to OSM footprints every 8 m | | Validation | 52 authored viewpoints · full-route player walkthrough · per-street passability sweep · zero page errors | Six widely-repeated figures were overturned by the survey and the world is built on the measured ones — the Yasaka Pagoda is 38.79 m, not 46, with a convex taper; the Kiyomizu stage deck is at 115.5 m ASL, not 240; the stage is 21.8 × 9.6 m on 168 pillars of 0.64 m diameter, not 18 × 10 m on 139 pillars of 2 m. More worlds coming. Each world follows the same pipeline, and every stage is in the repo so you can re-run it: - Reconnaissance — parallel research agents pull OpenStreetMap geometry, USGS elevation, transit and street specs, and a storefront census with per-fact sources and confidence levels. - Offline asset generation — Blender-as-a-library ( bpy ) scripts emit optimised GLB kits: façade modules, street furniture, vehicles, vegetation, retail fixtures, pedestrian body parts. - Runtime — a pure Three.js app assembles terrain, streets, façades, props, crowds and traffic from JSON specs. - Camera-match QA — Playwright drives the real app, screenshots fixed viewpoints, and diffs them against free-licensed photographs taken from the same spot; independent reviewer agents (architect, geographer, technical artist, interaction) file reports that drive the next fix cycle. Code and generated assets: MIT. Geometry is derived from OpenStreetMap (ODbL) and USGS 3DEP (public domain). Reference photographs are not redistributed here — their provenance is recorded per sector in each world's refs/*/SOURCES.md . Brand names and logos identify the real businesses at their real locations and belong to their owners.

3

Grok Bot vs. OpenClaw: How I replaced my entire agent stack

Lenny's Newsletter · original → · 8/10 · AI/Work: agent stack comparison and personal AI workflow, work-relevant
I’m running about 30 active agents at any given moment, and in this episode I break down my full Grok Bot setup: what it is, how it compares to OpenClaw, and the nine bots I’ve built for work and my…

I’m running about 30 active agents at any given moment, and in this episode I break down my full Grok Bot setup: what it is, how it compares to OpenClaw, and the nine bots I’ve built for work and my personal life. We go deep on Chief (my chief-of-staff bot sweeping six inboxes and multiple Slack workspaces), TradBot (the family agent that prints a kitchen-table newspaper for my kids), two engineering bots handling my PR queue and SOC 2 compliance monitoring, Holly Helpdesk, and a handful of personal bots I didn’t expect to actually love. I also walk through how I migrated everything from OpenClaw, including the script I used to export and transplant each agent’s identity and schedule.

Listen or watch on YouTube, Spotify, or Apple Podcasts

What you’ll learn:

  1. The three primitives Grok Bot is built on, and why one of them changes what agents can actually do

  2. How Chief, my general-purpose chief of staff, handles a scope I didn’t think a single bot could manage

  3. The writing quirk I noticed immediately with the Grok model, and what I did about it before letting it near my inbox

  4. Why I created a family agent, what it produces every morning, and the design principle I used that has nothing to do with a screen

  5. The two engineering bots doing work I used to do myself, and how one of them handles compliance in a way that surprised me

  6. How Holly Helpdesk started getting five-star reviews from customers who had no idea they were talking to a bot

  7. The personal bots I built mostly on a whim, and the one I now look forward to every Monday morning


Brought to you by:

WorkOS—Make your app enterprise-ready, with SSO, SCIM, RBAC, and more

Hyperagent—Deploy fleets of agents that handle real work

In this episode, we cover:

(00:00) Why I migrated from OpenClaw to Grok Bot

(02:10) Grok Bot overview: the three core primitives

(07:41) Chief: my chief-of-staff bot

(11:51) OpenClaw vs. Grok Bot

(12:41) TradBot: my family agent

(19:51) LGTM the PR Closer

(22:03) Lockdown: SOC 2 control monitoring bot

(24:00) Holly Helpdesk: customer support

(26:58) Penny Pincher: subscription audit, insurance negotiation, Rolex shopping

(29:37) ShopZilla and Sylvie Style: personal shopping and wardrobe bots

(32:54) How to migrate your OpenClaws

(34:26) Final take

Tools referenced:

• Grok Bot (SpaceXAI multi-agent platform): https://x.ai/news/introducing-grok-bot

• OpenClaw (previous agent platform): https://openclaw.ai/

Where to find Claire Vo:

ChatPRD: https://www.chatprd.ai/

Website: https://clairevo.com/

LinkedIn: https://www.linkedin.com/in/clairevo/

X: https://x.com/clairevo

Production and marketing by https://penname.co/. For inquiries about sponsoring the podcast, email jordan@penname.co.

4

Homeless charity moved 900 people back into community from temporary accommodation

Breaking News Ireland · original → · 7/10 · Irish policy: homelessness crisis and housing policy affecting citizens
The CEO of the charity Depaul has spoken of the importance of early intervention in helping people avoid entering homelessness. Speaking in advance of the public of the Depaul 2025 Impact Report,…

The CEO of the charity Depaul has spoken of the importance of early intervention in helping people avoid entering homelessness. Speaking in advance of the public of the Depaul 2025 Impact Report, David Carroll told RTÉ radio’s Morning Ireland that in the midst of a housing crisis, Depaul had managed to move 900 people back into the community from temporary accommodation. People were under incredible pressure from a cost-of-living point of view, he added. “We’ve seen the figures rise really since 2018-2019 to a situation now where we have 17,500 people in temporary accommodation, and what we want to make sure on the back of the publication of this report is that we don’t accept those figures as the new normal. “We now have to put in specific interventions and emergency interventions in order to be able to tackle this issue and make sure that we don’t accept the figures that we have at the moment.” Early intervention, he explained, would mean working with people within communities before they enter temporary accommodation. “We can find the signals of deteriorating tendencies on the back of maybe rental issues, antisocial behaviour, drug and alcohol difficulties and supporting people within community settings is really important. “The Housing First programme that we deliver now in Dublin is a prime example of where that can occur where complex people with complex needs, drug and alcohol needs are supported intensively in order to be able to support themselves and put roots in their communities.” DePaul will be providing up to 420 tenancy supports for Housing First by the end of 2029, which is really good news for us. Carroll said the forthcoming budget needed to contain a concrete plan on how to exit from the reliance on temporary accommodation. “That means setting key targets with regards to particularly the amount of children that we want to get out of homelessness. The other big piece for us is around mental health. “We’re seeing an emergency, a mental health crisis with people in temporary accommodation. We need an increase in the amount of HSE funding that’s going to support people with mental health challenges both within the community but also within temporary accommodation as well.” -ends-

5

Gemini 3.8 Flash and 3.8 Flash Cyber

Hacker News · original → · 7/10 · AI: Gemini 3.8 reasoning and coding improvements, work-relevant
Introducing Gemini 3.8 Flash and 3.8 Flash Cyber Building on the momentum of 3.7 Flash from three weeks ago and marking our third Flash release in only six weeks, today we’re introducing Gemini 3.8,…

Introducing Gemini 3.8 Flash and 3.8 Flash Cyber Building on the momentum of 3.7 Flash from three weeks ago and marking our third Flash release in only six weeks, today we’re introducing Gemini 3.8, our best reasoning & coding model yet, at the same speed and low cost of 3.7. Gemini 3.8 introduces 2 variants: - Gemini 3.8 Flash: our most intelligent workhorse model, delivering significant improvements from 3.7 Flash across software engineering, agentic tasks, and critical, multi-step reasoning in specialized domains. It is available at the same introductory price 1 as 3.7 Flash at $0.75 per million input tokens and $3.75 per million output tokens. - Gemini 3.8 Flash Cyber: our most capable cybersecurity model with frontier-level performance in vulnerability detection and automated patching, available to trusted defenders through our new Fairwind Program. While tailored for different deployment environments, both of today's releases are powered by the same foundational intelligence, and further accelerated by long-running agentic loops designed to recursively evaluate and refine the underlying models. The significant coding and reasoning gains across this shared core were driven by a number of innovations, including rigorous training in the highly demanding domain of cybersecurity. Gemini 3.8 Flash: built for long-horizon coding and autonomous agents Gemini 3.8 Flash delivers substantial gains from 3.7 Flash, often approaching the performance of higher-cost frontier models. On DeepSWE v1.1 (Long-Horizon Software Engineering) 3.8 Flash outperforms most larger frontier models in autonomously solving complex engineering problems end to end, only at a fraction of the cost. Additionally, 3.8 Flash exhibits the dependability required for critical enterprise autonomy, across specialized knowledge domains. In quantitative and professional fields that require advanced analysis and reporting, 3.8 Flash outperforms 3.7 Flash and other frontier models in benchmarks like Vals Finance Agent V2 and Harvey's Legal Agent Benchmark. 3.8 Flash also achieves a 54.9% on HLE-Verified, demonstrating its ability to handle multi-step reasoning across STEM, humanities, and professional fields. These performance gains stem from a core design choice: 3.8 Flash works harder. On complex tasks, it exhibits greater diligence — executing extra reasoning steps, and calling tools iteratively. At times, the model might use more tokens to maximize performance, especially at higher effort levels. For applications where compute efficiency is the primary constraint, developers can utilize lower effort levels to minimize token overhead or continue to rely on Gemini 3.7 Flash, which remains fully supported for efficiency-first workloads. Gemini 3.8 Flash Cyber: expert cyber performance Gemini 3.8 Flash Cyber, available to a set of trusted defenders via the Fairwind Program, provides a decisive advantage in today’s complex cybersecurity landscape, with the Flash speed and cost that enables quick iteration. Autonomous vulnerability discovery On the standard industry benchmark for finding vulnerabilities, CyberGym, Gemini 3.8 Flash Cyber demonstrates frontier-level performance in autonomous vulnerability discovery. It surpasses both 3.5 Flash Cyber as well as significantly larger frontier models. To better capture real-world defensive needs which are not limited to just C/C++ codebases like in CyberGym, we also evaluated Gemini 3.8 Flash Cyber against a comprehensive internal benchmark in which the model has to discover a wide range of vulnerabilities across complex codebases spanning 20 programming languages. Here, the model showcases an impressive leap over our previous models and reaches a success rate exceeding 70%. Automated patching With Gemini 3.8 Flash Cyber, we focused specifically on equipping defenders with expert capabilities that give them an advantage over attackers. This is why we have invested in vulnerability fixing from the start, and prioritized it over offensive capabilities like exploitation. CWE-Bench, run by Collinear, is a challenging external benchmark for patching capabilities. On this benchmark, Gemini 3.8 Flash Cyber is on the Pareto frontier: with a pass@1 of 47.2% compared to a leading frontier model at 47.8%, yet offered at a significantly lower cost. Real-world impact: securing Google’s code We’re already using Gemini 3.8 Flash Cyber to secure code across Google. For example: - The Chrome Security team found that 3.8 Flash Cyber produced 2.6 times more correct patches to vulnerabilities in Chrome than the best commercial models that are much larger. - Wiz found that Gemini 3.8 Flash Cyber achieves +7.5-9.7% higher recall on their internal penetration testing benchmark for a 2.3-5.2x lower cost compared to other leading frontier models. - Google’s Cloud Vulnerability Research team leveraged the 3.8 Flash Cyber model to find a critical foundational vulnerability in less than 2 hours, a vulnerability for which research and discovery usually takes months. What our Fairwind Program partners are saying Built with safety in mind 3.8 Flash ships with safeguards against misuse in the domains of Chemical, Biological, Radiological, and Nuclear (CBRN) and cyber offense, while enabling beneficial use cases, as per our Frontier Safety Framework. 3.8 Flash Cyber ships with a more permissive set of mitigations for cybersecurity, and as such, is only available to trusted defenders who require a more comprehensive set of cyber capabilities. Gemini 3.8 models have also made a significant leap in prompt injection robustness as measured by Gray Swan, protecting Gemini model users from prompt-injection related malicious attacks. Gemini 3.8 Flash and Cyber: get started today - Developers: Build with 3.8 Flash and explore agent-first workflows in Google Antigravity or start building today in the Gemini API via Google AI Studio and Android Studio, or generate UIs in Stitch. Get started with our developer docs. - Enterprises: Access 3.8 Flash in Gemini Enterprise. - Consumers: 3.8 Flash is available to Google AI Pro and Ultra subscribers across the Gemini app, AI Mode in Google Search and Gemini in Google Sheets. - Cyber: Through our new Fairwind Program, we’re providing trusted government authorities, as well as critical infrastructure operators and software maintainers with prioritized access to Gemini 3.8 Flash Cyber. Apply for access.

6

We could save petabytes of cache storage with Zstandard and Pingora

Hacker News · original → · 7/10 · Tech: cache storage optimization with Zstandard, work-relevant platforms
How we could save petabytes of cache storage with Zstandard and Pingora Memory costs are increasing dramatically. Both RAM and hard disk drive prices have exploded over the past year. At Cloudflare,…

How we could save petabytes of cache storage with Zstandard and Pingora Memory costs are increasing dramatically. Both RAM and hard disk drive prices have exploded over the past year. At Cloudflare, we run several massively distributed storage products (including our famous CDN) that rely on making efficient use of the memory we have deployed so we can continue to serve all of our customers. With this in mind, we prototyped a way to expand effective cache capacity. By encoding eligible assets with Zstandard inside Pingora, the architecture trades a minor CPU increase for significant storage and cross-data center bandwidth savings. We have been prototyping a system called Cache Transcoding, which I built during my internship at Cloudflare as part of the 1.1.1.1 Intern Program. When an eligible response enters the cache, we encode it using Zstandard, or zstd, before writing it to disk. We keep that compressed form while the asset lives in the cache and moves between data centers via Tiered Cache, then decode it before serving the response to the client. In our initial testing, this encoding shrunk eligible assets to ⅓ of their original on-disk size on average. The estimated extra CPU cost in our origin-facing proxy was small, but that is the trade. A small increase in CPU gives Cloudflare petabytes of effective cache capacity and reduces the data transferred between our data centers. The encoding cost is paid once when an asset enters the cache. The storage and bandwidth savings continue every single time that asset is reused. What is Zstandard? Zstandard, or zstd, is a lossless compression algorithm developed by Yann Collet at Facebook and open sourced in 2016. Lossless means that after compressed data is decoded, every byte is identical to the original. We can change how an asset is represented on disk without changing the asset itself. Zstd is designed to balance compression ratio with speed. In our earlier browser compression testing, it compressed data 42% faster than Brotli while producing nearly the same file size, and produced files 11.3% smaller than gzip at a comparable speed. That balance matters because Cache Transcoding would touch a large amount of traffic, so both encoding and decoding need to stay fast. The prototype uses zstd level 3, giving us most of the compression benefit without turning cache fills into a CPU bottleneck. Cloudflare traditionally stores an asset using the content encoding supplied by its origin. If an origin sends an uncompressed response, we store those uncompressed bytes on disk and transfer them between data centers in the same form. Cache Transcoding adds compression inside the cache itself. Not everything is worth compressing Transcoding does not mean compressing everything. Images, video, and fonts are usually compressed already. In our traffic sample, this media slice represented 21.4% of requests but 63.3% of bytes. Compressing it again would burn CPU for nothing. Compressible text is different. HTML, JSON, CSS, and JavaScript represented 67.3% of requests and 22.3% of bytes. Within that text slice, approximately 71% arrived uncompressed with Content-Encoding unset and it compresses well. In our controlled test corpus, the eligible assets compressed by roughly 2.8 times. Measure | Value | |---|---| Compression ratio | 2.834x | Encode cost | 4.31 ns per byte, approximately 232 MB/s, paid once per fill | Decode cost | 1.56 ns per byte, approximately 641 MB/s, paid on every serve | Encoding is more expensive per byte, but assets are served far more often than they are filled. By changing how assets are represented, existing hardware could store more customer content. Fewer bytes on disk mean each server can retain more objects. This increases cache density and reduces the likelihood that useful content is evicted because an uncompressed representation consumed more space than necessary. The smaller representation also helps as an asset moves through Tiered Cache because it reduces the data transferred between Cloudflare data centers, making backbone usage more efficient. Paying the compression cost once Compression is never free. Encoding and decoding both use CPU, so the important question is whether the byte savings are worth the processing cost. At zstd level 3 (often the default balance of speed and compression size output), our model kept the extra CPU cost to a few percent under the traffic and reuse assumptions we tested. We initially considered limiting transcoding to popular content, since hot assets are reused more, but it did not help. Decoding happens every time an asset is served, so limiting the feature to only the hottest content reduced the storage saving without cutting CPU by the same amount. The simpler policy performed better. Transcoding all eligible compressible text at or above 4 kibibytes (KiB) captured nearly all of the measured storage benefit, while remaining within the CPU budget. How Cache Transcoding works On a cache miss, our Pingora-based proxy encodes the body using zstd before writing it to disk. The cache metadata records that the stored representation is compressed and preserves the original content length. Before the response leaves the proxy, the body is decoded back to its original identity representation. On a cache hit, the stored zstd object is read from disk and decoded. With Tiered Cache, the compressed representation is transferred from the upper tier to the lower tier in the compressed form. Decoding only happens on the client-facing hop. On a full cache miss, the upper tier fetches identity bytes from the origin. Those bytes are encoded once, stored as zstd, and transferred to the lower tier in their compressed form. The lower tier also stores the zstd representation, then decodes it for the request path. If the lower tier misses but the upper tier already has the object, the origin is not involved. The compressed object moves directly between the cache tiers. It remains compressed on the wire and on disk, then is decoded once at the lower tier. If the lower tier already has the object, no network transfer or encoding is needed. The lower tier reads the zstd bytes from disk, decodes them, and passes the original asset onward. The storage encoding marker prevents an object from being encoded more than once. A cache layer receiving an object from another tier can see that it is already stored using zstd, and preserve it in that form. Why we only transcode certain text The fastest compression operation is the one we do not need to perform. Cache Transcoding therefore uses a series of eligibility checks to avoid content that is unlikely to benefit. The prototype only transcodes a 200 OK response when Content-Encoding is unset, the Content-Type is compressible text, and the response has a known Content-Length of at least 4 KiB. Slice subrequests, responses using active upstream compression, range requests, precompressed responses, unknown length bodies, and binary content remain unchanged. The 4 KiB threshold removed a large number of tiny requests while leaving out only about 1% of the otherwise eligible bytes. Lowering it would add per-object overhead without saving much more storage. The threshold and zstd level are both parameters rather than permanent limits. We started with zstd level 3 and a 4 KiB minimum because they gave us a conservative way to measure the architecture. With the initial CPU budget understood, we can test whether higher compression levels improve the ratio enough to justify their additional cost. Testing over one million requests through the cache We exercised the prototype against a controlled test zone and correlated each request across request logs, Prometheus metrics, and Jaeger traces. The correctness campaign covered cache misses, cache hits, single-hop fills, Tiered Cache fills, and more. We varied cache keys to make each request follow a specific path and used traces to confirm where encoding and decoding occurred. One performance campaign sent more than a million requests across 10 cache servers. Half of the campaign ran with Tiered Cache disabled and the other half with it enabled. This allowed us to measure local cache behavior separately from transfers between cache tiers. The two assets were approximately 195 KiB and 272 KiB, and both compressed by roughly 2.8 times. This was deliberately a compressible test corpus. It gave us a clear signal for validating the architecture, but it does not represent every text object on the Internet. A broader corpus is required before treating the measured compression ratio as a fleet-wide constant. Compress once, benefit many times What this experiment showed us is that there are significant efficiencies we can still deploy across our caching service that can benefit all of our customers. What we built for Cache Transcoding shows that the trade is favorable under the conditions we tested. The architecture preserved the content and remained within the CPU budget. For next steps, we plan to evaluate higher zstd levels, test a broader range of content types and object sizes, tune different parameters from the eligibility criteria and more. Future work can also examine range requests, pre-compressed origin responses, and passing the compressed object directly to downstream components that already support it without decoding. Throughout my internship, I’ve had the wonderful opportunity to work alongside Cloudflare's engineering teams on the real infrastructure that stores and serves content across our global network. If you want to start your career by helping build a better Internet, explore our internship opportunities and job openings.

7

How to turn your AI into a world-class designer

Lenny's Newsletter · original → · 7/10 · AI/Work: using AI as designer, work-relevant platforms/AI
👋 Hey there, I’m Lenny. Each week, I share deeply researched product, growth, and career advice. For more: Lenny’s Jobs | Lenny’s Podcast | Lennybot | How I AI | Become an AI-Native Builder and my…

👋 Hey there, I’m Lenny. Each week, I share deeply researched product, growth, and career advice. For more: Lenny’s Jobs | Lenny’s Podcast | Lennybot | How I AI | Become an AI-Native Builder and my other favorite AI/PM courses

Subscribe now

P.S. Get a full free year of Cursor, Notion, Replit, Lovable, Wispr Flow, Linear, ElevenLabs, Factory, PostHog, Granola, Brain.fm, Waking Up, and more, by becoming an Insider subscriber (while supplies last). Learn more.


I’d always thought AI was bad at design. But after reading this mind-blowing post by Anshu Chimala, I realize I was just doing it wrong. Anshu led software engineering and design teams at Apple for 12 years, focusing on research and prototyping for future AI products. He regularly shares design tutorials and demos on X (he’s one of my favorite follows). For deeper dives into crafting distinctive experiences with AI, check out his Substack and connect with him on LinkedIn.

Let’s get into it.


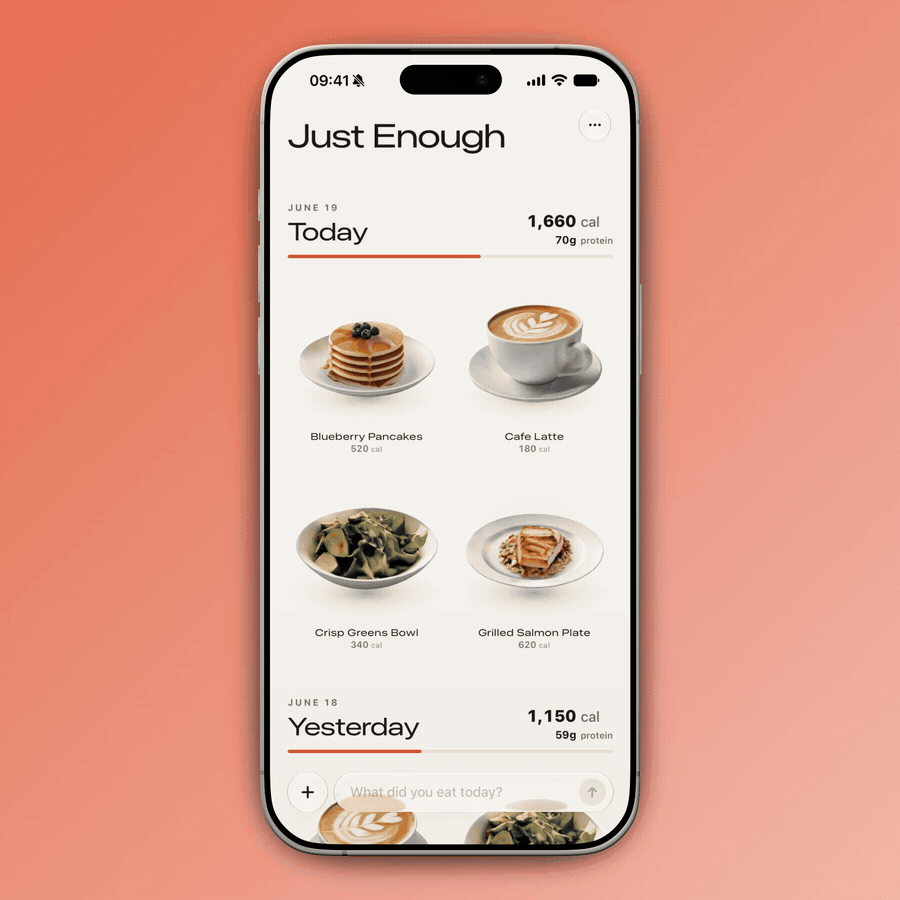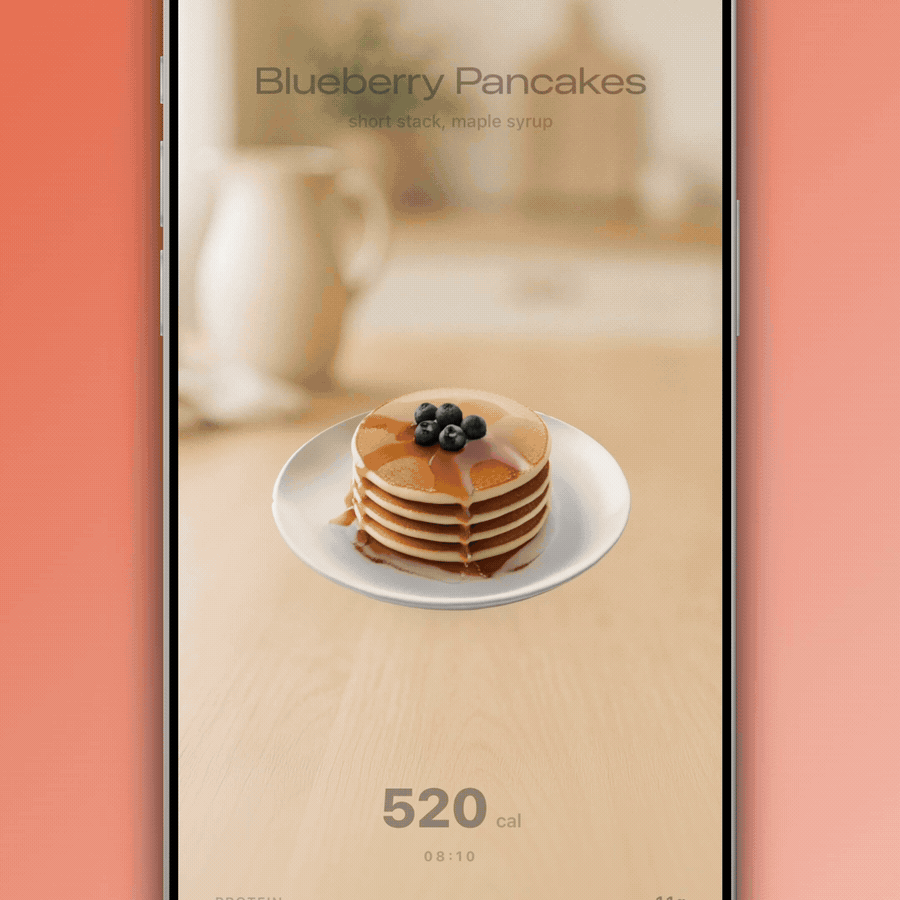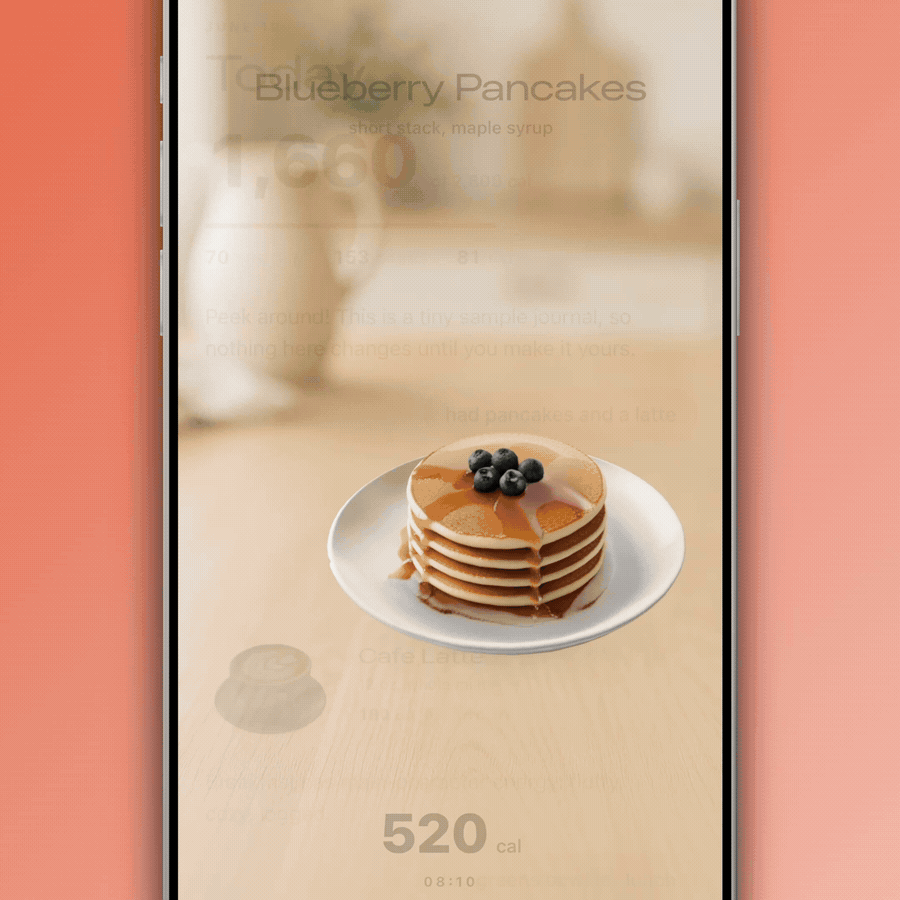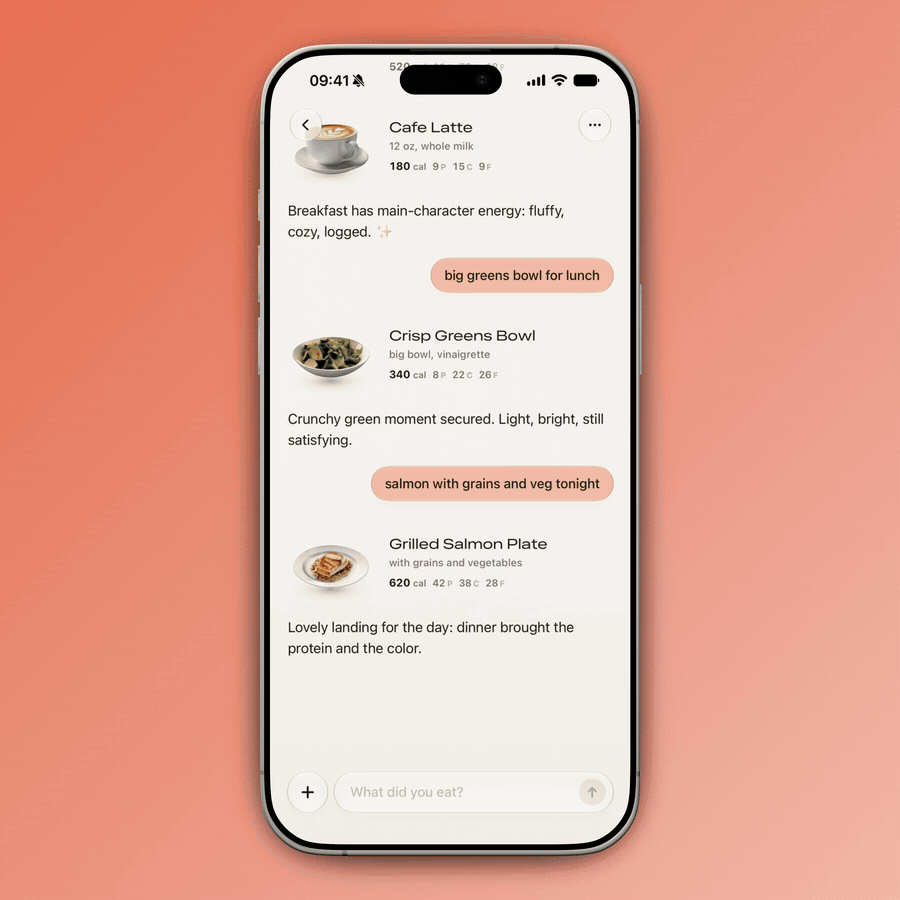
A conversational calorie tracker, built in three prompts with Claude Fable 5:

A space exploration game, built in two prompts with Claude Opus 5:

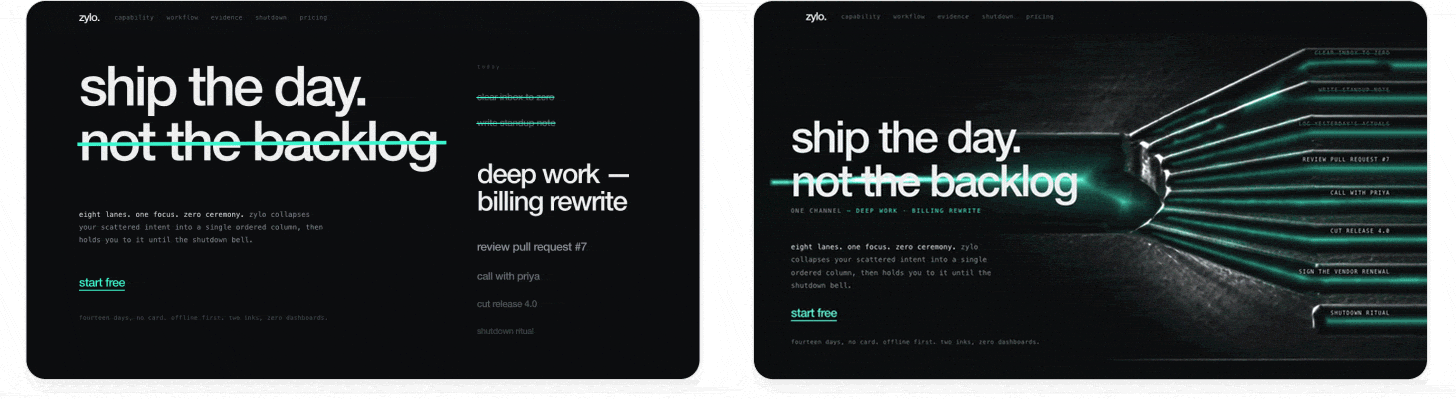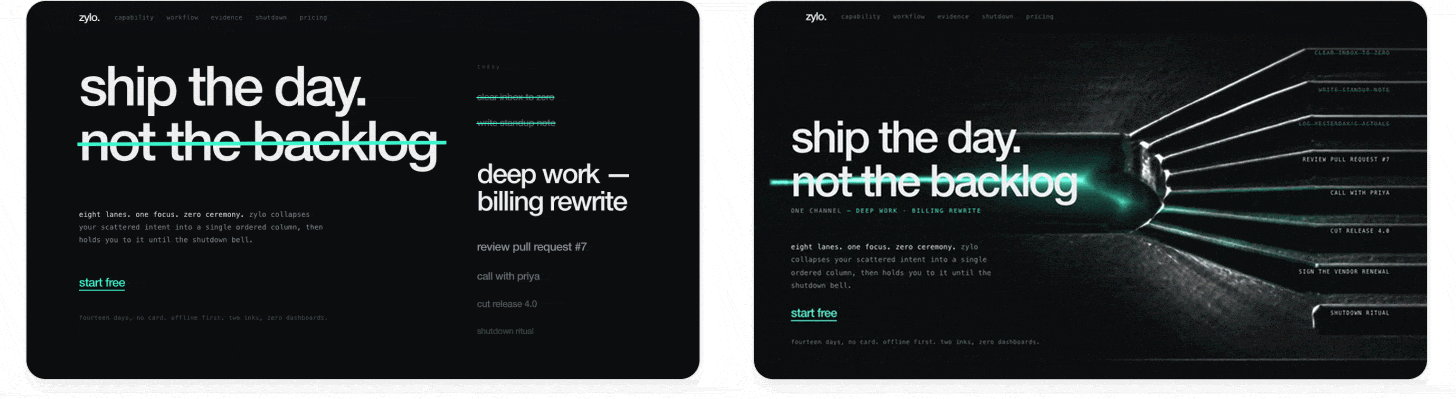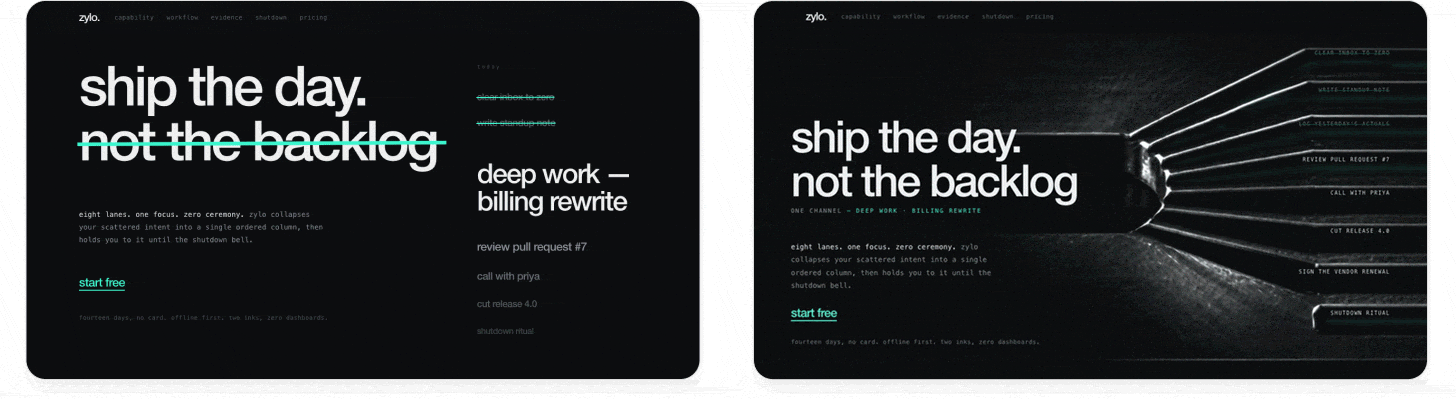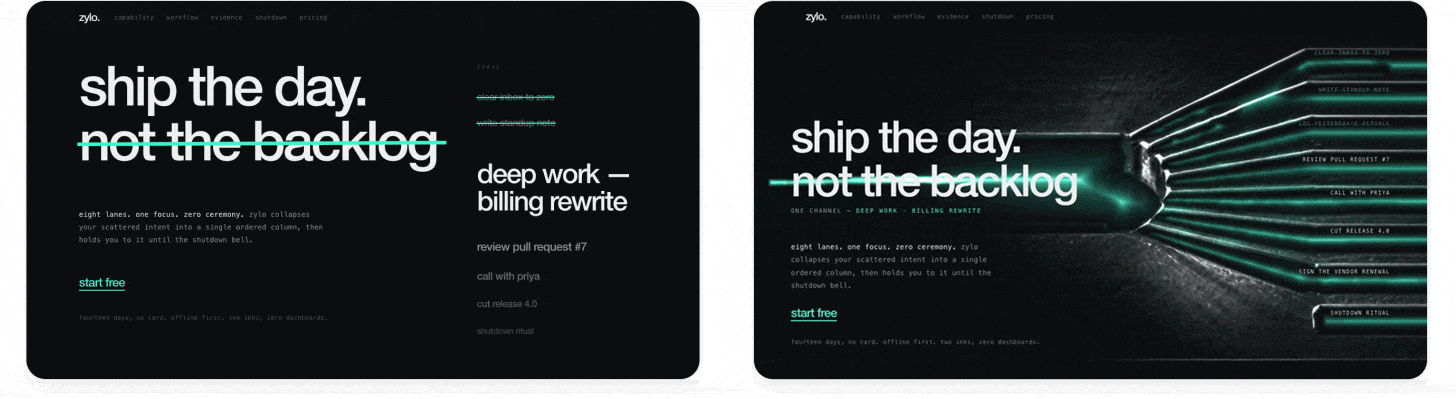
A dynamic landing page, built in three prompts with Claude Opus 5 + GPT-5.6 Sol:

I often post AI design demos like these on X. Every time I do, someone inevitably asks, “Why does the model create all this incredible stuff for you, but when I try, I only get generic slop? It’s like you’re using a completely different model.”

I’m not using a different model, but I am getting more out of the models I work with. Most people only see 1% of AI’s creative potential. I want to show you how to tap into the other 99%.

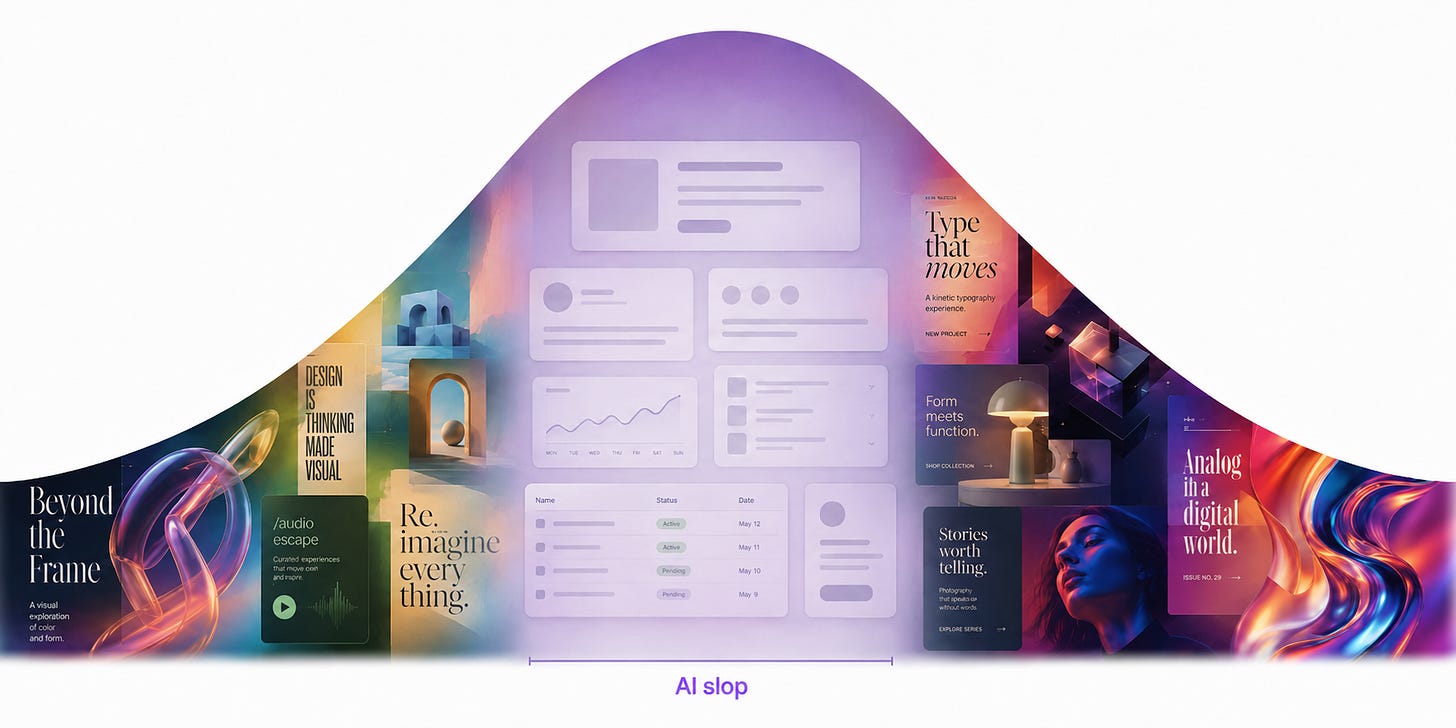
AI models are capable of amazing creativity, but that creativity gets stifled by how they’re trained. Large language models are next-token predictors: at each step, they look at a sequence of text and predict what comes next based on millions of examples. The results may be rated by humans, and those ratings fed back into the model. This teaches the model to make consistent, safe choices that fit everyone’s preferences.

This makes typical LLMs great at most tasks but poor designers. To create a design, an LLM has to build it out token by token. Whenever it needs to make a design decision—what colors to use, or how to arrange elements—the model fills in the tokens it thinks are most likely to please everyone. As a result, the design usually ends up being repetitive and bland. It’s like the ultimate case of design-by-committee.

Great design, on the other hand, starts with feeling and aims to create an emotional response. It bends the rules and delights users with memorable, unexpected choices. Great design is exactly the opposite of what an LLM does naturally, which is to make the most predictable choice at every step.

However, if we can get the model to reach beyond the most predictable choices, we can access a vast landscape of creative ideas that most people miss out on.

This is a lesson I learned from managing human designers, before I was managing AI ones. For most of my career at Apple, I led an R&D team designing exploratory future AI products. Early on, our preconceived notions about how user interfaces should work limited our creativity and kept us returning to the same old ideas. Through rigor and new processes, we learned to stop re-creating what’s comfortable and instead look to the fringes of what’s possible, to generate something new. We became experts at polishing the little details to an Apple level of quality.

Since my time at Apple, I’ve been working on applying that same process to my work with AI. In the past couple years, AI agents have become extremely capable. They can do in hours what used to take my team weeks. And with the right guidance, they can create designs that look completely unlike anything else.

Loosely inspired by the Double Diamond design process, I’ve reimagined the design process for a team of AI agents instead of human designers:

  1. Discover new ideas beyond the average slop by exploring a variety of directions and creating bold, ambitious design briefs.

  2. Define an individual design identity by pushing AI beyond its familiar patterns and chaining models together to fully realize the design’s potential.

  3. Deliver a stunning final result by polishing away the sloppy rough edges and focusing on the key elements.

By following these stages and applying the techniques within each one, you can create an incredible design remarkably quickly—and make people ask, “Why does AI create magic for you (and not me)?”

Discover: Explore the space of possibilities

The hardest part of the design process is looking at a blank screen with infinite possibilities. The best way to tackle that moment is to start by going broad before going deep. AI is an excellent tool to explore a wide variety of potential directions.

As we know, though, models tend to overrely on familiar patterns and make conservative choices. To explore the full potential design space, we want to coax a model to do the opposite: be bold, be varied, and take risks. Below are two ways to push it out of its comfort zone.

Technique 1: Use seed strings to inject variety

The idea here is to get the model to find a new source of inspiration for designs, rather than relying on the defaults it learned from training. If you’ve tried to prompt a model to design a website or app, you’ve probably already seen what that default looks like.

As a simple example, I gave four instances of Claude Code the same prompt:

Prompt:

Build me a landing page for my productivity app.

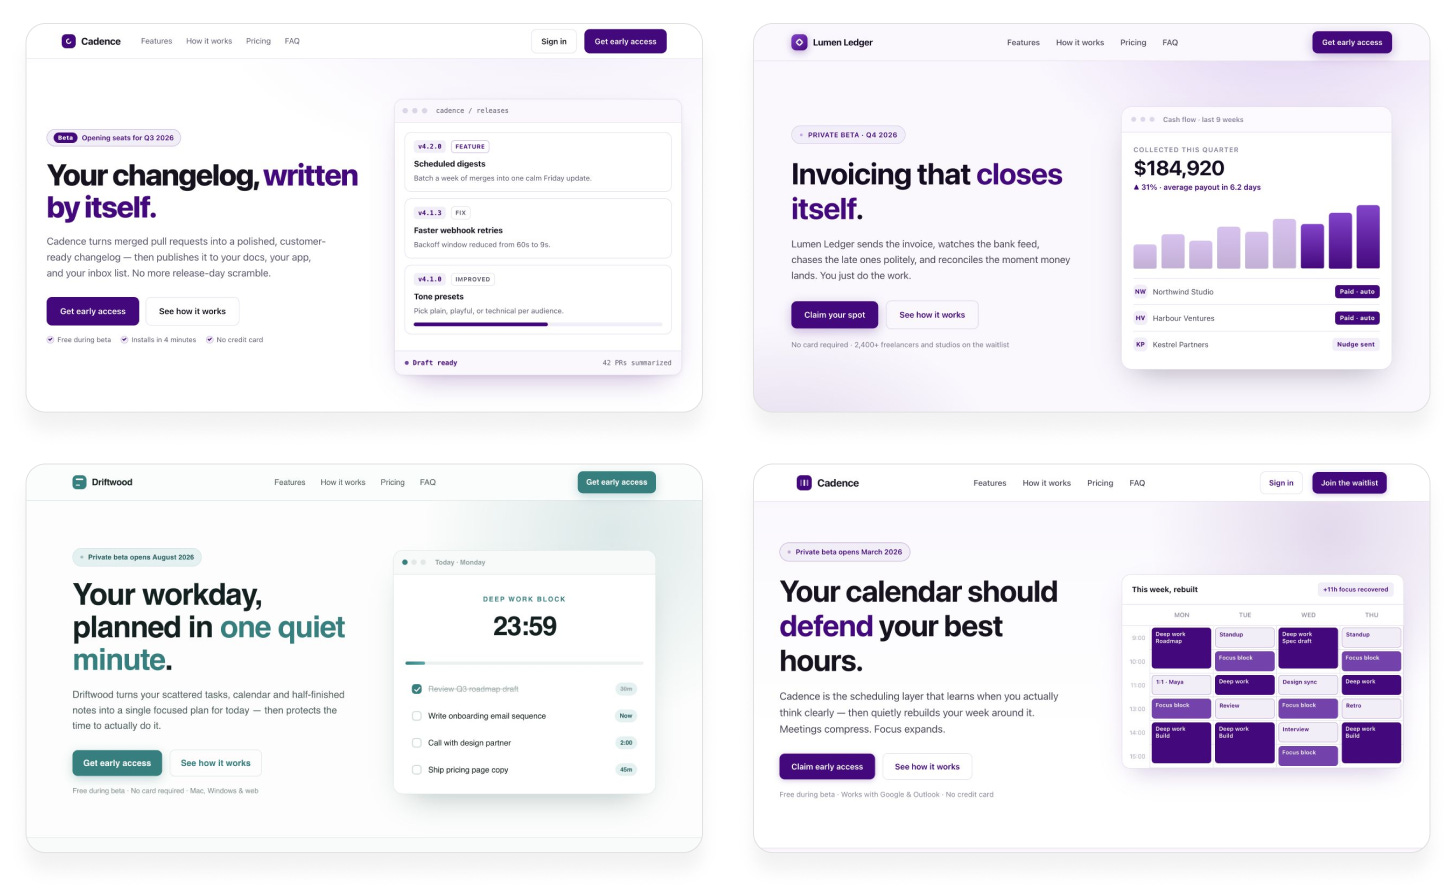
Claude Opus 5:

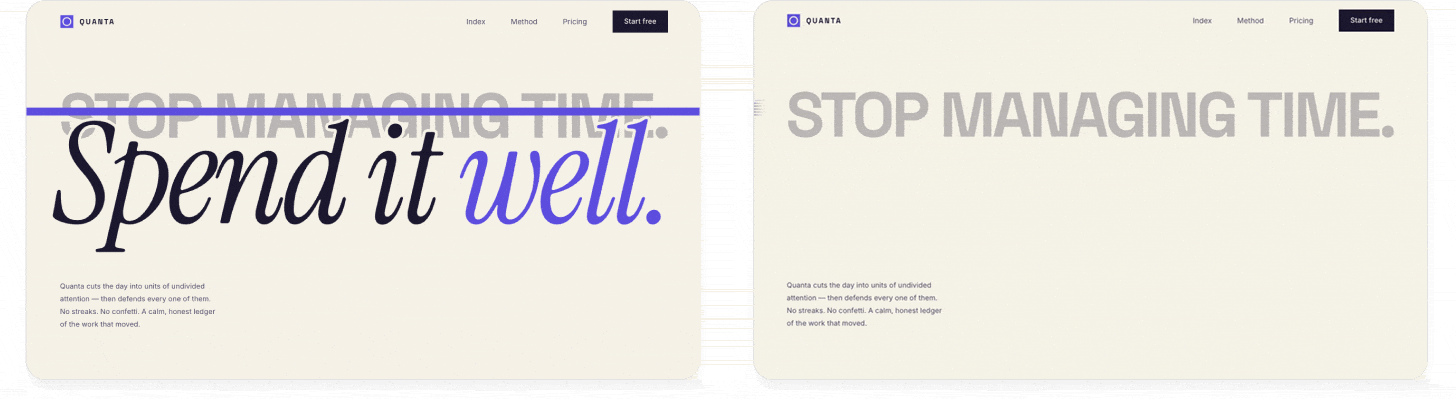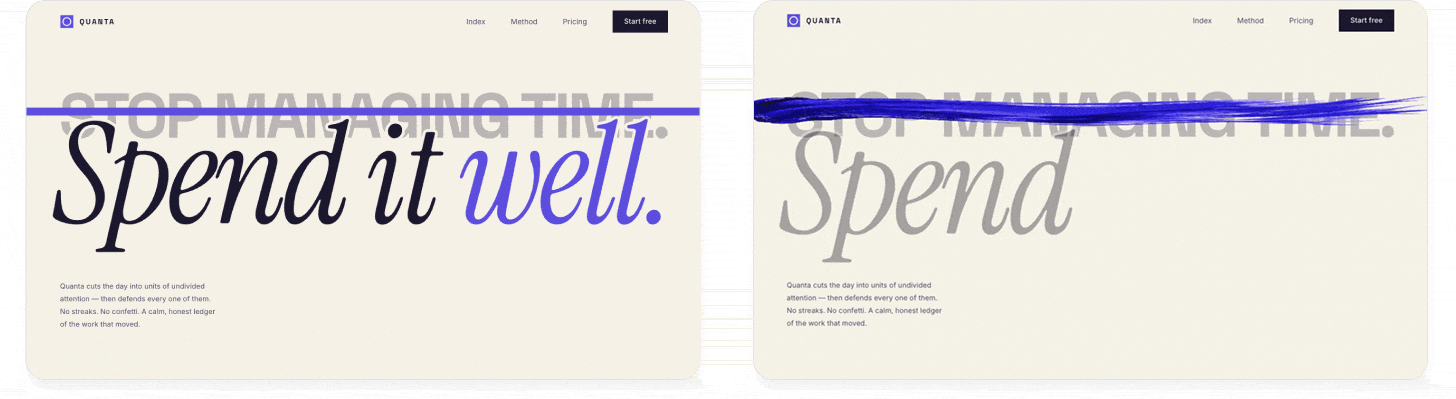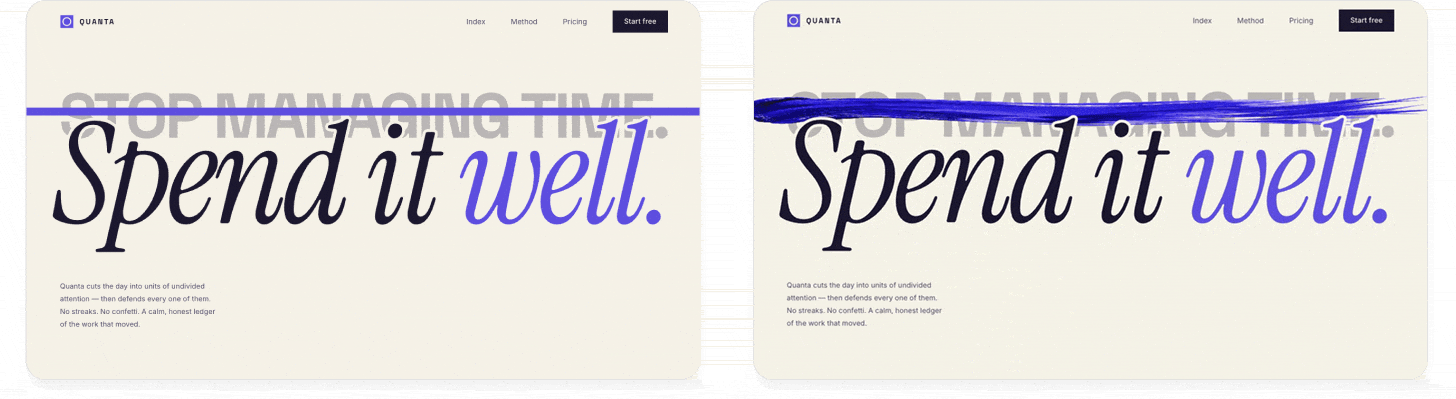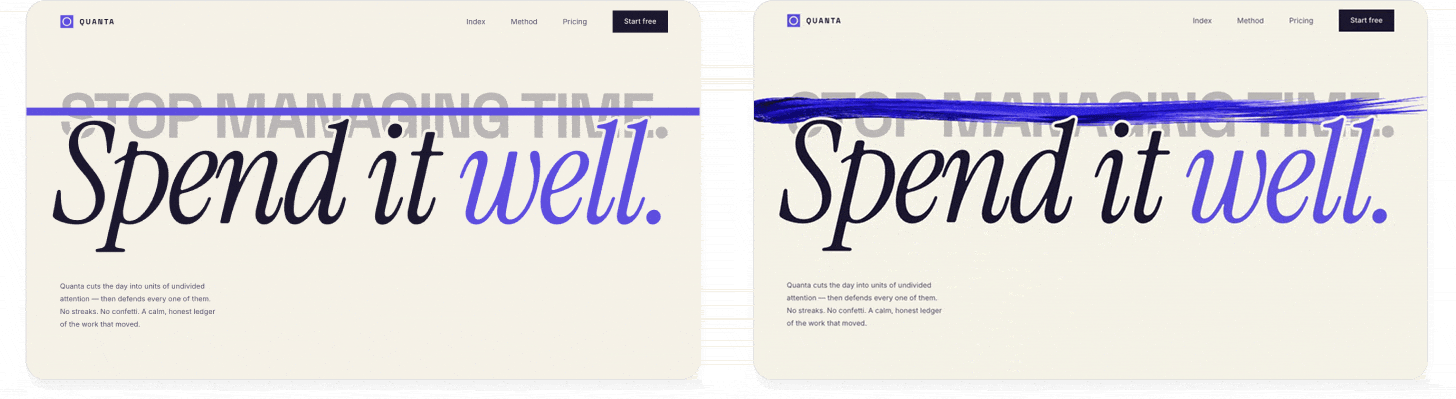
Almost every time, we get a purplish gradient, text on the left, graphic on the right, and the exact same structure. It looks like every AI-designed website ever.

We didn’t ask the model to do anything unique or varied, so it makes sense that it keeps falling back on the same patterns it knows well. But just asking for variety doesn’t work:

Prompt:

Build me a landing page for my productivity app. Give me something totally unique. Make every design decision completely at random.

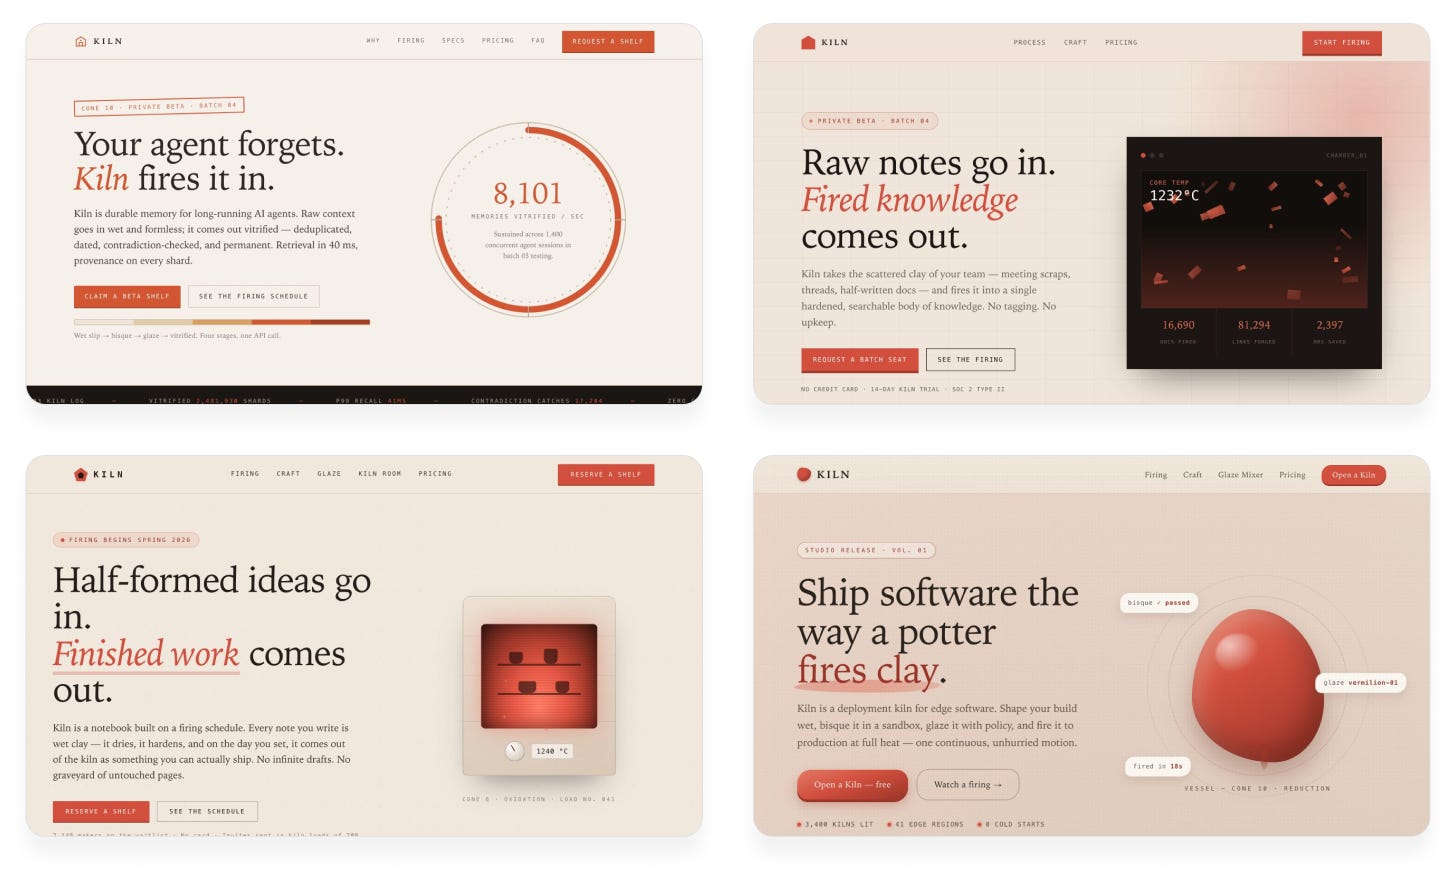
Claude Opus 5:

The results are different from before, but they’re still not varied. The model always uses the same color scheme, structure, and even the same awkward pottery metaphors. It’s predicting tokens that sound random but aren’t actually random.

The problem is that the model can’t inherently act randomly. It can only predict the most likely token. If we want variety, we have to bring it from outside the model. One technique for this is String Seed of Thought, published by Sakana AI. We make the AI generate a random string and use it as design inspiration. That way, the model is truly making different decisions each time.

Prompt:

I want you to build me a landing page for my productivity app.

Follow this procedure:

  1. Generate a long, random alphanumeric string using a shell script.

  2. Define the creative direction (color scheme, layout, typography, etc.) based on the string. Look beyond the surface for subpatterns, special numbers, anything that inspires you.

  3. Use your judgment to bring this direction to life and make it look great.

Don’t reveal the string in the design. It’s only for your inspiration.

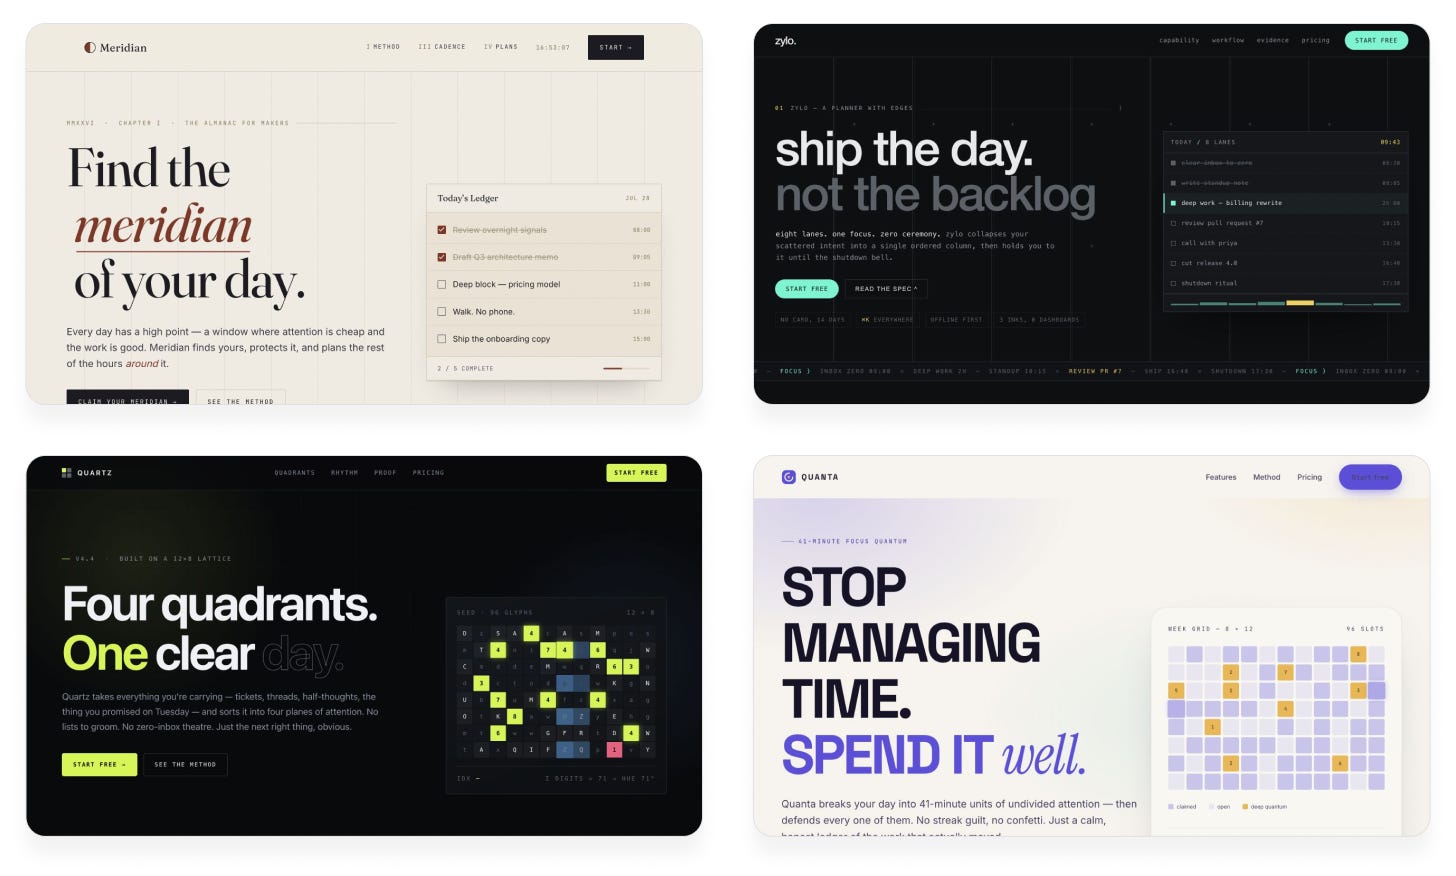
Claude Opus 5:

Suddenly the outputs are much more varied! Now we’re seeing different color schemes, fonts, and new ideas. The previous designs were ones that any Claude user could get. These designs are one-of-a-kind; no two runs ever produce the same result.

Technique 2: Be much more ambitious with your prompts

Another approach to giving a model a strong push is to get more specific and wild with your prompts. This gives the model a clear vision to base its decisions on, rather than letting it make them up on the fly. The best way to find a unique idea is by bringing your own taste into the equation. You first imagine the inspiration—a video game, an interior design trend, an art installation—and describe how you’d like that inspiration to influence the AI’s outputs. Here are some examples:

“Build me a landing page for my productivity app, with a bold pixel art theme and stunning graphics. Each section should feel like a still from a video game, yet somehow it should all function as a landing page.”

“Build me a landing page for my productivity app, set in an isometric living 3D city, where different features are somehow represented by neighborhoods or buildings.”

“Build me a landing page for my productivity app, with a radically asymmetric layout, dissonant colors and typography, and uncomfortable negative space. Break all the rules but still make it look good.”

Of course, the hard part is coming up with original ideas to ask for. AI can help with this too, but if you simply ask it for ideas, you’ll get the same average ones everyone else gets. Here’s a system I use to find unique prompt ideas with AI:

1. Ask AI to list a bunch of ideas, intentionally lacking detail. The goal is just to inspire your imagination.

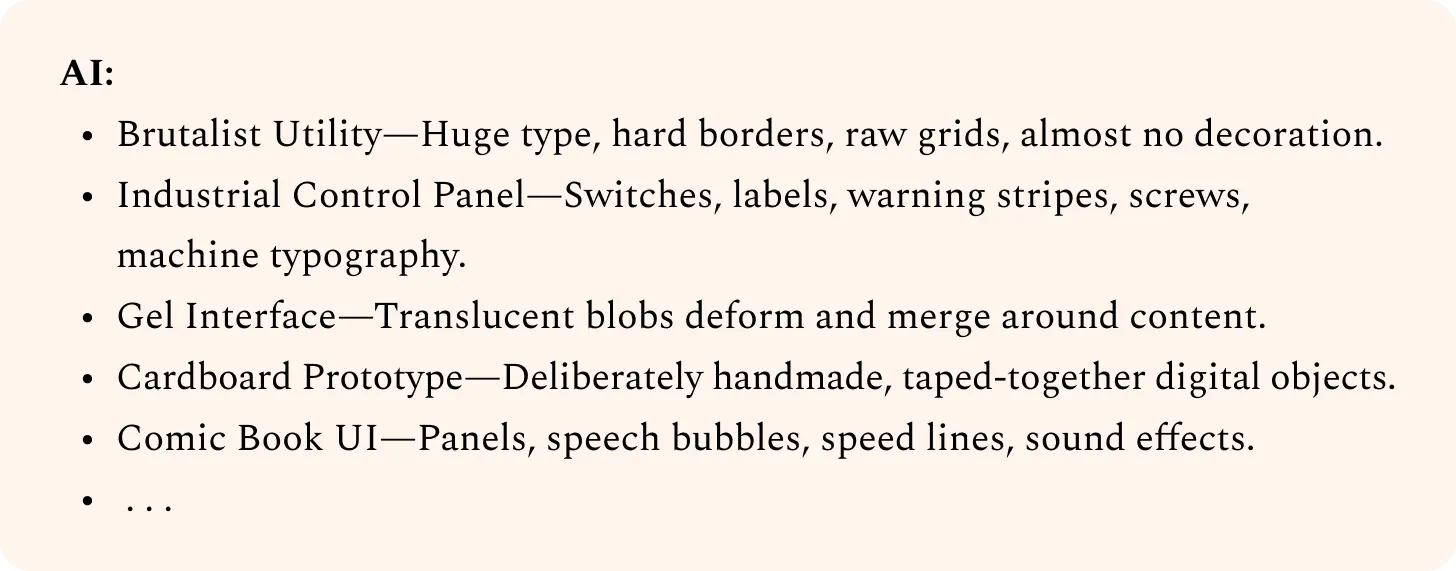
I want to come up with a bold, unique design language for my product. Can you list as many ideas as you can, with short, high-level descriptions? Go broad, not deep.

2. Visualize your favorites and note how you react to different directions. Then ask AI to refine them.

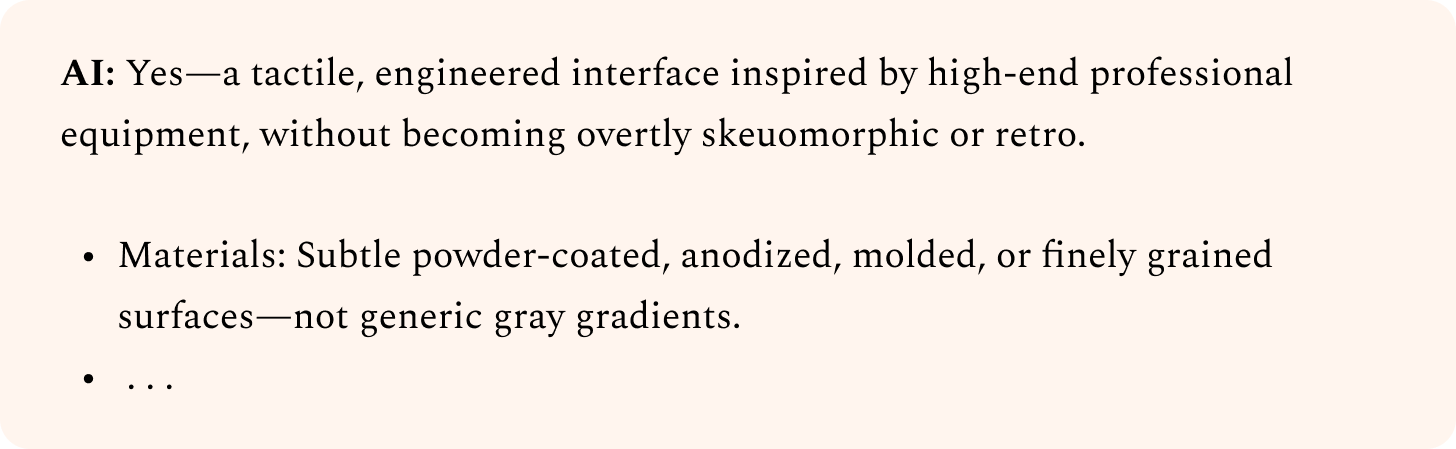
Industrial Control Panel:

  • I’m imagining something tactile. Clicky, satisfying buttons, nice sounds.

  • Initially I pictured something cartoony or skeuomorphic, but this feels tacky to me. Avoid that.

  • Instead, want consistent components and little touches that land this look without going overboard.

  • Gray gradients would look boring. Need more texture. Maybe we can incorporate some color, while retaining the control panel feel?

Can you sharpen this one based on my tastes?

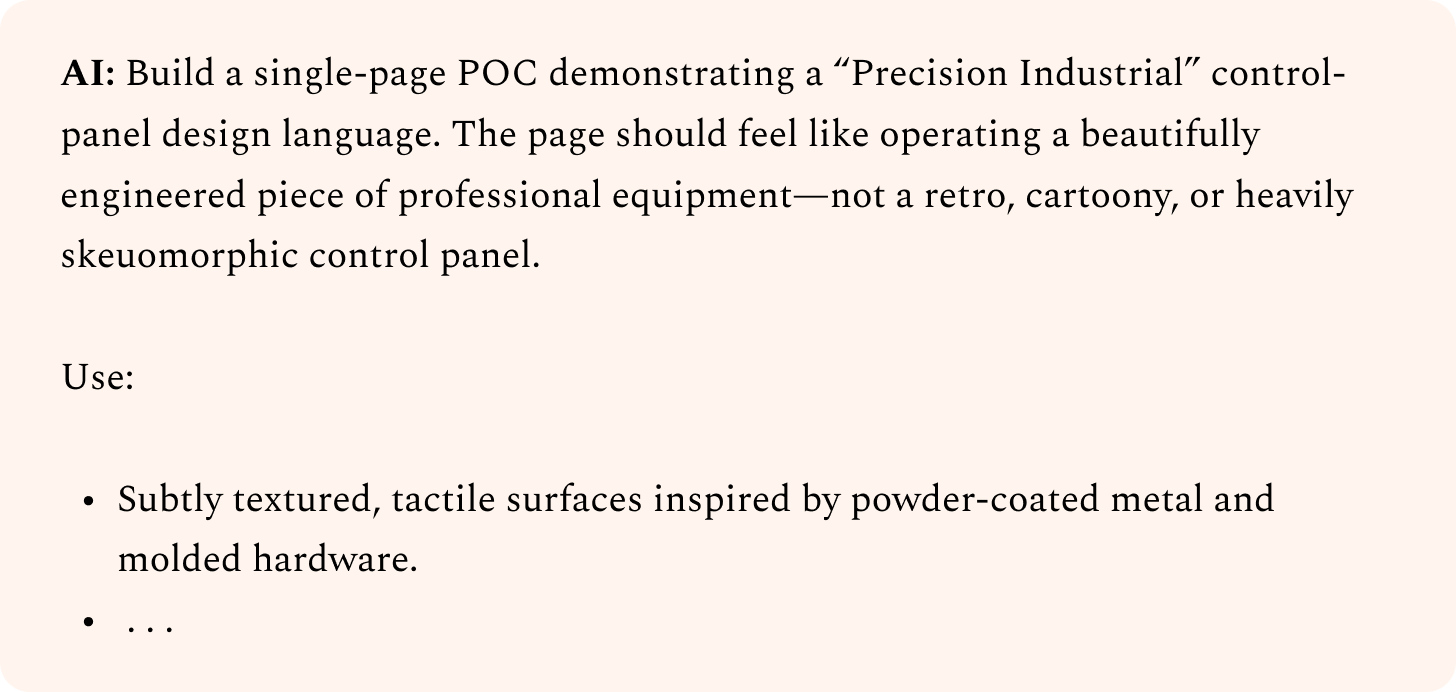
3. Iterate until you’re satisfied, then ask AI to write the prompt to build it.

Can you write a concise prompt that an AI agent could use to build an initial POC page with this?

If you just paste AI-generated ideas back into AI, it’s hard to get something unique. After all, anyone else could have done the same thing. However, when you actively steer the design direction, you end up with something only you could have created.

Don’t be afraid to try ideas that sound terrible. If you find yourself thinking, “There’s no way this will work,” you’re on the right track. Often, your agent will surprise you, and you’ll realize you were underestimating it. If not, just throw away those results and try something else. But save the prompts that don’t work, and test them again when newer models come out. That way, you’ll know you’re taking full advantage of what the latest models can do.

Define: Deepen your design direction

So far, we’ve looked at how to explore a broad set of ideas and hopefully land on a promising initial design. No matter how we prompt, though, our initial AI-generated designs will usually still feel generic.

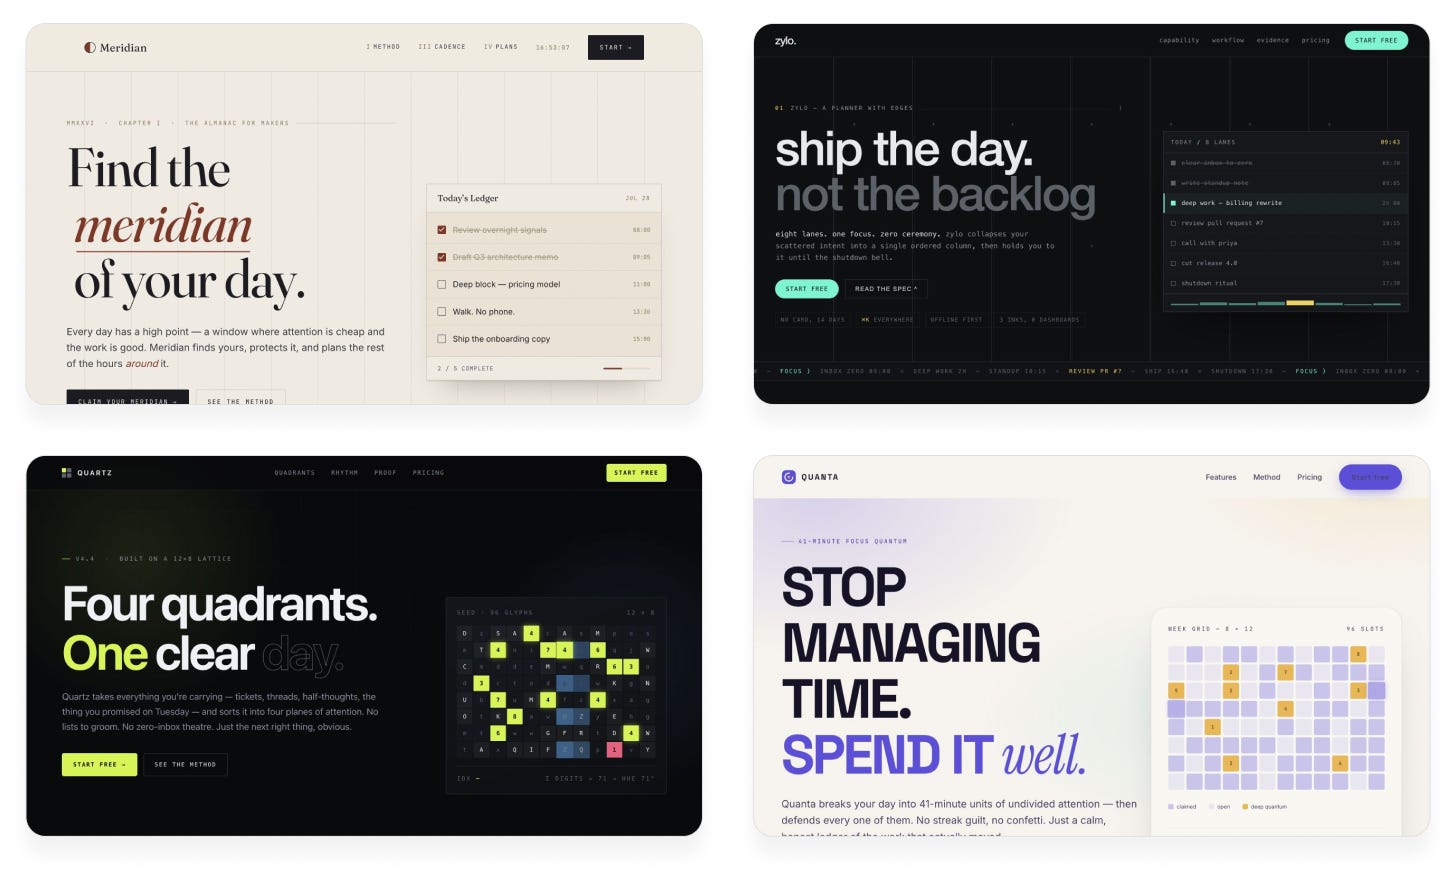
For example, look at the designs we came up with using seed strings:

These have promise, but they’re still relying heavily on the same stale patterns: text on the left with a CTA button below, nav bar up top, graphic on the right.

Our next goal is to give each design an individual personality through distinct design choices. Below are my favorite techniques to do that.

Technique 3: Create positive feedback loops with subagents

We need to iterate on our designs to improve them. But simply asking our agent to look at the design and improve it won’t work, because the agent isn’t objective: it reviews its own code, past decisions, and previous rationale. AI can’t easily zoom out, look at the big picture, and “think different.”

To solve this, instead of letting the coding agent decide when the design is good enough, have it ask another agent—a “design critic.” The critic’s job is to look at screenshots of the current design and provide feedback. It doesn’t care how the current design is implemented or how much effort went into it, only if it actually hits the quality bar.

This approach has an extra benefit: we can use a big, expensive model for the critic without breaking the bank, because we’ll only use it for executive decisions. A cheap, fast model can do the grunt work, while the strong critic model provides taste.

Let’s try this on our previous designs, using Claude Fable 5 as the critic:

Prompt:

I want you to improve this design. To figure out what to focus on, use a Fable 5 subagent as a design critic.

Follow this procedure at each iteration:

  • Capture a screenshot of the current design

  • Invoke the critic in a fresh context, with just the screenshot, not the code, implementation details, or earlier iterations/critiques

  • Ask it to evaluate the aesthetic that the design is going for, imagine how a top design studio would execute this aesthetic, then outline the biggest gaps

  • Lastly, it should provide a score out of 10 indicating how close the current design is to that studio-level quality bar

Provide this guidance to the critic in its prompt:

  • It should think high-level about the overall structure and composition as well as look at the fine details

  • It should watch out for patterns that feel overdone, excessive, or otherwise obviously AI-generated, and penalize them

  • It should provide tight, specific feedback, not vague prose

  • It should be bold and opinionated, not rely on what’s safe or easy

Your work is only complete when the critic independently deems it 9/10 or higher. Do not put that criterion in the critic prompt; keep it objective in its scoring. Use the same critic prompt each time.

Claude Opus 5:

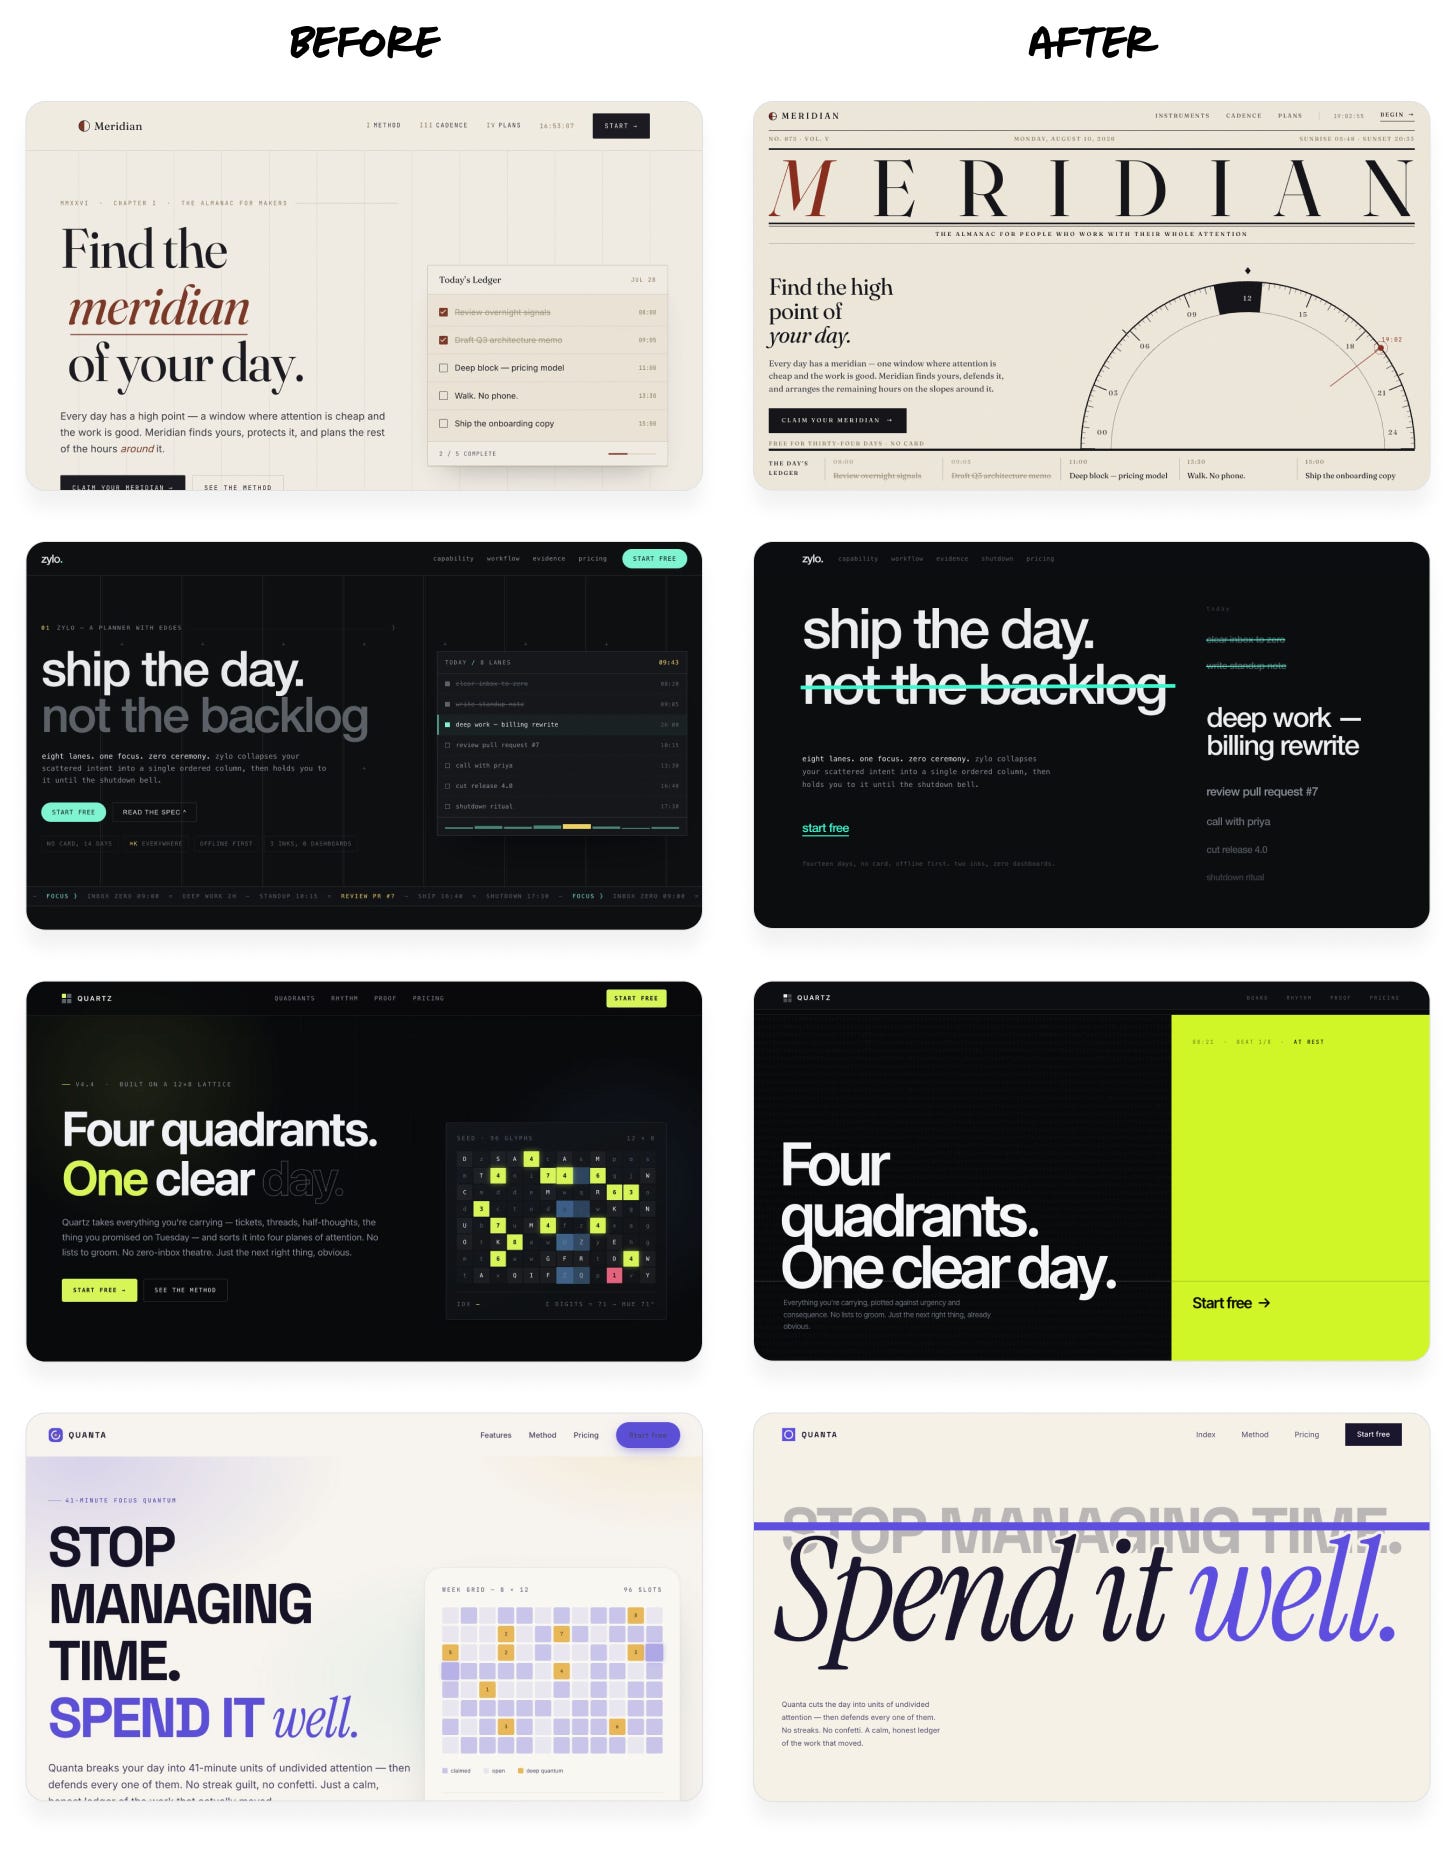
Instead of the same cookie-cutter layout over and over, each design now has its own identity—but still maintains its original high-level aesthetic.

Notably, in each case, Fable accounted for less than 10% of output tokens. Asking Fable to redesign the page directly would have cost twice as much and taken much longer.

The way you set these loops up matters a lot. Here are some tips:

  • Make sure the criteria for the critic are as clear and objective as possible.

    • Bad: “Judge if our design looks beautiful, not AI-generated.” This is too subjective, and the results will vary wildly from run to run.

    • OK: “Review the aesthetic we’re going for, visualize how a top design studio would execute it, then judge our design’s quality against that bar.” The prompt is still mushy, but it provides a consistent framework and quality bar.

    • Great: “Here are 5 designs: 4 professional examples and 1 screenshot of our product. Rank them by polish and taste level.” This instruction is concrete and objective, and gives a visual baseline for judgment.

  • Provide example images to demonstrate the target quality bar. You can use comparable screenshots or designs you like, or even AI-generated concept art. Instruct the critic to treat these as a baseline or a moodboard, not a target. You don’t want it to copy other designs outright.

  • Set the stopping criteria carefully. Otherwise, the critic may never consider the design good enough, and your agent will helplessly burn tokens trying to please it. Prompt it to do one or two iterations first, and see if it’s converging before adding more.

  • Choose the right model for each job. Consider bigger models for the critic role, since more parameters generally translate to better design sense and a wider distribution of ideas. Small models can be effective as the implementer, but don’t go too small. You still need a model that’s capable of executing a design direction well.

Technique 4: Use image generation to enrich designs

Coding agents love to write code, but they usually don’t incorporate images. Instead, they tend to use the easy code-based alternatives: gradients, shapes, and basic patterns. Those are all strong giveaways of an AI-generated design.

Some agents have image tools built in, but they underutilize them. Others don’t have image tools out of the box but can easily use the OpenAI or Gemini APIs to generate images with an API key.

Let’s try this on the designs from the last step:

Prompt:

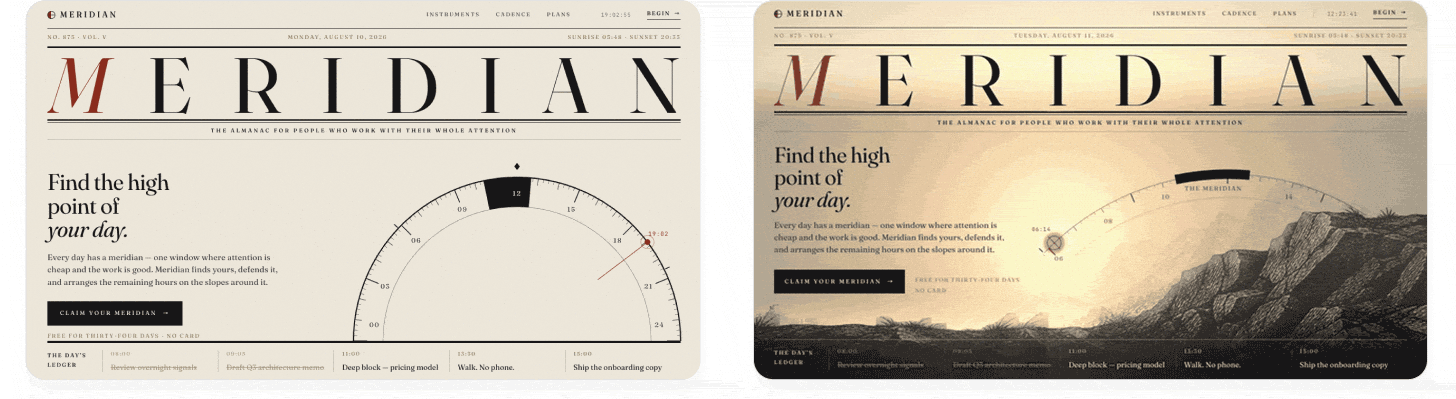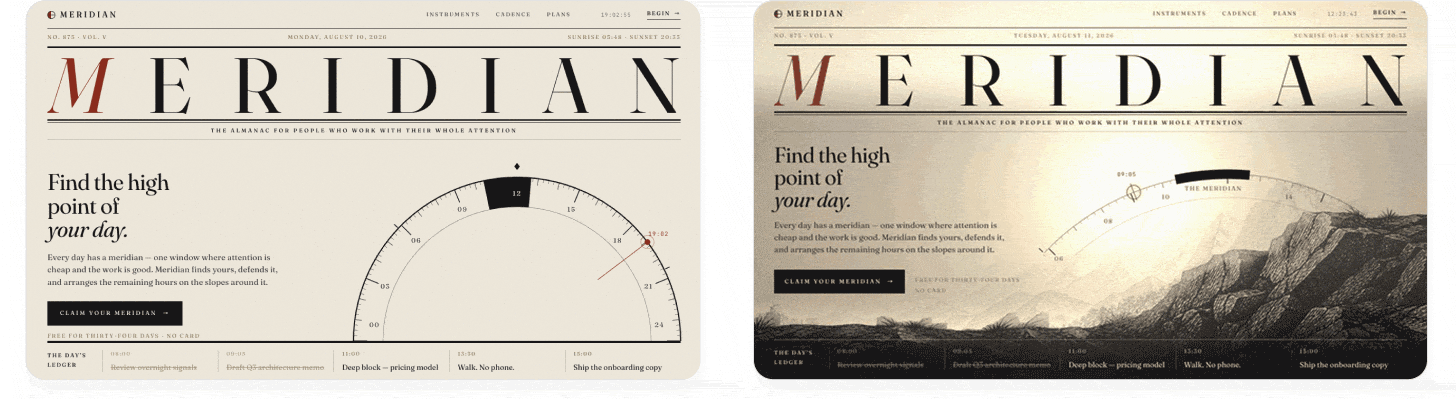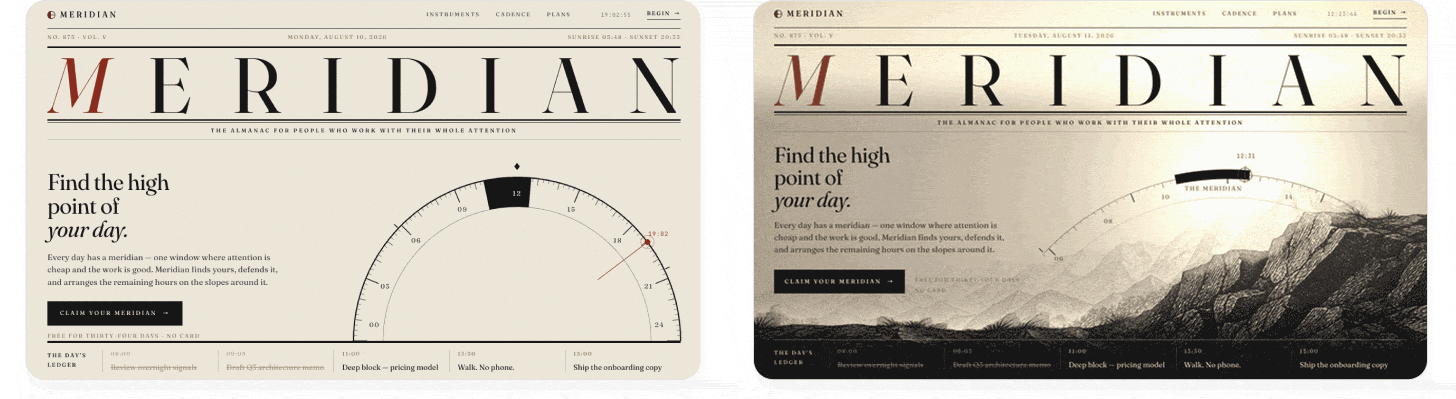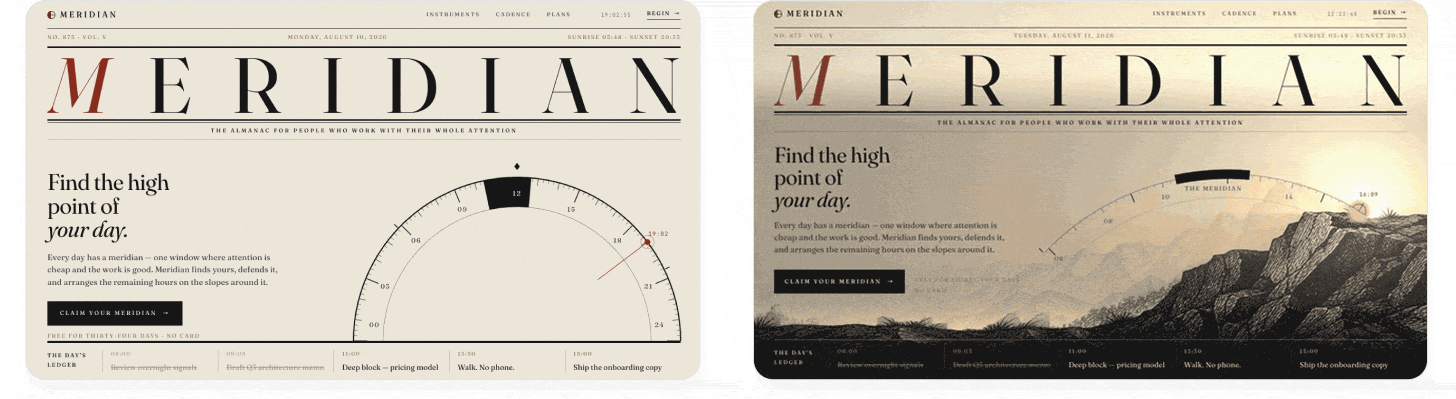
The design is pretty plain. Add more personality using image generation. Consider shaders or 3D effects in combination with images to create more interesting visuals.

For image generation, use this OpenAI API key (only use it locally, do not store it in the code or product): sk-a1b2c3d4…

Verify that your work looks right frame-by-frame in the browser.

Claude Opus 5 (before and after):

Images and effects like these can quickly add a lot of personality and make a design less obviously AI-generated, since they demonstrate more than surface-level effort.

Depending on your setup, there are different ways to connect your agent to image generation tools:

  • If you use Codex, Antigravity, or Grok Build:

    • Tell your agent to use its built-in image generation. The agent already knows how to do this but rarely does so until instructed.

  • If you use Claude Code or another agent but also have a ChatGPT subscription:

    • Tell your agent, “Use the Codex CLI to generate images. Help me install it if it isn’t already present. Make sure it’s billing my subscription, not an API key.” This lets you use your ChatGPT subscription for image generation without extra costs.

  • If you only use Claude, or any other tool:

    • The simplest path is to give your agent an OpenAI or Gemini API key to generate images. I recommend creating a separate API key with a tight spend limit, just for your agent. That way, your costs are controlled even if the key gets out or the agent misuses it, and you can easily revoke the key without disrupting other work.

    • If you find yourself pasting keys into chats frequently, put them in a file instead, and point your agent to it in your project. Tell your agent: “Create a gitignored file called .env.agents, store this API key in it, and note to yourself in AGENTS.md/CLAUDE.md that these keys are for you to use during development (but must not ship with the product).”

Technique 5: For more advanced motion, use video generation

Video generation models are incredibly powerful these days, but most people think of them as tools for generating UGC ads or clips of Will Smith eating spaghetti. They can work wonders for everyday design work too.

There are many video models out there, and the best ones change frequently, so I like to use an aggregator platform like fal.ai. This way, we can give our agent a single API key and let it evaluate different options and choose the best one without needing multiple integrations.

Here are two ways I love to use video models in my designs:

Create stunning animated graphics

The trick is to generate a looping clip with a solid color background, then either chroma key it out (like a green screen) or, in more complex cases, use a video matting model to remove the background. This gives you an animation that you can layer anywhere in your UI without it looking like a video.

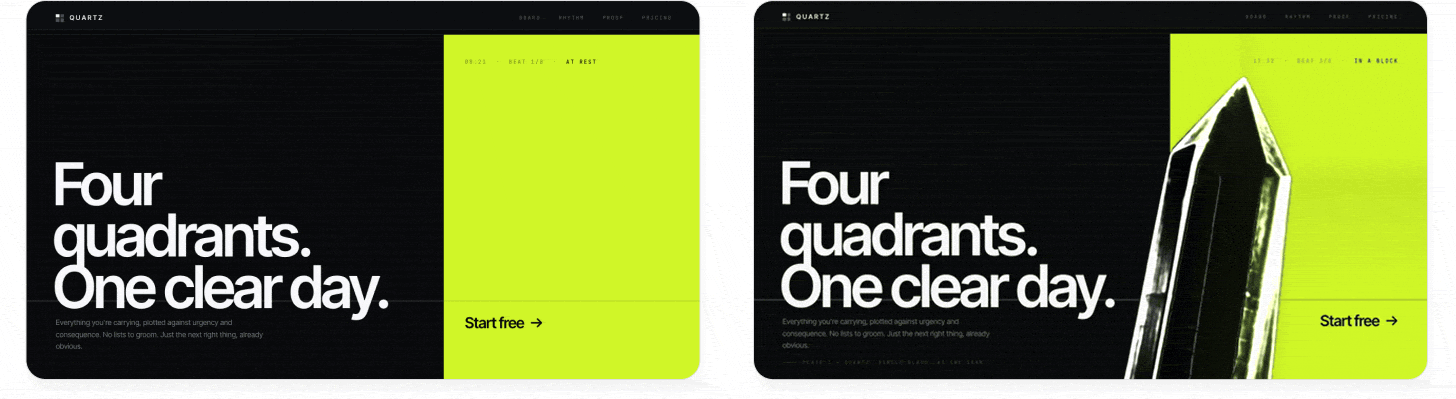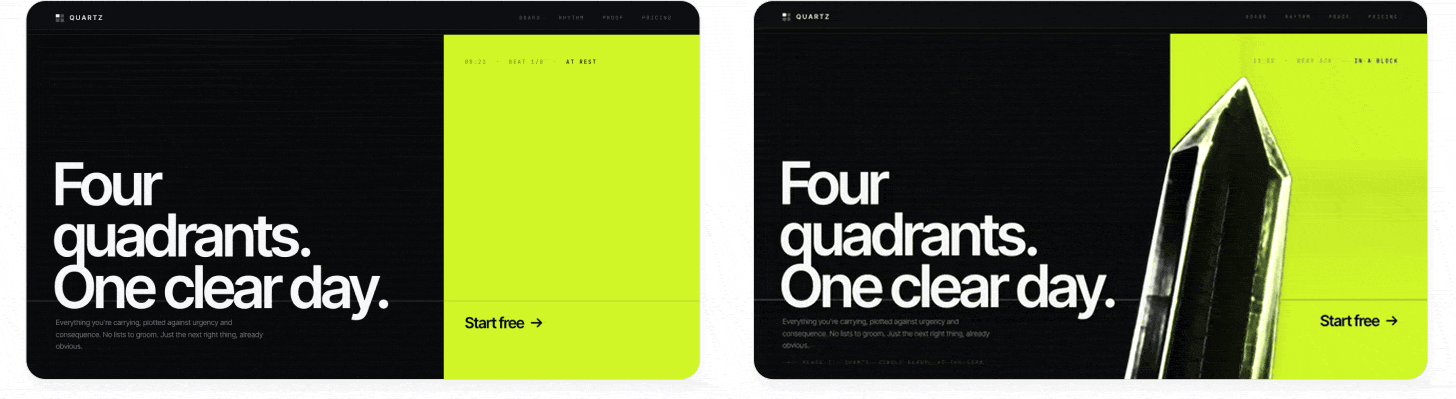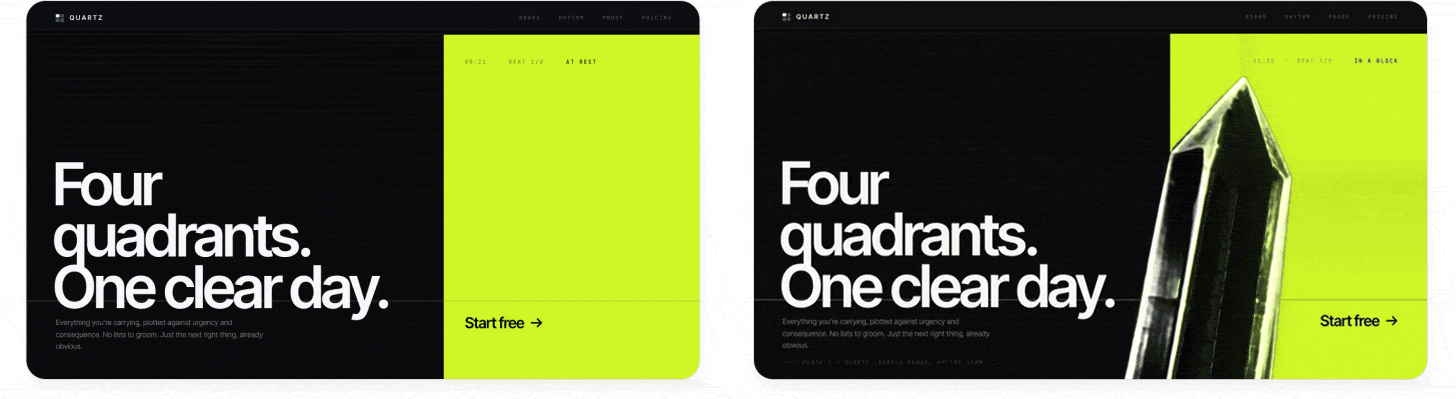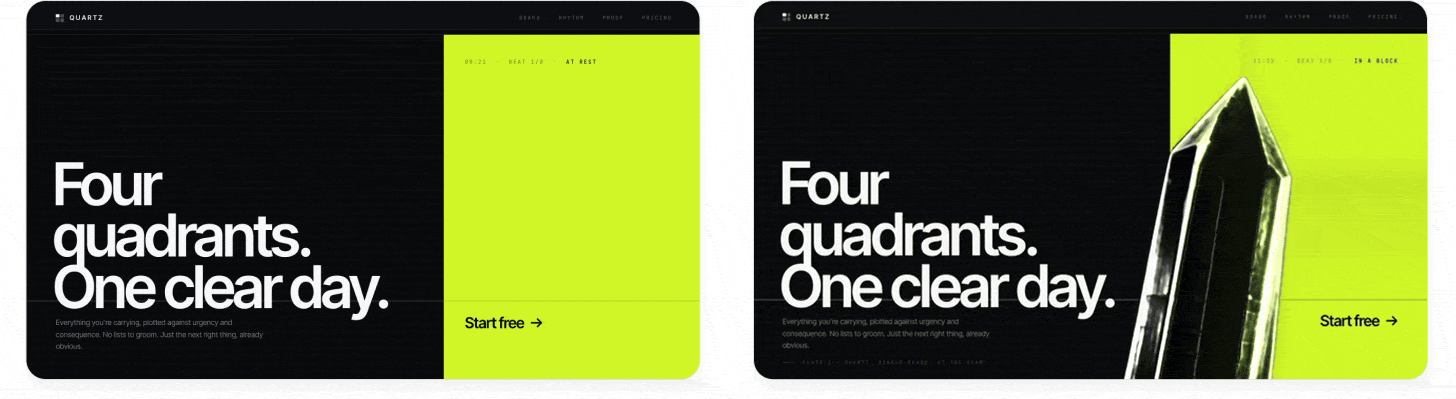
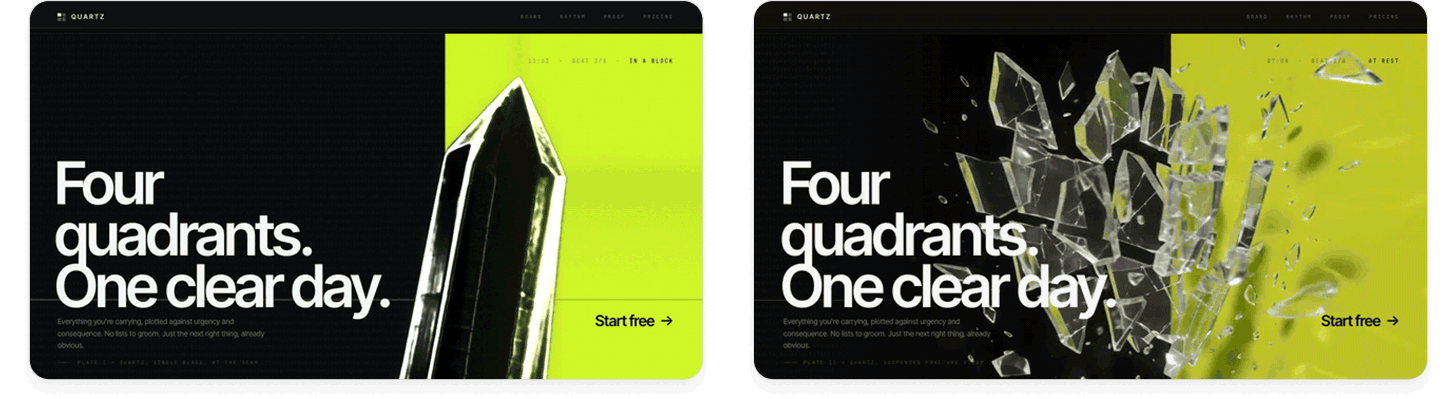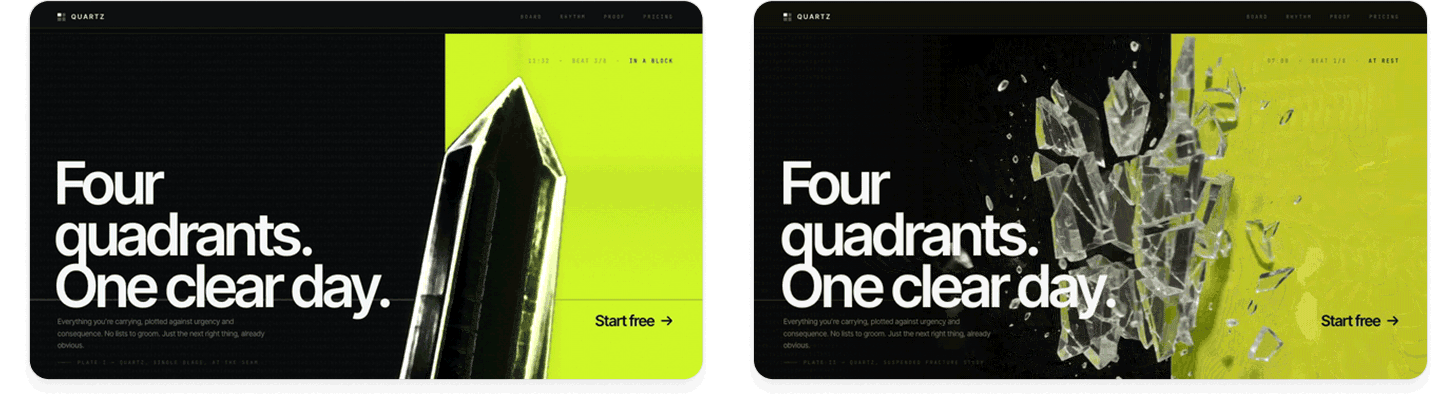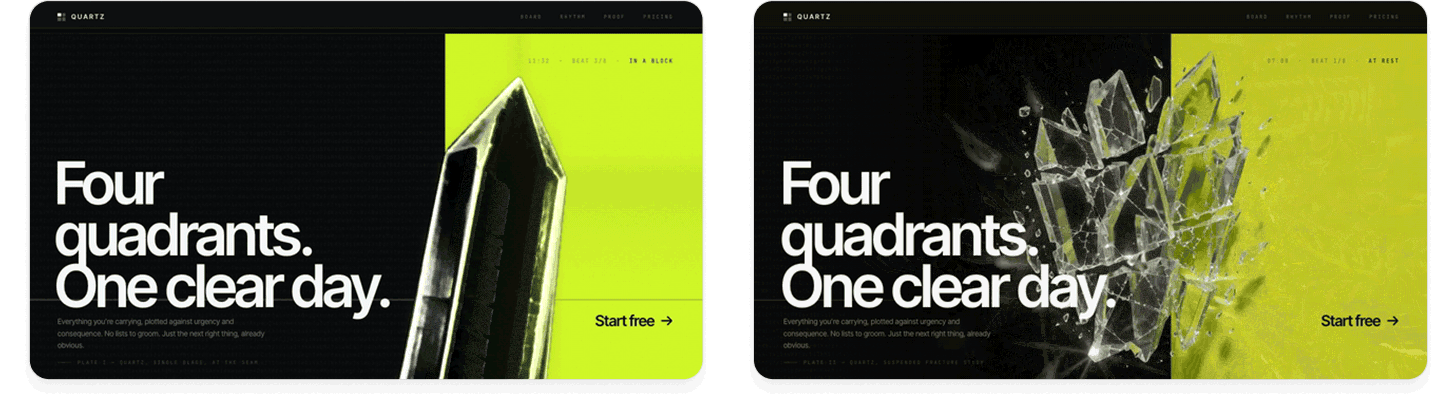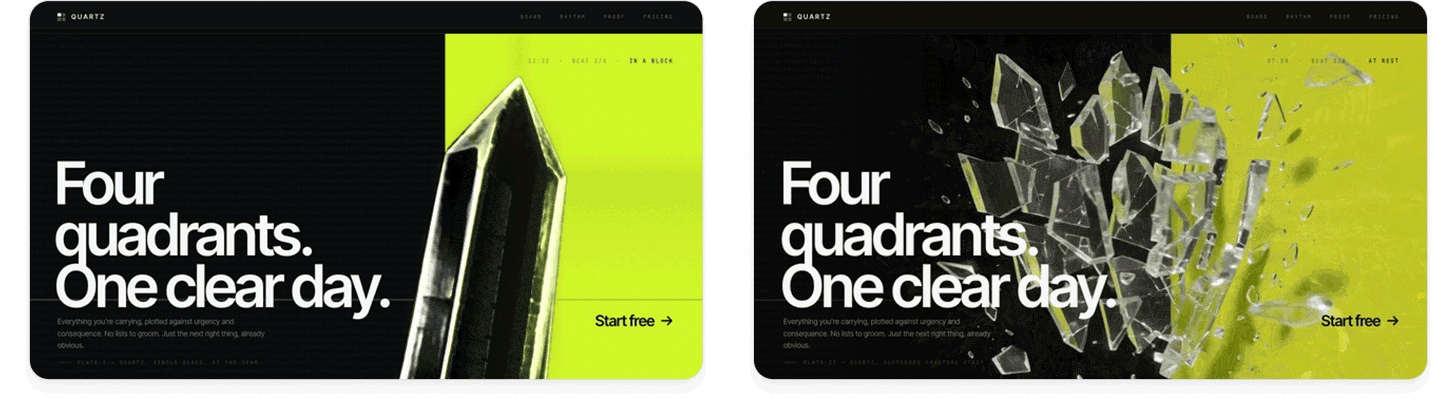
For example, I took one of our previous designs and ran this prompt:

Prompt:

Can you replace the image on this page with a looping video clip that does something more interesting? Have the crystal splinter apart and slowly spin around. It should have awesome glassy effects that refract the page background and cast shadows and light around it.

To get convincing glass refraction effects, render the video of the glass over the page background colors first (so it bakes in the refraction effects), then remove the background with a video matting model.

Use this fal.ai API key: sk-a1b2c3d4…

Find appropriate recent models for video generation and background removal.

GPT-5.6 Sol (before and after):

This is a much richer effect than you can get with code: interesting caustic reflections, glassy refraction effects, and complex physical motion.

Create fluid transitions between states

This is a really underrated use case for video models. In addition to generating video from text, many video models can interpolate between keyframe images. This lets you take two product stills and create a transition clip between them. You can play the clip when the user takes an action (like navigating to another screen of your app) or scrub through it frame-by-frame in response to a gesture (like scrolling or swiping).

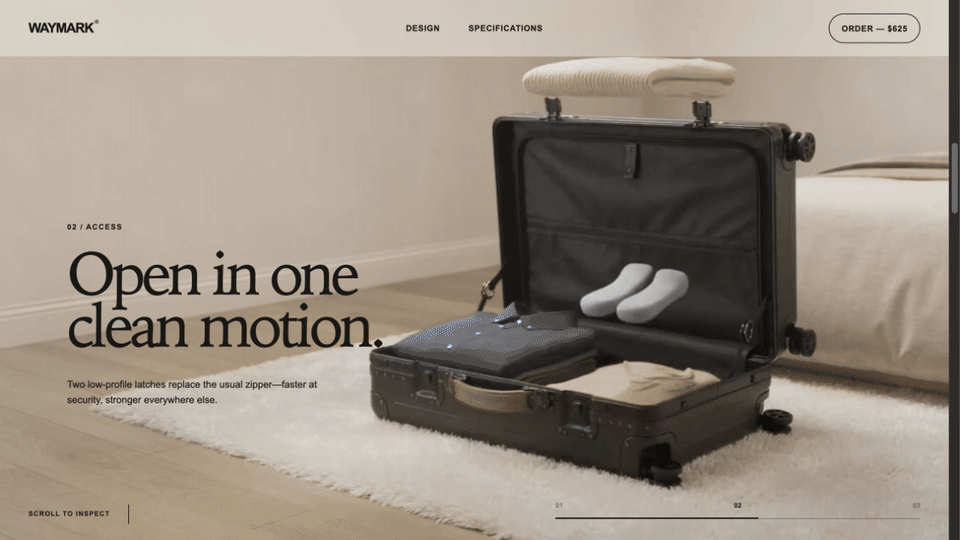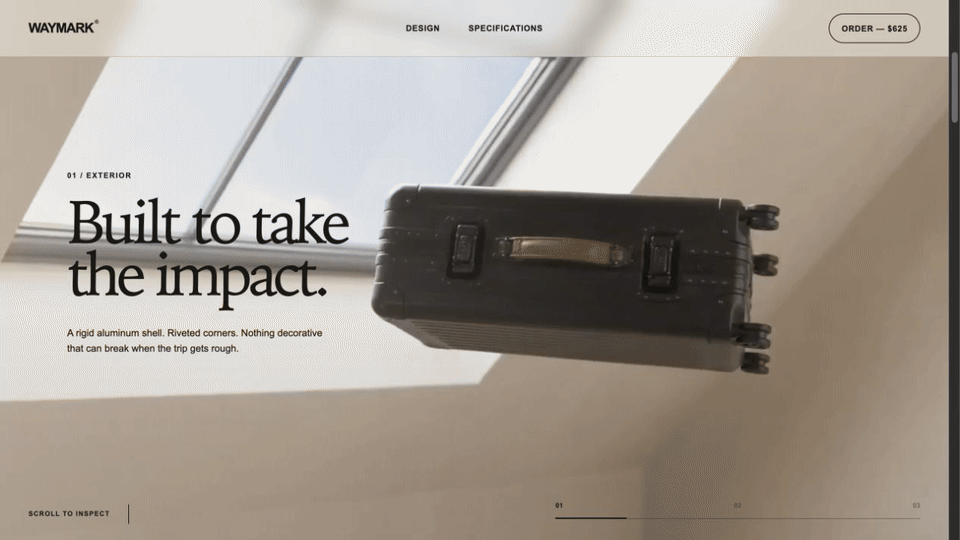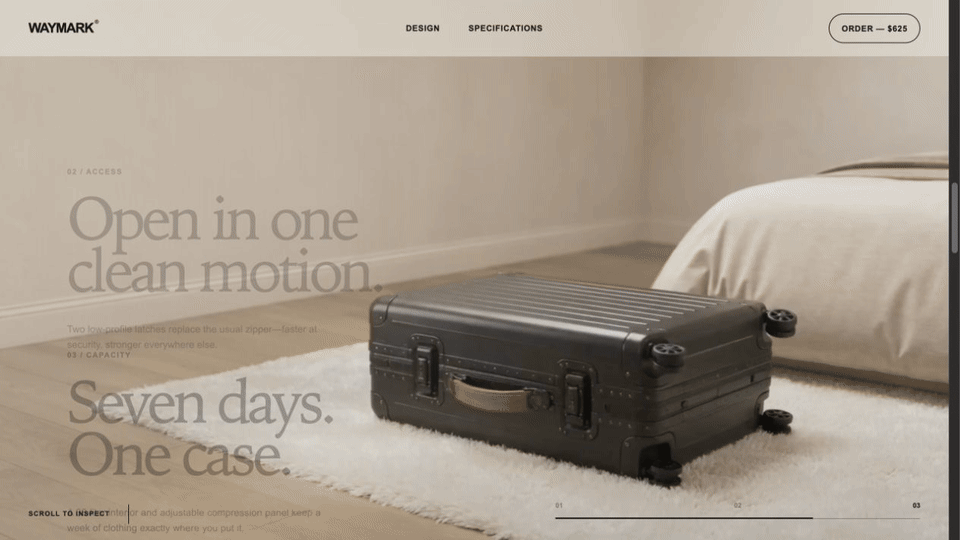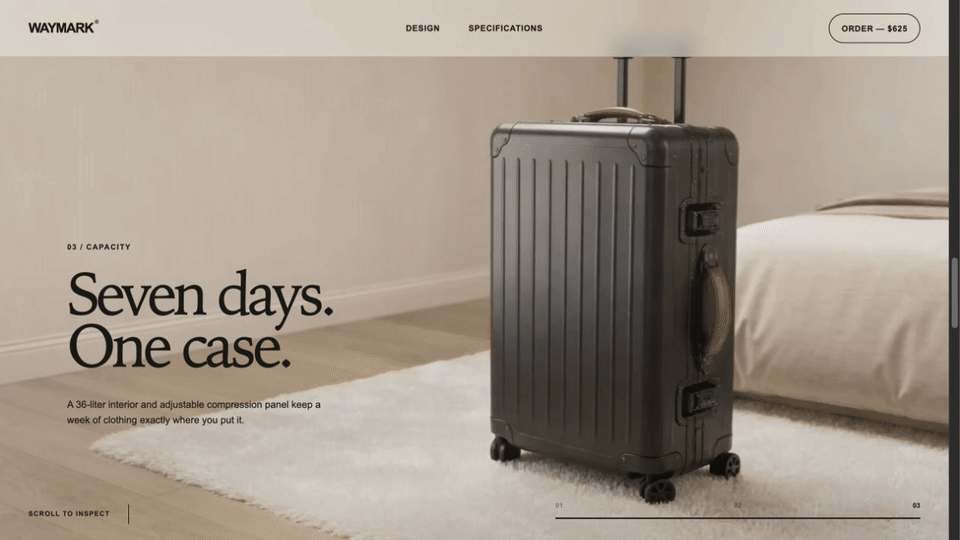
Here’s a demo page showing off a scroll effect. I built it with a single prompt using GPT-5.6 Sol in Codex:

Prompt:

Build a demo page for a suitcase that uses a video model to create interactive transitions between a couple of screens. Each screen should show the suitcase in a different state, with vertical motion that feels appropriate for scrolling:

  • Initially, have the suitcase floating high up in the air

  • Then have it land on the floor and pop open

  • Finally, have its contents neatly land into it from the top

Generate the initial frame using your image generation skill. Then, generate a video clip that starts from that frame and animates to the next state. Use the final frame of that video to seed the next transition so that it continues seamlessly. Scrub through the transitions one by one as the user scrolls.

Use this fal.ai API key: sk-a1b2c3d4…

Use a video model with strong physics and consistency, like Seedance 2.5.

GPT-5.6 Sol:

The transitions between pages scrub fluidly with the user’s scrolling and are fun to play with. Design like this makes the user want to keep scrolling and reading more about your product. And it only took one prompt!

Deliver: Polish your design into something users will love

Once we’ve gotten to a unique, standout design, the final step is to clean up the details and get it ready for production use. AI can build amazing, striking visuals, but your judgment will be key to making sure the design makes sense, flows well, and serves its practical purpose for your users.

Technique 6: Cut out elements that don’t add value

AI loves to add more, but it rarely takes away. One of the biggest signs that a design is AI-generated is that it overexplains everything or contains elements that don’t serve any practical purpose. By contrast, a design that exercises restraint immediately looks premium and tasteful.

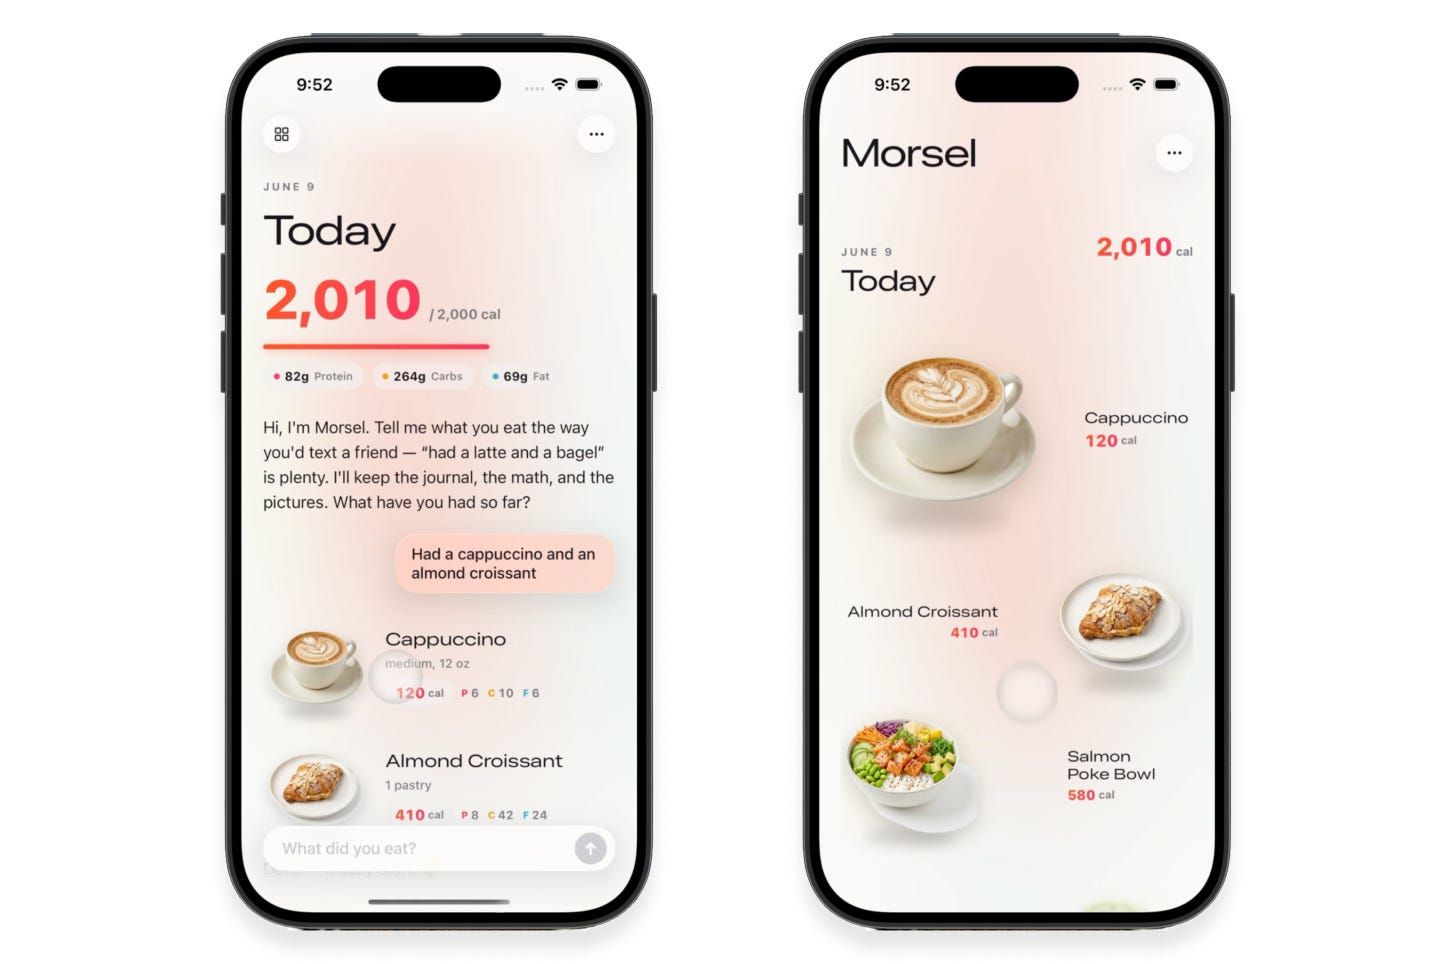
When polishing AI designs, most of my effort goes into removing things. For example, when I was building my calorie tracking app, this was my initial design from Claude:

I’d described the app’s functionality and specifically asked for a “clean, minimalist design.” The results weren’t bad, and were certainly impressive for being fully AI-generated. However, despite my asking for minimalism, a lot in the design wasn’t adding value:

  • Pink glowy effects in the background and on the progress bar

  • Random colors and highlights on text

  • Extra labels and empty space when displaying all the foods for a day, when the images already communicate this

  • Custom buttons and text fields that look worse than built-in iOS components

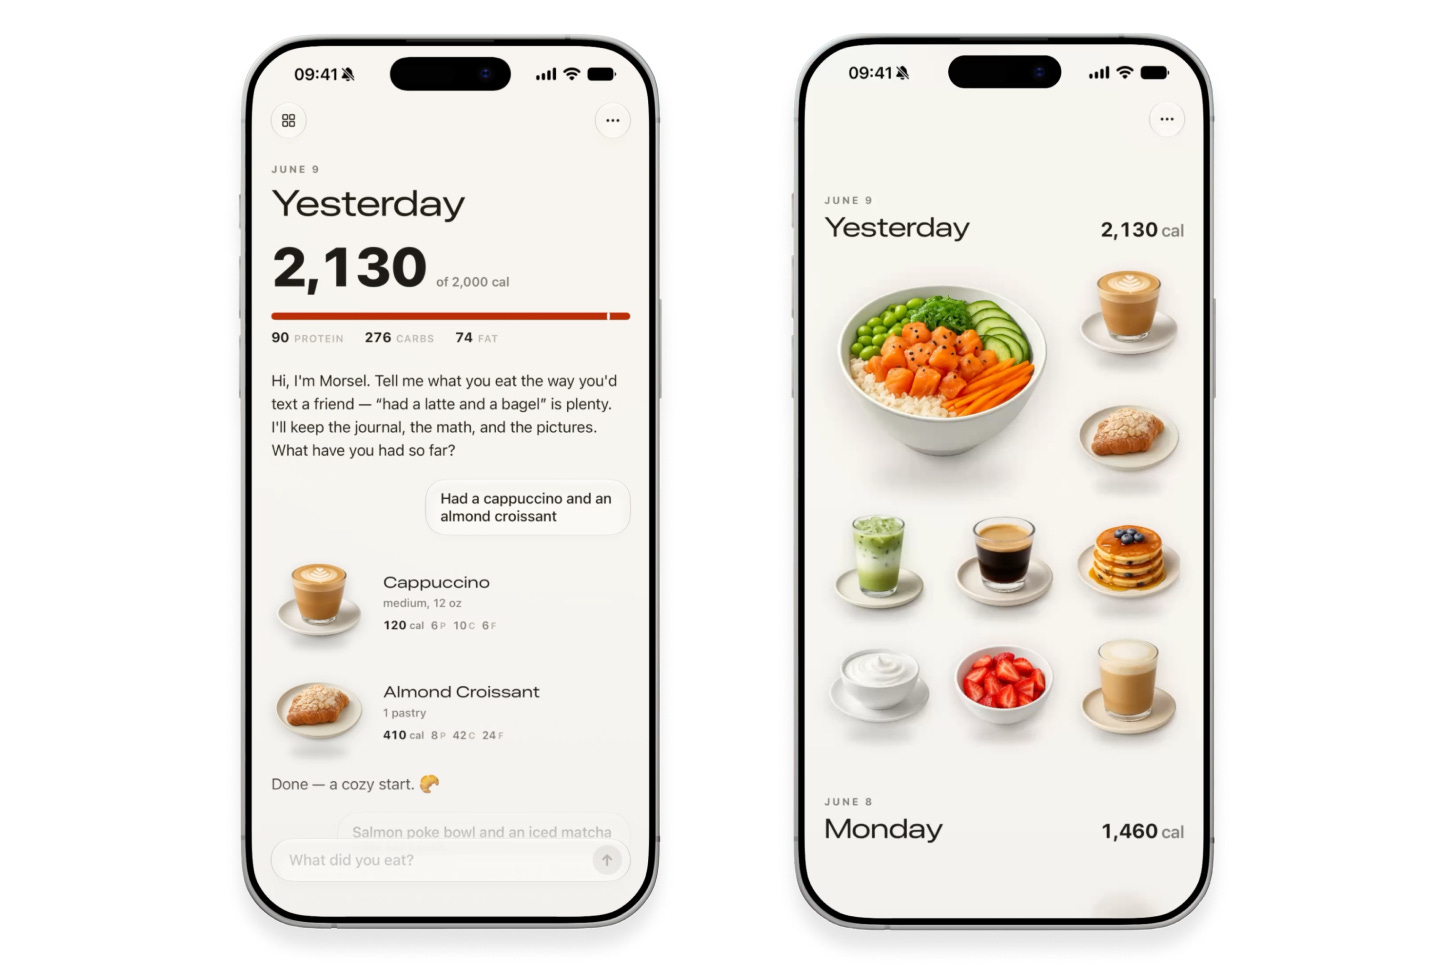
I asked Claude to dial things back:

  • Simplify the layout into an image-centric grid

  • Get rid of gradients, glows, and unnecessary containers

  • Aim for a truly minimalist aesthetic that feels Apple-native

This was the result:

To my trained eye, the result is much better. It’s opinionated and allows the visuals to speak for themselves. It uses native iOS components, and the excessive colors and gradients are gone. The text is smaller, simpler, and tighter. This is good design.

Today’s AI models would never think to make these choices on their own. Remember, AI doesn’t like to take risks, and it’s risky to strip down a design and delete code. The model needs a push from you. Look over your design and ask yourself what really needs to be there. Often, putting less on the screen communicates more, because you can hold your users’ attention without overwhelming them with clutter.

Technique 7: Remove AI tells

Read more
8

llm-gemini 0.34

Simon Willison · original → · 7/10 · AI: Gemini 3.8 Flash integration and thinking levels, work-relevant
2nd September 2026 - New model gemini-3.8-flash for Gemini 3.8 Flash, with low, medium and high thinking levels. #146- Fixed async responses failing to record the resolved model version. Thanks,…

2nd September 2026 - New model gemini-3.8-flash for Gemini 3.8 Flash, with low, medium and high thinking levels. #146- Fixed async responses failing to record the resolved model version. Thanks, Charlie Tonneslan. #137 Google released Gemini 3.8 Flash (and 3.8 Flash Cyber, but that's available to "trusted defenders" only) today. Here are the pelicans for high, medium, and low. This is high: For comparison, here are the same pelicans generated using Gemini 3.7 Flash. Something I appreciate about Gemini Flash is that it's fast, cheap, and competent at things like HTML and JavaScript. I was messing around with it and prompted "make me a cool thing in html" and it built this, which is certainly a cool thing in HTML! Took 13 seconds, cost 1.8 cents. If you click through to the demo you'll see one more thing I built with Gemini 3.8 Flash. My markdown-svg-renderer tool lets me feed in the URL to a Gist with Markdown in and renders that markdown with fenced code blocks for SVG correctly rendered. I used Gemini 3.8 Flash (with my very basic llm-coding-agent coding agent plugin) to add support for HTML as well, so now any HTML blocks in the Markdown are rendered using a sandboxed iframe. Here's the transcript. Recent articles - Claude's new system prompt really doesn't want to reproduce song lyrics - 2nd September 2026 - Claude Fable 5.1 made me a really nice animated pelican - 1st September 2026 - Understanding ChatGPT Work - 30th August 2026

Items scoring 7/10 or above from 11 sources, scored by claude-haiku-4-5-20251001 on relevance to my interests. At most 3 per source.

Scoring categories & sources
  1. Local Wexford or South East Ireland news
  2. Irish or EU-wide affairs affecting citizens broadly: elections, new laws or policy being debated, cost of living, education — especially impacts on mid-life adults or teenagers. Never courts/crime stories.
  3. Irish news on a topic relevant to my interests
  4. Work and tech topics: networking, AI, Kubernetes, platforms, SaaS
  5. AI news including critical or anti-AI perspectives
  6. Gaming: PC gaming, indie gaming, retro gaming
  7. General interests: gardening, woodwork, cycling, fitness, travel
  8. Comics

Sources: Breaking News Ireland, Wexford Local, Hacker News, r/gaming, r/pcgaming, r/antiAI, r/indiegaming, Lenny's Newsletter, One Useful Thing, Newcomer, Simon Willison

Comics

Handedness

XKCD · view →
A

A