daily

2026-09-02
1

Gorey stages Rás na mBan on Thursday

Wexford Local · original → · 9/10 · Local Wexford: Rás na mBan cycling event in Gorey
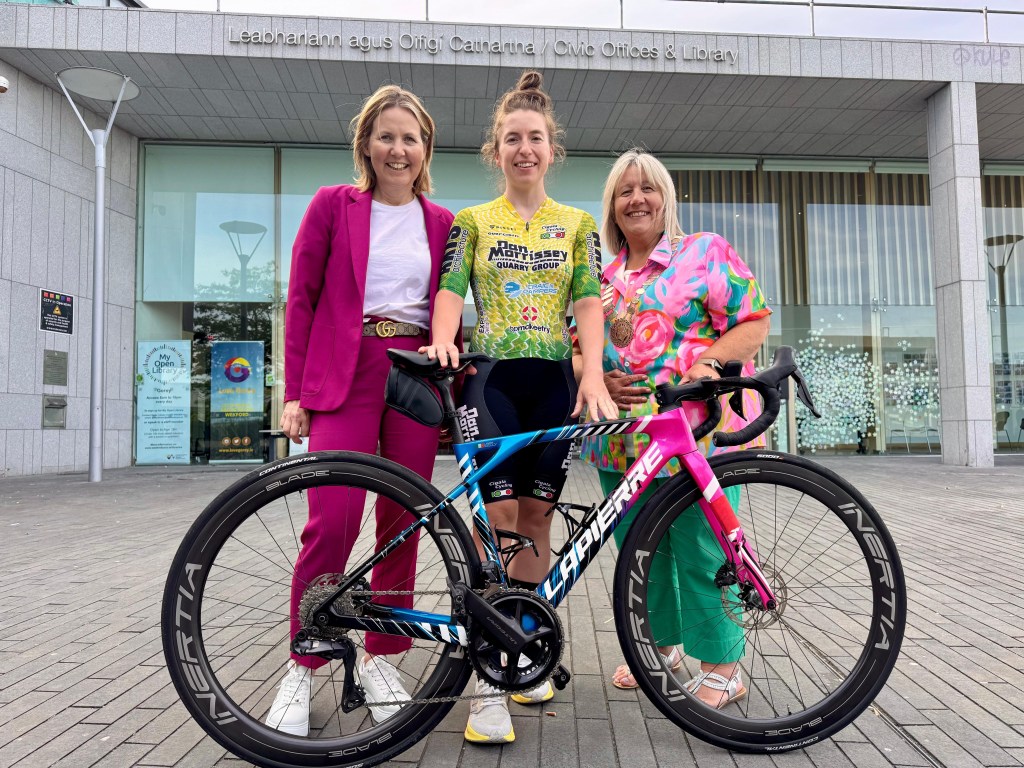
[image →]Pictured at the launch of Rás na mBan in Gorey were Race Director Valerie Considine, Linda Kelly and Cllr Mary Farrell, Cathaoirleach of Gorey Kilmuckridge Municipal District. By Dan Walsh…
[image →]
Pictured at the launch of Rás na mBan in Gorey were Race Director Valerie Considine, Linda Kelly and Cllr Mary Farrell, Cathaoirleach of Gorey Kilmuckridge Municipal District.

By Dan Walsh

Rás na mBan, Ireland’s premier international women’s cycle race, returns to County Wexford for the third year in a row as it marks its 20th edition.

Stage two of the 2026 event will take place on Thursday, featuring a new twist on a familiar route. Riders will set out from Gorey, taking on demanding climbs, fast racing and scenic roads before returning for a high-speed finish in the town.

The 97km stage starts with a neutralised rollout from Gorey District Park at 11am. Racing begins on the R772 towards Arklow, before the route turns to the day’s first competition: the Intermediate Sprint at the First World War memorial in Woodenbridge. From there, the riders continue towards Aughrim and the opening Queen of the Mountains test, a Category 3 climb at Rednagh.

The rolling course then leads to Sliabh Buí, the first Category 2 ascent of this year’s race. The 3.3km climb averages 4.4%, with sections reaching 18.6%. After the descent, more undulating roads take the riders through Ballycanew and back to Gorey, where the leaders are expected to finish at 1.16pm.

A cycling festival will run alongside the race, with Wexford County Council organising a programme of bike-themed activities in Gorey Town Park.

Cllr Mary Farrell, Cathaoirleach of Gorey Kilmuckridge Municipal District, welcomed the event’s return. “Gorey is honoured to host this prestigious international women’s cycling race. Having both the start and finish here gives us an excellent opportunity to showcase our town and Wexford’s renowned hospitality. I commend the Rás na mBan organisers and Wexford County Council for bringing elite women’s sport to our roads and inspiring future generations of female athletes.”

Race Director Valerie Considine said: “We’re delighted to bring Stage 2 of Rás na mBan back to Wexford. Our previous visits have been both memorable and rewarding. This year’s revised route, which remains entirely within County Wexford, will increase the challenge while showcasing the striking scenery for riders and spectators alike.

“Wexford’s heritage, landscape and warm welcome make it an ideal location for top-level racing. I also thank Wexford County Council and An Garda Síochána for their invaluable support in making the stage possible.”  

2

Academic resigns from Leaving Cert maths reform group over ‘incoherent and inaccurate’ courses

Breaking News Ireland · original → · 8/10 · Irish education: Leaving Cert maths reform affecting teenagers directly
Associate Professor of Mathematics Education at DCU, Aoibhinn Ní Shúilleabháin, who has stepped down from the Mathematics Development Group, which advises the National Council for Curriculum…

Associate Professor of Mathematics Education at DCU, Aoibhinn Ní Shúilleabháin, who has stepped down from the Mathematics Development Group, which advises the National Council for Curriculum Assessment, said she did so because she was not prepared to be associated with a document of such poor quality that was “incoherent and mathematically inaccurate. “I think it will do a disservice to our young people,” she told RTÉ radio’s Morning Ireland. “It will fail to adequately prepare them for their future lives in society and work and study because mathematics underpins so many aspects of our world but particularly STEM which is so important to our economy. And I think at the heart of this, it’s a systems issue. “Subject experts are not formally or consistently included in any subject development group.” Ní Shúilleabháin said that the work being done by the Mathematics Development Group was “hugely important”, as its role was to effectively draft the new maths curriculum specification for the way maths was being taught in schools. “Mathematics is a human endeavour like all other subjects and it’s important that we look at what we are teaching our young people, consider is it of value to them, is it going to prepare them for their future lives in society, in work, in study and consider then what is it that we should be asking them to learn or the skills we ask them to build while they are in school.” In January, Professor Pauline Mellon also left the group expressing similar concerns. Ní Shúilleabháin pointed out that experts were being asked to participate in curriculum changes, but their contributions were being ignored which had led to “frustrations and resignations” in other science subjects. “I’m very worried about the lack of rigor or the reduction in content and abstraction that we have for our high achieving students, this seems to be a systems issue. “There were excellent people on this group and I want to absolutely say that I very much enjoyed working with people on the group and there’s some excellent teachers on the group and that is necessary. “However, the balance of subject matter experts has to be there with pedagogy experts and teachers, as is done in most other countries where you have a good balance of subject experts and teachers. But in this case, it’s the decision-making processes that continue to be opaque. “Within the group, if people made suggestions, you would not understand or realise if they would be adopted or not, if they were agreed with or not, if they would be ignored or not, because mathematical errors, as an example, were independently and objectively corrected by separate members of this group and that has been consistently ignored.” When asked if efforts were being made to dumb down the Leaving Cert maths course, Ní Shúilleabháin said she did not like such language, but there had never been an opportunity to ask what would students need in 10 years time. “They’re going to be graduating at a time or coming into a world of work at a time that is data-driven and AI-based. “Is there mathematics topics or mathematical skills that we are not teaching them currently that will benefit them into the future? That discussion was not had, and I think that’s to a detriment of our young people.” The decision-making process on the curriculum was very opaque, she added. It was not known within the subject groups what suggestions, proposals or corrections would be accepted. “If I had trust that after the public consultation, fundamental changes could be made to this curriculum and errors corrected and the content made coherent, I would have stayed. But I do not trust that that is the process.” Ní Shúilleabháin said she “consistently” shared her concerns with the Mathematics group and members of the NCCA and had requested a meeting with the Minister for Education. “My concerns go beyond mathematics. I also think that we should be really preparing our young people for the climate and nature crisis that are ahead. “If we look at our biology curricula, plant-based science has been reducing in content consistently. That’s because the subject matter experts aren’t there. This is a systems problem with how we design our national policy documents that are our curriculum documents for secondary schools.” Prof Pauline Mellon of the UCD School of Mathematics, who earlier this year resigned from the Mathematics Development Group which advises the National Council for Curriculum Assessment, said she had resigned because the process was not fit for purpose and she could not give her stamp of approval to the curricula in that state. “I was concerned, first of all, about the state of the curricula at the time. There were problems with all three levels, foundation, ordinary and higher,” she told RTÉ radio’s Today with David McCullagh show. “And at the same time, I could see that feedback was not being taken on board. I had exhausted every possible avenue to try and get my voice heard. And I resigned because I feel they’re not fit for purpose. And I can’t give any stamp of approval to the curricula in that state.” Advice was not listened to, everything was very tightly controlled, she added. “There was, I believe, lack of engagement. Unfortunately, I think there’s a wider problem with the process, which is intrinsic to what’s actually going on. “The NCCA do not routinely or formally or systematically in any way involve subject experts. There’s very few. So there might be 20 people around the table with only one or two subject experts. And that’s not that doesn’t appear to be accidental because similar concerns have been raised with other subjects.” Mellon said she had tried to raise her concerns within the group and had produced several documents, as did other members of the group, but those documents and feedback seemed to “go into a black hole.” “Nothing was ever circulated to a group. So there was it seemed to me that the (2:47) NCCA personnel were trying to control the outcome.” There had been feedback from different cohorts, she said, but it had not been allowed to be shown to those who were tasked with writing the syllabus. “We were told that that was NCCA policy, that the public consultation feedback couldn’t be provided to the members of the group tasked with writing the syllabus. “So I’m afraid I have no faith in the public consultation process. “There was no opportunity to say, look, we’re now in an increasingly data-driven world. The rise of AI, we should really consider what’s the mathematics behind this? What is going to enable students to engage in this data-driven, AI-driven world? “We should have been looking at those kinds of broader questions. I can guarantee you that not a single minute of the 17 months I was on the committee was allowed to be given to any such broad considerations.” Mellon said she had particular concern about higher level maths. “I think there’s so much material has been cut, very poorly specified. “A particular concern is that what I would describe as the essence of mathematics is really diminished.” On the same programme, Humphrey Jones, head of biology and science at St Columba’s College, said similar frustrations had been experienced by members of the committee tasked with creating the science syllabus. Consultation data submitted by development groups was not included in the final documents, he said. Under Freedom of Information, his group had found that none of the information produced was included in the final document from the NCCA. “We have our frustrations as well. Members, representatives of the Irish University Association within the science specifications for biology, chemistry and physics, all of them formally dissociated from the final specification in protest for what was being produced as well. “So again, they’re subject experts and they’re not happy with the final documentation either.”

3

Claude Fable 5.1 and Claude Mythos 5.1

Hacker News · original → · 8/10 · AI: Claude Fable 5.1 advanced coding and knowledge work model
We’re introducing Claude Fable 5.1 and Claude Mythos 5.1. They’re the world’s most advanced models for coding and knowledge work—and their research capabilities offer an early glimpse of how AI…

We’re introducing Claude Fable 5.1 and Claude Mythos 5.1. They’re the world’s most advanced models for coding and knowledge work—and their research capabilities offer an early glimpse of how AI models will contribute to scientific progress. Claude Fable 5.1 and Claude Mythos 5.1 are the same model, but with different levels of safeguards. Fable 5.1 is generally available, while Mythos 5.1 is available only through our trusted access programs; its safeguards are specifically designed to support work in cybersecurity and the life sciences. Alongside its increased capabilities, Fable 5.1 takes important steps towards addressing the feedback we’ve received from customers on price, data retention, and safeguards. Price. Fable 5.1 will cost an estimated 25% less than Fable 5 for typical workloads, wherever usage is billed by token. This is because we’re reducing our pricing on cache reads (where the model reads inputs that have already been processed and stored). For highly agentic work, the savings will often be much larger—up to approximately 45%. Data retention. Our new system of Enterprise Frontier Safeguards (EFS) gives customers complete privacy (the same as a zero data retention policy) while still being state-of-the-art at preventing adversarial use. EFS works by storing data in cloud infrastructure controlled entirely by the customer, not Anthropic. It will be made available to enterprise customers in phases, beginning later this fall. Until EFS is available, eligible customers will be able to use Fable 5.1 with zero data retention. Safeguards. We’ve improved our safeguards to reduce false positives (where the system flags benign content). In cybersecurity, our newest safeguards block 60% fewer false positives than before. In part, this is because Fable 5.1 can now be used to discover software vulnerabilities—though not to develop exploits for them. In biology, we’ve established an access program, developed in partnership with the US government, to enable access to Claude Mythos 5.1’s advanced biology capabilities. We expect to open enrollment for scientists soon. A new performance frontier Claude Fable 5.1 sets a new standard for coding, knowledge work, and long-running problem-solving tasks. The charts below show that Fable 5.1 is capable of much higher performance than its predecessor, Fable 5. And when set to Low or Medium effort, Fable 5.1 achieves results similar to or better than Fable 5’s at a much lower cost. (Note that Fable 5.1 defaults to High effort in Claude Code, and to Medium in Claude Cowork and on Claude.ai.) Fable 5.1 avoids shortcuts that result in poorer-quality work, and it’s smart enough to fix the root causes of software issues. For example, in testing by the investment firm Millennium, Fable 5.1 found the cause of a rare crash in its internal systems that none of its engineers (or any other model) had been able to explain after several years of trying. Here, you can see how Fable 5.1 compares across various benchmarks: | Fable 5.1 | Fable 5 | Opus 5 | GPT-5.6 Sol | | |---|---|---|---|---| | Agentic scientific researchTerminal-Bench-Science 0.1 [1] | 52.6% | 24.7% | 29.0% | 22.4% | | Agentic codingTerminal-Bench 4.0 | 55.8%60.9% (Mythos 5.1) | 42.0% | 52.3% | 37.3% | | Knowledge workGDPval-AA v2 | 1853 | 1723 | 1824 | 1711 | | Computer useOSWorld 2.0 [2] | 77.9%partial | 72.9%partial | 75.4%partial | —partial | | Computer useOSWorld 2.0 | 41.7%strict | 36.1%strict | 39.6%strict | —strict | | Multidisciplinary reasoningHumanity's Last Exam | 60.9%no tools | 57.8%no tools | 56.6%no tools | —no tools | | 65.0%with tools | 63.8%with tools | 63.6%with tools | —with tools | | | Business workflowsAutomationBench | 31.4% | 17.1% | 26.9% | 19.6% | | Agentic codingCursorBench 3.2.0 | 73.4% | 70.5% | 70.0% | 67.2% | Our early-access partners noticed these performance upgrades, and also picked up on more qualitative improvements in the model’s outputs. Here’s what they told us: 1 of 22 Scientific research We tested the scientific research capabilities of Claude Fable 5.1 and Claude Mythos 5.1 across a wide range of domains. What we found—which includes the early examples we share below—adds to the evidence that AI models will soon make important contributions to scientific discovery. Molecular design. Many modern medicines work by binding to targets within the body to block, activate, or deliver something to them. High-affinity binders are necessary for drugs to work at lower doses; designing one is the first step in the development process for many common drug modalities. To see how well Claude Mythos 5.1 could do at this task, we gave the model access to open-source protein design and folding tools and sent its designs to two external organizations for experimental validation. Mythos 5.1 proved able to design very high-affinity binders. On three targets, [3] its binding affinities were 10 times higher than the best designs submitted to Adaptyv Bio’s protein design competitions. Its hit rate (that is, the number of designs that were viable binders) was the strongest we’ve measured to date: it reached nearly 50% across 12 targets. (Hit rates of 10–15% are typical in protein design today.) Computational analysis and modeling. Claude Fable 5.1 trained a neural network to create a new, high-resolution elevation map of a third of the planet Venus. Its work was based on radar images taken by NASA’s Magellan mission more than 30 years ago and a map that already existed for one-fifth of the planet. Claude’s new map now reveals details down to two to three kilometers, rather than 10 to 20, and shows heights up to 25% more accurately than before. We’re releasing this map under a Creative Commons license in advance of upcoming NASA VERITAS and ESA EnVision missions, in hopes that it might help them determine which geologic features to target for future observation. Computational biology. In computational biology, it’s common to run task-specific machine learning models on GPUs. The speed of these models is therefore a bottleneck to research progress. Mythos 5.1 provided one solution to this problem: by writing custom GPU kernels and caching their intermediate results, it sped up seven open-source deep learning models by up to 2.5 times (with identical outputs). The benefits of such speed-ups accumulate quickly. In any given experiment, biologists might run these models thousands of times (for example, testing every possible mutation near every human gene). On analyses like these, the optimized models cut estimated GPU costs by 30–60%. This kind of optimization would normally take a team of performance engineers weeks, and is often unaffordable for academic labs. Mythos 5.1 was able to do it in just days, using the publicly available source code alone. We plan to open-source these optimizations soon. As our models’ scientific capabilities improve, our investment in scientific progress is also growing. Last week, we previewed the Model Hardware Standard, which allows Claude to directly and safely operate laboratory equipment. We’ve also recently expanded our support for scientists through our AI for Science program, which provides free credits to researchers working on high-impact scientific projects, and we are offering steeply discounted usage through our new Claude Team plan for scientists. Safety, security, and alignment AI models’ agentic capabilities have become much more powerful over the past two years. But as we’ve documented, greater autonomy comes with new risks. Work on safety, security, and alignment needs to advance at the same pace as AI capabilities. Yesterday, we published a report describing how we are improving our own alignment and security efforts Prior to releasing Claude Fable 5.1 and Claude Mythos 5.1, we (and, in some cases, external researchers) subjected the models to extensive testing for risks across many areas. We describe these efforts in full in our System Card; below is a brief summary. Chemical and biological risks. We tested the extent to which Claude Mythos 5.1 could help create chemical or biological weapons. This involved expert red-teaming, automated evaluations, and a tabletop exercise that paired PhD-level biologists with AI experts, testing whether the models could match human specialists’ performance. Mythos 5.1’s capabilities are greater than those of Mythos 5. However, our evaluations indicate that it still falls short of the next risk tier defined in our Responsible Scaling Policy. We are therefore deploying Mythos 5.1 with the same safeguards that we applied to Mythos 5, which restrict access to research biology capabilities. Cyber risks. We ran a suite of evaluations to assess the cyber capabilities of Claude Mythos 5.1 (with cybersecurity safeguards off). Overall, the model demonstrates the strongest cyber capabilities of any model we’ve released, though it still falls within the lower category of risk in our Frontier Compliance Framework. We also performed extensive stress-testing of our cybersecurity safeguards for Fable 5.1: in addition to our own dynamic evaluation of their robustness, we commissioned external testing from two organizations, along with automated testing by Gray Swan. As with Fable 5 and Opus 5, we have not found evidence of a critical-severity jailbreak for these safeguards. Agentic safety. We ran evaluations of how Claude Mythos 5.1 responds to malicious requests and prompt injections (adversarial instructions hidden within content processed by AI models). It refused malicious agentic coding and computer use requests at a comparable rate to Mythos 5, Sonnet 5, and Opus 5, and it is our most robust model to date on an external prompt injection benchmark. Alignment. We tested the model’s behavior through static and interactive behavioral evaluations, analyses of its internal thinking using natural language autoencoders, misalignment-related capability evaluations, a review of our training data, and analyses of our internal pilot use. We also received reports from external testing. Our automated behavioral audit found that Claude Mythos 5.1 is better aligned across most metrics than its predecessor, Mythos 5. The model is significantly less likely than Mythos 5 to try to access resources outside of its test environment when assigned an otherwise impossible task. It is also less likely than Mythos 5 to use motivated reasoning to justify its actions (for instance, by reasoning that the situation is a simulation or evaluation), and it is less likely to ignore explicit constraints in pursuit of users’ goals. From our review of its training data, Mythos 5.1 both attempts reward hacking (or cheating), and succeeds at it, at a lower overall rate than Mythos 5. Though generally our alignment evaluations showed improvements, our testing found the model can still sometimes bypass approvals and auto-mode classifiers (as we discuss in more detail in our System Card). There are also limitations to the coverage provided by our alignment assessment. Currently, our automated behavioral audit provides less visibility into very long-context work and multi-agent settings. We also have less coverage of impossible tasks (which can elicit more abnormal and misaligned behavior) than we’d like, although we’ve recently made improvements in this domain and are working hard to continue doing so. We have also improved our safeguards so that they allow our models to be more useful without compromising on safety. We describe these changes below. Automated safeguards for enterprises. Enterprise Frontier Safeguards (EFS) allows us to detect and respond to misuse of our models while still providing our enterprise customers the privacy of a zero data retention agreement. With EFS, customers store their data on their own cloud infrastructure, rather than on Anthropic’s systems; any human review is, by default, done by the customer themselves, rather than Anthropic. We developed EFS in close collaboration with more than 100 customers across industries like financial services, healthcare, manufacturing, telecom, law, retail, and the public sector, and with our cloud partners at Amazon Web Services, Google Cloud, and Microsoft Azure. EFS will be supported on Claude Code, Claude Enterprise, the Claude Platform, Amazon Bedrock, Claude Platform on AWS, Google’s Agent Platform, and Microsoft Foundry. It’s rolling out in phases, starting this fall. As noted above, customers who are eligible for EFS can use Fable 5.1 (and Fable 5) with zero data retention until EFS is ready. You can read more about EFS here; to request access, please complete this form. More precise safeguards for biology and cybersecurity. In the past few months, we’ve made progress in making our safeguards for Fable 5.1 more precise: ensuring that they’re less likely to flag benign content (like queries about medical issues or cyberdefenders using the model to make their systems safer), but still ensuring they provide robust protection against genuine threats. As we recently shared, our latest biology safeguards for Fable 5.1 and Fable 5 fire 85% less often for benign requests related to elementary biology and medical questions (relative to those that launched with Fable 5). However, queries related to research and development in the life sciences will still be directed to our Opus models. We’re making the model’s life sciences capabilities available to professionals through an access program for Claude Mythos 5.1 that we’ve developed in partnership with the US government, which we discuss below. With Fable 5.1, we’re updating our cybersecurity safeguards to be more precise. We’re also now allowing Fable 5.1 to be used for identifying software vulnerabilities—that is, to conduct the kind of defensive work that improves software security. As a result of these changes, Claude Code users can expect an average of around 60% fewer interventions per session from our cyber safeguards, relative to the previous safeguards on Fable 5. Our safeguards do, however, still redirect several kinds of dual-use cybersecurity tasks (tasks that might have helpful or harmful applications) to our Opus models. This includes penetration testing, exploit generation, and binary-based vulnerability scanning. Anti-distillation mechanisms. Distillation is a method used to extract the capabilities of advanced models. It is often employed on an industrial scale, using thousands of fake accounts. Distillation is a safety risk, since the distilled capabilities can subsequently be released without adequate safeguards. Fable 5.1 comes with strengthened mechanisms to make distillation attacks harder. For example, it is no longer possible for new API accounts (those created from today onwards) to manually edit Claude’s prior context in a multi-turn conversation while preserving the transcript of Claude’s prior thinking. This closes off a common, publicly documented distillation technique, which allowed distillers to illicitly extract Claude’s thinking. We’re rolling out the change gradually, to minimize disruption: existing accounts are not currently affected by this change, though it will apply to all users with future model releases. A small number of customers’ custom integrations will then be affected. Our Help Center article explains more about this change and the adjustments that developers can make. Trusted access for Claude Mythos 5.1 Claude Mythos 5.1 is identical to Fable 5.1, but it offers more permissive safeguards for vetted individuals and organizations whose work is affected by the cybersecurity and life sciences restrictions outlined above. It will be available through two trusted access programs: - Cyber Verification Program: The CVP currently provides access to certain Opus- and Sonnet-class models with reduced cyber safeguards for defensive security work. In the near future, this program will also include access to Claude Mythos-class models. Apply to join the CVP here. - Life Sciences Verification Program: The LSVP is designed so that life sciences professionals can use Claude Mythos 5.1 with safeguards designed for professional research and development activities (while all other safeguards remain in place). In partnership with the US government, we have enrolled our first participants, and we plan to expand access to this program to the broader life sciences community. In addition to these trusted access programs, Claude Security, our product that scans codebases for vulnerabilities and suggests patches for human review, is now also powered by Claude Mythos 5.1. Compliance with the EU AI Act In July 2026, Anthropic (along with 190 other signatories, including several other major AI model providers) signed the EU AI Act’s Code of Practice on Transparency of AI-Generated Content. This required us to add a watermark—a numerical way of determining the likelihood that Claude was involved in writing a piece of text—to the outputs of models released after August 2, 2026. As we recently explained, this watermark is invisible to anyone who does not have the detection API. It has no practical impact on the quality or content of Claude’s outputs and contains no information about the user, their organization, or their conversations with Claude. The Act also required us to provide a way for users to tell whether a text likely contains the watermark. We are thus rolling out a detection API in private preview. It is currently available to eligible organizations (such as regulators, law enforcement, media, fact-checkers, independent researchers, educational organizations, and EU civil society groups) as required under EU law. It is also available for enterprises that are similarly obligated to verify watermarking for their own compliance with the Act. We plan to expand access to the detection API over time. You can register interest in access here. Cost and availability Claude Fable 5.1 is available today on all platforms, including Amazon Web Services, Google Cloud, and Microsoft Azure. Developers can get started with claude-fable-5-1 on the Claude API. As mentioned above, we have reduced the price of Fable 5.1’s cache reads (where the model reuses context it has already processed) wherever usage is billed by token, such as on our API. Cache reads now cost 75% less, or $0.25 per million tokens. This change leads to a substantial reduction in the overall cost of running the model. For typical workloads, costs are reduced by around 25% relative to Fable 5. For complex coding and highly agentic tasks, the savings could be up to around 45%. The graph below illustrates why this change makes such a big difference: Fable 5.1’s pricing is otherwise the same as Fable 5’s: $10 per million input tokens and $50 per million output tokens. In parallel, we’re continuing our work to bring many of the improvements of Fable 5.1 to the rest of our model family. As discussed above, Claude Mythos 5.1 is available to vetted cyberdefenders and life scientists. Currently, it is only available to a set of US organizations, though we’re coordinating with the US government to expand access to a broader set of domestic and international partners as quickly as possible. To register interest in access to Claude Mythos 5.1 for cyberdefense through the CVP, head here. Get started Footnotes 1 Terminal-Bench-Science 0.1: The standard error is ±3.5–4.5 pts per model. The public leaderboard (3 trials/task, Claude Code harness) reports Claude Opus 5 at 30.0% and Claude Fable 5 at 21.4%; our setup reproduces them at 29.0% and 24.7%, respectively, both within noise. 2 OSWorld 2.0: Scores are on the benchmark authors’ August 2026 task release; Fable 5 and Opus 5 were re-run under the same conditions. Because the task files differ from earlier releases, these numbers aren't directly comparable to previously published OSWorld 2.0 results, which is why no competitor score is shown 3 These three targets are (EGFR, Nipah G, 15-PGDH) and come from Adaptyv Bio’s protein design competitions. The Nipah G comparison is against de novo designs targeting the receptor-binding site on the G head (best: ~8–12 nM, N1032). A de novo entry from Nick Boyd/Escalante Bio that targets a different region (the stalk) reached ~1.4 nM (design_7), comparable to our best binder. Further reading 1. The Claude Fable 5.1 and Claude Mythos 5.1 system card. View card 2. More detail on our Enterprise Frontier Safeguards. Learn more 3. Request access to our Enterprise Frontier Safeguards. Open form 4. An overview of our improvements to our biology safeguards. Learn more 5. Support for scientists. Read more 6. Earlier work by Claude in protein design. Read more 7. Earlier work by Claude in mathematics. Read more 8. More about the Model Hardware Standard. Learn more
4

Public service industrial action could be under way by month’s end, says Fórsa trade union

Breaking News Ireland · original → · 7/10 · Irish affairs: public sector pay dispute affecting citizens broadly
Public service industrial action could be under way by the end of the month over the absence of a new pay deal, the general secretary of Fórsa, the State’s largest public sector union, has said…

Public service industrial action could be under way by the end of the month over the absence of a new pay deal, the general secretary of Fórsa, the State’s largest public sector union, has said Kevin Callinan said he expected it would be “a very long dispute” and “one that will have very serious effects right across the public sector”.

5

My local model setup on an M4 Pro Mac Mini

Hacker News · original → · 7/10 · AI/networking: local LLM setup on Mac with inference server
I run a local LLM server on my M4 Pro Mac mini with 48 GB of RAM. It handles everything from my Hermes agent backend to quick chat queries on my phone. The whole thing takes about 30 minutes to set…

I run a local LLM server on my M4 Pro Mac mini with 48 GB of RAM. It handles everything from my Hermes agent backend to quick chat queries on my phone. The whole thing takes about 30 minutes to set up. Here is the stack: - Qwen3.6-35B-A3B-OptiQ-4bit: my main model for anything that needs reasoning or depth - Gemma-4-E4B-it-OptiQ-4bit: lightweight model for simple chats, formatting, and other routine tasks - oMLX: the inference server - Tailscale: tailnet connecting the Mac mini, my iPhone, and my MacBook Hermes runs as the agent backend on the Mac mini, with my MacBook running the desktop client and my phone running Telegram. For non-Hermes usage I use Apollo on iOS for quick chats (reads like Claude, good for throwaway questions), Pi as my coding agent (I already wrote about that setup), and Raycast AI on my Mac for random things. Why bother? The main reason to run local: cloud APIs are rented land. They can change their pricing, hit your usage limits, or swap the model being served behind the scenes whenever they feel like it. I was regularly maxing out two $200/month subscriptions and it felt like I was getting different things from them at different points. Sometimes a model was fine, sometimes it degraded with no notice. Data privacy is another issue. You do not know what these companies do with your data once they have it. They might limit how it gets used, they might sell it, they might expose it. Either way, it creates an operational security risk. If you work with sensitive code, client data, or proprietary workflows, sending it to a third-party API is a decision you make once and cannot undo. Then there is AI sovereignty. I have been watching how the US government has limited the rollout of various models. That can happen at any point from any government, for any reason, and you have no control over it. If your workflow depends on a cloud model that gets restricted, you have to stop or scramble. The only way to avoid that is to own your compute. Other practical advantages: - Cost predictability. APIs are variable. Your usage spikes and your bill follows. With local hardware, the cost is the hardware purchase plus electricity. Flat. After that, every inference is free. - Latency. No network roundtrip means faster responses for everyday tasks. The M4 Pro’s media engine handles inference at speeds that feel instant for most prompts. - Offline capability. No internet, still works. For agent workflows that run in the background, this matters more than it sounds. - No rate limits. API providers throttle you when you hit usage thresholds. Your own machine does not care how much you run. How I actually use it The Mac mini is always on. It sits on my desk and I barely notice it except when I need it. Hermes runs on the Mac mini as well, using a local model on the same machine. I access my agent through Telegram (on my phone) and the Hermes desktop app on my MacBook. The Hermes desktop app acts as a ‘shell’ and connects to a Hermes backend on another device (in this case the Mac mini). This means I share a backend, conversation history, and skillset across all my devices. Then there is everything else: - Apollo on iOS for quick throwaway chats. I want something that reads like Claude but does not require an API key or a subscription. Connect Apollo to http://[mac-mini-tailnet-url]/v1 and you are done. Good for “rewrite this paragraph” or “what does this error mean” type questions. - Raycast also on my Mac for random things I don’t want to install anything for. - Pi for coding. Already wrote about that setup. The point is not to replace API-based models. It is to handle the 80% of requests that do not need GPT-5 or Claude Opus. And when I do need those, they are already available. Local just covers more of my day-to-day for free. The model breakdown Running a large model locally comes down to one thing: how much RAM it actually needs in memory. Most people look at the parameter count and get the wrong idea, because the difference between dense and mixture-of-experts (MoE) models matters a lot on consumer hardware. Here is how to read the identifier: Qwen3.6-35B-A3B-OptiQ-4bit Qwen3.6 : model family and version35B : total parameters across all expertsA3B : active parameters per token (3 billion, not 35)OptiQ-4bit : mixed-precision quantization (4-bit mostly, 8-bit on sensitive layers) gemma-4-e4b-it-4bit gemma-4 : Google’s Gemma 4 familye4b : encoding size, roughly 4 billion parameters totalit : instruction-tuned4bit : uniform 4-bit quantization The key difference is the A3B part. A dense 27B model has 27 billion parameters loaded in RAM at all times, for every single token. An MoE model like the Qwen3.6-35B-A3B has 35 billion total parameters spread across 256 experts, but only about 3 billion are actually activated per token. The other 32 billion sit in RAM doing nothing. On my 48GB Mac mini, the Qwen3.6-35B-A3B in 4-bit takes about 20GB of RAM. That leaves 28GB for context windows, the operating system, and everything else running on the machine. The Gemma-4-E4B is roughly 2.4GB. Small enough to keep around for simple tasks where using the full 20GB model is overkill. My friend’s MacBook Air had 16GB total. A dense 27B in 4-bit needs roughly 14GB. That is literally everything the machine has, minus room for the OS. So it works for a moment, and then when it does not, it swaps to SSD and becomes painful. MoE changes this. The 35B model in my identifier would fit on the same MacBook because only 3B of weights are actually active per token, which means the GPU/Media Memory footprint is more like what a 6B dense model would need. The 35 billion total parameter weights all sit in unified memory. How to check if a model will work on your hardware: - Look at the quantized file size first. A 4-bit model is roughly the number of parameters in gigabytes (35B params ≈ 17-20GB depending on the quantization method). - Subtract your OS overhead. macOS takes about 6-8GB on Apple Silicon. - Leave room for context windows. Every few thousand tokens adds megabytes to the KV cache. Plan for 8-16GB overhead if you expect long conversations. - For MoE models, the total parameter count is misleading. Look for the “active parameters” figure to understand actual inference memory. - If your model plus context still fits within your available unified memory with a 10-15% buffer, you are good. Anything closer to full will swap to SSD. Swapping models is easy This is the part nobody talks about. You can swap out your local models every few weeks as new ones drop. It is literally a download and a restart. The workflow: - Download the new model into ~/models/ - oMLX auto-discovers it from the model directory - Pick it in the oMLX app or restart the server - Done The oMLX admin dashboard has a built-in HuggingFace model browser. Find a model, click download. Change the model in Hermes, Pi, Raycast, and Apollo, and I am all done. A lot of this can be done via CLI too, so I can SSH into the Mac mini from any of my devices. Why this matters: the gap between local models and API models is closing fast. What was “meh” quality a year ago is competitive for most real-world tasks now. Coding, reasoning, tool use are where it matters. And the 4-bit quantization from OptiQ keeps quality surprisingly high. The 35B-A3B at 4-bit only loses about 1-2 points on most benchmarks compared to BF16 (16-bit floating point, the uncompressed baseline). That is an acceptable tradeoff for 48GB of memory usage instead of 70. The network Tailscale creates a mesh between all my devices. Mac mini, iPhone, MacBook, all on the same private network. Nothing exposed to the public internet. The oMLX server listens on port 8000. Any device on the tailnet can connect. Raycast, Apollo iOS, Hermes desktop on my MacBook, they all hit the same endpoint. No configuration drift between devices. oMLX’s KV cache persistence also matters on the tailnet setup. Coding agents repeatedly circle back through earlier context in a session. oMLX caches each block to SSD, so when the agent returns to a previous prefix, it is restored from disk in milliseconds instead of being recomputed. That makes the local setup actually practical for agent work, which is where Hermes lives. Closing out Local models on Apple Silicon are not a side experiment anymore. The M4 Pro Mac mini handles it without breaking a sweat, the models are good enough for most tasks, and you can swap them out whenever you want. You are not paying per token. You are not routing sensitive data through third-party endpoints. And when a better model drops next week, you can try it with barely any effort for the cost of some hard drive space. I have already ordered a 128GB M5 Max Mac Studio to be delivered later this year, but I am incredibly happy with the performance of this M4 Pro Mac mini so far. If you have other Apple Silicon devices, try it out - you may need to change the model based on your specs, but the general setup holds.

6

The efficient frontier of LLM inference

Hacker News · original → · 7/10 · AI: LLM inference efficiency and cost-capability tradeoffs
In the AI industry, we borrowed the term “efficient frontier” from economists. We use it to talk about managing tradeoffs, most often the tradeoff between cost and capabilities for models. A model…

In the AI industry, we borrowed the term “efficient frontier” from economists. We use it to talk about managing tradeoffs, most often the tradeoff between cost and capabilities for models. A model is a “frontier model” if it offers the highest degree of intelligence at a given cost or size. We also have efficient frontiers in inference engineering. Most often, this is expressed as a tradeoff between latency and throughput (which determines cost), though we can also exchange quality for throughput (via quantization, distillation, and pruning) or intelligence for speed (in the form of reasoning level). There are two types of techniques available to inference engineers: Techniques which make a tradeoff between two factors to move a deployment along an efficient frontier. Techniques which push out the entire frontier for a given deployment, creating more overall efficiency which can be allocated to whatever outcome is most beneficial. Both types of techniques are valuable. It’s useful to be able to target any point along an efficient frontier by making tradeoffs. Giving up per-user speed makes it possible to build high-throughput, low-cost pipelines for batch workloads. Sacrificing throughput to improve speed makes sense when latency-sensitive users have a high willingness to pay. And of course, it’s incredibly useful to push out the entire frontier. Unlocking more efficiency creates gains that can be allocated to lower latency, higher throughput, or a combination of the two. This article details which inference engineering techniques let you target a point on the frontier, and which techniques push the entire frontier out. For this article, we’ll assume we’re running an LLM like GLM-5.3 or Kimi K3 for agentic coding with KV cache reuse enabled and optimal KV-aware routing. Techniques that manage tradeoffs Hitting a certain target in production is often less about discovering some novel approach and more about finding the right set of configurations given the nature of the traffic. In practice, the efficient frontier is very jagged. Rather than a smooth, continuous line between outcomes, small changes can have big impacts. These cutoff points are often unintuitive and must be discovered empirically through sweeps. Batch sizing The most obvious tradeoff between latency and throughput comes from batch sizing. A batch is the number of requests that are processed concurrently. While token-level continuous batching means that there isn’t any latency from waiting for batches to start, the configured batch size determines the per-user latency and the overall throughput. With small batch sizes, per-user latency is excellent, but few total tokens are generated per GPU. This means the cost per token is quite high. Increasing batch size has the opposite effect: worse per-user latencies, better overall throughput for lower cost. Parallelism strategy Today’s LLMs measure in the hundreds of billions or trillions of parameters and must be spread across multiple GPUs. The way in which they are shared, or parallelized, across GPUs can boost either latency or throughput. For latency-sensitive deployments, focus on increasing Tensor Parallelism (TP). While TP has expensive all-to-all communication, it is effective for lowering latencies as these operations are fast over high-bandwidth NVLink interconnects. Expert Parallelism (EP) can help with both latency and throughput. A lower degree of EP is often associated with better latencies, while wide EP, including EP across a full rack of GPUs, generally supports higher throughput. Another parallelism technique for improving throughput is Attention Data Parallelism (ADP). This technique replicates attention layers for parallel computation, which boosts system throughput at the expense of per-request speed. Quantization Quantization, or running a model with a lower level of precision in weights, activations, and/or KV cache values, improves both latency and throughput. A quantized model pushes out the efficient frontier on serving tradeoffs. However, quantization introduces a new set of tradeoffs between quality and serving efficiency. This is a particularly jagged frontier, where a large degree of improvement to serving efficiency is possible with little-to-no reduction in model quality, especially when using microscaling floating-point number formats like MXFP4 and NVFP4. Techniques that move the frontier These techniques are the ones that make the headlines. Improving overall performance is the most fun part of inference engineering. The best part is that these techniques often compound. For example, doubling performance from better hardware while also doubling performance from better software means a four times improvement in overall serving, which can be allocated across latency and throughput. Kernel optimization and runtime improvements A CUDA kernel is a low-level function that executes a single piece of the inference process, like a matrix multiplication. Improving the performance of individual kernels, as well as the end-to-end performance of a forward pass in the inference engine, means fewer resources are needed to generate each token. These efficiency gains compound throughout the stack and push the frontier of performance. For more on kernel-level performance, read this excellent writeup by Baseten intern Brian Li. Speculative decoding Speculative decoding is the process of guessing which tokens a model might generate, then validating those guesses. When speculative decoding was new, this posed a tradeoff between latency and throughput: speculation was expensive, sequence lengths were short, and acceptance rates were low, meaning speculative decoding was only feasible at small batch sizes. Today, techniques like EAGLE-3, DSpark, and DFlash still compete with the main model loop for resources, somewhat limiting maximum batch sizes. However, thanks to the strong performance of these techniques, especially on code generation where output token sequences are relatively predictable, they yield efficiency gains from skipped forward passes in addition to the raw reduction in latency in the form of more tokens per second per user. Disaggregation P/D disaggregation, or separating prefill and decode onto dedicated workers, is a strategy for optimizing high-volume deployments of LLMs. Running prefill and decode independently means that workers can be optimized for the unique characteristics of each phase of inference, and that the ratio between prefill and decode workers can be adjusted to match the input and output sequence lengths and cache hit rates from incoming traffic. This article provided a basic overview of techniques for managing tradeoffs versus techniques for improving systemwide performance. For more detail on every technique mentioned in this article, read my free book Inference Engineering.

7

SNES Superbrite!

r/gaming · original → · 7/10 · Retro gaming: SNES Superbrite vintage console
[image →] Over the weekend a friend of mine delivered this vintage SNES Superbrite sign to me. This is the same SNES Superbrite i owned years ago. I had sold to my friend in 2019 & it feels so good…
[image →]

Over the weekend a friend of mine delivered this vintage SNES Superbrite sign to me. This is the same SNES Superbrite i owned years ago. I had sold to my friend in 2019 & it feels so good to finally have purchased it back. Couldn't be happier & wanted to share. Hope you enjoy!

submitted by /u/D-Funk187
[link] [comments]
8

Claude Fable 5.1 made me a really nice animated pelican

Simon Willison · original → · 7/10 · AI: Claude Fable 5.1 coding and reasoning capabilities
Claude Fable 5.1 made me a really nice animated pelican 1st September 2026 Today is Claude Fable (and Mythos) 5.1 day. Anthropic say that Fable 5.1 “sets a new standard for coding, knowledge work,…

Claude Fable 5.1 made me a really nice animated pelican 1st September 2026 Today is Claude Fable (and Mythos) 5.1 day. Anthropic say that Fable 5.1 “sets a new standard for coding, knowledge work, and long-running problem-solving tasks”. Their announcement spends a notable amount of time on scientific research, boasting of a 52.6% score on the brand new Terminal-Bench-Science 0.1 benchmark (first announced on August 27th), up from 24.7% for Fable 5, 29.0% for Opus 5 and 22.4% for GPT-5.6 Sol. Other benchmarks show slightly improved scores, but none as impressive as the Science one. But how well can it pelican? Back in July I wrote about how I was losing faith in the pelican benchmark—its connection to how good the models were at other tasks didn’t seem to hold as strongly as it did back in 2025. The most interesting insights I get from it now are comparisons within model families, and particularly comparisons for the same prompt at different reasoning effort levels. Fable 5.1 has five reasoning levels: low, medium, high, xhigh, max—and no option to turn off reasoning entirely. I fixed an issue in llm-anthropic which caused reasoning traces not to be correctly recorded, then ran some prompts. Here’s the full set of pelicans for all of the reasoning levels, each with the full reasoning transcript. I’ll replicate them here: Low and medium, both without reasoning? Next, a bit of a mystery. This is what I got for effort low : The transcript doesn’t show any summarized reasoning tokens, and the output token count is 1,998. With Claude that output token count includes reasoning tokens. It took 23.8 seconds and cost 10.017 cents. I bumped that up to medium and got this: Weirdly, that one also shows no reasoning text and used 1,977 output tokens—21 tokens less than low . It took 23 seconds and cost 9.912 cents. So for this particular prompt (“Generate an SVG of a pelican riding a bicycle”) Fable 5.1 appeared to skip reasoning entirely at both low and medium settings. High Here’s high —29.6 seconds, 2,612 output tokens, 13.087 cents: This one did do a bit of reasoning, summary here: I’m planning the SVG layout for a pelican riding a bicycle, with a sky and ground background, a bicycle with two spoked wheels, frame, seat and handlebars, and a white-bodied pelican with a long neck and orange beak positioned on top. Really not much difference from low and medium , though. Extra High At xhigh things got radically different. 36,767 output tokens, 7 minutes 51 seconds, $1.83! The reasoning trace is pretty lengthy, and includes details like this: Adding the eye, wings stretching down to the handlebar grip, orange legs reaching to the pedals, and a small tail feather, while keeping the pelican intentionally oversized compared to the bike for comic effect. [...] I’ll accept the slight thickness as charming rather than overengineering it. Max Setting effort to max gave me the best pelican I’ve seen from any of Anthropic’s models. 65,927 output tokens, 13 minutes and 54 seconds, $3.30: There’s a lot to like about this. The background is tasteful, the legs are clearly on either side of the frame, the feet are on the pedals, the wing is on the handlebars, the pelican has a cute blue hat and there’s a basket with a fish. It’s still not showing nearly the same level of flair as Gemini 3.7 Flash, but I didn’t ask for flair—I asked for an SVG, and that’s what I got. Some highlights from that reasoning trace: Adding pedal shapes near both feet, with the far foot on the second leg partially visible behind the frame. I’m considering whether to add a small scarf or cap for extra character, but leaning toward keeping it simple to avoid clutter. Now I’m debating a bicycle helmet on the head versus the pelican’s signature crest—the beak and pouch already read clearly as “pelican,” so a helmet could reinforce the bicycle theme without losing identity, though it might compete with the crest for visual space. I realize the beak at (484,84) would overlap with the dome helmet, so I need to shrink the helmet so it only covers the top of the head, adjusting its arc endpoints to sit higher and narrower so the beak can attach cleanly at the front without collision. [...] I’m adding a darker tip region to represent the primary feathers, then reconsidering the trailing edge to include scalloped feather curves instead of one smooth line for a more natural look. [...] Now I’m checking the vent line placements on the helmet, making sure they sit far enough inside the helmet’s edge given the stroke width and rounded caps, and confirming each vent stays within the helmet’s circular boundary. [...] I decide skipping a handlebar bell and tire highlights since they’re unnecessary additions. Now I’m reconsidering the front fork’s curve — the current control point pulls the shape backward when it should bow forward for a proper rake, so I need to shift the control point rightward to fix the fork’s lean. OK, let’s animate it On Hacker News, swalsh commented on that Max pelican: Now that it’s a solved benchmark, can we get the animated version? I didn’t want to spend another $3 so I took the Max pelican and piped it into the default thinking level of High: llm logs -cx | llm -m claude-fable-5.1 -s 'animate this' 6,121 input, 26,201 output = $1.37. The result looked like this, exported here as video since some people have trouble viewing animated SVGs: The wheels in the video are rotating in the wrong direction, but I think that’s an artifact of the conversion to MP4—they seem to be going in the correct direction in the original SVG. More recent articles - Understanding ChatGPT Work - 30th August 2026 - Conceptual integrity and counting lines of code - 19th August 2026

Items scoring 7/10 or above from 11 sources, scored by claude-haiku-4-5-20251001 on relevance to my interests. At most 3 per source.

Scoring categories & sources
  1. Local Wexford or South East Ireland news
  2. Irish or EU-wide affairs affecting citizens broadly: elections, new laws or policy being debated, cost of living, education — especially impacts on mid-life adults or teenagers. Never courts/crime stories.
  3. Irish news on a topic relevant to my interests
  4. Work and tech topics: networking, AI, Kubernetes, platforms, SaaS
  5. AI news including critical or anti-AI perspectives
  6. Gaming: PC gaming, indie gaming, retro gaming
  7. General interests: gardening, woodwork, cycling, fitness, travel
  8. Comics

Sources: Breaking News Ireland, Wexford Local, Hacker News, r/gaming, r/pcgaming, r/antiAI, r/indiegaming, Lenny's Newsletter, One Useful Thing, Newcomer, Simon Willison