daily

2026-09-09
1

Material World Exhibition at County Hall

Wexford Local · original → · 8/10 · Local Wexford: Material World Exhibition at County Hall
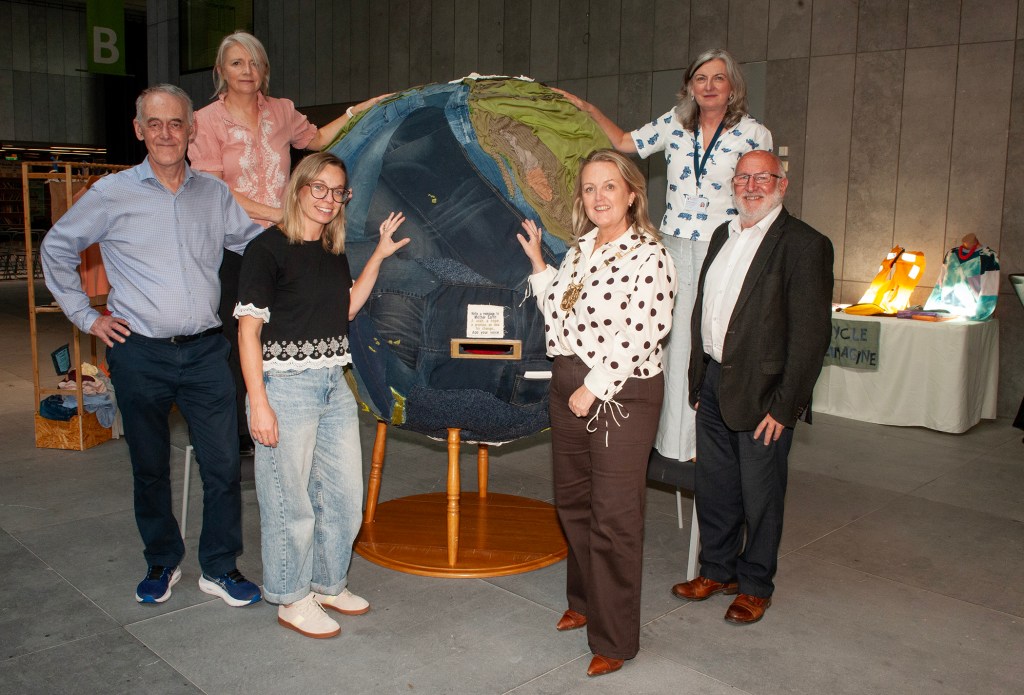
[image →]Pictured at the Material World Exhibition at County Hall, Wexford, were (left to right); Caroline Sinnott, Wexford County Council, Hugh Maguire, Wexford County Council, Lynn Haughton, the…
[image →]
Pictured at the Material World Exhibition at County Hall, Wexford, were (left to right); Caroline Sinnott, Wexford County Council, Hugh Maguire, Wexford County Council, Lynn Haughton, the Upcycle Movement, Cllr Lisa McDonald, Cathaoirleach Wexford County Council, Cliona Connolly, Wexford County Council and Eamonn Hore, Deputy Chief Executive, Wexford County Council. (Pic; Jim Campbell).

By Dan Walsh

Cathaoirleach of Wexford County Council Cllr Lisa McDonald officially launched ‘Material World’ an exhibition exploring fashion, textile waste, and climate action and open to the public at County Hall, Wexford.

Cllr Lisa McDonald stated; “I am delighted to launch the exhibition ‘Material World’ which explores our relationship with clothing, consumption and the impact of a fast fashion system and textile waste on our natural world.

The exhibition encourages us all to rethink textiles, reduce waste and make sustainable choices that benefit our communities and our planet. Each of us has the power to make a positive change in creating a more sustainable future,” concluded Cllr McDonald.

Developed by Lynn Haughton of The Upcycle Movement in partnership with Wexford County Council and Waterford City and County Council, Material World is a unique interactive exhibition exploring fast fashion, textile waste, and climate action.  

Throughout its Wexford tour, Material World will welcome local school groups for facilitated sessions, alongside special community evenings where visitors can experience the exhibition, take part in hands-on activities and conversations, and discover creative, practical ways to rethink, repair, and reimagine textiles.  

Cliona Connolly, Wexford County Council added; “The exhibition is open to everyone to visit during the participating venues’ normal opening hours, giving members of the public the opportunity to explore Material World in their own time. Material World encourages people to think differently about how clothing is produced, consumed, and discarded.”

The Material World exhibition runs at County Hall, Wexford until Friday, September 11th and from Monday to Thursday, inclusive, September 14th-17th. It will visit Gorey Library from Tuesday to Saturday, October 6th-10th.

An evening talk / session will take place on Thursday, September 10th in County Hall Wexford at 6pm and in Gorey Library on Tuesday, October 6th at 6pm. The evening session / talks will be facilitated by Lynn Haughton of the Upcycle Movement. 
2

Opera train returns after almost 20 years

Wexford Local · original → · 8/10 · Local Wexford: Opera train returns for festival 75th anniversary
[image →] By Dan Walsh The Wexford Festival Opera Train is returning after almost 20 years for the festival’s 75th anniversary, in association with Railtours Ireland, for one special journey on…

By Dan Walsh

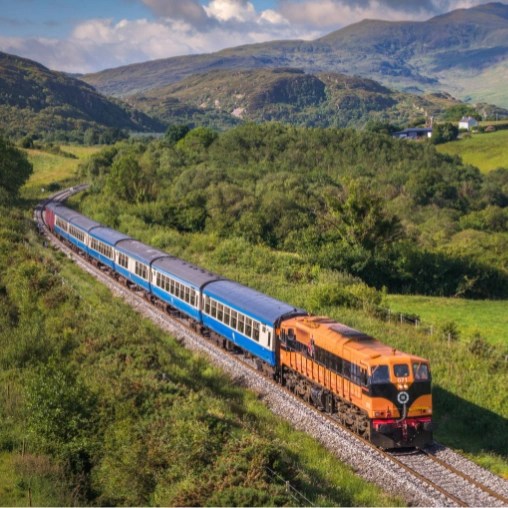
The Wexford Festival Opera Train is returning after almost 20 years for the festival’s 75th anniversary, in association with Railtours Ireland, for one special journey on Thursday, October 22nd.

For generations of Festival-goers, the journey to Wexford was part of the magic. The legendary Opera Train brought audiences from Dublin dressed to the nines, with dinner served en route to Wexford and supper on the return journey after the performance. Now you too can enjoy this magical experience.

Festival patrons will once again be able to travel from Dublin to Wexford on the Opera Train, enjoying dinner on board before an evening at the opera and returning to Dublin after the final curtain.

The black-tie experience begins at Dublin’s Connolly Station with a champagne toast. Once aboard, guests will enjoy a four-course dinner as the train travels south along Ireland’s spectacular east coast towards Wexford for a performance of Sergei Prokofiev’s The Gambler.

The Opera Train Experience programme includes;

  • Welcome: Champagne reception on the platform at Dublin’s Connolly Station.
  • 15:30: Depart Connolly Station on the Emerald Pullman Heritage train.
  • Dining onboard: Four-course dinner with wine
  • 18:00: Arrival at Wexford O’Hanrahan Station with private coach transfer to the National Opera House
  • 19:30: Opera performance: Sergei Prokofiev’s The Gambler
  • 22:30: Performance ends. Coach transfer to Wexford train station
  • 23:00: Opera Train departs Wexford
  • Supper onboard: Soup and sandwiches
  • 01:10: Arrival at Dublin’s Connolly Station
  • Onboard bar: Full cash bar available throughout the journey

Tickets: €479 per person [includes return train, champagne reception, dinner, wine, opera ticket and supper]. A limited number of places are available. Early booking is advised.

For any queries relating to any aspect of the Opera Train, please contact operatrain@wexfordopera.com.

3

John championed music, culture and tourism

Wexford Local · original → · 7/10 · Local Wexford: tribute to musician John Murphy, culture
[image →]JOHN MURPHY By Dan Walsh Tributes have been paid to John Murphy of Colfer’s Pub, Carrig-on-Bannow, an internationally renowned musician and lifelong champion of culture and tradition, who…
[image →]
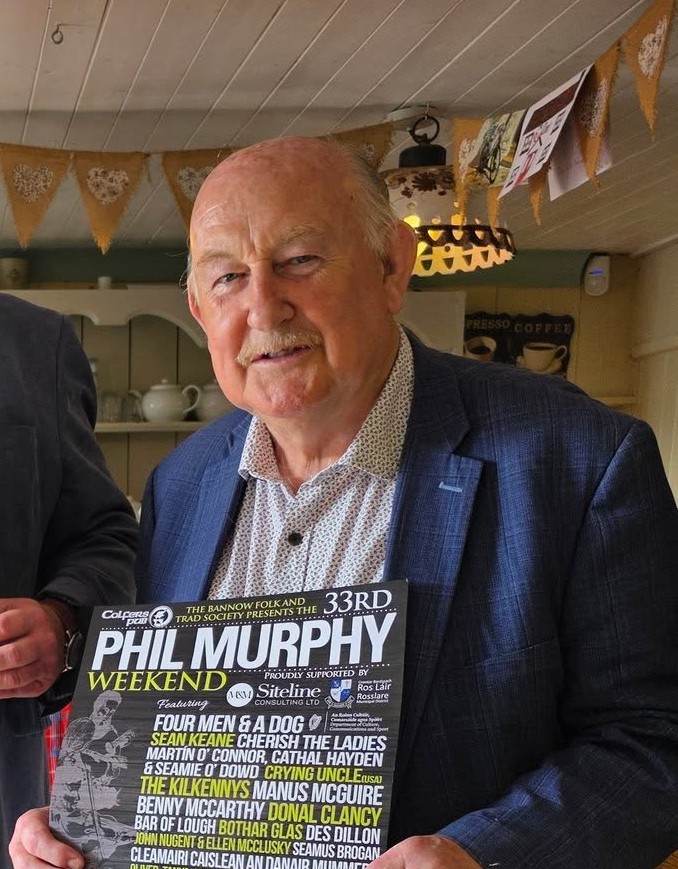
JOHN MURPHY

By Dan Walsh

Tributes have been paid to John Murphy of Colfer’s Pub, Carrig-on-Bannow, an internationally renowned musician and lifelong champion of culture and tradition, who has sadly passed away.

John was best known to many as the organiser of the annual Phil Murphy Weekend, launched in July 1992, which brought leading traditional musicians to Carrig-on-Bannow each July.

John and Pip (his brother) were recently honoured by the Eugene O’Neill International Festival of Theatre.

Cllr Jim Codd admired John for many traits. “What he did for music, culture and tourism could not be quantified. His name was known wherever the harmonica was played and he was on first name terms with international stars. It has been a pleasure to know The Great John Murphy. I am sure he will be playing ‘The Trip To Cullenstown‘ with his father tonight,” added Cllr Codd.

Danescastle Music Group paying tribute on social media stated; John will be greatly missed by all of our musicians. He was instrumental in bringing world class musicians to Carrig and encouraged them to give workshops to our group. We were always welcome to play music in Colfer’s Pub. Ar dheis Dé go raibh a anam.

Locally, John has been described as “An amazing musician and a much-loved character in the community, John will be remembered for his warmth, friendship, generosity and love of good music and company, bringing great joy to many over the years.”

FAMILY NOTICE; The death has occurred of John Murphy, Ballygow, Bannow and Colfers, Carrig-on-Bannow, Co. Wexford. John passed away peacefully surrounded by his loving family in the care of The Oak Ward, Waterford University Hospital.

Beloved husband of Teresa (Tesie) and brother of Nick, Pat and Pip. John will be so sadly missed by his wife, brothers, sisters-in-law. brothers-in-law, nieces, nephews, godchildren, cousins, his loyal friend “Hammy”, extended family, neighbours and many friends.

May He Rest in Peace

Reposing in The Tin Sandwich Bar, Colfers, Carrig on Bannow, Co. Wexford (Y35VY10) from 4pm to 8pm on Tuesday, September 8th. Funeral Mass on Wednesday at 2pm in The Church of Mary Immaculate and St. Joseph, Carrig on Bannow followed by burial in St. Mary’s cemetery Kilmore.

4

Mercury 2.5

Hacker News · original → · 7/10 · AI/platforms: Mercury 2.5 LLM production model release
Today, we’re releasing Mercury 2.5, our most capable production model yet. It is a significant step up in quality over Mercury 2, with the same low-latency, low-cost serving profile. Since Mercury…

Today, we’re releasing Mercury 2.5, our most capable production model yet. It is a significant step up in quality over Mercury 2, with the same low-latency, low-cost serving profile. Since Mercury 2’s launch, thousands of developers have built with it, dozens of enterprises have put it into production, and usage has grown over an order of magnitude. It now serves latency-sensitive workloads across search, voice, and coding products. Those workloads gave us a clearer signal than benchmarks alone. We used customer feedback and production failure cases to sharpen the evals and focus training. Mercury 2.5 is the first result of that loop. What changed Mercury 2.5 is the most capable diffusion LLM on the market. To our knowledge, it is the largest diffusion language model ever trained. Quality: 40% increase in intelligence from Mercury 2. Comparable to cost-optimized frontier models like GPT-5.6 Luna (Low), Gemini 3.5 Flash-Lite, and Claude Haiku 4.5. Speed: 1,107 tokens per second on widely-available NVIDIA GPUs. Context: 260K tokens. Price: $0.20 per million input and $0.75 per million output. At launch, Mercury 2.5 is 80% off at $0.04 per million input and $0.15 per million output. Capabilities: Tunable reasoning, parallel tool calls, and schema-aligned JSON. Since Mercury 2's launch, we've watched Inception advance diffusion-based language models further on NVIDIA AI infrastructure. Mercury 2.5's step up in intelligence paired with sustained speeds and low costs, reflects how quickly new architectures can mature into production-ready systems on the NVIDIA platform. Shruti Koparkar, Senior Manager of Product, Accelerated Computing Group at NVIDIA Mercury in production Search Agents and RAG pipelines One search request can trigger dozens of model calls: plan the search, rewrite queries, rerank results, structure facts, summarize sources, and check the answer. Mercury keeps those calls fast enough to stay inside a single user interaction. Several leading search-infrastructure companies now run it in production. Voice agents and interactive applications In voice, latency isn’t an infrastructure detail. It is the pause a caller hears. OpenCall builds AI phone agents that handle live customer calls. On its production workload, Mercury brought median model response latency close to 170 milliseconds. After we switched to Mercury, our P99 response time dropped from several minutes to just one second, and our P50 dropped from 0.4 seconds to under 0.2 — significantly faster than any other provider we’ve seen, and that’s including reasoning. Oliver Silverstein, Co-founder and CEO, OpenCall Coding subagents and assistants Coding agents already split work across models. One may plan or write code while others search, run tools, route requests, summarize state, or compact a long session. Those supporting calls happen again and again, so latency and cost compound quickly. Augment Code uses Mercury for context compaction, model routing, and MCP tool search. Moving compaction to Mercury cut latency by 82%, from roughly 150 seconds to 27 seconds, and reduced cost by 90% while maintaining quality. Tool-search summaries return in under a second. The same speed applies to developing web apps. Watch Mercury 2.5 generate a working music discovery log web app from a few prompts in the demo below. Mercury Voice and Mercury Router Preview Alongside Mercury 2.5, we’re announcing a preview of Mercury Voice and Mercury Router. Mercury Voice delivers time-to-first-token (TTFT) under 170 milliseconds and is a dLLM optimized for voice agents with the tightest latency budgets. Mercury Router understands incoming prompts with a dLLM and routes them to the best models (open and closed models) that offer the best mix of quality, speed, and cost. Get Started Mercury models are available through our Inception API, Baseten, and OpenRouter. Enterprise deployments support dedicated capacity, autoscaling, compliance controls, and configurable data retention. Try Mercury 2.5 in chat Try the API with 100 million free tokens · Read the API docs Baseten customers: Deploy Mercury 2.5 through your existing Baseten setup. Y Combinator companies: Claim $500,000 in deployment benefits. Evaluating Mercury for voice? We’ll work with you to test workload fit, and validate performance under your serving constraints. Contact us. What’s Next We have already started training our next model. It is our largest model yet, and we are targeting a release in the coming months. Our next model will be a leap in capability without giving up diffusion’s speed and token-efficiency. That requires progress on model training, inference, evals, and infrastructure. If that's the kind of problem you want to work on, we’d love to hear from you. More soon.

5

An Accidental Blackboard

Hacker News · original → · 7/10 · AI/platforms: agentic engineering at Thoughtworks
An Accidental Blackboard This article is part of “Exploring Gen AI”. A series capturing Thoughtworks technologists' explorations of using gen ai technology for software development. 02 September…

An Accidental Blackboard This article is part of “Exploring Gen AI”. A series capturing Thoughtworks technologists' explorations of using gen ai technology for software development. 02 September 2026 This week, across Thoughtworks Europe, we took 10 engineers and put them in one room in our Barcelona office. The goal was to see how far and how fast we could go if we really leant into agentic engineering. We called it hyper-agentic. Along the way, we accidentally re-discovered something about coordinating agents. The 10 engineers were given the goal of building an airline IROps system. This is the system that airlines use in a flight control centre when something goes wrong. When a plane has a technical fault that needs to be repaired. When a crew member gets sick and the crew needs to be replaced. It’s how they decide which flights to cancel, which planes to swap, which passengers get offloaded and put into hotels, etc. etc. They’re doing this over hundreds of aircraft, hundreds of thousands of passengers and many, many crew across multiple stations and airports. It’s a really, really hard problem, hard to solve, hard to execute. An IROps system is complex to build, complex to understand, and complex to use. We managed to build one in four days. But this post isn’t about how we did that. We started with a specification and a simulated airline, because this was a practice exercise, not a real client. We tried a couple of things just to see what would and wouldn’t work. We used a monorepo. All the engineers began working at once. We just got started, and after a couple of days we began to see things happening in interesting ways, things emerging. Emergent behaviour from tuning our approach With lot of agents working in one repo, build pipelines suffered. To deal with this we introduced a discipline: our agents were to continually commit and rebase from main. At first, we required a rebase after commit and to then push, with all of the build checks and controls in place. We introduced this change to catch build failures locally: integrate early and often. But, there was a side-effect. We were directing the agents to plan, to scope work to sections in the spec and to create plans linked to those sections. These plans were stored in the repo. All agents were working off the same spec using the same numbered and identified sections. As agents worked, plans were updated to record progress. These updates, alongside all others, were swept up with the new commit discipline. Agents were able to see other agents’ progress. So, one agent was, say, working on the evaluator, the component to determine if a particular plan to restore operations is valid, whether it breaks hard constraints or soft constraints, etc. At the same time another agent was working on the search algorithm that looks for plans that could solve the disruption. The search component depends on the evaluator. Each component can be written together, but there is a shared interface and search depends on the evaluator. The plans recorded these integration points. One plan said at this point I’m going to need to update the callers to call the real verifier. And on the search side, it said, at this point I need to insert the call to the real verifier when it arrives. Both agents could see each plan, and the progress. We realised that the agents were using the plans to coordinate. One agent would mark a line of the plan as in progress, the other agent would see that and not work on that line. When the first agent finished, the other agent would see not only that the work was complete and thus it was released to proceed, but would also be directly delivered notes on how the line had been implemented. We started to exploit this. We’d kick off a session and direct it to work on a particular journey. One example was to introduce a cost model alongside the verifier. Knowing that someone else had been working on the cost model and pushing commits continually, we directed the agent working on the verifier to look at plans and source, monitor the repo, and when the work for the cost model lands start to integrate it. And it did. This was entirely ad hoc. It was an accident of a series of decisions. We saw it happen. And then started to use it. The repo as an accidental blackboard for agents There’s a name for the pattern our agents had discovered: a blackboard system. This was something I explored back in my university days. My research thesis was in directing agent behaviour with hierarchical sensors. I was looking at applying modern machine learning techniques of the time, such as reinforcement learning, across large, dynamic datasets. Looking back over the literature, I adopted the blackboard pattern as the core coordination structure. This had previously been discovered in the development of the Hearsay-II system in 1980. It had been subsequently been developed into the more formal tuple space concept by Gelernter et al. in 1986. A blackboard or tuple space is a shared memory that autonomous agents can read and write from independently. They read and write tuples with a certain minimum structure, and then as many extra fields as you want: no schema. It’s a very effective technique for coordinating autonomous problem solvers towards a single goal. They can each solve a decomposed part of the problem, drop their solution into the shared space, label it, and other autonomous searchers will find it, pick it up, and use it as part of their work. We had accidentally prompted our agents to start using our repo as a blackboard. But it was an accident. It wasn’t an intentional act. It wasn’t fully structured. It was missing some of the key parts of how blackboards operate. And because it was accidental, I’m not convinced I would be able to reliably prompt our agents into doing it again. I’ve got a pretty good idea what we did, because we did some analysis and identified the single prompt that caused this cascade to start happening. But it was an emergent behaviour. It wasn’t a directed behaviour. As well as creating this intentionally, rather than accidentally, I believe you want this communication channel to be sitting independently of source control. While we created it by directing a frequent push cycle, we backed-off from that. The frequent commits were overloading our CI pipeline. We switched to only push when a more coherent chunk of change was complete. This deprived the agents of the continuous flow of updates on progress. A good accidental solution requires a good intentional project. I’ve started working on a project I’m calling Talwrn. That’s Welsh for a threshing pit, an area or space where arguments and conflict get worked out. This is aiming to be a blackboard for agentic engineering. My goal is a very simple to use tool that drops straight into your project and immediately offers a communication channel for agents to coordinate work. The first step is to get Talwrn to a point where it can support its own development. I’m planning to post about it regularly as I’m hoping to use it as a single, evolving example of how pure agentic engineering can proceed. latest article (Sep 02): previous article:

6

AI Has a Discovery Problem

Hacker News · original → · 7/10 · AI: discovery problem in AI adoption
2026-09-03 The Discovery Problem The biggest bottleneck to AI adoption is a simple question: what can this do for me? The hard part is that you don’t know what you don’t know. You don’t know what a…

2026-09-03 The Discovery Problem The biggest bottleneck to AI adoption is a simple question: what can this do for me? The hard part is that you don’t know what you don’t know. You don’t know what a button does until you press it. You don’t know what a prompt can produce until you write it, hit go, and watch it run. As long as capabilities stay locked behind a blank text box, the possibilities stay invisible. That’s a discovery problem, and it’s the one we’re still stuck on. There are partial fixes. Templates give people something to run without needing to invent the request themselves. But then the question becomes relevance. Do these templates actually match your work? Do you care? Context helps too: a system that knows about you can suggest things that matter to you instead of things that matter in general. Both help. Neither solves it. Alan Kay has a metaphor for this. Imagine you’re an ant at the bottom of the Grand Canyon. You look up, and your entire notion of the sky is a thin sliver of blue between two canyon walls. Someone standing on the rim sees the whole blue plane. Same sky, completely different sense of what exists. It’s not that the ant is less capable. It just can’t see the axis of possibility from where it’s standing. That’s the gap between a skilled AI user and everyone else. Take a non-technical marketing person and someone fluent in agents and tool use. The agent-fluent person can watch the marketer work for an hour and immediately see a dozen things to automate, delegate, or reinvent, including things the marketer hasn’t even tried yet. But put the most intelligent tool in the world in front of the marketer, and they’re staring at a blank prompt, unsure what to type. All that intelligence, and no way to see it. This is the strange state we’re in: the system could do almost anything, but it requires the user to already know what to ask for. Too much of the work of discovering what’s possible falls on the person, when it should fall on the system. You’d expect something this advanced to reveal its own capabilities — gradually, contextually, in ways that match your actual work. We’re not there yet. Somehow, the interface has to start showing you the sky.

7

On the Navier–Stokes Millennium Prize Problem

Simon Willison · original → · 7/10 · AI: Navier-Stokes problem solved by OpenAI
8th September 2026 - Link Blog On the Navier–Stokes Millennium Prize Problem (via) Impressive result from OpenAI, who used an unreleased model to produce a resolution to the Navier–Stokes existence…

8th September 2026 - Link Blog On the Navier–Stokes Millennium Prize Problem (via) Impressive result from OpenAI, who used an unreleased model to produce a resolution to the Navier–Stokes existence and smoothness problem, one of the seven Millennium Prize Problems that have been subject to a $1,000,000 prize since May 24th, 2000. The discovery is somewhat overshadowed by accusations of skulduggery from Tristan Buckmaster, an NYU mathematics professor who was collaborating on related problems with Levent Alpöge, an accomplished mathematician who currently works for Anthropic. Tristan's complaint accompanied a hastily published version of their own results. Here's the PDF describing what happened. The very short version is that Tristan and Levent worked on the problem for almost a year, making extensive use of Claude and Codex (mainly GPT-5.6 Sol), then had a breakthrough on August 15th. The mathematical rumour mill kicked into gear and Tristan and Levent heard that OpenAI had heard that Anthropic had resolved "a major open problem", so they reached out and learned that OpenAI had a team working on a related problem, with a similar approach. Quoting Tristan: I asked when the first prompt had been sent by them. This question was not answered directly by OpenAI for some time. Eventually it was agreed that it had been sent in the past few days, after information about our work had reached OpenAI. I asked whether the model had been trained on, or had access to, our sessions in Codex, into which we had been putting all our drafts for the whole of this project. I was told the model did not look up user data. I asked again, about training, and I did not get an answer. It gets more complicated from there. The OpenAI team offered to wait for Tristan to publish, or to have him author a paper about their result, but were clear that Levent would not be invited as a co-author due to OpenAI's competitive relationship with his employer. Here's how OpenAI described their work: On Tuesday, September 1, we heard rumors that two Millennium Prize problems had been resolved. Inspired by these rumors and by the step change in performance of our internal model, we launched an effort to evaluate it on all open Millennium Prize problems and a few other high-impact problems. [...] The agents arrived at their resolution on Saturday, September 5, about 88 hours after the first agents were launched. Lean formalization and verification took an additional 17 hours via GPT‑6 Astra. Across all attempted problems, the agents sent 4.9 million messages and used about 300 billion output tokens. In the process of resolving the Navier–Stokes problem, the agents sent 2.7 million messages and used approximately 130 billion output tokens. (We don't know the cost structure of the internal model they used, but 300 billion output tokens at public API prices for GPT-6 Astra would cost $15,000,000.) Here's where they provide their perspective on Tristan and Levent's work (emphasis mine): Our effort began on September 1st after hearing a rumor which we later realized was related to Levent Alpöge, an Anthropic employee, and Tristan Buckmaster, a math professor at NYU. After the completion of our full project and Lean verification (on September 6th), believing from the rumor they also had a solution of Navier–Stokes, we reached out to them to offer a concurrent release of our result and to recognize their priority in a joint announcement. [...] We (the researchers and the agents) did not see any of their work through any means until they released it publicly — in particular, no specific user data was accessed in order to solve this problem. While unlikely, we cannot rule out that de-identified data derived from their usage of our products helped improve our models. However, our proofs differ significantly and even the precise results proved are different in the Euler case (forced vs unforced). My interpretation of what happened here is that OpenAI heard that some Millennium Prize problems had been solved using LLMs and saw this as an opportunity to demonstrate the power of their latest model, without thinking too hard about the optics of scooping a team who had been using OpenAI's own models to work on this problem for the best part of a year. This situation appears to mirror what's happening in the world of computer security right now. Anil Madhavapeddy recently pointed out that Just a rumour of a bug is enough to find a security exploit these days, because if someone knows that some software has an unpatched vulnerability, they can set their agents the task of finding it. Is the same now true of mathematics? Just knowing that there is an unpublished solution to a problem might trigger millions of dollars in LLM spending to get there first. This also highlights one of my ongoing frustrations about how all of this works. When an AI lab says that my data is "used to improve model performance", what does that actually mean? My two favourite hypothetical questions regarding this used to be: - If I'm running Codex and one of my API keys accidentally gets consumed in the context, what are the chances that someone else might ask for an API key in the future and get mine back? (I asked someone at OpenAI once and they called this the "regurgitation" problem and assured me that they take great pains to prevent that... but wouldn't describe how.) - If I brainstorm with ChatGPT about potential new directions for my company, what's the chance that information might be exposed to a competitor in six months' time who asks "what might company X plan to do next"? My new preferred hypothetical for this is: - If I use ChatGPT to help me partially solve a Millennium Prize problem, what are the chances that my work will influence training such that a later model helps someone else solve it first? Recent articles - The Pelican comparison grid for Astra is pretty interesting - 4th September 2026 - OpenAI's rogue agents were caught communicating via public wikis - 4th September 2026 - Claude's new system prompt really doesn't want to reproduce song lyrics - 2nd September 2026

Items scoring 7/10 or above from 11 sources, scored by claude-haiku-4-5-20251001 on relevance to my interests. At most 3 per source.

Scoring categories & sources
  1. Local Wexford or South East Ireland news
  2. Irish or EU-wide affairs affecting citizens broadly: elections, new laws or policy being debated, cost of living, education — especially impacts on mid-life adults or teenagers. Never courts/crime stories.
  3. Irish news on a topic relevant to my interests
  4. Work and tech topics: networking, AI, Kubernetes, platforms, SaaS
  5. AI news including critical or anti-AI perspectives
  6. Gaming: PC gaming, indie gaming, retro gaming
  7. General interests: gardening, woodwork, cycling, fitness, travel
  8. Comics

Sources: Breaking News Ireland, Wexford Local, Hacker News, r/gaming, r/pcgaming, r/antiAI, r/indiegaming, Lenny's Newsletter, One Useful Thing, Newcomer, Simon Willison