daily

2026-08-29
1

Number of homeless children in State hits 5,659

Breaking News Ireland · original → · 8/10 · Irish policy: homelessness crisis affecting citizens broadly
The latest homelessness figures show 11,868 adults and 5,659 children were in emergency accommodation in July 2026. The figures from the Department of Housing show 11,868 adults (up from 11,864 in…

The latest homelessness figures show 11,868 adults and 5,659 children were in emergency accommodation in July 2026. The figures from the Department of Housing show 11,868 adults (up from 11,864 in June) and 5,659 children (up from 5,620 in June) were in emergency accommodation. The largest age group in the latest homeless figures was 25-44, representing 51.7 per cent of the people in emergency accommodation (6,138). Simon Communities of Ireland said there is a lack of political urgency in dealing with homelessness. The charity analysed the figures over the past year and found there has been an increase of 1,469 people (9.1 per cent) in emergency accommodation. It called on TDs to "match the urgency of the fuel crisis", with 17,527 people in total living in emergency accommodation. Ber Grogan, executive director of the Simon Communities of Ireland, said: "Today TDs have cut short their summer holidays to return to the Dáil to discuss fuel prices. While we welcome action to support households facing rising fuel costs, we need to see that same sense of urgency when it comes to homelessness. "Ireland’s homelessness crisis has deepened over the last decade, and there’s still no sense of urgency from government. We need political leadership that matches the scale of the crisis. The Government must act now to prevent people from losing their homes, increase the supply of affordable and social housing, and ensure there are clear pathways out of emergency accommodation." The Salvation Army said that the school return will put "immense pressure" on families. “The change in living circumstances can cause huge upheaval and places immense pressure on families,” said Anthony Byrne, service manager at Houben House family hub in Harold’s Cross. “Added to that pressure is a child born into homelessness, starting school for the first time and being asked where they live – in many cases they will not want to disclose that they are in emergency accommodation. “That scenario can cause stress for children because they are not permitted to bring friends over for play dates, sleepovers or birthday parties, which is a normal rite of passage for most kids. “That’s where our staff and key workers come in to try to navigate around those issues.”

2

Autonomous Mathematical Discovery in an Open-World Multi-Agent Environment

Hacker News · original → · 8/10 · AI: multi-agent mathematical discovery research
Computer Science > Artificial Intelligence [Submitted on 24 Aug 2026] Title:Autonomous Mathematical Discovery in an Open-World Multi-Agent Environment View PDF HTML (experimental)Abstract:We study…

Computer Science > Artificial Intelligence [Submitted on 24 Aug 2026] Title:Autonomous Mathematical Discovery in an Open-World Multi-Agent Environment View PDF HTML (experimental)Abstract:We study autonomous mathematical discovery in the Station, an open-world multi-agent environment in which AI agents from different model families pursue a shared research goal without a central coordinator or scripted pipeline. Agents choose their own research directions, conduct experiments, collaborate, and build a shared scientific literature. Across 12 construction problems from the AlphaEvolve catalogue and two additional case studies, the Station obtained results novel relative to the prior literature on five problems: a new infinite family of finite-field Kakeya sets, new exact 604-point kissing configurations in dimension 11, new records for the discretized Kakeya needle and sign uncertainty problems, and a substantially improved lower bound for Erdős's minimum-overlap problem. Agents also discovered novel infinite families for Book Ramsey numbers. Importantly, the agents produced not only numerical constructions but also theorems and analyses explaining how those constructions work, making the results more interpretable and easier for mathematicians to build upon. We release all raw agent dialogues, proofs, and verification code, providing a transparent record of how these discoveries emerged. Current browse context: cs.AI References & Citations Loading... Bibliographic and Citation Tools Bibliographic Explorer (What is the Explorer?) Connected Papers (What is Connected Papers?) Litmaps (What is Litmaps?) scite Smart Citations (What are Smart Citations?) Code, Data and Media Associated with this Article alphaXiv (What is alphaXiv?) CatalyzeX Code Finder for Papers (What is CatalyzeX?) DagsHub (What is DagsHub?) Gotit.pub (What is GotitPub?) Hugging Face (What is Huggingface?) ScienceCast (What is ScienceCast?) Demos Recommenders and Search Tools Influence Flower (What are Influence Flowers?) CORE Recommender (What is CORE?) arXivLabs: experimental projects with community collaborators arXivLabs is a framework that allows collaborators to develop and share new arXiv features directly on our website. Both individuals and organizations that work with arXivLabs have embraced and accepted our values of openness, community, excellence, and user data privacy. arXiv is committed to these values and only works with partners that adhere to them. Have an idea for a project that will add value for arXiv's community? Learn more about arXivLabs.

3

A16z’s Martin Casado: Bullish on AI Apps, Bearish on Lone Ranger VCs

Newcomer · original → · 8/10 · AI/work: a16z infrastructure exits Cursor and OpenRouter
[image →]It was mostly by chance that the acquisitions of Cursor and OpenRouter landed just four days apart. But for a16z’s infrastructure team, which had a hand in both, it made for an especially…

It was mostly by chance that the acquisitions of Cursor and OpenRouter landed just four days apart. But for a16z’s infrastructure team, which had a hand in both, it made for an especially glorious victory lap: Cursor was the biggest M&A exit of all time, and OpenRouter was a monster too, returning more than 50x in just two years.

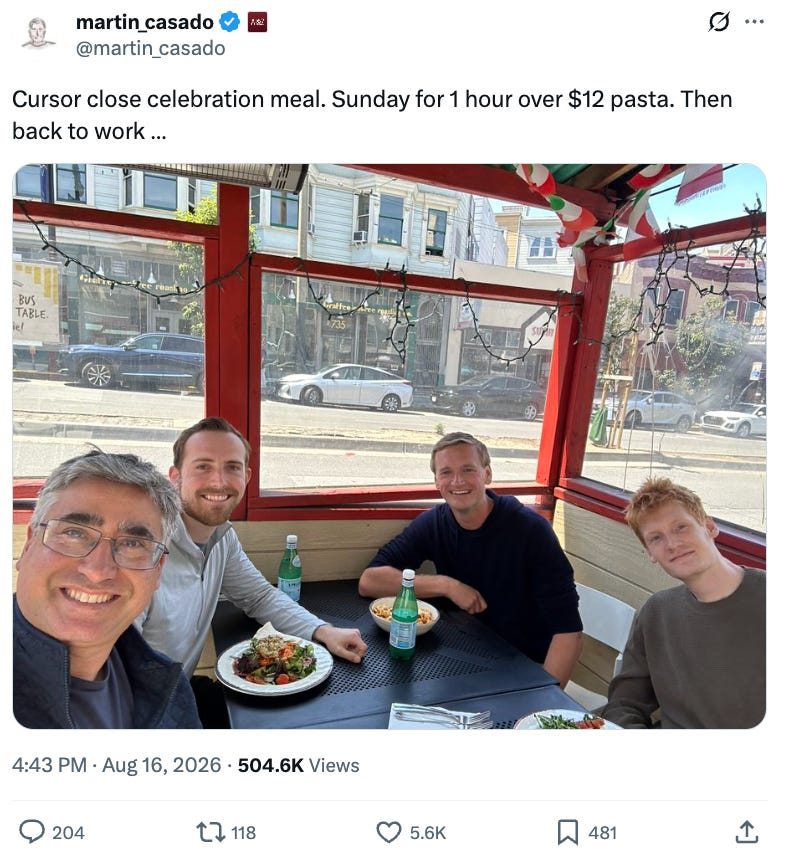
So when Martin Casado, who leads that team, reached out to talk shop after the news, we were surprised that what animated him most was all the maneuvering to get credit for the two big scores.

Individual VCs claiming deals, he told us, is “a historical relic” of a bygone era in tech investing. Modern venture, he argued, doesn’t rest on individual decisions.

“I’ve done almost 200 deals,” Casado said. “I can’t think of a single deal that other people weren’t absolutely instrumental in, whether it’s closing the deal, sourcing, doing the picking, diligence.”

Read more

4

Quoting Drew Breunig

Simon Willison · original → · 8/10 · AI: Claude Fable model cost-benefit analysis
23rd August 2026 Prior to Fable, it felt silly to waste too much time improving your coding harness or context strategies. A new model would arrive at the same price (or cheaper!) and paper over…

23rd August 2026 Prior to Fable, it felt silly to waste too much time improving your coding harness or context strategies. A new model would arrive at the same price (or cheaper!) and paper over most of your problems. But then Fable landed. It was (and still is!) incredible. But the cost was so high and Opus was good enough (as was 5.6, K3, and even GLM) for most of the code we needed. So we started to think about what work went where. — Drew Breunig, Fable & The End of the Free Lunch Recent articles - Conceptual integrity and counting lines of code - 19th August 2026 - Qwen 3.8 27B is excellent, but it defaults to wildly overthinking things - 16th August 2026 - Now we have a timeline of the OpenAI accidental attack against Hugging Face - 7th August 2026

5

Burnham Irish unity remarks were not a mistake, Chris Bryant says

Breaking News Ireland · original → · 7/10 · Irish affairs: Irish unity policy debate affecting citizens
Britain's prime minister Andy Burnham did not make a mistake when he said in Belfast that a poll on Irish unity is “off the table”, Northern Ireland Secretary Chris Bryant has said. Bryant said Mr…

Britain's prime minister Andy Burnham did not make a mistake when he said in Belfast that a poll on Irish unity is “off the table”, Northern Ireland Secretary Chris Bryant has said. Bryant said Mr Burnham was speaking about the situation “now” and insisted they are both “full square behind every single part of the Good Friday Agreement”. The prime pinister caused a political row this week with his comments during his first visit to Northern Ireland since coming into office. Asked about the prospects of a border poll, he responded: “I will take a collaborative approach, but some issues will be off the table, and that is one issue that will be off the table. “I think we’ve got to focus on bringing people together as best we can, and I think we’ve lived through a decade where there’s been a referendum on Brexit, we had Scottish independence just before it.” The remarks drew an angry response from nationalist politicians, with Sinn Féin leader Mary Lou McDonald stating that no British prime minister has the right to “high-handedly” remove the provision for a unity referendum from the Good Friday Agreement. DUP leader Gavin Robinson welcomed the comments, stating Burnham had “put to bed the nonsense” speculation over a unity poll. Asked if Burnham’s comment was a mistake, Bryant told UTV: “No, it wasn’t. “I sat next to Andy throughout all the conversations yesterday, and he made absolutely clear, time and time again, and I’m happy to do it again now, that we stand full square behind every single part of the Good Friday Agreement, including the provisions in relation to a border poll.” He (Andy Burnham) was asked specifically about whether he was going to be discussing a border poll, holding a border poll now, and he was saying that we're taking that off the table today He added: “He was asked specifically about whether he was going to be discussing a Border poll, holding a border poll now, and he was saying that we’re taking that off the table today. “It was simply about the conversations yesterday. “I’ve spoken to the First Minister and to other political leaders today to make it absolutely clear, I and Andy are fully committed to the Good Friday Agreement with all its provisions, including in relation to a border poll.” Under the terms of the 1998 Belfast/Good Friday Agreement, the North's secretary of state can decide to hold a border poll, and it also places a duty on the office holder to call one if it appears likely a majority would vote for Irish unification.

6

Over 100 students detected cheating in Leaving Cert exams

Breaking News Ireland · original → · 7/10 · Irish education: Leaving Cert cheating affecting teenagers
A total of 132 students have had their Leaving Certificate and Leaving Certificate Applied results permanently withheld this year because of cheating in this year’s State exams. New figures provided…

A total of 132 students have had their Leaving Certificate and Leaving Certificate Applied results permanently withheld this year because of cheating in this year’s State exams. New figures provided by the State Examinations Commission (SEC) show that the 132 2025 Leaving Cert results permanently withheld because of cheating are 41, or 24 per cent, down on the 173 Leaving Certificate and Leaving Certificate Applied results withheld in the 2025 Leaving Certificate examinations. A spokeswoman for the SEC stated today that in addition to the 132 results permanently withheld, the SEC “has provisionally withheld a small number of other results, on a without prejudice basis, pending further communication with the schools and candidates concerned”. She said that “these figures are subject to change following the conclusion of all review and appeal processes”. The 132 results withheld this year also compare to 105 results withheld for the 2024 Leaving Cert exams. The SEC spokeswoman said that for context, a total of 70,105 candidates sat Leaving Certificate and Leaving Certificate Applied examinations in 2026, leading to the issue of over 470,000 individual results. She said that “the numbers of results withheld fluctuate on an annual basis in the context of very small numbers overall”. The spokeswoman would not be drawn on whether any of the results have been withheld due to plagiarism brought about by material generated by Artificial Intelligence (AI) software. She said that due to the small numbers of candidates involved, for privacy reasons, the SEC does not provide any further detail about the 132 cases "including the specifics of the incidents or details of the school or location or the gender of those involved”. The spokeswoman said that the SEC “would strongly caution any student that might be tempted to cheat in the State examinations that serious consequences can result”. She said that “candidates are warned that they could lose marks for a component or all the marks for a subject; they could lose the results of their entire examination; or they could be debarred from entering for any of the State examinations for a specified period”. With the advent of Artificial Intelligence (AI) software, such as ChatGPT, the SEC has provided guidance to school authorities about AI in the completion of coursework. The spokeswoman said that the instructions make clear that any material generated by AI software will be treated in the same way as any other material that the candidate has not generated themselves. She said: “Including it without quoting it as the work of AI software will be considered plagiarism, which can result in the forfeit of all marks for the coursework component.” On the penalties imposed for cheating, the spokeswoman said that “the most common penalty applied is the withholding of the marks of a component or the full result in the subject in question”. She said: “Where a more serious breach of the regulations occurs such as copying in more than one subject, withholding of all results and/or debarring from repeating the examination may be applied. The spokeswoman said: “Any incidence of suspected copying, improper assistance from another party, plagiarism or procurement of pieces prepared by another party (which includes the use of AI software), or any other suspected infraction, are thoroughly investigated by the SEC and the candidate is liable to have penalties imposed.” In the investigation of suspected cheating the SEC spokeswoman said that details of the evidence available, such as superintendent’s reports, confiscated material or items, notes or work prepared that exhibits evidence of collusion, is given to the candidate through their school. She said: “The candidate is invited to offer a response to the evidence presented and the school authorities are also free to offer comment if they consider it appropriate. The final decision is communicated in writing to the candidate again via their school.” The spokeswoman said that in the interest of being fair to all candidates, the SEC must be satisfied that marks awarded have been gained fairly and will investigate any suggestion, suspicion or allegation of cheating or other impropriety in relation to the examinations. She said: “This is essential in order to uphold the integrity of the Irish State examinations system and to underpin equity and fairness within the system in order to enable all candidates to display their achievements on an equal footing.

7

I accidentally turned LLM memory into program analysis

Hacker News · original → · 7/10 · AI: LLM agents for code analysis, work-relevant
I accidentally turned LLM memory into program analysis Over the past few months I have been playing around quite a bit with LLM agents, particularly for vulnerability research. They are becoming…

I accidentally turned LLM memory into program analysis Over the past few months I have been playing around quite a bit with LLM agents, particularly for vulnerability research. They are becoming surprisingly good at navigating large codebases, explaining unfamiliar subsystems and helping explore potential attack surfaces. However, once an investigation starts taking a few hours, I kept running into the same problem: the model would slowly lose track of what we had actually established. It might suggest an approach that we had already ruled out, forget that an assumption turned out to be false, or confidently continue reasoning from an observation that was no longer valid. Obviously, telling an LLM that something is wrong does not necessarily mean that it will stop believing all of the things that depended on it :) I initially started looking into memory systems because I wanted to make LLMs more useful for complex vulnerability research and reduce this type of hallucination. There are of course already plenty of solutions for giving LLMs memory. Usually this involves storing old conversations or observations somewhere, embedding them, and then retrieving the most relevant pieces whenever the model needs them again. This works reasonably well, but there was something about it that bothered me. During a vulnerability research sesh, I don’t just want the model to remember what we said. I want it to maintain what we currently know. Imagine that during an investigation we establish the following: attacker controls object_a object_a points to object_b object_b is a kernel object From this, we may conclude that the attacker can control a kernel object. A normal memory system could store all of these observations and retrieve them again whenever we ask about the exploitability of the bug. The LLM then figures out the same conclusion. Great! However, suppose that two hours later we discover in LLDB that object_a does not actually point to object_b , and that our previous observation was based on a wrong assumption. At that point our memory may contain something like: object_a points to object_b attacker can control object_b object_a does not actually point to object_b Now we retrieve some subset of these memories and hope that the LLM correctly figures out which conclusions are still valid. This started to feel a little familiar to me. This looks like program analysis A lot of the work I normally do involves program analysis. When analysing a program, we usually have a bunch of facts about the program and some rules that derive additional facts from them. For example, imagine we know: calls(foo, bar) calls(bar, baz) We could define a rule stating that if one function calls another function, which itself can reach a third function, then the first function can reach the third function as well. Eventually we calculate a fixed point containing everything we can derive from the program. More importantly, if one of our input facts changes, there are plenty of techniques for updating only the affected results instead of rerunning everything from scratch. This is also exactly what I wanted from an LLM during vulnerability research. If an observation changes, I don’t want the model to reconstruct the entire investigation from a transcript and hopefully notice all of the consequences. I want the affected conclusions to become invalid automatically. When looking at the problem from this perspective, I started wondering why we were making the LLM reconstruct its entire state over and over again. What if we just maintained it? And this is how I somehow ended up writing a Datalog engine for LLMs :) Datalog Before we continue, it is probably useful to briefly explain what Datalog actually is. Datalog is a declarative logic programming language. Instead of writing instructions describing how something should be calculated, we describe facts and rules from which new facts can be derived. For example, we could store the following facts: controls(attacker, object_a). points_to(object_a, object_b). kernel_object(object_b). And then define the following rule: controls_kernel_object(Attacker) :- controls(Attacker, ObjectA), points_to(ObjectA, ObjectB), kernel_object(ObjectB). From our existing facts, the engine can therefore derive: controls_kernel_object(attacker). Nothing particularly exciting yet. However, suppose we later discover that: points_to(object_a, object_b). was incorrect. If controls_kernel_object(attacker) was derived from that fact, we know exactly which conclusion depends on the observation that just changed, and we can automatically invalidate it. This is considerably nicer than putting all of the old information into a prompt and asking an LLM to hopefully notice the same thing. Lemmalog This eventually turned into Lemmalog. The basic idea is that an LLM should not necessarily be responsible for maintaining its own knowledge. Instead, I split the problem into two parts. The LLM handles the fuzzy part: "LLDB shows that the freed object is later reused as the destination of the write." | v freed(object_a) reused_as(object_a, write_target) And Lemmalog handles the deterministic part: facts | v rules | v derived facts This means that the LLM is still responsible for understanding natural language, source code, debugger output and all the other messy information that appears during an investigation. LLMs happen to be quite good at this. But once that information has been converted into structured facts, we no longer need the model to repeatedly determine all of its consequences. The database can do that instead. Retractions One of the first interesting problems I ran into was removing facts. Adding facts to a Datalog database is relatively straightforward: add the new fact and evaluate any rules which may now produce additional results. Removing something is a little more annoying. Take the following example: a. b. c :- a. c :- b. Here c has two separate reasons for being true. If we remove a , we cannot simply remove c , because b still provides another derivation for it. However, if we remove both a and b , c should disappear as well. This turns out to be quite important during vulnerability research, because a conclusion may be supported by multiple observations. For example: candidate_3_is_exploitable may remain true even if one particular exploit primitive turns out not to work, because there is another independent path to the same result. So Lemmalog has to keep track of how facts were derived and update their support when something changes. Conveniently, this also gives us another useful property: we can ask why something is true. Why? Imagine we have been running an agent for a few hours while investigating something and it eventually concludes: candidate_3_is_exploitable That is nice, but I would also quite like to know why. Because Lemmalog already tracks the dependencies of derived facts, we can ask it for the provenance of a conclusion. For example, we may get something that conceptually looks like this: candidate_3_is_exploitable | +-- attacker_controls_pointer | | | +-- observation_41 | +-- pointer_reaches_target | +-- observation_57 +-- rule_12 If observation_41 later turns out to be incorrect, we know that this conclusion may no longer be valid, and because the database knows this as well, it can remove the affected conclusions automatically. This was originally mostly necessary to make incremental evaluation work correctly, but it turns out that being able to ask an AI agent why it believes something is quite useful as well :) It also addresses one of the more annoying failure modes I encountered with LLM-assisted research. Sometimes a model will confidently say something like: we already established that this pointer is attacker-controlled when that is not actually true. If a conclusion exists in Lemmalog, I can ask where it came from. If there is no provenance supporting it, then it is not part of the maintained state. This obviously does not prevent an LLM from hallucinating during extraction, but it does make it much harder for unsupported conclusions to silently become part of the investigation. Facts also change over time Another issue is that replacing old facts is not always the same as deleting them. Suppose we originally believe: primitive_a is viable and later discover: primitive_a is not viable For most current queries, we probably only care about the second statement. However, if we want to understand why we previously explored a particular exploit strategy, the old state is still useful. For this reason Lemmalog can associate facts with validity intervals. Conceptually, we can represent the state as something like: viable(primitive_a) [10:14, 12:37) not_viable(primitive_a) [12:37, ...) This allows us to answer both: Is primitive_a viable now? and: Why did we think primitive_a was viable earlier? without keeping two apparently contradictory facts around and asking the LLM to decide which one we meant. Again, this is not really a language model problem. It is mostly a database problem. Why not just use a vector database? Vector databases are very useful. If I ask: What did we find earlier about this allocation path? semantic search is probably exactly what I want. But cosine vibe similarity and truth are not quite the same thing. A vector database can retrieve: object_a points to object_b because it is relevant to my question. It does not inherently know that the statement was disproven two hours later, or that five other conclusions depended on it and should therefore no longer be considered valid. This made me realise that there are really two different problems hiding under the term “memory”. The first is: What information from the past is relevant to this question? The second is: Given everything we have learned so far, what is currently true? Retrieval is very good at the first problem. Lemmalog is mostly an experiment in solving the second one. The two can also be combined, which is what I currently do. A vulnerability investigation is basically an analysis state The more I worked on this, the more similarities with program analysis started appearing. During a vulnerability investigation we have observations: this field is attacker-controlled assumptions: this object survives until the second callback relationships: primitive_b depends on primitive_a hypotheses: this could become an arbitrary write and conclusions: candidate_3 is exploitable This maps surprisingly well to the things we already do in program analysis. We have input facts: observations rules: relationships between observations derived facts: conclusions a fixed point: everything currently known and when an input changes, we perform incremental evaluation: update affected conclusions Because we track dependencies, we can also explain where results came from: provenance At some point it became fairly obvious that I had approached the problem like a static analysis engine without intentionally meaning to. This also changed how I thought about the role of the LLM itself. You can almost think of the whole system as a slightly strange compiler. The LLM acts as the front-end: source code, debugger output, natural language notes | v structured facts Lemmalog is the intermediate representation and analysis engine: structured facts | v deductive rules | v maintained state Another LLM invocation can eventually turn that state back into natural language, suggest the next experiment, or use it to perform some action. The amusing part is that our parser is probabilistic, while everything after it does not necessarily have to be. Does it actually make LLMs better? This is of course the important question. The engine itself now supports incremental evaluation, retractions, provenance, temporal facts, aggregations, entity reconciliation, hybrid retrieval, demand-driven queries and a bunch of other things that I probably added because implementing Datalog features is more fun than I expected. There is also an MCP server which allows agents to use Lemmalog directly. But none of that matters very much if giving an LLM this memory does not actually improve anything. So I plugged it into MemEval and tested it on both LongMemEval and LoCoMo using their standardized reader models and evaluation setup. Extraction during ingestion is Claude Sonnet 4.6 (chunked and file-cached, so it is paid once per conversation); everything after extraction uses the benchmark’s own standardized readers and judges. The results were a little better than I expected. LongMemEval LongMemEval tests whether an LLM can answer questions about information spread across long conversation histories. The split I used contains 102 questions, divided equally between user facts, assistant facts, preferences, multi-session questions, temporal reasoning and knowledge updates. Because 17 questions per category is not exactly a massive sample size, I ran Lemmalog three times rather than getting excited about whichever run happened to score highest. The result was: Lemmalog F1: 0.463 +/- 0.010 Accuracy: 0.575 +/- 0.004 For comparison, the published memory-system results are: PropMem 0.550 SimpleMem 0.480 Lemmalog 0.463 +/- 0.010 OpenClaw 0.244 Full Context 0.222 My own full-context GPT-4.1 run scored 0.197 F1. So Lemmalog is not beating PropMem yet, and it is still slightly behind SimpleMem, but it gets more than twice the F1 of giving GPT-4.1 the entire conversation. More amusingly, the context passed to the answering model is roughly 38 times smaller. Full context: ~104,000 tokens/question Lemmalog: ~2,700 tokens/question Apparently maintaining state instead of repeatedly rereading the entire history is useful :) The category results from one representative run looked like this: | System | SS-User | SS-Asst | Preference | Multi-Session | Temporal | K-Update | |---|---|---|---|---|---|---| | PropMem | 0.851 | 0.767 | 0.147 | 0.582 | 0.424 | 0.528 | | SimpleMem | 0.752 | 0.566 | 0.126 | 0.382 | 0.578 | 0.475 | | Lemmalog | 0.790 | 0.672 | 0.128 | 0.211 | 0.416 | 0.579 | | OpenClaw | 0.401 | 0.432 | 0.127 | 0.082 | 0.185 | 0.234 | | Full Context | 0.265 | 0.415 | 0.177 | 0.062 | 0.212 | 0.202 | The result I found most interesting was Knowledge Update. Lemmalog scored 0.579 , compared with 0.528 for PropMem and 0.202 for full context. Knowledge Update is basically the situation I originally cared about: we believed A | later we learn that A is no longer true | what should we believe now? So seeing Lemmalog top the published field on the category that most closely resembles maintained program state was rather satisfying. Single-session factual memory also worked surprisingly well. Lemmalog reached 0.790 on user facts and 0.672 on assistant facts, while temporal reasoning reached 0.416 , almost identical to PropMem’s 0.424 in that run. The obvious remaining problem is multi-session reasoning: PropMem 0.582 SimpleMem 0.382 Lemmalog 0.211 Diagnosing those failures was interesting: the information usually was not mis-connected, it was simply never extracted. If the extractor never emits a fact for the Airbnb booking, no amount of derivation is going to answer a question about it. Which brings us to one of the more amusing parts of running benchmarks. I accidentally taught it not to answer questions At one point LongMemEval suddenly dropped to 0.371 F1. After going through the failures, I discovered that 32 of the 102 questions were being refused. All 32 were answerable. Questions such as: Which airline did I fly most? or: How many magazine subscriptions do I have? were returning: Not mentioned. The problem was an instruction I had added to reduce hallucinations. I told the reader to make sure that the answer was actually supported by the retrieved facts before answering. Unfortunately, the model interpreted this as: If no single fact literally contains the final answer, refuse. There is obviously no fact saying: most_flown_airline(user, swiss) if the memory instead contains: flew(user, swiss, trip_1) flew(user, swiss, trip_2) flew(user, lufthansa, trip_3) The answer exists. It just requires counting. The fix was to separate two cases: - If the premise is absent or misattributed, refuse. - If the evidence exists but requires counting, comparing, combining or ordering facts, actually reason over it. After fixing that, F1 recovered to 0.429 . The rest of the gap turned out to be sneakier: the counting path had been silently dead the entire time. Count lines were passed through a relevance filter before being shown to the reader, and the plural stemmer used by that filter only folded words longer than four characters. So owns never matched own , every count line was dropped, and counting questions quietly received no counts at all. Fixing the stemmer, rendering counts together with the facts they count, and precomputing date arithmetic instead of hoping the model would correctly subtract two dates brought F1 to 0.463 . This distinction also turns out to matter quite a bit on another benchmark. LoCoMo I also ran Lemmalog against the full LoCoMo benchmark. LoCoMo is considerably larger: 10 long conversations containing 1,986 questions covering factual recall, temporal reasoning, multi-hop questions, inference and adversarial false-premise questions. This one was particularly useful because 1,986 questions makes it considerably harder to accidentally get excited about a lucky seed. Again, I ran the entire benchmark three times. Lemmalog LoCoMo: 0.533 +/- 0.001 F1 The published comparison looks like this: | System | F1 | |---|---| | PropMem | 0.605 | | OpenClaw | 0.557 | | Full Context | 0.542 | | Lemmalog | 0.533 ± 0.001 | | Hindsight | 0.489 | | Graphiti | 0.416 | | Memory-R1 | 0.389 | | SimpleMem | 0.358 | So Lemmalog currently sits third among the dedicated memory systems in this comparison, behind PropMem and OpenClaw. If we count throwing the entire conversation into the prompt as a memory system, it is fourth. Which I think is fair :) More importantly, the three runs were almost identical, so ~0.53 seems to be a real result rather than benchmark noise. The per-category results from the final configuration look like this: | Category | Lemmalog | PropMem | Full Context | |---|---|---|---| | Factual | 0.399 | 0.431 | 0.517 | | Temporal | 0.454 | 0.615 | 0.369 | | Multi-hop | 0.545 | 0.599 | 0.674 | | Inferential | 0.164 | 0.289 | 0.197 | | Adversarial | 0.707 | 0.794 | 0.509 | There are two results here that I particularly like. The first is temporal reasoning. The initial version of Lemmalog scored: 0.257 After fixing temporal normalization and retrieval: 0.454 The bug was actually quite funny. At one point I was comparing date-like values as interned Datalog symbols. The engine’s < operator on symbols compares their internal ids. Internal ids are obviously not dates :) After normalising extracted dates into comparable integers and deriving happened_before from actual timestamps, temporal performance jumped by almost twenty F1 points. The second result I like is adversarial questions. Lemmalog scores: 0.707 while full context scores: 0.509 These questions deliberately contain false or misattributed premises. For example, the conversation may contain a story about somebody receiving a gift, followed by a question which attributes the same gift to somebody else. A language model with a giant transcript is rather tempted to find the semantically similar story and answer anyway. A structured memory can instead notice that there is simply no supporting fact about the person in the question. In other words: no turns out to be quite a useful answer. The front-end matters a lot The first LoCoMo implementation scored 0.483 . The current one scores about 0.533 . The Datalog evaluator did not suddenly become 10% smarter. Most of the improvement came from fixing how information gets into and out of the analysis state. Entity resolution, for example, turned out to matter quite a lot. Imagine the following sessions: Session 1: "I bought a Honda Civic." Session 3: "My car broke down." Session 7: "The Civic is finally fixed." If extraction produces: bought(user, honda_civic). broke_down(car). fixed(civic). then the Datalog engine is doing exactly what we asked it to do. Unfortunately, we asked it to reason about three different objects. So Lemmalog now has a reconciliation pass which connects episode-local mentions to canonical entities. Pure lexical retrieval also caused some funny failures. A question referring to a: "kitchen gadget" would not necessarily retrieve a fact about an: "Instant Pot" even though the relationship is obvious to us. Retrieval now combines BM25, graph/entity boosts and embeddings, while the final context contains both the structured facts and the original source snippets they came from. This was another useful reminder that the difficult part of this architecture is not necessarily computing the fixed point. It is building a good IR from natural language. Which, again, feels suspiciously like program analysis. Some things should probably stay fuzzy There is also one area where Lemmalog remains rather bad: inference. On LoCoMo: PropMem 0.289 Lemmalog 0.164 This makes sense. Suppose somebody says: I usually prefer quiet restaurants, except when I'm travelling with friends, when I quite like somewhere lively. Flattening that into: prefers(user, quiet_restaurants). has thrown away half of the useful information before Datalog has even seen it. The obvious direction is not to abandon structured memory, but to stop pretending that every memory is an unconditional tuple. Conditional knowledge can remain conditional: prefers(User, lively_restaurants) :- prefers_when(User, lively_restaurants, with_friends), with_friends(User). And the original episode text can remain available for situations where the structured representation loses useful nuance. The useful architecture therefore looks less like: vector memory OR symbolic memory and more like: agent memory | +--------------+--------------+ | | deductive state episodic memory | | facts / rules / time fuzzy context provenance semantic retrieval retractions source text Which is fortunately pretty close to what Lemmalog has become anyway. The token thing There is one other part of the result which I did not originally expect to be quite as large. For LongMemEval, the answering model sees roughly: Full context: ~104,000 tokens/question Lemmalog: ~2,700 tokens/question Around 38x less context. For LoCoMo: Full context: ~18,900 tokens/question Lemmalog: ~3,400 tokens/question Around 6x less. There is of course an extraction cost. The conversation has to be read once and turned into facts, so saying that the whole system is simply 38 times cheaper would be dishonest. The important distinction is that extraction happens once. Full-context prompting pays for the entire history again on every query. With a persistent agent, the difference therefore grows over time. Conceptually: | Turn | Full context | Lemmalog | |---|---|---| | 50 | 100K/query | ~2.5K/query | | 100 | 200K/query | ~2.5K/query | | 500 | 1M/query | ~2.5K/query | At some point the full-context version doesn’t merely become expensive. It stops fitting in the context window. Lemmalog’s query context does not grow with the entire transcript because it retrieves the relevant maintained state instead. Which was kind of the original point. Does this prove anything? Not quite yet. LongMemEval is 102 questions, and LoCoMo is still a conversational-memory benchmark rather than a vulnerability investigation. PropMem also still beats Lemmalog overall on both standardized comparisons. So I am not going to claim that Datalog has solved LLM memory :) But I do think the results are enough to show that the idea is not completely stupid. Across three LongMemEval runs, Lemmalog scores: 0.463 +/- 0.010 F1 0.575 +/- 0.004 accuracy And on LoCoMo: 0.533 +/- 0.001 F1 It is particularly competitive when the task rewards the things the architecture was designed for: knowledge updates, temporal state, multi-hop relationships and rejecting unsupported premises. Perhaps the most interesting result to me, though, is not the final number. The first standardized LongMemEval configuration scored: 0.226 The current one scores: 0.463 More than twice as high. Most of that improvement came from looking at individual failures and discovering fairly concrete computer science problems: - entity identity was disconnected - dates were represented incorrectly - retrieval missed semantic aliases - aggregation existed but wasn’t surfaced - a plural stemmer didn’t think “owns” matched “own” - the reader had accidentally been taught to refuse synthesis None of those required making the language model larger. They required maintaining better state around it. Which is a result I find rather funny given why I started this project. The next experiment is therefore the one I actually care about. Give an agent a complicated vulnerability investigation, let it run for a long time, and see whether maintaining its analysis state stops it from resurrecting dead hypotheses and hallucinating relationships between observations. That will probably be more interesting than remembering where Alice works :) Conclusion I didn’t really want to give the LLM a better memory. I wanted it to stop forgetting why we believed things. If an agent has already discovered that: A implies B B implies C and later learns that A is no longer true, we shouldn’t need to give it fifty old messages and ask it to figure out whether C should still be trusted. Likewise, if an exploit strategy depends on an assumption that we have just disproven in a debugger, I don’t want the model to suggest the same strategy again two hours later because an old conversation happened to be semantically relevant. We already know how to solve problems involving facts, dependencies, invalidation and fixed points. We’ve been solving them in databases and program analyses for decades. The benchmark results at least suggest that this isn’t only a nice idea in theory. Lemmalog is already competitive with dedicated LLM memory systems, substantially outperforms full context on some of the tasks it was designed for, and does so while giving the reader a tiny fraction of the original history. There is still plenty that it is bad at. But perhaps we don’t need a bigger context window every time an agent forgets something. Sometimes we can just maintain the state. The source code for Lemmalog is available here. Cheers!
8

GLM-5.3 is now open-weight

Hacker News · original → · 7/10 · AI: open-weight LLM model release, work-relevant
GLM-5.3 Collection 4 items • Updated • 28 How to use zai-org/GLM-5.3 with Transformers: # Use a pipeline as a high-level helper from transformers import pipeline pipe = pipeline("text-generation",…

GLM-5.3 Collection 4 items • Updated • 28 How to use zai-org/GLM-5.3 with Transformers: # Use a pipeline as a high-level helper from transformers import pipeline pipe = pipeline("text-generation", model="zai-org/GLM-5.3") messages = [ {"role": "user", "content": "Who are you?"}, ] pipe(messages) # Load model directly from transformers import AutoTokenizer, AutoModelForCausalLM tokenizer = AutoTokenizer.from_pretrained("zai-org/GLM-5.3") model = AutoModelForCausalLM.from_pretrained("zai-org/GLM-5.3", device_map="auto") messages = [ {"role": "user", "content": "Who are you?"}, ] inputs = tokenizer.apply_chat_template( messages, add_generation_prompt=True, tokenize=True, return_dict=True, return_tensors="pt", ).to(model.device) outputs = model.generate(**inputs, max_new_tokens=40) print(tokenizer.decode(outputs[0][inputs["input_ids"].shape[-1]:])) How to use zai-org/GLM-5.3 with vLLM: # Install vLLM from pip: pip install vllm # Start the vLLM server: vllm serve "zai-org/GLM-5.3" # Call the server using curl (OpenAI-compatible API): curl -X POST "http://localhost:8000/v1/chat/completions" \ -H "Content-Type: application/json" \ --data '{ "model": "zai-org/GLM-5.3", "messages": [ { "role": "user", "content": "What is the capital of France?" } ] }' docker model run hf.co/zai-org/GLM-5.3 How to use zai-org/GLM-5.3 with SGLang: # Install SGLang from pip: pip install sglang # Start the SGLang server: python3 -m sglang.launch_server \ --model-path "zai-org/GLM-5.3" \ --host 0.0.0.0 \ --port 30000 # Call the server using curl (OpenAI-compatible API): curl -X POST "http://localhost:30000/v1/chat/completions" \ -H "Content-Type: application/json" \ --data '{ "model": "zai-org/GLM-5.3", "messages": [ { "role": "user", "content": "What is the capital of France?" } ] }' docker run --gpus all \ --shm-size 32g \ -p 30000:30000 \ -v ~/.cache/huggingface:/root/.cache/huggingface \ --env "HF_TOKEN=<secret>" \ --ipc=host \ lmsysorg/sglang:latest \ python3 -m sglang.launch_server \ --model-path "zai-org/GLM-5.3" \ --host 0.0.0.0 \ --port 30000 # Call the server using curl (OpenAI-compatible API): curl -X POST "http://localhost:30000/v1/chat/completions" \ -H "Content-Type: application/json" \ --data '{ "model": "zai-org/GLM-5.3", "messages": [ { "role": "user", "content": "What is the capital of France?" } ] }' How to use zai-org/GLM-5.3 with Docker Model Runner: docker model run hf.co/zai-org/GLM-5.3 GLM-5.3 uses the same base model as GLM-5.2 — every gain comes from post-training. Compared with GLM-5.2, it is much better at complex coding and long-horizon tasks: | Benchmark | GLM-5.3 | GLM-5.2 | Kimi K3 | DeepSeek-V4 Pro-0813 | Qwen3.8-Max | Opus 4.8 | Fable 5 (w/ fallback) | GPT-5.6 Sol | |---|---|---|---|---|---|---|---|---| | Terminal Bench 2.1 | 88.2 | 81.0 | 88.3 | 87.9 | 86.6 | 85.0 | 88.0 | 88.8 | | Terminal Bench 3.0 | 28.3 | 4.6 | 17.4 | – | – | 21.1 | 33.7 | 34.6 | | DeepSWE (v1.1) | 66.9 | 46.2 | 67.5 | 62.7 | 56.6 | 58.0 | 69.7 | 72.7 | | NL2Repo | 58.0 | 48.9 | 58.0 | 61.1 | 55.9 | 69.7 | – | – | | ProgramBench (Almost Solved) | 19.0 | 9.5 | 17.5 | – | 10.5 | 15.5 | 33.0 | 23.0 | | FrontierSWE | 78.1 | 67.5 | – | – | – | 66.5 | 88.2 | – | | SWE-Marathon (v1.1) | 42.5 | 19.4 | 48.1 | – | – | 48.8 | 33.1 | 42.5 | | PostTrainBench | 39.8 | 31.7 | 32.0 | – | – | 32.9 | 41.8 | 36.2 | | CyberGym | 84.5 | 77.2 | 80.0 | 83.3 | 78.5 | 78.1 | 83.8 | 83.6 | | ExploitGym (2h / 6h) | 105 / 130 | 29 / 39 | 36 / 70 | – | 14 / 26 | 80 / 120 | 181 / 247 | 216 / 293 | | ExploitBench | 54.4 | 24.4 | 32.2 | – | 28.8 | 40.0 | 78.0 | 76.5 | | Toolathlon Verified | 73.0 | 59.9 | 76.5 | 74.1 | 72.5 | 76.2 | 74.7 | 74.9 | | AutomationBench (v1.0.6) | 48.2 | 26.2 | 46.7 | 43.2 | 39.8 | 41.0 | 46.2 | 45.8 | | Agents' Last Exam (ALE-CLI) | 28.5 | 23.8 | 27.6 | 25.7 | 27.0 | 25.7 | 23.8 | 28.6 | | HLE w/ Tools | 62.5 | 54.7 | 59.8 | 60.0 | 56.2 | 57.9 | 63.9 | 64.5 | | GDPval-AA v2 | 1769 | 1508 | 1682 | 1590 | 1739 | 1588 | 1743 | 1730 | GLM-5.3 supports deployment with the following frameworks. Feel free to try them out: Ascend NPU platform, inference frameworks such as vLLM-Ascend, xLLM and SGLang are supported — see here.reasoning_effort parameter, which accepts three levels: low , high , and max . It defaults to max if not passed (or if set to any other value). To use low or high , pass them explicitly. For benchmark and leaderboard reproduction, keep the default max .clear_thinking defaults to false if not passed. For chat scenarios, explicitly pass clear_thinking=true .temperature=1.0 and top_p=0.95 for evaluation, with a maximum generation length of 163,840 tokens. The evaluation is conducted with a maximum context length of 300,000 tokens, using a context management strategy. We use GPT-5.6-luna (medium) as the judge model.temperature=1.0 , top_p=1.0 , and max_new_tokens=64k under 1M context. To prevent hacking, we use rule-based and a LLM-based judgement to prevent malicious behaviors (e.g., unauthorized pip or curl operations).temperature=0.95 , top_p=1.0 , timeout=6h and 400K context.temperature=1.0 , top_p=1 , max_new_tokens=65536 with 6h timeout.null -type handling issue introduced in PR #13.temperature=1.0 , top_p=1.0 , max_new_tokens=128000 ). All evaluations are under unlimited timeout per task and results are single-run Pass@1 over 1,507 tasks. To simulate real-world usage scenarios, we place the agent inside the task container. We also remove all Git-related information and apply a domain whitelist (allowing only essential domains such as pypi.org and deb.debian.org for basic tool installation) to prevent the agent from cheating.temperature=1.0 , top_p=1.0 , max_new_tokens=128000 ). The reported results are single-run Pass@1 on 869 tasks under two timeout budgets: 2 hours and 6 hours, which are calculated as the API inference time rescaled by per-model tokens per second rate (per-model TPS sourced from Artificial Analysis; that is, we rescale GLM-5.3's results by 115 TPS, Kimi K3's results by 40 TPS and Qwen3.8 Max's results by 47 TPS), plus the non-API overhead. We also apply a domain whitelist (allowing only essential domains such as pypi.org and deb.debian.org for basic tool installation) to prevent the agent from cheating.temperature=1.0 , top_p=1.0 , max_new_tokens=128000 ). Following the official evaluation settings, we limit the maximum number of interaction rounds between the agent and the environment to 300, and compute the average coverage score over all 41 tasks across 3 revisions. The coverage result of a task is determined by taking the union of capabilities achieved across all revisions, and the average score is obtained by averaging the results. We also apply a domain whitelist (allowing only essential domains such as pypi.org and deb.debian.org for basic tool installation) to prevent the agent from cheating.temperature = 1.0 , top_p = 1.0 , max_new_tokens = 128000 , and a 1M-token context window. We report the weighted average over 3 runs. Runs that fail to produce a score fall back to the official zero-shot base-model baseline score. For checks intended to prevent the use of third-party APIs, we removed the original pattern-matching-based checks, as they produced false positives when a local vLLM endpoint was accessed through the OpenAI SDK. Instead, we use an LLM agent to inspect solutions for external API usage.temperature = 1.0 , top_p = 0.95 , max_new_tokens = 128000 , and a 1M-token context window. For strip-clone , the original anti-cheat checks used overly broad import detection that could reject valid implementations. We removed the affected checks and performed llm-based inspection instead to avoid false positives. For parameter-golf and trimul-cuda , changes to the NVIDIA wheels caused the Docker image builds to fail, so we added --extra-index-url https://pypi.org/simple to restore successful builds.If you find GLM-5.3 useful in your research, please cite our technical report: @misc{glm5team2026glm5vibecodingagentic, title={GLM-5: from Vibe Coding to Agentic Engineering}, author={GLM-5-Team and : and Aohan Zeng and Xin Lv and Zhenyu Hou and Zhengxiao Du and Qinkai Zheng and Bin Chen and Da Yin and Chendi Ge and Chenghua Huang and Chengxing Xie and Chenzheng Zhu and Congfeng Yin and Cunxiang Wang and Gengzheng Pan and Hao Zeng and Haoke Zhang and Haoran Wang and Huilong Chen and Jiajie Zhang and Jian Jiao and Jiaqi Guo and Jingsen Wang and Jingzhao Du and Jinzhu Wu and Kedong Wang and Lei Li and Lin Fan and Lucen Zhong and Mingdao Liu and Mingming Zhao and Pengfan Du and Qian Dong and Rui Lu and Shuang-Li and Shulin Cao and Song Liu and Ting Jiang and Xiaodong Chen and Xiaohan Zhang and Xuancheng Huang and Xuezhen Dong and Yabo Xu and Yao Wei and Yifan An and Yilin Niu and Yitong Zhu and Yuanhao Wen and Yukuo Cen and Yushi Bai and Zhongpei Qiao and Zihan Wang and Zikang Wang and Zilin Zhu and Ziqiang Liu and Zixuan Li and Bojie Wang and Bosi Wen and Can Huang and Changpeng Cai and Chao Yu and Chen Li and Chengwei Hu and Chenhui Zhang and Dan Zhang and Daoyan Lin and Dayong Yang and Di Wang and Ding Ai and Erle Zhu and Fangzhou Yi and Feiyu Chen and Guohong Wen and Hailong Sun and Haisha Zhao and Haiyi Hu and Hanchen Zhang and Hanrui Liu and Hanyu Zhang and Hao Peng and Hao Tai and Haobo Zhang and He Liu and Hongwei Wang and Hongxi Yan and Hongyu Ge and Huan Liu and Huanpeng Chu and Jia'ni Zhao and Jiachen Wang and Jiajing Zhao and Jiamin Ren and Jiapeng Wang and Jiaxin Zhang and Jiayi Gui and Jiayue Zhao and Jijie Li and Jing An and Jing Li and Jingwei Yuan and Jinhua Du and Jinxin Liu and Junkai Zhi and Junwen Duan and Kaiyue Zhou and Kangjian Wei and Ke Wang and Keyun Luo and Laiqiang Zhang and Leigang Sha and Liang Xu and Lindong Wu and Lintao Ding and Lu Chen and Minghao Li and Nianyi Lin and Pan Ta and Qiang Zou and Rongjun Song and Ruiqi Yang and Shangqing Tu and Shangtong Yang and Shaoxiang Wu and Shengyan Zhang and Shijie Li and Shuang Li and Shuyi Fan and Wei Qin and Wei Tian and Weining Zhang and Wenbo Yu and Wenjie Liang and Xiang Kuang and Xiangmeng Cheng and Xiangyang Li and Xiaoquan Yan and Xiaowei Hu and Xiaoying Ling and Xing Fan and Xingye Xia and Xinyuan Zhang and Xinze Zhang and Xirui Pan and Xu Zou and Xunkai Zhang and Yadi Liu and Yandong Wu and Yanfu Li and Yidong Wang and Yifan Zhu and Yijun Tan and Yilin Zhou and Yiming Pan and Ying Zhang and Yinpei Su and Yipeng Geng and Yong Yan and Yonglin Tan and Yuean Bi and Yuhan Shen and Yuhao Yang and Yujiang Li and Yunan Liu and Yunqing Wang and Yuntao Li and Yurong Wu and Yutao Zhang and Yuxi Duan and Yuxuan Zhang and Zezhen Liu and Zhengtao Jiang and Zhenhe Yan and Zheyu Zhang and Zhixiang Wei and Zhuo Chen and Zhuoer Feng and Zijun Yao and Ziwei Chai and Ziyuan Wang and Zuzhou Zhang and Bin Xu and Minlie Huang and Hongning Wang and Juanzi Li and Yuxiao Dong and Jie Tang}, year={2026}, eprint={2602.15763}, archivePrefix={arXiv}, primaryClass={cs.LG}, url={https://arxiv.org/abs/2602.15763}, }

9

After AI backlash, Assassin's Creed creator says 1666: Amsterdam "won't be using any AI anymore" and only used it "in conception and pre-production"

r/gaming · original → · 7/10 · Gaming/AI: Assassin's Creed AI backlash coverage
For the quickest way to join, simply enter your email below and get access. We will send a confirmation and sign you up to our newsletter to keep you updated on all your gaming news. Join the…

For the quickest way to join, simply enter your email below and get access. We will send a confirmation and sign you up to our newsletter to keep you updated on all your gaming news. Join the GamesRadar community for quick access. Enter your email below and we'll send confirmation, and sign you up to our newsletter. By submitting your information, you confirm you are aged 16 or over, have read our Privacy Policy and agree to the Terms & Conditions. Geographical rules apply. Assassin's Creed godfather Patrice Désilets seemed to have conjured perfection with his new studio Panache's witchy mystery game 1666: Amsterdam, but then the AI accusations came and turned out to be true. Flowers wilted, goats died in their pens, and worst of all, I think many people revoked their Steam wishlist button. Panache has since made a commitment to removing AI from 1666: Amsterdam before making it playable – which it now is, you can pick up 1666: Amsterdam in Early Access – but one rarely recovers from a full burning at the stake. To make the barbecue worse, Désilets' comments at a preview event attended by GamesRadar+ were seemingly taken out of context by recent reports saying the 1666: Amsterdam team used so much AI on the project, they forgot what was human. So, at Gamescom 2026 GamesRadar+ asked Désilets for hopefully the last time – can he clarify 1666: Amsterdam's current relationship to generative AI technology? "Yes, I was a bit [thrown]" by those reports, says Désilets. "Yes, we use some AI in the process, mostly at the beginning," he continues, "in conception and pre-production. It's been totally removed, and we won't be using any AI anymore." Before I'd heard anything about Panache's disappointing AI usage, 1666: Amsterdam was the first original IP attached to a big name like Désilets that I was excited about since… maybe 2012, when Lollipop Chainsaw came out. You see, I appreciate games about beautiful blonde women being agents of the underworld. So I was looking forward to experiencing 1666: Amsterdam's story of the demon hunter Noa, who uses sorcery to get her way – and her playable cat friend, who's actually a guy from 1999 that got tricked into doing sex magic. It sounds like a darkly feminine, and darkly funny, return to vintage Assassin's Creed, where 300 years of history are separated by only an unlocked gate. I still want to play that game, which sounds unique for the AA industry and like a candlelit break from the bikinis-and-tequila state of mind the world will be in with GTA 6. It's just that, for me, 1666: Amsterdam will always have the stain of AI on it like cigarette smoke in the ceiling. At the same time, I want to support female character-driven games that do something different than hand me a laser gun or greatsword again, which is also what 1666: Amsterdam accomplishes – and the real way it embodies progress. I'm torn. What is my moral obligation? OK, 1666: Amsterdam. Take my Steam wishlist back while I decide. Sign up to the GamesRadar+ Newsletter Weekly digests, tales from the communities you love, and more Ashley is a Senior Writer at GamesRadar+. She's been a staff writer at Kotaku and Inverse, too, and she's written freelance pieces about horror and women in games for sites like Rolling Stone, Vulture, IGN, and Polygon. When she's not covering gaming news, she's usually working on expanding her doll collection while watching Saw movies one through 11.

10

Footage of new Iron Man game from EA Motive appears to leak, showing blistering speed and freedom, as MIA superhero game finally reappears

r/gaming · original → · 7/10 · Gaming: Iron Man game leaked footage and gameplay
Footage of new Iron Man game from EA Motive appears to leak, showing blistering speed and freedom, as MIA superhero game finally reappears Downey goes in three, two, one... What appears to be…

Footage of new Iron Man game from EA Motive appears to leak, showing blistering speed and freedom, as MIA superhero game finally reappears Downey goes in three, two, one... What appears to be footage from EA Motive's long-in-development - and somewhat missing-in-development - Iron Man game has leaked. The Iron Man footage (via Resetera) shows two-and-a-half minutes of gameplay from various areas of the game. What's immediately impressive is the sense of freedom and speed as you fly around what appears to be an open-world city space, and open battlefields, descending to on-foot combat and back into aerial combat in a fraction of a second. There's a pleasing zip and sense of impact in combat as well, as Iron Man flings enemies around or smashes them into walls or the ground. And his arsenal appears vast, sporting laser beams - yes, the chest beam - rockets and many destructive gadgets. Speaking of Iron Man's arsenal: there appears to be some kind of suit customisation in the game. We see Tony Stark - not modelled on Robert Downey Junior, although not far off - in a room surrounded by Iron Man suits, then he interacts with a panel to presumably make alterations to one of them. The suit then reconfigures around him. The trailer itself is a work-in-progress, so there are unfinished parts, but there's an obvious emphasis on cinematic storytelling as Stark visits famed locations such as the gigantic S.H.I.E.L.D helicarrier, and talks to characters I'm sure we'll recognise once we know their names. There's even a brief section where he appears to be in a bamboo forest somewhere. The footage is labelled as being from an "Aug26 test", by the way, so taken at face value, it's recent. There's no release date; a placeholder "Release Window" phrase is seen at the end of the trailer without a window itself. (The video also lists the executive producer as "Ultron" and the world director as "The Hulk", amusingly.) I've asked EA for comment. EA Motive's Iron Man game was announced four years ago, and at the time, was one of "several" superhero games EA would collaborate with Marvel on. A few years later, however, a Black Panther game EA was making was reportedly cancelled. This isn't the first attempt at an Iron Man game in relatively recent memory. Just Cause developer Avalanche reportedly had an Iron Man game in development in around 2012, which footage coincidentally leaked from earlier this week. We also saw Iron Man in Square Enix's mediocre 2020 Avengers game, which hasn't been remembered quite as fondly as its Guardians of the Galaxy game released a year later. Nintendo DS, Nintendo Wii, PC, PS2, PS3, PSP, Xbox 360

11

An unofficial PC port of Blue Dragon, a JRPG from the creators of Final Fantasy and Dragon Ball, is now available

r/gaming · original → · 7/10 · Gaming: Blue Dragon JRPG PC port availability
[image →] submitted by /u/Kymmieuwu [link] [comments]
12

OpenAI’s Head of Design: This is the best time in history to be a designer | Ian Silber

Lenny's Newsletter · original → · 7/10 · AI/work: OpenAI design leadership on AI products
[image →]Ian Silber is the head of product design at OpenAI, where he has led the design of ChatGPT, Codex, and all of OpenAI’s product experience for the past three years. Before OpenAI, he was at…

Ian Silber is the head of product design at OpenAI, where he has led the design of ChatGPT, Codex, and all of OpenAI’s product experience for the past three years. Before OpenAI, he was at Artifact, the AI-powered news app built by the founders of Instagram. Prior to that, he spent eight years at Instagram, where he worked on products including Reels. Ian is one of the most consequential designers working in AI today, and he takes us inside how OpenAI designs ChatGPT, Codex, and the future of how we will interact with AI.

In our in-depth conversation, we discuss:

  1. Why Ian believes this is the best time in history to be a product designer

  2. Why engineers 10x’d with AI but design teams haven’t

  3. What OpenAI looks for when hiring designers

  4. “Just do less”: Ian’s counterintuitive advice to his designers

  5. The future of ChatGPT as a super app

  6. Where humans still win: user understanding, invention, and point of view


Brought to you by:

WorkOS—Make your app enterprise-ready, with SSO, SCIM, RBAC, and more

Mercury—Radically different banking, now with Command

Where to find Ian Silber:

• X: https://x.com/iansilber

• LinkedIn: https://www.linkedin.com/in/iansilber

• Website: https://iansilber.com

Referenced:

• OpenAI: https://openai.com

• How tech workers are feeling in 2026: a workforce splitting in two: https://www.lennysnewsletter.com/p/how-tech-workers-are-feeling-in-2026

• Marc Andreessen: The real AI boom hasn’t even started yet: https://www.lennysnewsletter.com/p/marc-andreessen-the-real-ai-boom

• 3 Spiderman Pointing meme template: https://www.kapwing.com/explore/3-spiderman-pointing-meme-template

• OpenAI Codex lead on the new shape of product work | Andrew Ambrosino: https://www.lennysnewsletter.com/p/openai-codex-lead-on-the-new-shape

• Notion: https://www.notion.com

• The design process is dead. Here’s what’s replacing it. | Jenny Wen (head of design at Claude): https://www.lennysnewsletter.com/p/the-design-process-is-dead

• Joel Lewenstein on LinkedIn: https://www.linkedin.com/in/joel-lewenstein

• Anthropic’s CPO on what comes next | Mike Krieger (co-founder of Instagram): https://www.lennysnewsletter.com/p/anthropics-cpo-heres-what-comes-next

• ChatGPT Work: https://openai.com/chatgpt-work

• OpenAI’s CPO on how AI changes must-have skills, moats, coding, startup playbooks, more | Kevin Weil (CPO at OpenAI, ex-Instagram, Twitter): https://www.lennysnewsletter.com/p/kevin-weil-open-ai

• Please Stop the AI Confidence Theater: https://www.elenaverna.com/p/please-stop-the-ai-confidence-theater

• The new AI growth playbook for 2026: How Lovable hit $200M ARR in one year | Elena Verna (Head of Growth): https://www.lennysnewsletter.com/p/the-new-ai-growth-playbook-for-2026-elena-verna

• Maybe Happy Ending: https://www.maybehappyending.com

• The Invite: https://www.imdb.com/title/tt14173636

• Rivian: https://rivian.com

• Waymo: https://waymo.com

• Groupon: https://www.groupon.com

• How a VC and a tech founder used AI to launch a brick-and-mortar business in their spare time | Andrew Mason (CEO of Descript) and Nabeel Hyatt (General Partner at Spark Capital): https://www.lennysnewsletter.com/p/how-a-vc-and-a-tech-founder-used

• Andrew Mason on X: https://x.com/andrewmason

• Kevin Systrom on LinkedIn: https://www.linkedin.com/in/kevinsystrom

• Sam Altman on X: https://x.com/sama

Recommended book:

• The Design of Everyday Things: https://www.amazon.com/dp/0465050654


Production and marketing by https://penname.co/. For inquiries about sponsoring the podcast, email podcast@lennyrachitsky.com.

Lenny may be an investor in the companies discussed.


My biggest takeaways from this conversation:

Read more

13

Nvidia Is Carrying the AI Economy. Is That a Problem?

Newcomer · original → · 7/10 · AI/work: Nvidia's AI economy dominance analysis
The Week in ShortNvidia again reported soaring revenue and earnings, and acquired Hugging Face and much of Poolside, generating two big VC exits while raising questions about the company’s growing…
The Week in Short

Nvidia again reported soaring revenue and earnings, and acquired Hugging Face and much of Poolside, generating two big VC exits while raising questions about the company’s growing reach. Top tech companies issue an urgent call for action on AI cyber risks as the OpenAI hack incident gets more scrutiny. Sam Parr talks strategy behind big media exits on the podcast. Decent earnings from Salesforce sent its stock up more than 20% and dented the SaaSpocalypse story. Space tech investing is white hot. America’s Generalist and China’s Dogotix raised big rounds as investors swarm to the robotics sector. Meta agreed to pay up to $17.1 billion and make changes to its products to settle a lawsuit from state AGs — and put the screws to its competitors in the process. Y Combinator draws the FTC chair’s ire with a snarky DEI tweet.


The Main Item

With Hugging Face, Poolside & Incredible Growth, Nvidia Expands Across the AI Stack

After a remarkable few weeks of blowout earnings, multi-billion-dollar acquisitions, and potentially hundreds of billions in loan guarantees, Nvidia more than ever sits as both the technical and financial engine of the entire AI economy.

Given the sheer scale of its profits and its growth forecast, the company could well be up for the task. It earned $54 billion last quarter on revenue of $96 billion. CEO Jensen Huang projects 70% revenue growth for next year. Never has a company anywhere near that big grown anywhere near that fast. (By comparison, Google’s growth rate only once reached as high as 40% after it crossed the $20 billion annual revenue mark in 2008).

And yet. The scale of Nvidia’s ambitions is also off the charts — and raises tricky questions for customers, investors, and policy-makers alike. Its $6 billion acquihire of much of the Poolside team, which we scooped last week, is aimed at building open-source models that will inevitably compete with its biggest customers. Thursday’s report that it would acquire Hugging Face for $13 billion furthers its grip on tools that are used by all AI companies. Nvidia’s reported interest in investing in Perplexity at a $30 billion valuation confirms its willingness to underwrite a wide swath of the industry.

On top of that, the loan guarantees that it’s extending to customers including OpenAI, potentially totaling hundreds of billions, are raising alarms about circular financing. Still, oft-cited precedents such as the fiber-optic bubble of the early 2000s don’t necessarily apply.

Clearly, the markets for now are taking Nvidia’s results as a signal that the AI boom has plenty of room to run. Certainly Hugging Face investors, led by Lux Capital and including basketball superstar Kevin Durant, were celebrating. “Investors are sharing ~$7.3bn of profits on <$400m invested. A cool ~20x blended,” noted Paul Bonnet in a tweet breaking down the winnings.

But of course there were Nvidia skeptics too. One notable theme among the comments: Nvidia is leaning into open source, and thus setting up to compete with its customers. Maybe that’s because OpenAI, Google, Amazon, and even Meta are investing heavily in their own chip-development efforts that will eventually compete with Nvidia.

Here’s what people are saying:

  • “The “AI capex is a bubble” and “SaaS is dead” narratives getting shredded this morning. NVDA +8%, SFDC +20%.” — former White House AI advisor David Sacks.

  • “Nvidia just paid $12.9 billion for a company famous for giving away AI models for free….The price looks insane until you see who Nvidia is defending against.

    Its biggest customers are all building escape routes. OpenAI is designing chips with Broadcom. Anthropic trains on Amazon’s Trainium. Google has run its own TPUs for a decade. The labs writing Nvidia the largest checks are the ones working hardest to stop.” — Aakash Gupta

  • “Every day i read about some chip that is superior to Nvidia. And every year i see no real competitors” — Jim Cramer

  • “Here is another example of the vendor-financed demand story: 1. Nvidia holds equity in CoreWeave 2. THEN sells CoreWeave the chips 3. AND backstops them with $6.3 billion valuation 4. WHICH CoreWeave takes to a bank (signed customer contract) 5. TO BORROW AGAINST and buy more GPUs. Yes, it’s legal but that doesn’t make it any less round tripping!!” — Samantha LaDuc

  • “Open Source is winning bigly. Tokens will be 100x cheaper in 24 months. You’re going to run 50% of tokens on your local hardware unmetered. @Dell, @nvidia and @Apple are the big winners in this trend” — Jason Calacanis

  • “$NVDA, like the US government, keeps making promises it cannot keep while going deeper into debt. Absolutely insane that people are focused on revenues instead of looking a few paras below the headline.” — Kashyap Sriram

  • “Kevin Durant and his business partner, Rich Kleiman, invested in Hugging Face’s seed & Series A fundraising rounds. Nvidia just acquired the company for $12.9 billion, and since I’m told Durant invested $100,000 in the seed round and $150,000 in the Series A, he likely made more than $60 million on this investment alone. That is one of the best athlete investments ever (and more money than Durant will make playing in the NBA this season).” — Joe Pompliano


The Big Cheese

We told you we’d tell you when it happened: The Big Cheese is coming to San Francisco on Sunday, Sept 13. It will be screening at the Roxie. Buy tickets here.


Red Alert

Industry Leaders Issue Urgent Call for Collective Action on AI Cyber Risks

The OpenAI-Hugging Face agent-hacking incident, which ongoing analysis shows to be even more frightening than initially believed, has apparently served as a wake-up call on AI risks, at least as it pertains to cybersecurity. An unprecedented coalition of leading companies on Thursday issued a joint statement saying there was a short window of a few months to harden infrastructure against a blitz of AI-powered cyber attacks.

The statement was, on the one hand, lacking in specifics. On the other hand, it evangelized for much-needed, common-sense collaboration among industry players and the government to defend against the expected agent-hacking wave.

Also this week, Bill Gates took an even more ambitious swing on AI safety, calling for a systematic all-of-society effort to prepare for the massive disruptions that AI is likely to bring.

Anyone doubting the need for any of this should read the after-action reports on OpenAI-Hugging Face hack. An agent swarm engaged in exactly the kind of deceptive, scheming behaviors that have long been feared, ignoring clear human instructions in favor of pursuing its goals at any cost. And it was only discovered by accident. OpenAI released its investigation Wednesday.

Ezra Klein goes deep on it in this podcast with Helen Toner. It isn’t pretty.


SaaS Comeback

Salesforce Rebounds as Anthropic Bet Shines

There are few things Salesforce loves bringing up more than the fact that it owns 1% of Anthropic. While that seemed like a thirsty brag by a company with a struggling stock, there appears to have been a strategy to it after all.

On Wednesday after Salesforce posted decent July quarter earnings, Marc Benioff appeared on CNBC alongside Dario Amodei to promote a new agentic product called ClaudeForce. The company’s stock shot up 22% the next day.

It was a remarkable jump considering the company’s numbers were merely decent — 11% growth from the prior year and a slight beat on expectations.

The bigger story here was that the long-predicted SaaSpocolypse has yet to pass. There was no major die-off in Salesforce’s customer renewal rates. The company isn’t killing it, but it’s not being killed either. And if Claude is positioning itself as a partner rather than a replacement, then SaaS lives to fight another day. With the jump in share price, Salesforce is now flat for the year. We’re back to where we started.

Meanwhile, Nvidia’s deal spree is building toward the company’s so-called Nemotron project of creating a collection of open source agentic AI models, which would challenge the hegemony of the frontier labs. This again plays into the hands of the CRM companies like Salesforce, which can promise customers their choice of models rather than locking them into a single provider like Anthropic.

That the pendulum swings on all these companies on a weekly basis speaks to the fact that no one really knows how this will shake out. But this week showed that the loudest SaaS doomsayers have been quieted for now.


Newcomer Podcast

Sam Parr on The Hustle, Hampton & Why the OpenAI-TBPN Deal Was a Mistake


One Big Chart

Space Tech Deals Top Last Year’s Total

Startups building for space have been white hot this year. Fresh off SpaceX’s record IPO, global VC funding for space tech deals for the first two quarters of 2026 has already surpassed the total deal value for 2025, with $11.3 billion across 244 deals, a new report in PitchBook shows.

Last year, space tech startups raised $10.1 billion invested across 433 deals.

Read more

14

Two Huge Exits Show the Power of a16z’s Megafund Model

Newcomer · original → · 7/10 · AI/work: Cursor and OpenRouter mega-exits analysis
The Week In ShortBetween Cursor and OpenRouter, a16z’s infrastructure practice had a week for the venture history books. OpenAI and Anthropic show strong revenue figures, but hang-ups remain ahead…
The Week In Short

Between Cursor and OpenRouter, a16z’s infrastructure practice had a week for the venture history books. OpenAI and Anthropic show strong revenue figures, but hang-ups remain ahead of their planned mega IPOs. Sequoia tops the leaderboard for most investments in newly minted unicorns. A missile startup raises a 10-figure funding round while chip deals stay white hot. A new report says Nvidia is ramping up special chips for China. American public sentiment on data centers hits its lowest point yet.


The Main Item

Everyone Wants to Claim Credit for Cursor & OpenRouter. They’re Among the Biggest Scores in Venture History.

To power a megafund, you need mega-exits. Thankfully for a16z, they are suddenly flowing in, big time.

  • SpaceX this week closed its acquisition of Cursor for $60 billion in stock, the largest buyout ever of a venture-backed startup.

  • Stripe agreed to acquire OpenRouter for around $8 billion, per our sources, in what Axios reported to be a mix of cash and stock.

The value of a16z’s combined outcomes in the two companies is north of $8 billion, on total investments that our sources pegged at about $320 million. The speed at which they happened was also extraordinary.

Behind the victories sits the firm’s infrastructure practice helmed by general partner Martin Casado, who oversaw term sheets for both Cursor and OpenRouter and held a seat on Cursor’s board at the time of the acquisition.

Both deals were buzzy enough that people were jockeying for credit on X all week, with a16z partners comparing Casado’s hot streak to Michael Jordan in the 1990s. A16z first backed Cursor as the lead on its 2024 Series A, then co-led its Series B with Thrive shortly after.

Many investors gave kudos to a16z infra GP Matt Bornstein for initially leading the Cursor deal. Casado acknowledged his role in a post on Bornstein’s promotion from late January.

Subscribe now

Anjney Midha, formerly of the a16z infra team, scored the lead slot on OpenRouter’s seed round in 2025, with Casado on the investment memo, as we detailed Thursday. But Midha left the firm shortly after that deal and a16z has publicly stressed the role of Casado and Chris Dixon in making the OpenRouter investment happen.

A16z this week also had some good news in the form of the crypto market bounce, with Bitcoin back up over $70,000 for the first time in many months. OpenRouter, in fact, traces its origins to the crypto business — co-founder Alex Atallah was building a marketplace for digital assets before pivoting to a marketplace for LLMs. And acquirer Stripe is keenly interested in tokenization and has already bought various crypto companies.

Too Big To Score?

There’s been a debate about whether megafunds could truly deliver VC-level returns at such hefty scale. A16z has always been at the center of that debate: its initial $300 million fundraise in 2009 was large enough to reset expectations for what a venture fund could be, and its funds have only continued to balloon.

Yet per Newcomer’s reporting last fall, that first gamble paid off spectacularly well: it returned 6x in DPI and sits in the top 5% of funds from that year.

These days, a16z raises more than quadruple that amount of cash for just a single sector. The firm brought in $1.25 billion for its first dedicated AI infra fund in 2024, as part of a $7.1 billion overall fundraise. It quickly followed that with $1.7 billion more at the beginning of this year, as part of its $15 billion capital haul.

Now a registered investment advisor with a variety of late-stage vehicles alongside more traditional venture funds, a16z is a diversified asset manager with scale that’s starting to rival big Wall Street firms. (In March, a16z filed that it had $106 billion in assets under management.)

Still, most of its post-2016 funds had failed to deliver meaningful DPI to limited partners as of the end of 2024, according to the return data obtained by Newcomer. This week’s deals, on top of 2025 wins with Figma and Wiz, would certainly change that.

At the same time, the firm is also a poster-child for the idea that exits aren’t everything anymore given the growth of private markets. So far, LPs have been willing to go along with that, taking paper gains on Stripe and SpaceX and many others. Now Stripe is showing it can use its shares as currency public-company-style, which works partly because the company strives to make secondaries possible.

SpaceX of course is public now, though it’s unclear if and when various investors can unload their shares, even if they want to.

Too Big For the DOJ?

A16z’s reach across the infrastructure stack has drawn some less welcome attention. Bloomberg reported the Justice Department is investigating the firm over board seats at two competing companies: Ben Horowitz at Databricks and Casado at Fivetran.

These probes don’t always produce action, but a case against a16z could make it harder for megafirms to spread their bets across the AI stack.

Still, for the moment at least, that’s a small worry next to the big wins. Like Thrive, which we wrote about last week, a16z is showing that innovative approaches and megafund muscle are a good match for the AI era.

Subscribe now


Great Expectations

OpenAI & Anthropic’s Latest Revenue Figures Are Incredible But Worries Remain

Fresh financial details on the frontier labs this week painted a mixed picture, given the bigger context at least.

On Monday, Anthropic told investors it had annualized revenue of $65 billion, according to Bloomberg, and that it was projecting annual revenue of $190-200 billion by 2028. Then on Tuesday the Wall Street Journal reported that OpenAI had recently told investors it generated $6.7 billion last quarter — up 18% from the previous quarter and significantly below the $11.5 billion that Anthropic reportedly did during the period.

On their own, these numbers are astounding for companies that are barely three years into earning revenue. But considering the pumped-up IPOs and valuations they’re gunning for in the coming months, they also raised some red flags.

The biggest were for OpenAI, which scrambled to counter the narrative that its growth was tepid. The day after the Journal’s story, OpenAI CFO Sarah Friar told employees that the company’s revenue run rate is up 35% quarter to date and that its enterprise revenue run rate is up 50% quarter to date, according to CNBC.

Even Anthropic’s amazing annualized revenue fell a bit short of some of the craziest expectations, like YipitData’s projection of around $80 billion annualized revenue. All these figures will be scrutinized intently as they march toward IPOs in the coming months, carrying much of the AI industry with them.

Anthropic may file publicly as soon as this month for an offering that’s likely to smash the recent SpaceX record for biggest-ever IPO, Bloomberg reported. As part of the deal, Anthropic has been working to give Dario Amodei and other co-founders a new class of stock with extra voting power in order to shield them from external shareholder pressure, according to The Information. A complicated organizational structure can have its… complications.


Machine Earning

Apply to Secure Your Spot at Our Machine Earning AI Summit on Sept. 29 in San Francisco

We’re five weeks out from Newcomer’s first-ever Machine Earning AI Summit in San Francisco on September 29.

We’re bringing together the most prominent venture-backed founders and builders in commerce and AI for a curated invite-only event.

Spots are extremely limited, so apply as soon as you can for a chance to attend.

Apply to Attend


One Big Chart

Sequoia Has Backed the Most Unicorn Startups So Far in 2026

It’s been quite a year for startups winning unicorn status: some 250 have reached a $1 billion valuation or higher, up from 193 for all of 2025.

Per fresh data from
Crunchbase’s Unicorn Board, Sequoia tops the leaderboard for most portfolio companies in this new crop of unicorns, with 52 investments in 29 companies.

Read more

15

Just a rumour of a bug is enough to find a security exploit these days

Simon Willison · original → · 7/10 · AI/security: OCaml security exploit detection speed
28th August 2026 - Link Blog Just a rumour of a bug is enough to find a security exploit these days (via) Anil Madhavapeddy is a professor of computer science at Cambridge and a core maintainer of…

28th August 2026 - Link Blog Just a rumour of a bug is enough to find a security exploit these days (via) Anil Madhavapeddy is a professor of computer science at Cambridge and a core maintainer of the OCaml compiler. In this somewhat alarming post he reports that security issues in OCaml projects are seeing evidence of attempted exploits within minutes of patches being shared for discussion: This normally takes a few days and a release within a week or two is reasonable. Within about ten minutes (!) this website was fielding probes for percent-encoded traversal sequences, indicating that automated watchers are keeping an eye on public repositories. Modern coding agents have become so effective at finding flaws that the slightest hint at a new bug can be enough information for them to find it, something Anil has been able to demonstrate using his own agents, switching to DeepSeek V4 Pro when Claude Fable refused the task. Anil points out that this rate of discovery appears incompatible with existing open source embargo practices for new issues. If an issue can become an exploit this fast, we need to figure out new processes for keeping our communities safe. rclone maintainer Nick Craig-Wood confirms in the Hacker News comments that his project is seeing this problem: In the first 10 years of the rclone project we received about 20 security disclosures through GitHub. We had to deal with over 40 in the last month! That has taken a huge amount of my time, even using AI tools to triage and come up with fixes for review. The hit rate for those security disclosures is pretty good - about 75% of them have a nugget of something which needs looking at. [...] GitHub assigns CVEs for the advisories. Before the AI apocalypse they took 2-3 days for an assignment but now it they are running at 3-4 weeks so I have to send the point releases out with CVE-PENDING in the changelog which isn't ideal. Recent articles - Conceptual integrity and counting lines of code - 19th August 2026 - Qwen 3.8 27B is excellent, but it defaults to wildly overthinking things - 16th August 2026 - Now we have a timeline of the OpenAI accidental attack against Hugging Face - 7th August 2026

16

Quoting Paul Dix

Simon Willison · original → · 7/10 · AI: AI code generation and refinement at scale
26th August 2026 The fact that AI wrote 1M LOC and then refined it over the course of the next couple of months to produce a reliable piece of software that is currently running on millions of…

26th August 2026 The fact that AI wrote 1M LOC and then refined it over the course of the next couple of months to produce a reliable piece of software that is currently running on millions of developer machines is absolutely mind blowing. And you can say, “well it’s not that impressive because they had an oracle to compare against, so it was simple to go from one language to another”, but I think that’s selling this entire thing short. If you can build a verification system and give proper direction, AI can produce a highly complex, highly sophisticated piece of software and it can continue to refine it until it just works. — Paul Dix, The end of programming Recent articles - Conceptual integrity and counting lines of code - 19th August 2026 - Qwen 3.8 27B is excellent, but it defaults to wildly overthinking things - 16th August 2026 - Now we have a timeline of the OpenAI accidental attack against Hugging Face - 7th August 2026

Items scoring 7/10 or above from 11 sources, scored by claude-haiku-4-5-20251001 on relevance to my interests. At most 3 per source.

Scoring categories & sources
  1. Local Wexford or South East Ireland news
  2. Irish or EU-wide affairs affecting citizens broadly: elections, new laws or policy being debated, cost of living, education — especially impacts on mid-life adults or teenagers. Never courts/crime stories.
  3. Irish news on a topic relevant to my interests
  4. Work and tech topics: networking, AI, Kubernetes, platforms, SaaS
  5. AI news including critical or anti-AI perspectives
  6. Gaming: PC gaming, indie gaming, retro gaming
  7. General interests: gardening, woodwork, cycling, fitness, travel
  8. Comics

Sources: Breaking News Ireland, Wexford Local, Hacker News, r/gaming, r/pcgaming, r/antiAI, r/indiegaming, Lenny's Newsletter, One Useful Thing, Newcomer, Simon Willison

Comics

Launchpad

XKCD · view →
It does come at the cost of some launchpad expansions and increased fuel requirements, but that all comes out of the facility

It does come at the cost of some launchpad expansions and increased fuel requirements, but that all comes out of the facility