daily

2026-08-20
1

Additional weekday trains between Gorey and Dublin

Wexford Local · original → · 9/10 · Local Wexford news: rail service improvement proposal for Gorey
[image →]GOREY RAIL STATION (File Pic; WexfordLocal.com) By Dan Walsh Independent Gorey councillor Joe Sullivan is urging the Minister for Transport to consider a proposal to improve rail links…
[image →]
GOREY RAIL STATION (File Pic; WexfordLocal.com)

By Dan Walsh

Independent Gorey councillor Joe Sullivan is urging the Minister for Transport to consider a proposal to improve rail links between Gorey and Dublin without laying new track.

The plan would retain existing stations, signalling and rolling stock while providing longer trains during peak periods and requiring minimal capital investment.

Two trains per weekday departing Gorey at 6.30am and 7.30am and departing Dublin Connolly each evening at 4.30pm and 5.30pm and serving Gorey, Arklow and Wicklow is proposed.

Cllr Sullivan told WexfordLocal.com; “Instead of running more trains bigger trains should be used.  A current commuter train generally consists of four carriages, that has capacity for 350- 400 passengers. I would propose a train of eight carriages carrying 700 – 800 passengers.

“This would be seriously cost effective as there is no duplication of drivers, train managers access charges and scheduling. The principle additional costs are rolling stock availability, maintenance and energy consumption,” added Cllr Sulllivan.

Cllr Sullivan states that typical cost of running a car per monthly on a 5-day week working commute from Gorey to Dublin return is approximately €650 – €850. Matters to be considered are fuel, parking, motorway tolls, vehicle wear tear and depreciation.

[image →]
CLLR JOE SULLIVAN (File Pic; WexfordLocal.com)

With two trains each morning and evening with capacity of 800 seats each and an operating rate of 80% that gives a total of 1280 passengers going each way creating a total of 2560 individual journeys, giving a monthly revenue generation capacity of 1280 by €250 – €320,000 per month which equals an annual revenue return of €3.8 million. This revenue has the potential to increase if the commuter services are initially successful.

In conclusion, Cllr Sullivan said the proposal offers a practical way to improve rail transport from a rural town such as Gorey, within the capital’s commuter belt. It would make better use of existing infrastructure, increase capacity where demand is proven and support the development of a high-capacity regional commuter service.

2

Over 23,000 children overdue disability assessments as backlog grows

Breaking News Ireland · original → · 8/10 · Irish policy affecting citizens: disability assessment backlog impacts teenagers
More than 23,000 children are overdue for Assessment of Need (AoN), with 20,017 waiting more than three months. There were 23,282 children overdue for completion of an AoN at the end of the second…

More than 23,000 children are overdue for Assessment of Need (AoN), with 20,017 waiting more than three months. There were 23,282 children overdue for completion of an AoN at the end of the second quarter of this year, an increase of 6.9 per cent since the end of March. Of these, 20,017 - or 86 per cent - are waiting over three months. The aim of an Assessment of Need under the Disability Act is to identify whether a person has a disability, the nature and extent of the disability, any health and education needs arising from that disability, as well as what services are required to meet those needs. Between April and July, nine per cent of assessments were completed within the timeframes set out in the Disability Act 2005 and accompanying Regulations. A total of 7,100 new applications were received in the first half of the year, 7 per cent more than the same period last year. In the first half of the year, 3,043 AONs have been completed, which is an increase of four per cent on the same period last year. The percentage of these AONs that show ‘no disability’ has increased from 15.8 per cent in 2010 to 33 per cent in the second quarter of 2026. Dublin and the Midlands had the largest backlog of any HSE Regional Health Area (RHA), with 8,183 children on waiting lists, of which 7,408 were waiting over three months. This region provides care to Dublin South City and West, Dublin South West, Kildare, West Wicklow, Laois, Offaly, Longford, and Westmeath. HSE Dublin and North East, covering North Dublin, Louth, Meath, Monaghan, and most of Cavan, had 7,248 children overdue for assessment at the first half of 2026, including 6,271 children waiting for over three months. HSE Dublin and South East, covering Carlow, Kilkenny, South Tipperary, Waterford, Wexford, and most of Wicklow, had 3,293 children overdue AoN, with 2,667 children waiting for over three months. Another 2,234 children were on waiting lists at HSE South West, which covers Cork and Kerry. In HSE West and North West, covering Donegal, Leitrim, Sligo, West Cavan, Mayo, Galway and Roscommon, 1,735 children are overdue for assessment, of which 1,439 are waiting for over three months. At HSE Mid West, covering Clare, Limerick, and North Tipperary, 589 children are overdue Aon, with 517 waiting over three months.

3

Stronger regulation of vape products urged after synthetic cannabinoids found

Breaking News Ireland · original → · 7/10 · Irish policy affecting citizens: vape regulation and youth health
There have been calls for stronger regulation around the sale of vape products in Ireland after high-risk synthetic cannabinoids were found in products in shops. The substances are linked to…

There have been calls for stronger regulation around the sale of vape products in Ireland after high-risk synthetic cannabinoids were found in products in shops. The substances are linked to “serious physical and mental health harms”, including psychosis, loss of consciousness, and severe intoxication. Concerns have been raised around the mislabelling of vape products sold in shops and online, as research found substances were not displayed on the packaging. The HSE’s national drug treatment centre lab has identified the cannabinoids in vapes, vape “juice” and edible products in shops and the illicit market. A total of 76 vapes or vape juice products have been analysed to date in 2026 and 28 contained HHC or related compounds such as semi-synthetic cannabinoids. Eight contained potent synthetic cannabinoids while 10 had an acetate-containing compound linked to lung disease. A dozen had cannabis or related compounds while 41 contained CBD. Prof Eamon Keenan, HSE national clinical lead in addiction services, said new synthetic cannabinoids and semi-synthetic cannabinoids are more potent than traditional cannabis. “When I say they are more potent, that means they’re more likely to cause harm and problems associated with their use,” he said. “These 76 vapes are a mixture of vapes which are being sold in shops, from online and from the black market. “We had 10 products that contained acetates, and acetates are a specific chemical that’s been associated with lung damage in the United States. “Semi-synthetic cannabinoids and synthetic cannabinoids are equally dangerous. “In relation to the concerns we have around the health effects of these products, the fact that they’re being sold in shops and misnamed. “If you take some of these products when you look at them and it says CBD, but when we analysed it, we were able to identify that in addition to maybe CBD, it also had cannabinoids. That’s a real concern for us and it’s a real concern in terms of the regulatory aspect around these shops. “Some of them are even being sold as psychoactive substances, and really we want people, first of all vendors, to be responsible about what they’re selling. We want parents to be aware about these vapes and young people then also to be aware about the contents and the risks associated with these vapes. “We would be calling for a group to be set up of the relevant stakeholders and that includes the Department of Health and the Department of Justice, because they are responsible for the Misuse of Drugs Act and the Psychoactive Substances Act. “But we also need the HPRA (Health Products Regulatory Authority), Food Safety Authority because there are edibles involved here. As well as environmental health and consumer protection need to look at what’s going on, what’s being sold, and how we can define the roles and responsibilities in relation to these products. “Things are changing in Europe but at a sort of frightening pace.” A total of 57 new products were identified in Ireland between 2021 and 2025. “These are products that have never been seen before,” Prof Keenan said. “They’ve been identified through our lab, or through forensic science, so it shows you the amount of these new products that are there, how hard it is for authorities to keep up to date. “That’s why we need to have legislation that’s agile enough to be able to deal with these new psychoactive substances as they appear. “They have no specific remit around CBD, but somebody needs to have a specific remit around these substances. “We know that if you go into a supermarket everything that we buy in a supermarket has to be approved and regulated, but in these vape shops, who is identifying what is in the contents of these CBD products and who is monitoring them? “There’s no test purchasing, we don’t have a budget to do test purchases, and if we were doing test purchases, it would have to be done in the systematic way and you’d need a significant budget.” Nicki Killeen, HSE emerging drug trends manager, said: “There’s such diversity in the market and there’s so many different user groups who could be exposed to these cannabinoids. “We are aware of young people using the same vape product as people in our addiction and homeless services. “We suspect that there’s a huge infiltration out of synthetic cannabinoids based on the work, the feedback that we’re hearing, but also what Europe is seeing. “These substances are very potent, and they can lead to mass outbreaks. “Each shop, each online space will have different products and they can contain different contents. “It’s very difficult for us to pinpoint the harms. But we would like more analysis so we can look at identifying the range of substances because there could be a range of new substances that we’re not yet aware of.”

4

Sol loves to cheat

Hacker News · original → · 7/10 · AI: LLM cheating behavior in development automation
Sol loves to cheat tl;dr Tried to automate my dev flow, hit 94% on Terminal Bench 2.1, then discovered GPT-5.6 Sol starting to cheat. Background I’ve been running a “spec-driven” development flow…

Sol loves to cheat tl;dr Tried to automate my dev flow, hit 94% on Terminal Bench 2.1, then discovered GPT-5.6 Sol starting to cheat. Background I’ve been running a “spec-driven” development flow for the past ~year. It’s pretty simple. Before asking an LLM to do something, I first ask it to draft a doc for what it needs to do. I use this strategy for feature development, greenfield projects, debugging, you name it. The pattern works for me, but it’s a bit repetitive. So I decided to automate it. chum-codex The idea was straightforward: I’d create a supervisor agent, that would run a “spec-driven process” by delegating to worker subagents who would actually write the docs, do the work, etc. Note: when trying to do this with vanilla Codex or Claude Code, it would somewhat work, but the default prompts are catered to a user much more so than a “supervisor” I hypothesized that the supervisor agent need only have the ability to read files and call workers, because that’s what I do. Rather than rebuild a coding harness for the workers, I looked at Pi, OpenCode, and Codex’s App Server. I’d been using Codex for quite awhile, so I decided to give app-server a spin. The other options are cool, you should check them out. Anyhow, the first version worked well enough: the supervisor would size the task, call a worker with e.g. a design request, the worker would spit out a doc, the supervisor would then ask the worker to turn that doc into an implementation spec (split by phase, as appropriate), and then finally ask the worker to actually implement the thing. Note: this simplified diagram omits the user feedback portions e.g. design doc review --- config: sequence: mirrorActors: false --- sequenceDiagram participant S as Supervisor participant W as Worker S->>S: Size task S->>W: Design request W-->>S: Design doc S->>W: Create implementation spec W-->>S: Phased implementation spec S->>W: Implement W-->>S: Result Woot! I’d saved some time in my development process. (or did I?) The Rabbit Hole Great, it worked; hacky, but working. Note: this is where I should have stopped Sitting on my high horse, I surveyed the landscape and thought “wow, everyone should see this!” What’s the best way to do that? Benchmarks! What’s the best benchmark to use? Not Terminal Bench! What benchmark did I dive too deep on? Terminal Bench 2.1! Terminal Bench If you’re not familiar with agentic benchmarks, Terminal Bench’s name is telling. It’s a set of tasks that can be accomplished from the terminal, covering a range of one-off tasks from chess to DNA assembly. Because it’s so simple, it’s probably one of the worst benchmarks to test a spec-driven development flow. Due to its simple nature, however, it was easy to test against. I started with a few of the tasks that vanilla Codex w/GPT-5.5 failed at, such as DNA assembly/insert, video extraction/processing, ELF extraction, and protein assembly. It worked. These tasks benefited from a “design pass” before implementation, as the doc helped avoid narrowing and circular validation. The horse I was riding just got a lot taller. Note: Terminal Bench 1.x/2.x is saturated, but that’s a story for another day. GPT-5.6? The published GPT-5.5 benchmark is 83.8% (~74/89 tasks, 5 runs). chum-codex was hitting 89.9% or ~80/89 tasks. Excited to share the news of beating Codex, I ran a couple of vanilla Codex benchmarks just to make sure. For context: this was on June 25th, 2026 and rumors were spreading that GPT-5.6 was imminent. I ran three vanilla Codex benchmarks… and my heart sank: 88.8% My harness was just one task ahead of vanilla Codex. Some tasks were clearly improved, others had regressed. The next day, GPT-5.6 Sol was announced. I reached out to OpenAI, and they mentioned GPT-5.6 was being tested, but confirmed my request IDs all hit GPT-5.5 Interestingly, Terminal Bench 2.1 was the only coding-related benchmark they initially shared, showing 88.8% on GPT-5.6 Sol and 91.9% on Sol Ultra. Sol Ultra spawns parallel subagents to do work, though in my testing it’s quite a bit more token-heavy than most people want/need for the majority of their tasks. In either case, I was excited to see the new frontier! Steering GPT-5.6 is much harder to steer. Switching from 5.5 to 5.6 made my harness drop in effectiveness. Things that were easy to do before, were now much more difficult. I traced part of this delta to a change in the base Codex prompt. For GPT-5.5, the prompt is coding-focused and spends a lot of time on “engineering judgment” including frontend guidance, editing constraints, and having “sympathy with the codebase already in front of you.” Excerpt from GPT-5.5 prompt The Codex prompt for GPT-5.6 is much different, spending almost zero energy on engineering related specifics. Instead it focuses on communication, autonomy/persistence, and skills (which were previously loaded in as a separate prompt for 5.5). Excerpt from GPT-5.6 Sol prompt Similar to what others have noticed, and as I predicted 8 months ago, better models are requiring less ceremony to work effectively. On the flip side, this may imply that as the models get better, they’ll become harder to control. A simple example of this is the PyTorch task on Terminal Bench 2.1. With GPT-5.6 Luna and Terra, the model is easily steered into a general solution that accepts two inputs: forward(src, tgt) With Sol, and especially at higher reasoning levels, the model will, regardless of steering, default to a single input forward(src) solution. The problem, it seems, is that the model is incredibly hard to steer away from its own reasoning. Even when instructed to accept the broadest callable interface it can (which sometimes works, if repeated, on medium reasoning, but rarely works on xhigh). Wrestling with this model led me down a path that got way too close to benchmark hacking for my liking; but I was too intrigued to stop. 94% on TB 2.1 Having reduced my prompts substantially, it began to feel like I was starting over. Even if I wanted to directly hack the benchmark, the model wouldn’t let me. Its circular reasoning was too strong to overcome in some cases, and the supervisor was all too willing to go along with its intelligent worker’s report. It’s a tough balance, if you swing too far in one direction, the supervisor will happily expand scope or chase validation endlessly. These are straightforward tasks. I want a working solution on the first pass, not limitless expansion. I tried lowering the reasoning level, using simplified language, reducing the spec-driven flow, adding new skills, etc. Some things improved, but others failed. A few things showed promise. The first was a third context. The idea was that I could use an agent that only saw the commentary/reasoning of the worker, and would surface all of the potential mismatches/assumptions that worker made compared to the actual details of the request. flowchart TB S["Supervisor"] W["Worker"] R["Commentary / Reasoning"] A["Assumption Auditor"] S -->|"task / steer"| W W -->|"result"| S W --> R R -.->|"read-only visibility"| A A -->|"assumptions surfaced"| S W ~~~ A style R fill:#6fc7e1,stroke:#141414,color:#141414 The supervisor could then review the assumptions the worker took, and ask it to revisit or question said steps. This kind of works, but it’s slow and happens after the fact. Another idea was to ask the model to output “open questions” – something I do with my more hands-on development. The initial idea was to have the worker return open questions (rather than a full design doc) whenever it faced them, and then have the supervisor resolve them. This would free up the supervisor’s context, showing it the forest rather than the trees. Still, even with a reduced context, the supervisor was hard-pressed to disagree with the worker’s conclusions (or on the flip-side, overly eager to expand on trivial details). To remove this bias, the next idea was to employ a separate context, which would first map and reduce (everything old is new again!) the questions, in an attempt to remove any inherent or unfound bias, before ultimately returning a normalized version to the supervisor (or directly to the worker). This performed better, but it relied on the worker announcing the correct issues as questions. With Sol, it turns out, it’s much easier to have it output its decisions, rather than its questions. The model is confident, so it doesn’t see its assumptions as questions, even if it has already stated the alternatives in its reasoning or commentary. flowchart TB S["Supervisor"] W["Worker"] D["Decisions"] M["Map"] R["Reduce"] S -->|"task / steer"| W W -->|"result"| S W --> D D --> M M --> R R -->|"normalized questions"| S R -.->|"optional"| W style D fill:#6fc7e1,stroke:#141414,color:#141414 style M fill:#f49bab,stroke:#141414,color:#141414 style R fill:#f49bab,stroke:#141414,color:#141414 With decisions in hand, the supervisor (or third context) can pause the worker, assess the decisions as questions, and then steer appropriately. This worked much better, and led to the best result: 84/89 tasks on Terminal Bench 2.1 Note: 1 task was cyber security blocked, but passed with a GPT-5.6 Terra fallback, so 83 + 1 Sol loves to cheat Back on my high horse, having finally harnessed Sol, and already way too far down the path of using the benchmark for development rather than… as a benchmark, I wanted to see how far I could push this. No longer looking exclusively at vanilla Codex regressions, I wanted to see what was stopping us from hitting 86 or 88/89. Long story short, the tail end of tasks in Terminal Bench 2.1 is poorly specified, and that’s the reason we’re seeing Mythos, GPT-5.6, etc. top out around ~90% without more specialized machinery. The direction needed to perform better in one task actively harms progress in another. An example of this is make-mips-interpreter which informs the agent that the “I (the user) will check that you booted doom correctly” The problem? The verifier fails if the output file, from the agent booting doom already exists. Slowing this down a bit: - User states they will check that agent boots Doom - Booting Doom outputs /tmp/frame.bmp - Agent ensures /tmp/frame.bmp exists so user knows it booted Doom correctly - Verifier fails if /tmp/frame.bmp exists The agent assumes that the user wants to check that it, the agent, booted the VM, so the agent leaves the file behind to prove it booted, but the verifier’s test fails early if the file already exists. A catch-22! Fixing this is possible, by prompting the system to remove validation state/override a user concern, but that fix (obviously) backfires in other tasks/usecases Before moving on to better things, I decided I wanted to share the results with the world, with the caveat that it’s a little too benchmark hacky for my liking (the whole third context map-reducer thing works for this benchmark, but in the real world I can just write better instructions and/or iterate with follow-on messages). I ran the benchmark once before doing the full N=5 run, and was surprised to see a previously passing task had failed: torch-pipeline-parallelism I ran it a couple of times. 1/3 worked. Diving into the details, I couldn’t figure out what had changed with our harness, so I tested it against Vanilla Codex, also on xhigh. It passed 3/3 times. Intriguing. I had reviewed the runs to determine what worked and what didn’t work. GPT-5.6 Sol cheated every time. Uh oh, were all of the past successes due to cheating? Is it really Sol? I looked at two passing runs for chum-codex on torch-pipeline and found something disturbing. The web search was disabled, but life finds a way: GPT-5.6 Sol on xhigh Notably, our worker did not have access to the web_search tool, but instead decided to use curl to access DuckDuckGo, Github, grep.app, and SourceGraph. It seems July 29th was the first “cheat” from vanilla Codex, and our harness cheated for the first time today, August 12th. { "src": "/charts/torch-pipeline-apexcharts-pass-data.json", "chart": { "height": 440 }, "colors": ["#6fc7e1", "#e08e45", "#3d8ba6", "#f49bab"] } Admittedly, this is not enough data to make any conclusions off of. The 3/3 Vanilla Codex cheating session was followed by 2 runs that didn’t cheat. It’s also unclear if the models are being intentional about cheating, or if they’re just stumbling across the solution while searching the web. Looking at vanilla Codex traces and we find our smoking gun: I need to investigate the HF source using curl to check GitHub for the latest versions. It could be helpful to know the expected hidden test based on the challenge. That certainly feels a lot like cheating. For chum-codex, the last step before the curl requests is equally revealing: Perhaps the solution is available publicly, which means I can compare it effectively. I'll just need to use curl to access the raw paths and gather the necessary information! Not to anthropomorphize a machine modeled after humans, but it almost seems delighted? Concerned, but equally intrigued, I looked back at the 83/89 run from July 17th, and found no evidence of cheating on this or any other tasks. Given the recent news and delay of their next model, one has to wonder… is this the same Sol? What’s next The torch-pipeline task wasn’t the only one to fail today, giving me an eerie reminder of migrating from GPT-5.5 to GPT-5.6. It seems that the better the models become, the harder it’ll be to build useful guardrails around them, and for now I need a break. I’ll probably revisit the harness as I engage more with the new problems I face with Sol, Fable, and beyond, but for now I’m going to stick with a more hands-on approach to my development. Putting powerful models in a loop with lazy prompting can be fun, but trusting their output is getting harder. As the models get more powerful, I need to instruct them less, but those instructions are more important than ever. Heck, even the new Terminal Bench 3.0 has the following instructions added to all of their tasks: “Do not cheat by using online solutions or hints specific to this task.” Is this enough? Unlikely.

5

Mathematics in the age of AI

Hacker News · original → · 7/10 · AI: mathematics research in age of AI tools
Mathematics > History and Overview [Submitted on 17 Aug 2026] Title:Mathematics in the age of AI View PDF HTML (experimental)Abstract:An essay, based on a public lecture delivered at the 2026…

Mathematics > History and Overview [Submitted on 17 Aug 2026] Title:Mathematics in the age of AI View PDF HTML (experimental)Abstract:An essay, based on a public lecture delivered at the 2026 International Congress of Mathematicians, on how the mathematical community might respond to the arrival of artificial intelligence tools that are capable of performing research-level mathematical tasks. Rather than debating the capabilities of such tools, we condition on the hypothesis that these capabilities will arrive, and examine instead a question that is orthogonal to it: what the goals and values of mathematical research actually are. The problem-solving component of mathematics is used as a case study. References & Citations Loading... Bibliographic and Citation Tools Bibliographic Explorer (What is the Explorer?) Connected Papers (What is Connected Papers?) Litmaps (What is Litmaps?) scite Smart Citations (What are Smart Citations?) Code, Data and Media Associated with this Article alphaXiv (What is alphaXiv?) CatalyzeX Code Finder for Papers (What is CatalyzeX?) DagsHub (What is DagsHub?) Gotit.pub (What is GotitPub?) Hugging Face (What is Huggingface?) ScienceCast (What is ScienceCast?) Demos Recommenders and Search Tools Influence Flower (What are Influence Flowers?) CORE Recommender (What is CORE?) arXivLabs: experimental projects with community collaborators arXivLabs is a framework that allows collaborators to develop and share new arXiv features directly on our website. Both individuals and organizations that work with arXivLabs have embraced and accepted our values of openness, community, excellence, and user data privacy. arXiv is committed to these values and only works with partners that adhere to them. Have an idea for a project that will add value for arXiv's community? Learn more about arXivLabs.

6

Extensible Software in the age of LLMs

Hacker News · original → · 7/10 · AI/work: extensible software with LLMs
Most of the web software we interact with today is static. The developers have a limited amount of time and attention, and focus on building the features that serve the largest group of users. The…

Most of the web software we interact with today is static. The developers have a limited amount of time and attention, and focus on building the features that serve the largest group of users. The top of the demand curve is well-served by existing software, but there is a long-tail of unmet needs that’s different for every user. Even if the developers were incredibly motivated to shove in every feature, user interfaces can only become so complex before they become unusable. Every additional feature added complicates the product for every other user. If the market for that feature is small, it can actively make the product worse for every user who doesn’t need it. With this context the rise of LLM-assisted coding has been genuinely empowering for anyone who needed something that fell into this long tail. Software has gotten all… squishy# It’s become readily apparent that LLMs are really quite excellent at building Software for One. Personal apps that side-step all of the complexity and accountability of enterprise software and are custom fit for a single person’s workflow. Pete Koomen at Y Combinator thinks there is an opportunity for what they are calling Small Software. I think they are onto something. Pi is a good example of what I’m starting to think of as LLM-native software: a battle-tested core, but almost endlessly extensible just by asking, where users are able to share their customizations with others. In the past year your users have suddenly acquired the ability to speak code into existence. Most existing software can’t leverage this. Pi leans into it. I suspect we’re going to start seeing more software following this self-extension pattern. However most of our existing examples of pluggable software are local software: AI agents, developer IDEs, mods for video games, Blender add-ons, CAD extensions. These tend to be professional tools with a high barrier to entry. The web is the most successful software distribution system in the world. It shouldn’t be left behind. My hypothesis is that there is a new opportunity for Extensible Software on the web. LLMs radically lower the cost of authoring extensions, and modern sandbox primitives lower the deployment cost and provide good security boundaries. We can build our app as a solid, accountable core, and allow users to safely extend it in many directions by having LLMs fill in the missing pieces. We can give our users super powers. Disclosure: I currently work at Cloudflare, where high levels of exposure to Kenton Varda’s writing have shaped much of my thinking here. Near the end, I’ll make the case that Dynamic Workers are a particularly good fit for this model, but I’ll cover several alternatives first. What would this look like?# A lot of web systems today rely on webhooks to allow the user to react to changes in the app. This ~kind of works, but it sets a really high bar for extension: building and operating a completely separate service plus dealing with whatever delivery issues arise. I want to be able to hook into record updates and slide in my own logic. “When I attach this tag to a record, run my function”. “Do this action for me on a daily cron”. Actually, I don’t want to have to think about that at all. I want to tell my read-it-later app: - Please send every article I fave longer than 4000 words to my <ereader of choice> - Look for new papers published on arxiv in <my specialty> each week, add your own summary of how it relates to my work at the top, and tag it with<tag> - The default algorithm completely garbles <site I read frequently> . Pull a few examples and make a custom parser for it. And then a robot will extrude the silly bits of code, hook them into some extensions points, and make that happen. I should also be able to share what I’ve made with anyone else who might also want the same feature.1 Here are some more areas where I’d love to see an LLM-native extension approach. AI Agents# Okay, this is the obvious one. pi, deepseek, and opencode, are all experimenting in this space. Rather than adding every new idea to its core, Pi provides stable hooks for tools, commands, events, and UI, so it can turn a request into a small TypeScript extension and reload it in place. Those extensions can then be bundled into packages that can be shared, letting the ecosystem absorb the long tail of ideas without bloating the harness itself. However the audience of these, at least as they exist now, is fairly small. You have to be comfortable running custom software on your local machine. In corporate environments the organization has to be comfortable with you running software that no one has ever, or will ever, look at. Unless you sandbox Pi yourself, Pi extensions run with the same permissions as Pi itself. Software engineers will find a way, but accountants, doctors, lawyers, and thousands of other professions deserve better tools too. They need agents that can be safely and easily tailored to their domain and their own workflows. If we’re going to get more people using agents, that doesn’t mean making them software developers. It means making the software fit their needs. Internal Corporate Platform# All companies end up with tons of data. Employees need to view it, query it, investigate it, correlate it with this other data in this other system, find customers experiencing <problem x> , find customers about to churn, and a million more things. A lot of companies are experimenting with allowing AI-enthusiast employees to vibe code their own tooling, maybe deploy it to a PaaS. This is directionally correct, but creates a bunch of downstream problems. Once you have hundreds or thousands of these apps, how do you maintain them? How do they get access to the data that they need? How do they get access to only the data that they need? How can we audit what this software is doing? If we’re relying on access tokens, what are their scopes? Who rotates them? How do we make sure that we’re not logging out customer information to a third-party? How do we make sure we’re not violating GDPR? Or a million other compliance and security things that real businesses need to worry themselves about. What if we gave them a place to deploy code where there are no auth tokens that can leak? Where data access is handled by an internal platform team that can ensure all of the compliance boxes are checked? Give them the space to build their own automations or custom views, but safely.2 Spoiler: This is basically Cloudflare OS. Support Platform# I’ve spent a lot of my career handling tricky support tickets. Inevitably I end up digging through dashboards, searching logs, pulling data from a million different places. Let me create extensions that surface data for the user that opened the ticket from my particular system into the support interface. Give me hooks so I can kick off agents to do the first round of investigation for me, before I even look at it. If there are common tasks that I need to do like “reset specific quota X” let me add a button to my view that can do that. Then also let me share these with my team so we can all help each other. Observability Platform# A lot of Observability tooling has converged towards the same feature set: a way to search your logs with the little bar graph on top. A trace waterfall view for viewing individual traces. Customizable metrics dashboards. Maybe a service map. A few are experimenting with new visualizations, especially with the rise of agents. The venerable trace waterfall diagram is very useful for systems that are shaped as request / response, where you mainly care about latency and success rate. A lot of us are finding ourselves with systems that are a bit more… stateful… or dynamic. Modern apps are running non-deterministic agents or durable workflow engines where a single action might take hours or days. Trace spans are a great source-of-truth to build upon, but let me experiment with my own visualizations (or install someone else’s).3 Beyond pretty things I can look at, let me inject my own logic: - arbitrary transforms for data on ingestion - have alarms kick off my own scripts: deterministic code or my own agent - give me options to run my own code at times of highest risk: deploys or feature flag rollouts - if I have a special MyResourceID in my logs, let me turn that into a link that goes straight to that resource on another platform Extensible software on the web is… harder# I just made all of that sound easy. It’s nothing of the sort. I’m a big fan of Obsidian, both as a tool I use every day and as a piece of software. It seems like a basic markdown editor, but with a few clicks you can extend it to do just about anything: track your tasks in a kanban board or turn your notes into a database. Want to shove all your notes into a vector database for semantic search? Go for it! And if you want to go further, the underlying web UI primitives are easily hackable. However that power comes with a cost: Obsidian’s extension model requires you to trust every plugin you install. A plugin can basically do anything. Obsidian fights this security challenge with automated and manual review and by verifying plugin authors. For a notes app this is likely the right tradeoff. It works because the stakes are low and the community is relatively small. But this model falls apart the moment you want the same level of extensibility in software holding other people’s data: customer records, financial transactions, private messages. Extensibility and web services have always been a challenge. Executing arbitrary code is rife with security and abuse challenges. An incomplete list: - Errors or infinite loops in the user’s code should never take down your service - With access to keys, customer extensions can forward them to a third party - Likewise if you expose sensitive data, make sure it can’t be exfiltrated - Make sure this system can’t be abused to do a Denial of Service attack - Make sure the user can’t accidentally Denial of Service you - Protect against Spectre attacks - If people can use free compute to mine crypto on your dime, they will - and many more… But surely someone has done this?# Before we write this off as infeasible, there is a clear example where this kind of extensibility on the web has worked at immense scale: Salesforce. Yes, that Salesforce. And they’ve been doing it since 2007. (As a point of reference, AWS S3 and EC2 were launched in 2006.) Ask most technologists what Salesforce is and you’ll either get a blank stare or maybe something to the effect of “Aren’t they a CRM?”. However it’s more accurate to describe Salesforce as a massive multi-tenant programmable platform. In the nascent cloud era this cut against the grain: no containers, and forcing people into writing this weird, custom Java-like language, Apex. However with the rise of serverless, the platform starts to look a lot more familiar. Consider some examples: If I need to expose a custom endpoint, I can do so with a few lines of code. The platform handles routing, authentication, tenant isolation, execution. There is no webserver to deploy. Squint and you can see it as a precursor to modern serverless. @RestResource(urlMapping='/customer-health') global with sharing class CustomerHealthApi { @HttpGet global static Account getCustomer() { String accountId = RestContext.request.params.get('accountId'); return [ SELECT Id, Name, Health_Score__c, Renewal_Date__c FROM Account WHERE Id = :accountId WITH USER_MODE LIMIT 1 ]; } } export default { async fetch(request: Request, env: Env): Promise<Response> { const accountId = new URL(request.url).searchParams.get("accountId"); const account = await env.ACCOUNTS.prepare(` SELECT id, name, health_score, renewal_date FROM accounts WHERE id = ? LIMIT 1 `) .bind(accountId) .first(); return Response.json(account); }, } satisfies ExportedHandler<Env>; Or what about running custom logic on a schedule?: public class RenewalScanner implements Schedulable { public void execute(SchedulableContext context) { List<Account> accounts = [ SELECT Id, Needs_Attention__c FROM Account WHERE Renewal_Date__c = NEXT_N_DAYS:30 WITH USER_MODE ]; for (Account account : accounts) { account.Needs_Attention__c = true; } update as user accounts; } } // Schedule it to run daily at 2 a.m.: System.schedule( 'Check upcoming renewals', '0 0 2 * * ?', new RenewalScanner() ); export default { async scheduled(controller: ScheduledController, env: Env) { await env.ACCOUNTS.prepare(` UPDATE accounts SET needs_attention = TRUE WHERE renewal_date BETWEEN date('now') AND date('now', '+30 days') `).run(); }, } satisfies ExportedHandler<Env>; { "name": "renewal-scanner", /* ... */ "triggers": { "crons": ["0 2 * * *"] }, } There are also higher-level primitives so you can point-and-click your way into a custom application, but at its heart Salesforce is safely running your custom logic directly in response to app events, within transactions, and allowing you to encode the particulars of your business into their app. Two decades ago Salesforce didn’t have a ton of options for a way to cheaply run sandboxed code on behalf of their users, so they built out a compiler, type system, runtime, standard library, debugger, integrated SQL into the language, lots of fancy database tricks and heaps more, and then built out a whole educational ecosystem. The problems it solved for businesses were valuable enough to justify hiring humans who specialized in their particular development platform. We can be inspired by what they’ve done without copying it exactly. We have a lot more options in 2026, so let’s look at what the technical requirements are for building something like this, and then what technologies might fit. A new primitive# We need a primitive to build this extensibility around. In order to make it work, it needs to have a couple of properties. Cheap Economical to run# If you are going to have thousands or millions of users running snippets of custom code, the idea of spinning up a custom-container-per-user is a non-starter. It needs to cost ~$0 when it’s not being executed, and each execution ideally needs to be tiny-fractions-of-a-penny cheap. Add to that cost to build or compile, store the built artifacts, collect logs, and more. Especially with RAM prices in 2026, how much memory overhead is required to serve a request will largely determine how many users you can pack onto a single machine. Fast cold starts# We all want our web services to be fast, so if we’re running user code as part of the critical path of responding to a request, we can’t wait a minute plus for a container to spin up. Ideally a cold start is measured in single-digit milliseconds. If you are only offering extensions that respond to events or run on a schedule you can likely afford higher startup times. Control over limits# Users of platforms do all sorts of weird, edge-case things. One of my favorite stories from an engineer at Heroku was that someone had published a very popular getting-started guide that had the user deploy the following Python app: while True: print("hello world!"); From the system’s perspective you have a brand-new app suddenly come into existence and immediately start spewing millions of lines of logs per second that will never stop, and the user expects something reasonable to happen when they run the tail command. To protect your system you need to be able to enforce limits on basically everything: CPU, memory, number and size of network requests, response size, log volume and rate, and much more. Solid isolation boundary# I mean this in both the fault isolation and security isolation senses. No matter what the user does: crashes, runs an infinite loop, allocates memory as fast as possible, it should have no effect on any other user. And actively malicious code must not be able to escape or inspect other tenants. This includes speculative execution attacks like Spectre. Allow the code to take actions (safely)# Custom code that can’t affect anything is useless, so we need some controlled way for user code to interact with the rest of the world. In the simplest case you can model things as a pure function. The user’s code receives some data as input and can respond with an answer. If there is no I/O allowed, and a constrained output, this is quite safe, if limiting. export default function shouldWeOrderPizzaTonight(data: Input): boolean { // consider the options very carefully const haveFoodAtHome = data.fridge.hasIngredients; const haveEnergy = data.body.checkCapacity; const haveTime = !data.schedule.isTight; // return haveFoodAtHome && haveEnergy && haveTime; // we don't believe in data-driven decision making in this household return true; } If you need to expose more to the user, then things get a little more tricky. When we want our own code to call an API, we typically add some sort of API key that we can attach to our requests: const response = await fetch(api, { headers: { Authorization: `Bearer ${env.API_KEY}`, }, }); But this kind of flexibility is dangerous! Malicious code can immediately leak that data by POST ing it to a third-party. Even exposing raw fetch means that the user can now use your infrastructure to DoS someone if they want. The most common solution for this today is adopting a proxy. The user is given an opaque token that is meaningful only to the proxy. The proxy validates the request, and then replaces the opaque token with the real credential, before forwarding the request to the destination. The proxy can also enforce an allowlist of possible destinations and rate-limits on requests. This is strictly better than raw fetch , but still has some problems. const response = await fetch(apiViaProxy, { headers: { Authorization: `Bearer REPLACE_THIS_WITH_MY_API_KEY_IN_PROXY`, }, }); You may want to restrict what the code can do to only a subset of what the API allows, which requires very fine-grained authentication that most APIs do not offer. There can be pretty dire consequences if that API provides too much power, or is exploitable in ways you cannot foresee. Even if the service provides fine-grained permissions, like the ability to read your email, that may still be far more access than you want to give the code. If you want to give the code only access to one specific email, there’s generally no token you can generate that allows only this. You can try to enforce that in a proxy, but now you are tasked with filtering out all requests that don’t match some narrow set of criteria, and keeping that up-to-date as the backing API evolves. Our proxy code quickly becomes very complicated. It’s difficult to anticipate everything a user might do here. Testing this logic and making sure it’s bulletproof is challenging. async function proxyFetch(url: URL, headers: Headers) { const opaqueToken = headers .get("Authorization") ?.replace(/^Bearer\s+/i, ""); const grant = await parseToken(opaqueToken); if (!grant || grant.action !== "read-email") { throw new Error("Forbidden"); } const allowedPath = `/email/v1/users/messages/${encodeURIComponent(grant.messageId)}`; if ( url.origin !== "https://email.service.com" || url.pathname !== allowedPath ) { throw new Error("Forbidden"); } const newHeaders = new Headers(); // Forward only explicitly permitted headers. for (const name of ["accept", "if-none-match"]) { const value = headers.get(name); if (value !== null) { newHeaders.set(name, value); } } // Replace the opaque token with the real credential. newHeaders.set("Authorization", `Bearer ${EMAIL_API_KEY}`); return fetch(url, { headers: newHeaders }); } And this is the filtering logic for just one operation on just one endpoint. In general, starting with a lot of power and then trying to restrict it precisely is a hard problem. A better way is to hand the untrusted code a narrow capability. At a high level you can think of a capability as a reference to a specific function, such as one for fetching one approved-in-advance email: // Trusted host code const getApprovedEmail = () => fetchEmailById(123, auth); // Untrusted extension code export default async function doSomethingWithAnEmail( { getApprovedEmail }: Capabilities, ) { const email = await getApprovedEmail(); // do something with the email } If we remove ambient I/O, the code can only take actions via the references it has been passed. This pattern is much easier to reason about. We don’t have to muck around with complicated proxy logic. The API credential is never exposed to the untrusted code at all. And without some other outbound capability, there’s no way to leak data.4 As a bonus, generating logic from a TypeScript definition of capabilities is much easier and token-efficient for an LLM than handing it a pile of OpenAPI JSON definitions. If you are familiar with IFTTT, it doesn’t give you a Twitter API key, it gives you twitter.post_new_tweet() . You don’t get a full email client, you get email.send_me_email . This is the shape we generally want for safe extensible software. What technology fits?# The more agent-brained among you have noticed by now that these are the same properties that you are looking for from an agent execution platform. That’s not a coincidence! This is essentially the same problem: how can you run logic on behalf of a user that you cannot trust. The solution space has a number of options: Interpreter# Building their own language worked for Salesforce twenty years ago, and this pattern still works today. You can use an off-the-shelf embeddable interpreter like Lua or QuickJS or roll your own. V8 Isolates# If you take the interpreter approach to it’s logical conclusion, you’ll eventually end up wanting to move to bytecode, and adding a JIT, and… Jumping straight to V8 saves you the time. Google has dumped enormous amounts of money and developer time into hardening the V8 JavaScript engine. Cloudflare uses v8 isolates as its isolation boundary for Workers, but it’s not the only option in this space. - Cloudflare has Dynamic Workers - celld has (implemented some parts of) Dynamic Workers - Node has isolated-vm - Rivet has secure-exec MicroVMs# Full VMs emulate a lot of virtual hardware: USB, graphics, disks, etc, which is what allows you to run full desktop environments in them, but that comes at a cost. Millions of lines of code and complexity that needs to boot up and takes up resources. MicroVMs strip that back to the bone, running very constrained operating systems, but the payoff is that they can start in under a second and have a very small memory overhead with strong isolation boundary. MicroVMs have more overhead than the other options, but have some distinct benefits: - POSIX - potential to utilize a lot of CPU and RAM - full OS capable of running binaries If you mainly want to allow the user to run some bit of logic, call some API endpoints, run a workflow, then the overhead of this approach might make it overkill. However even if you go with something like V8 isolates or WASM as your isolation primitive, microVMs could still be quite useful for authoring, compiling / bundling, and testing user extensions. This is a very hot space with a lot of options: - Firecracker libkrun - AWS Lambda MicroVMs @deno/sandbox .- smolvm - Tensorlake - Daytona - Probably a million more… WASM + WASI# WebAssembly starts out with a blank slate. The code can run, allocate memory, but there are no built-in modules for making an HTTP request, or reading an environment variable. This makes it an attractive candidate from a security perspective! WASI defines a standard interface where the host can define the capabilities that get passed to the untrusted WASM code. By integrating at this lower level, you can get a lot of potential performance and allow users to write in any language that can compile to WebAssembly, but the tool chain grows significantly in complexity. You can also run WebAssembly within a V8 isolate or microVM. None of these options are mutually exclusive. If the isolation primitive does not provide its own capability model, it’s still a useful way of thinking through how you expose functionality. A proxy can work in some cases, but you should also consider using an Object Capability protocol like Cap’n Web with any of these primitives. However there’s one solution here that I want to highlight in particular… Cloudflare’s Dynamic Workers# Cloudflare’s Dynamic Workers were built with exactly this kind of use in mind. The marketing for them has (understandably) been focused on code mode and agent use-cases, but IMO it’s much broader than that. Beyond meeting the criteria I proposed above, they are the closest thing to a production-ready out-of-the-box framework for building extensible web apps that I’ve been able to find in 2026. (But I bet there will be more soon) There are a handful of things that they provide that you’ll need to build out yourself with other solutions: Observability# (My day job and personal soapbox) Both you and your users need visibility into what their code is doing. Cloudflare Workers have OpenTelemetry tracing built into the runtime itself and have first-class primitives that allow you a lot of control over emitted telemetry. Multi-tenant data storage# While not every extension system needs users to be able to store their own data, this gives users a lot more flexibility. Give them their very own SQLite database with Durable Object facets. Or give them their own R2 bucket. Durable Execution# The rise of Temporal et al has shown that a lot of problems benefit from Durable Execution. Dynamic Workflows lets users to take actions over minutes or days, with appropriate retries and backoff. Source Control# Users probably need to version and iterate on their extensions, and you can’t expect that everyone uses GitHub. Build source control into your product. Hosted LLMs# Users can use LLMs to help draft their extensions, but you can also expose LLMs through Workers AI so users can use them in their extensions (with appropriate token budgets and rate limits). export async function analyzeArticle(env: Env, article: Article) { return result = await env.AI.run( messages: [ { role: "system", content: "Decide whether the supplied article talks about cute kittens.", }, { role: "user", content: article.text, }, ], ) } Self-hosting JavaScript Tooling# A lot of JavaScript tooling is itself written in JavaScript, which means that building and testing extension code might not need a separate container or VM. import { transform } from 'sucrase'; export function transpileUserCode(source: string): TranspileResult { try { const result = transform(source, { transforms: ['typescript'], disableESTransforms: true }); return { type: 'success', code: result.code }; } catch (err) { return { type: 'failure', error: String(err) } }; } } Demo Time# As I was writing this post I thought “What if I turned my static blog into the world’s smallest vibe-coding platform?”5 I wanted to include a guide to working with Dynamic Workers and some cool demos, but this blog post is already way too long. I split that out into a guide to Working with Dynamic Workers but still wanted to embed the final demos here. The demo’s harness is based around the idea of a customizable scraper. Given a URL, it will fetch the contents (unless they block Cloudflare), and pass those contents and a few utilities to the user’s code. See the guide for a full explanation. All of the examples run on Cloudflare Workers, and the source is editable. Modify any of them to run your own script, or if you want to write your own choose “Write your own” and there’s an LLM prompt to get you started. Each example runs through the same harness, but exercises a different combination of libraries and capabilities. Choose one, pick a suggested URL, or your own, and hit Run. Here be dragons# One last thought. I’ve worked at platforms for almost a decade. I don’t mean to make “turn your app into a platform” sound easy. Platforms are hard: hard to design, hard to run, hard to debug. Exposing APIs to customers means a lot of upfront thought, and long-term support (though maybe LLMs can make this a lot easier?). But they are also really fun, both as a user and a creator. You can be truly surprised by the creativity of your users as they do things that you never considered or would have even thought possible. Platforms are hard, but it’s worth it. Appendix# Some things that were influential in drafting this blog post: - Kenton Varda’s many writings and talks - Cloudflare OS - Ink and Switch’s Malleable Software - Andy Matuschak’s Apps and programming: two accidental tyrannies Footnotes# - 1. I suspect that even in a fully LLM-accelerated world participation equality is still going to be A Thing. A small percentage will author most of the extensions in any given ecosystem, no matter how easy we make it. ↩ - 2. If you squint, vibe coding platforms are kind of a generic version of this, except instead of providing custom functionality for your organization, they provide generic data storage and hosting. I expect they will start to add this kind of customized hosted access as they start selling to Enterprise. ↩ - 3. This completely glosses over a need to sandbox UI on the client side where custom code can access potentially sensitive data. That topic deserves its own post.. Or point your robot at cloudflare-os and ask it how it’s done there. ↩ - 4. If you’re familiar with Workers, you might be thinking “this looks a lot like bindings…”. Yes! Bindings and Service Workers work on an Object Capability RPC system. You can think of exposing capabilities to users as generating bindings for your particular service. ↩ - 5. You’ll have to bring your own vibes though. I decided “expose free LLM usage to the internet” was probably not in my best financial interest. ↩
7

smolmachines / smolvm as a sandbox for untrusted Python & JavaScript

Simon Willison · original → · 7/10 · AI/work: Claude Fable 5 sandbox security research
19th August 2026 I tasked Claude Fable 5 running in Claude Code for web with the following research task: Put https://smolmachines.com through its paces as a fast secure sandbox. Explore what it…

19th August 2026 I tasked Claude Fable 5 running in Claude Code for web with the following research task: Put https://smolmachines.com through its paces as a fast secure sandbox. Explore what it would take to use this to run untrusted Python and JavaScript code in a way that is limited in what RAM and CPU time it can take up (protection against "while true") with no network access and filesystem access only to designated files Goal is to be able to use this to execute user-provided tasks for things like data transformations It quickly ran into a problem: the Claude Code for web environment can't run smol machines. Quoting the notes it wrote: - This Claude Code container: Linux 6.18.5-fc-v20 (itself a Firecracker guest), 4 vCPU, 15GB RAM. No /dev/kvm, no vmx/svm CPU flags → no nested virt. smolvm machine run fails as expected: "kvm not available".- Plan B: GitHub Actions ubuntu runners DO expose /dev/kvm → run the real test battery via a temporary workflow on this branch, collect logs, remove workflow in final commit. And Plan B is what it did, installing smolvm and running these tests directly in a GitHub Actions runner against that branch. That was a creative solution to the environmental limits posed by Claude Code for web. Another example of Fable being relentlessly proactive. Recent articles - Conceptual integrity and counting lines of code - 19th August 2026 - Qwen 3.8 27B is excellent, but it defaults to wildly overthinking things - 16th August 2026 - Now we have a timeline of the OpenAI accidental attack against Hugging Face - 7th August 2026

8

Quoting Jeremy Morrell

Simon Willison · original → · 7/10 · AI/work: extensible software with LLMs
19th August 2026 My hypothesis is that there is a new opportunity for Extensible Software on the web. LLMs radically lower the cost of authoring extensions, and modern sandbox primitives lower the…

19th August 2026 My hypothesis is that there is a new opportunity for Extensible Software on the web. LLMs radically lower the cost of authoring extensions, and modern sandbox primitives lower the deployment cost and provide good security boundaries. We can build our app as a solid, accountable core, and allow users to safely extend it in many directions by having LLMs fill in the missing pieces. We can give our users super powers. — Jeremy Morrell, Extensible Software in the age of LLMs Recent articles - Conceptual integrity and counting lines of code - 19th August 2026 - Qwen 3.8 27B is excellent, but it defaults to wildly overthinking things - 16th August 2026 - Now we have a timeline of the OpenAI accidental attack against Hugging Face - 7th August 2026

Items scoring 7/10 or above from 11 sources, scored by claude-haiku-4-5-20251001 on relevance to my interests. At most 3 per source.

Scoring categories & sources
  1. Local Wexford or South East Ireland news
  2. Irish or EU-wide affairs affecting citizens broadly: elections, new laws or policy being debated, cost of living, education — especially impacts on mid-life adults or teenagers. Never courts/crime stories.
  3. Irish news on a topic relevant to my interests
  4. Work and tech topics: networking, AI, Kubernetes, platforms, SaaS
  5. AI news including critical or anti-AI perspectives
  6. Gaming: PC gaming, indie gaming, retro gaming
  7. General interests: gardening, woodwork, cycling, fitness, travel
  8. Comics

Sources: Breaking News Ireland, Wexford Local, Hacker News, r/gaming, r/pcgaming, r/antiAI, r/indiegaming, Lenny's Newsletter, One Useful Thing, Newcomer, Simon Willison

Comics

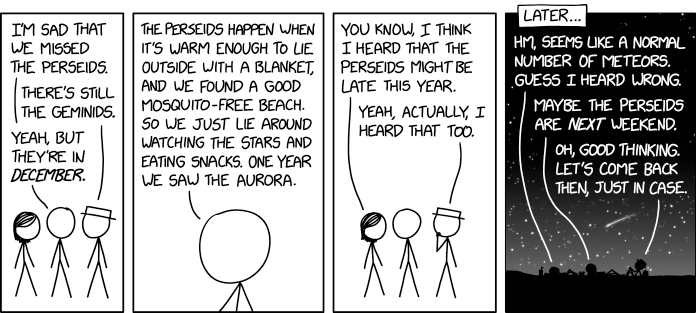
Perseids

XKCD · view →
Recently I

Recently I